Xiaomi/Vision-Language
Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
Company
Releases
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
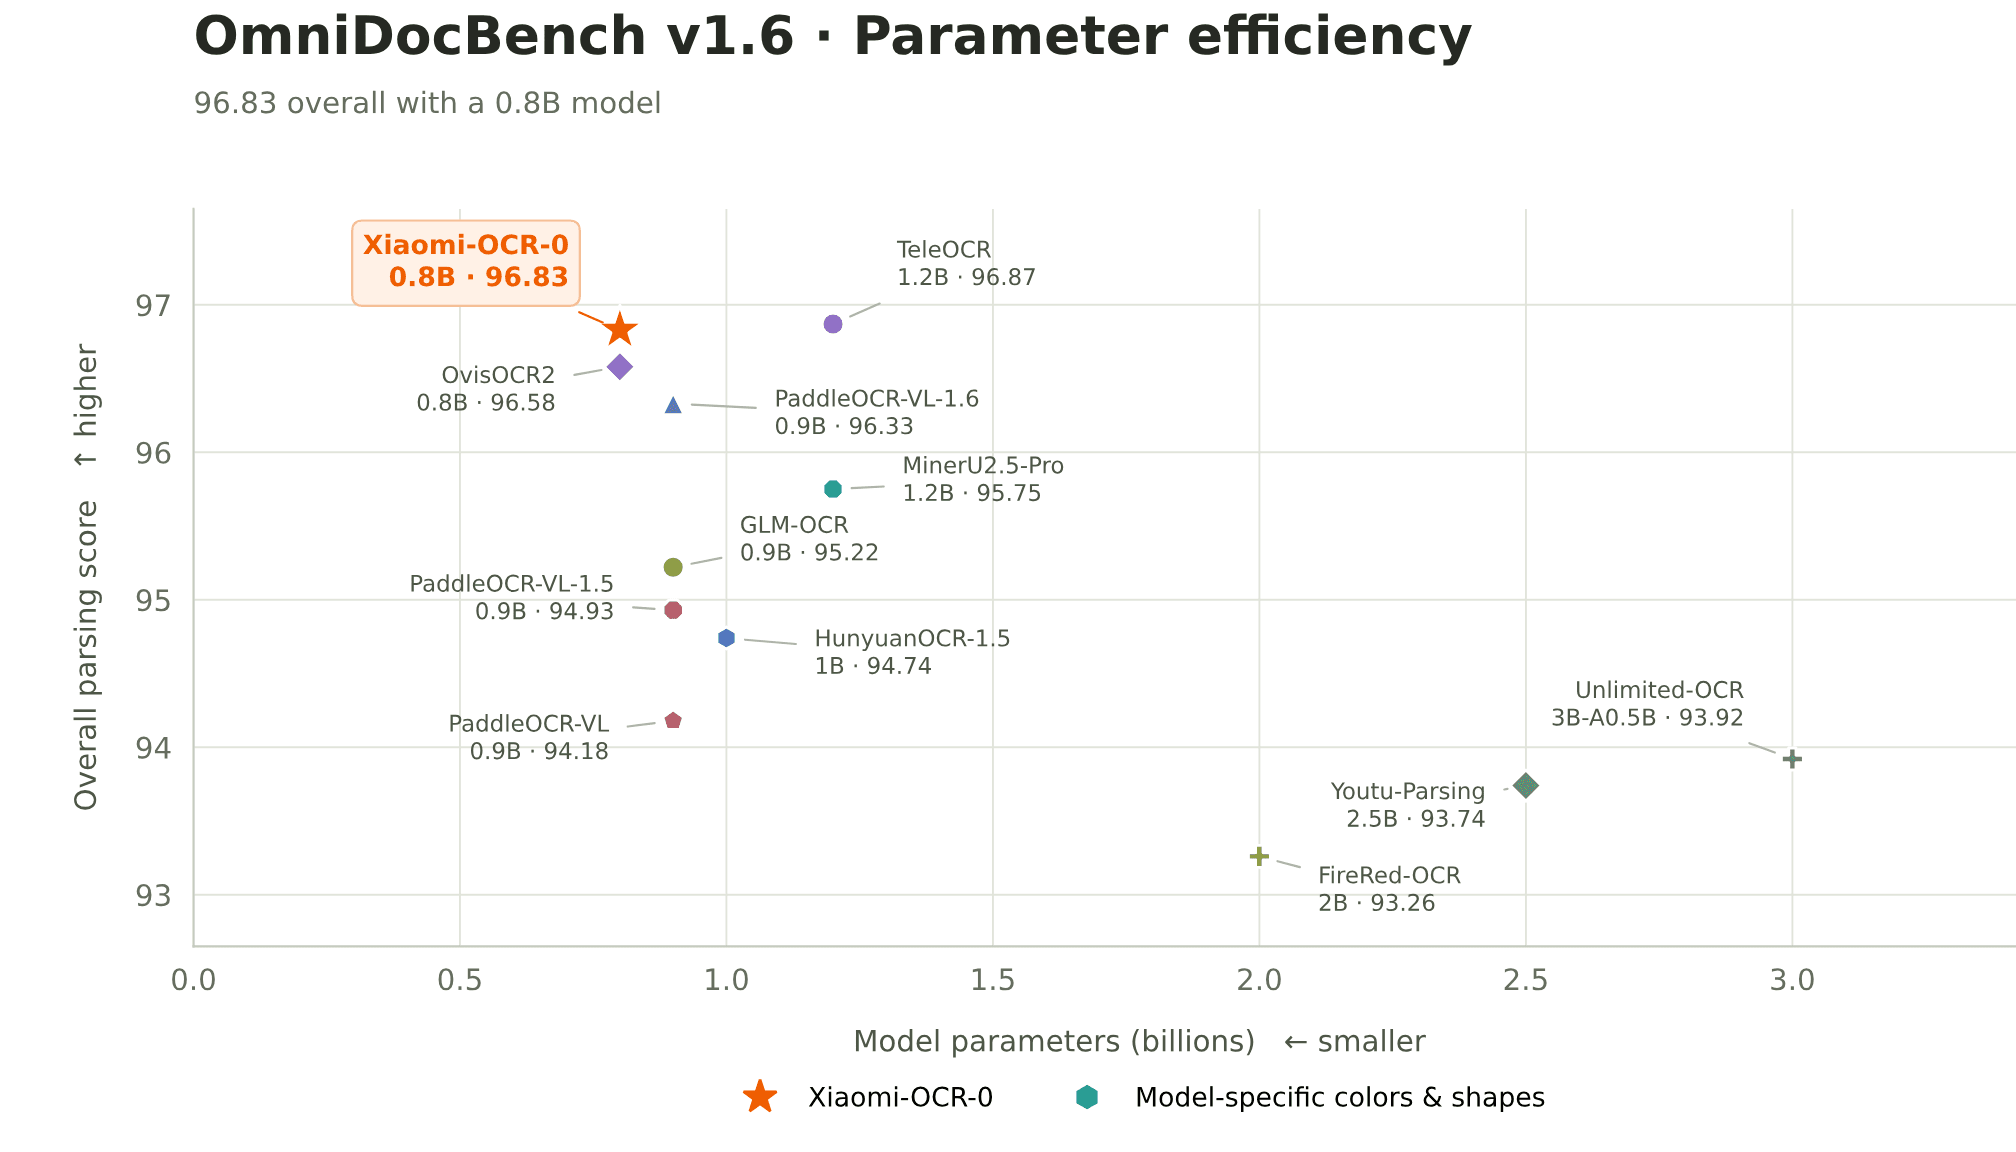
The company's research arm releases Xiaomi-OCR-0, a document-parsing vision-language model built on a Qwen3.5 backbone.
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
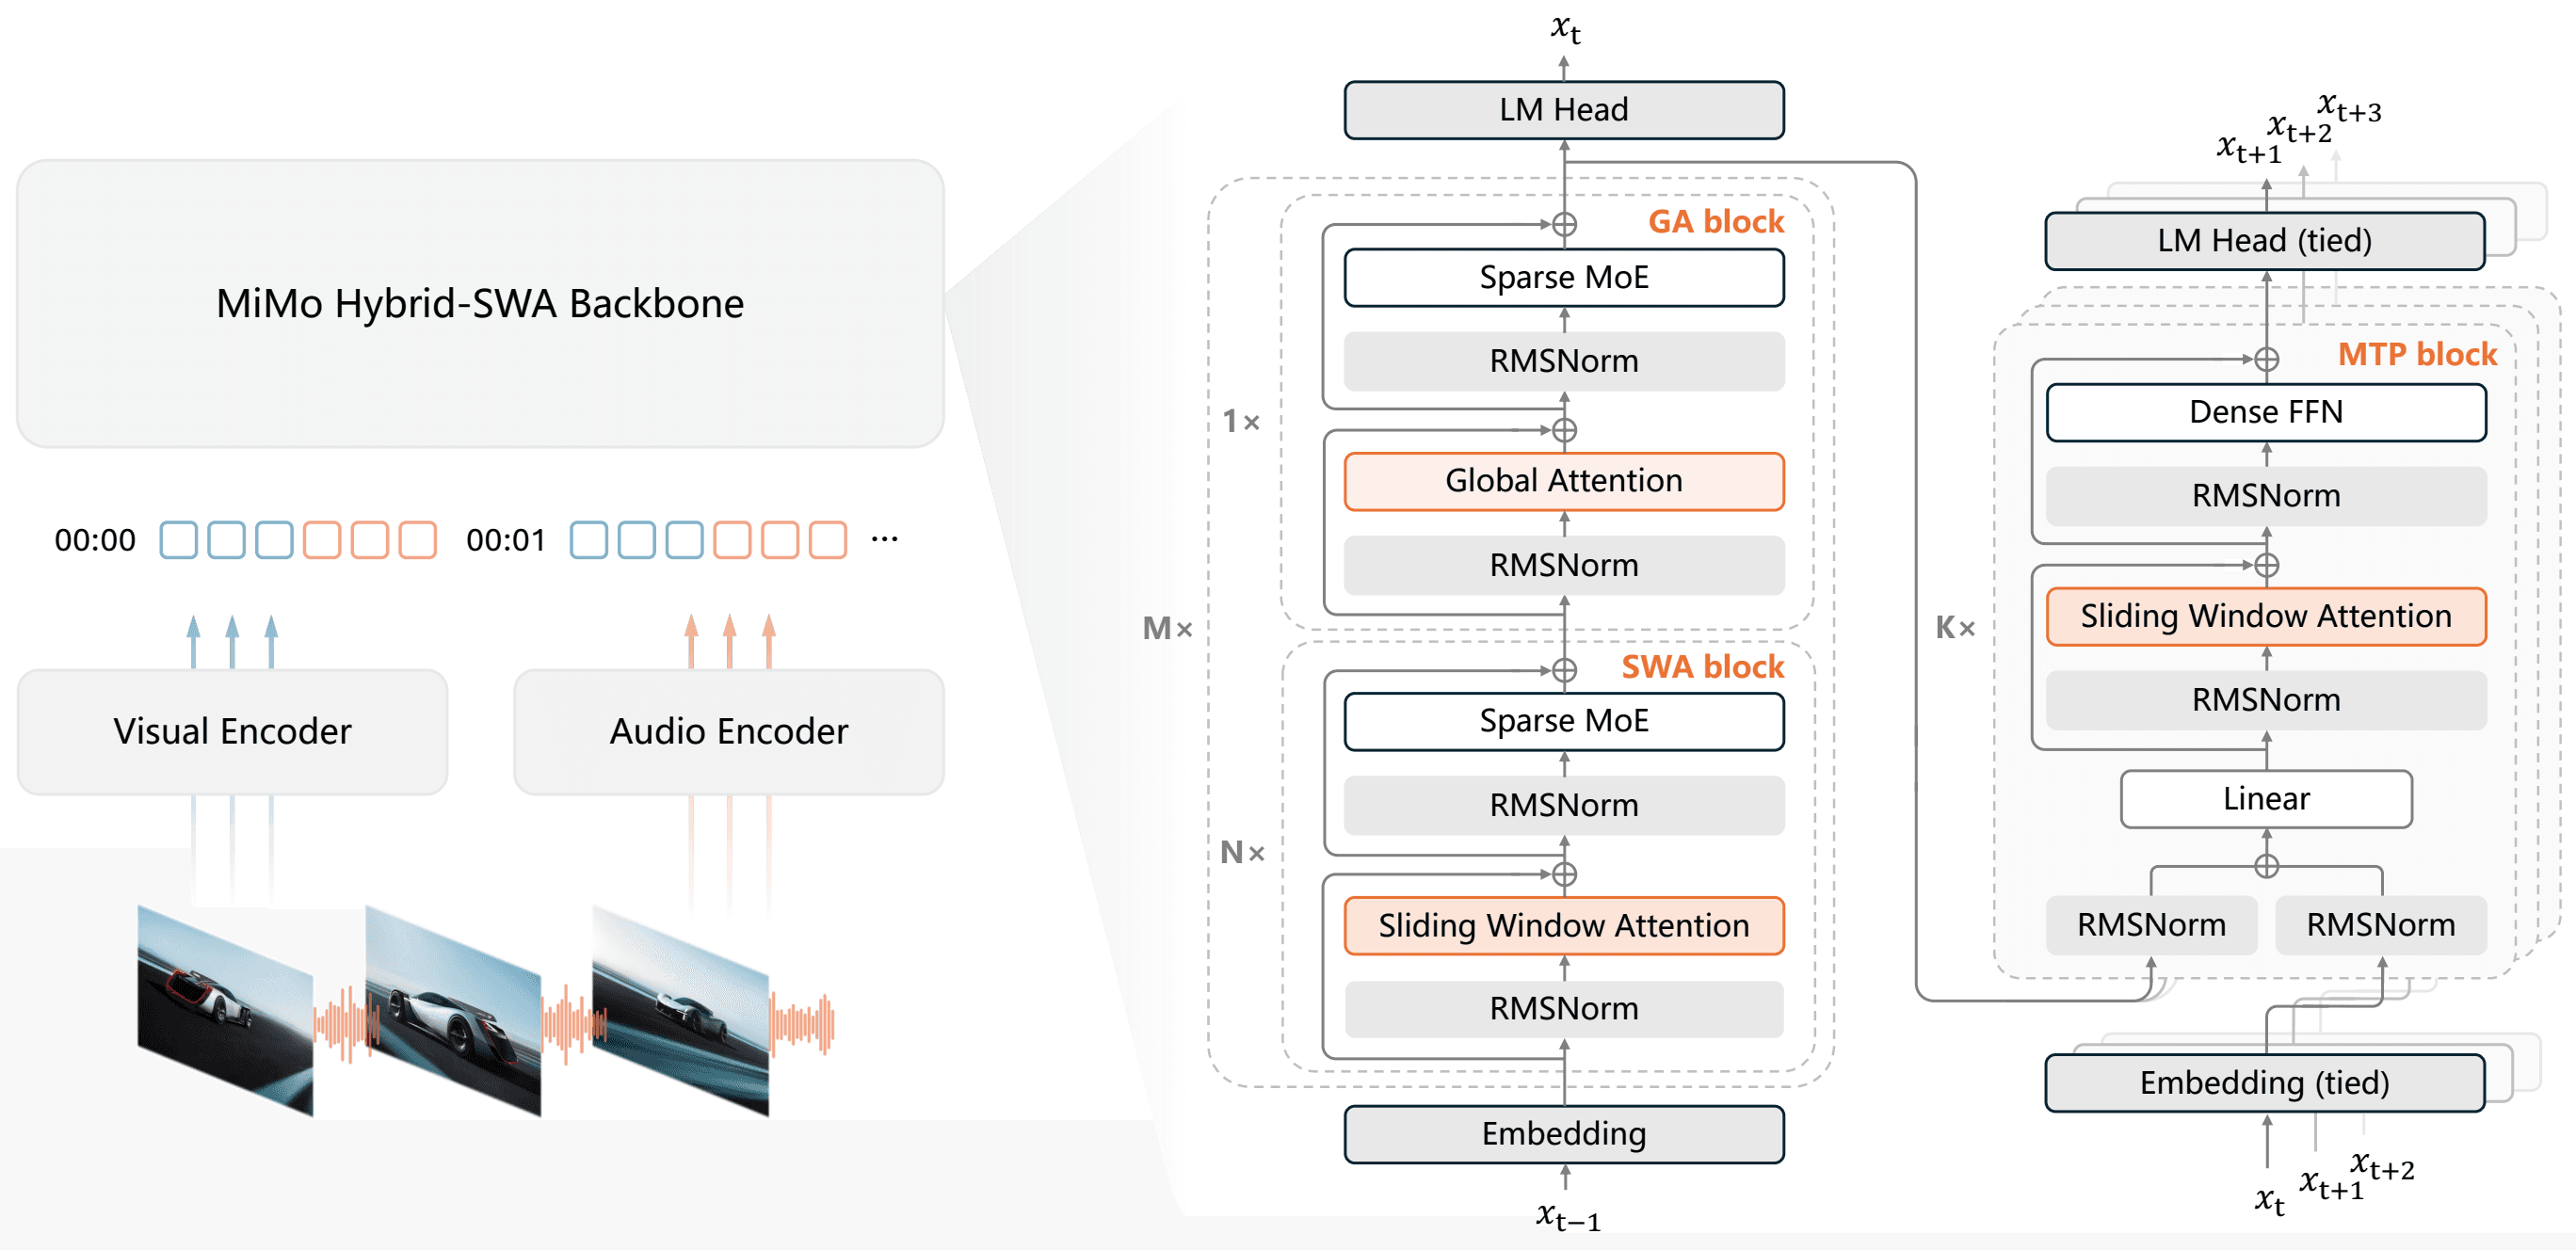
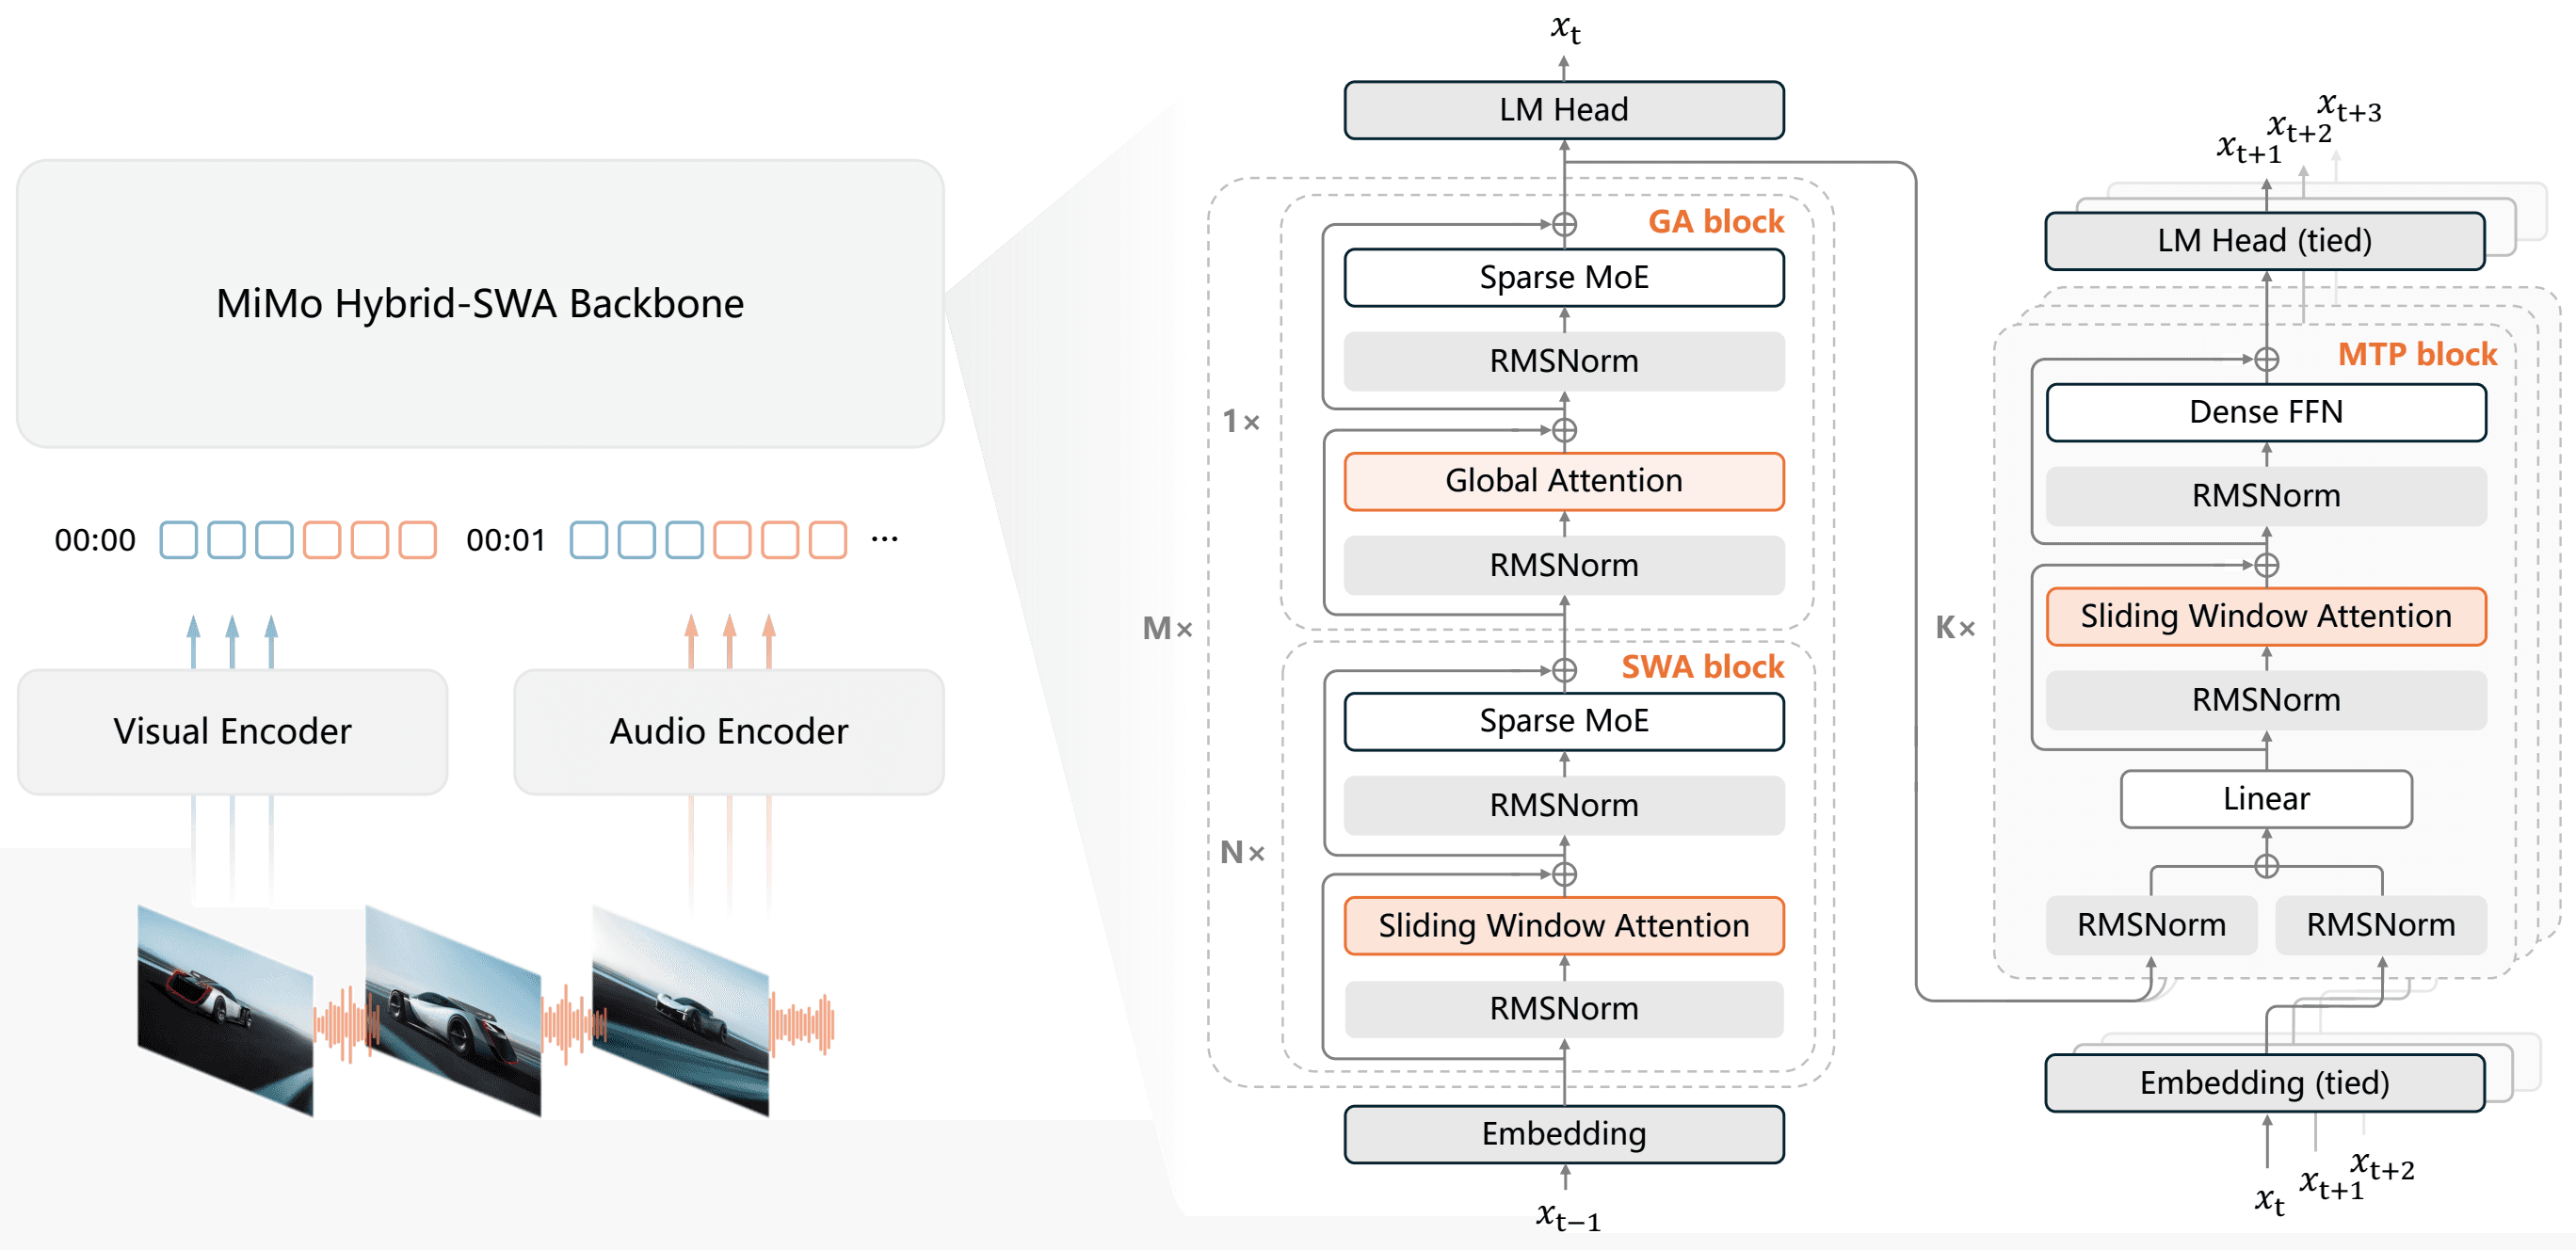
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.
The new open-source model from the Chinese tech giant offers automatic speech recognition for Mandarin, Cantonese, and English under a permissive MIT license.
The new open-source model from Xiaomi's FireRedTeam leverages the Qwen-Image-Edit pipeline to offer instruction-based image editing in both English and Chinese.
This new instruction-tuned model from Xiaomi can handle a flexible combination of audio and text inputs and outputs, from transcription to voice synthesis.