Xiaomi's MiMo-Audio 7B Tackles Complex Speech Tasks
This new instruction-tuned model from Xiaomi can handle a flexible combination of audio and text inputs and outputs, from transcription to voice synthesis.

Xiaomi has released MiMo-Audio-7B-Instruct, a versatile 7-billion-parameter model designed to handle a wide array of speech and audio tasks. Published under a permissive MIT license, the model marks a notable open-source contribution from the major electronics company, providing a powerful new tool for developers working with audio AI.
The key innovation of MiMo-Audio is its "any-to-any" architecture. Unlike specialized models that perform a single function, MiMo-Audio is a generalist system that can process and generate audio and text in flexible combinations. This allows it to act as a unified solution for multiple distinct tasks.
A Unified Model for Speech AI
According to its release materials on Hugging Face, the instruction-tuned model is capable of performing a variety of functions, including:
- Speech Recognition (ASR): Transcribing spoken audio to text.
- Text-to-Speech (TTS): Synthesizing speech from written text.
- Speech-to-Speech Translation (S2ST): Translating spoken language directly into another spoken language.
- Audio Captioning and Generation: Describing sounds or creating audio from text prompts.
This flexibility makes MiMo-Audio a compelling foundation for building complex voice-enabled applications. By releasing a capable, general-purpose audio model under an open license, Xiaomi is providing a significant building block for the open-source AI community and a strong alternative to proprietary speech APIs.
Sources
- Visit
XiaomiMiMo/MiMo-Audio-7B-Instruct
Hugging Face
More from Xiaomi
All Xiaomi releases →Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
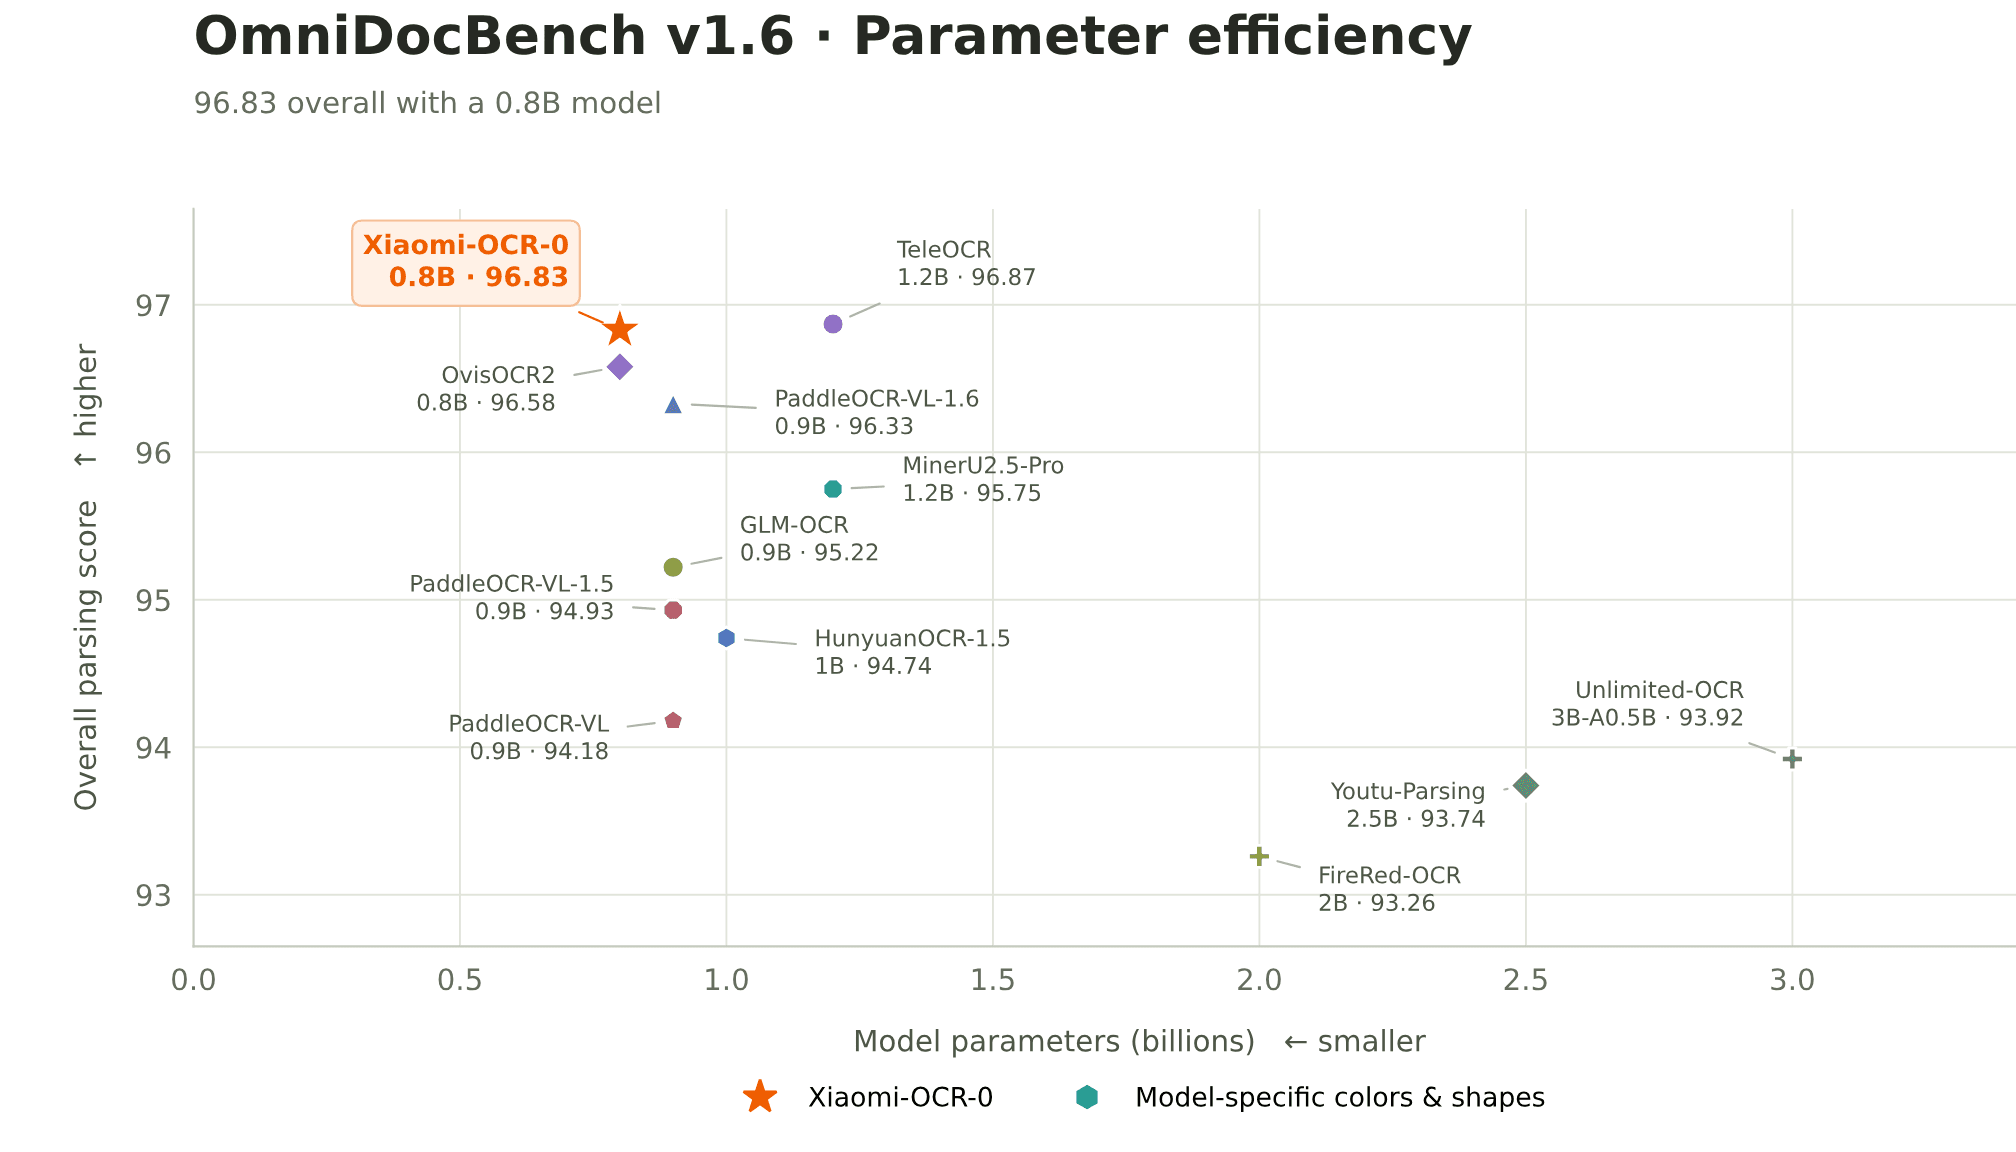
Xiaomi Enters Document OCR With New Vision Model
The company's research arm releases Xiaomi-OCR-0, a document-parsing vision-language model built on a Qwen3.5 backbone.

Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.