Xiaomi expands MiMo line with V2.6 multimodal models
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
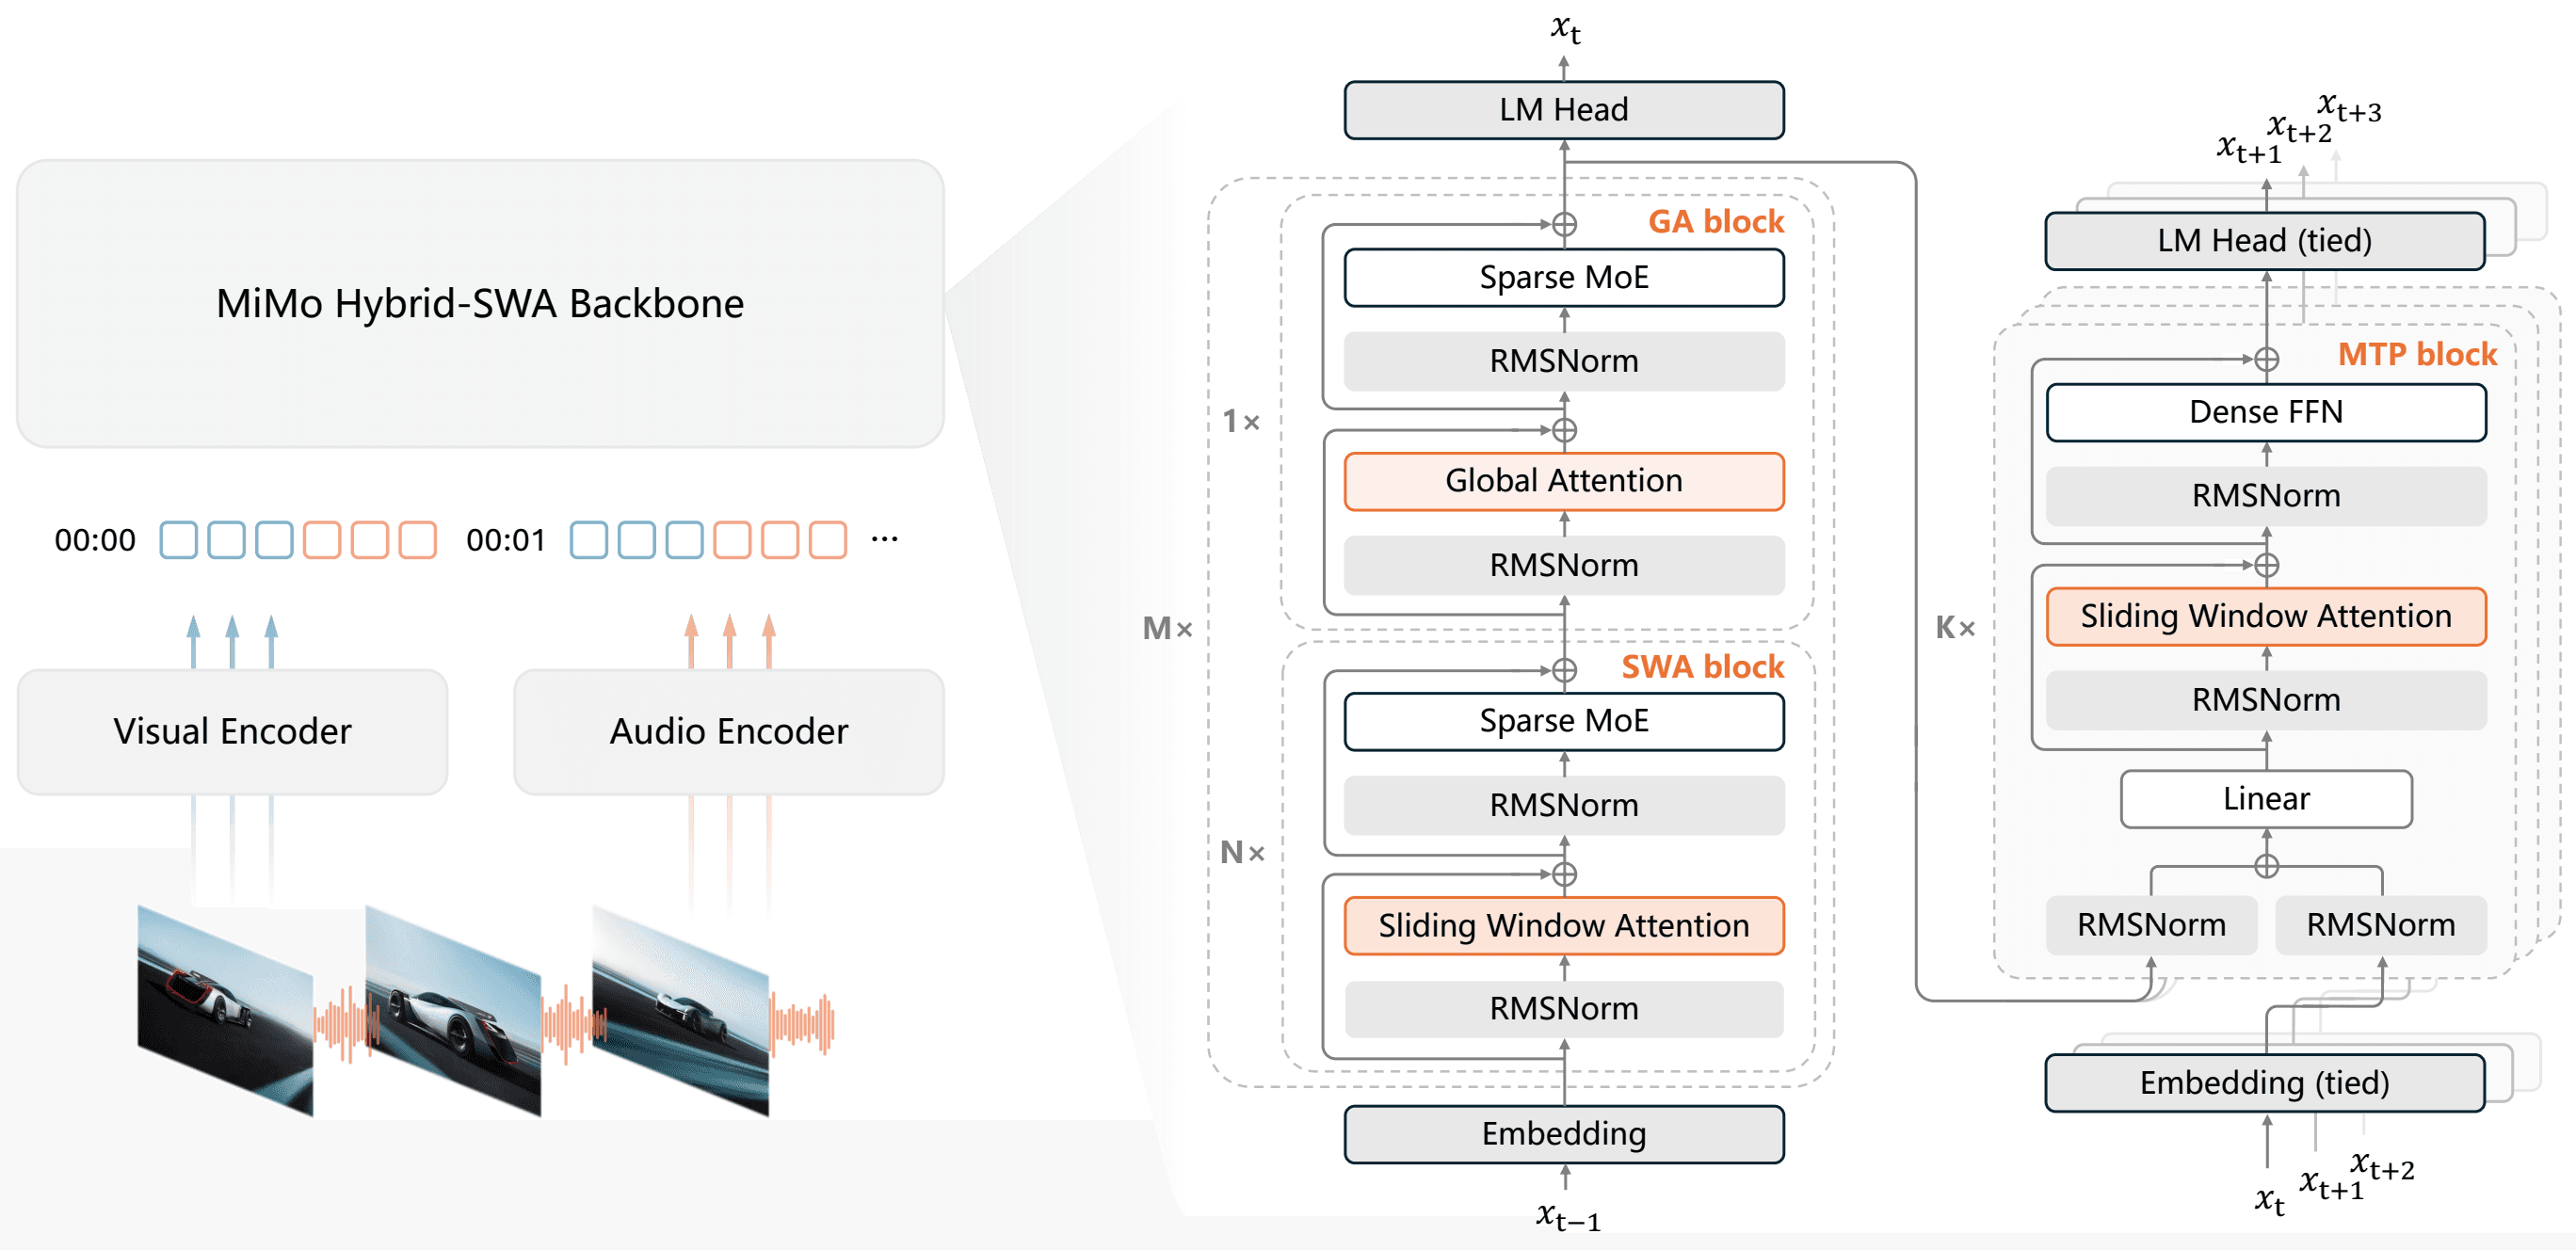
Xiaomi has published MiMo V2.6, a set of multimodal models trained with reinforcement learning that the company is releasing across three tiers — Flash, Pro, and Distill. The Flash-RL checkpoint on Hugging Face anchors the launch, positioning MiMo as an any-to-any system that handles vision and audio inputs alongside text.
The release leans into reasoning and agentic use. Xiaomi describes the models as combining vision-language understanding, audio, agent behavior, and long-context handling — the kind of feature set increasingly expected from frontier open releases, where a single model is meant to see, listen, plan, and act rather than just chat.
What's in the lineup
- Flash — the lighter, faster variant, published here as an RL-tuned checkpoint
- Pro — the higher-capability tier for more demanding workloads
- Distill — a compressed version aimed at cheaper deployment
Exact parameter counts, context windows, and benchmark figures aren't specified in the release record, and the weights ship under a custom license rather than a standard permissive one — worth checking before commercial use.
Why it matters: Xiaomi is one of several large consumer-hardware companies investing in open multimodal models, and a tiered Flash/Pro/Distill structure signals an intent to cover everything from on-device inference to server-side reasoning. For developers, that breadth makes MiMo V2.6 worth evaluating against the growing field of open vision-and-audio models.
Sources
- Visit
XiaomiMiMo/MiMo-V2.6-Flash-RL
Hugging Face
More from Xiaomi
All Xiaomi releases →Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
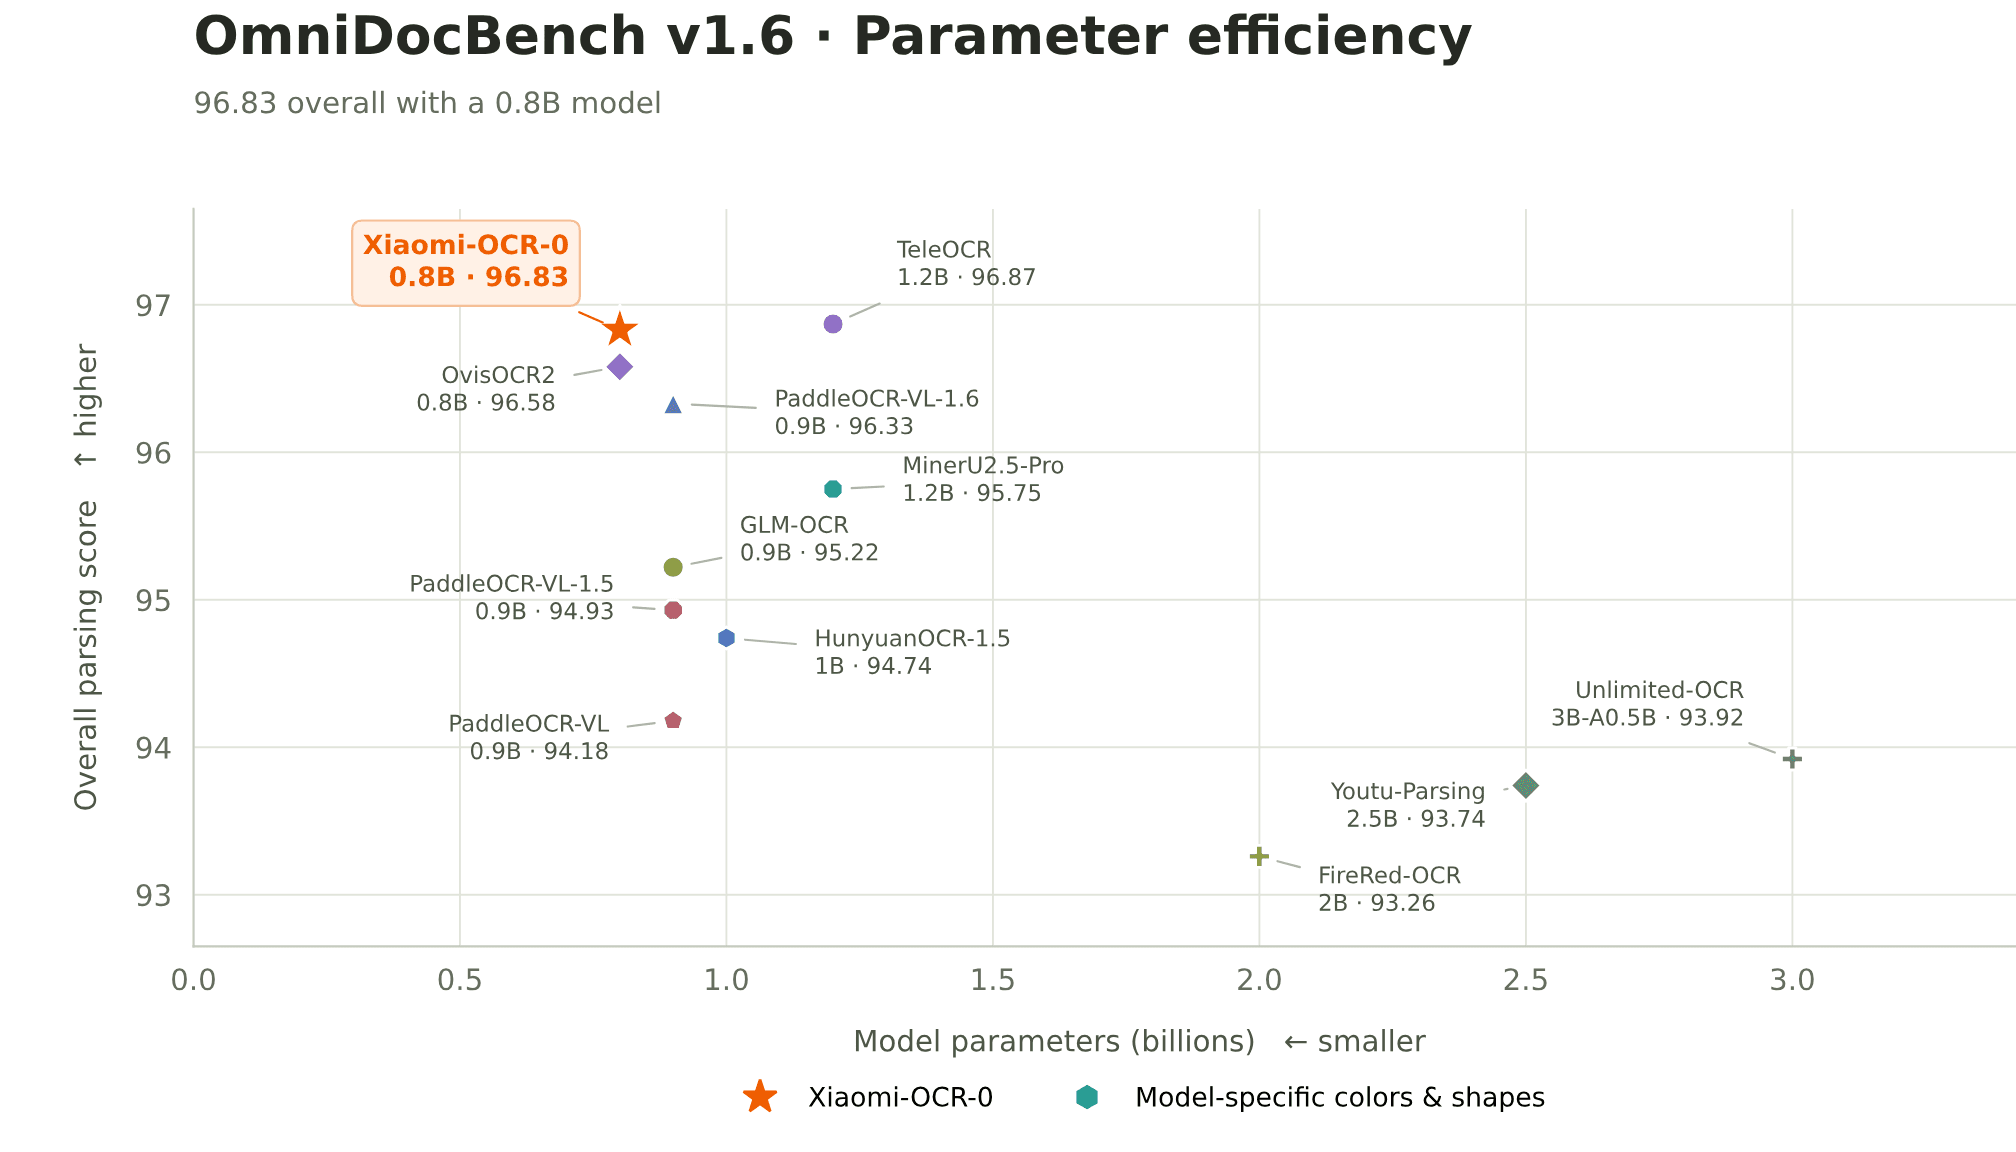
Xiaomi Enters Document OCR With New Vision Model
The company's research arm releases Xiaomi-OCR-0, a document-parsing vision-language model built on a Qwen3.5 backbone.

Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.