NVIDIA Releases Nemotron-3-Nano Omni-Modal MoE
The new 30-billion-parameter Mixture-of-Experts model handles any combination of modalities with just 3 billion active parameters.

NVIDIA has introduced Nemotron-3-Nano-Omni, a powerful new model designed for sophisticated multimodal tasks. The model employs a Mixture-of-Experts (MoE) architecture, a technique that activates only a fraction of its total parameters for any given task, leading to significant computational savings.
With a total of 30 billion parameters, Nemotron-3-Nano-Omni uses just 3 billion active parameters during inference. This efficient design allows it to deliver the performance of a much larger model without the corresponding computational overhead, making advanced reasoning more accessible. The model is available with BF16 weights, a common format for balancing performance and precision.
Any-to-Any Reasoning
The model's key feature is its "omni-modal" capability, allowing it to process and generate information across different formats seamlessly. It can handle what the company calls "any-to-any" tasks, meaning it can ingest a mix of inputs—such as text, images, and video—and produce a mix of outputs in response. This flexibility is critical for complex applications that require understanding context across multiple data types.
Nemotron-3-Nano-Omni represents a notable step forward for efficient and versatile AI. While it is governed by a custom NVIDIA license rather than a permissive open-source one, its availability on the Hugging Face Hub enables researchers and developers to experiment with its unique multimodal reasoning capabilities.
Sources
- Visit
nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
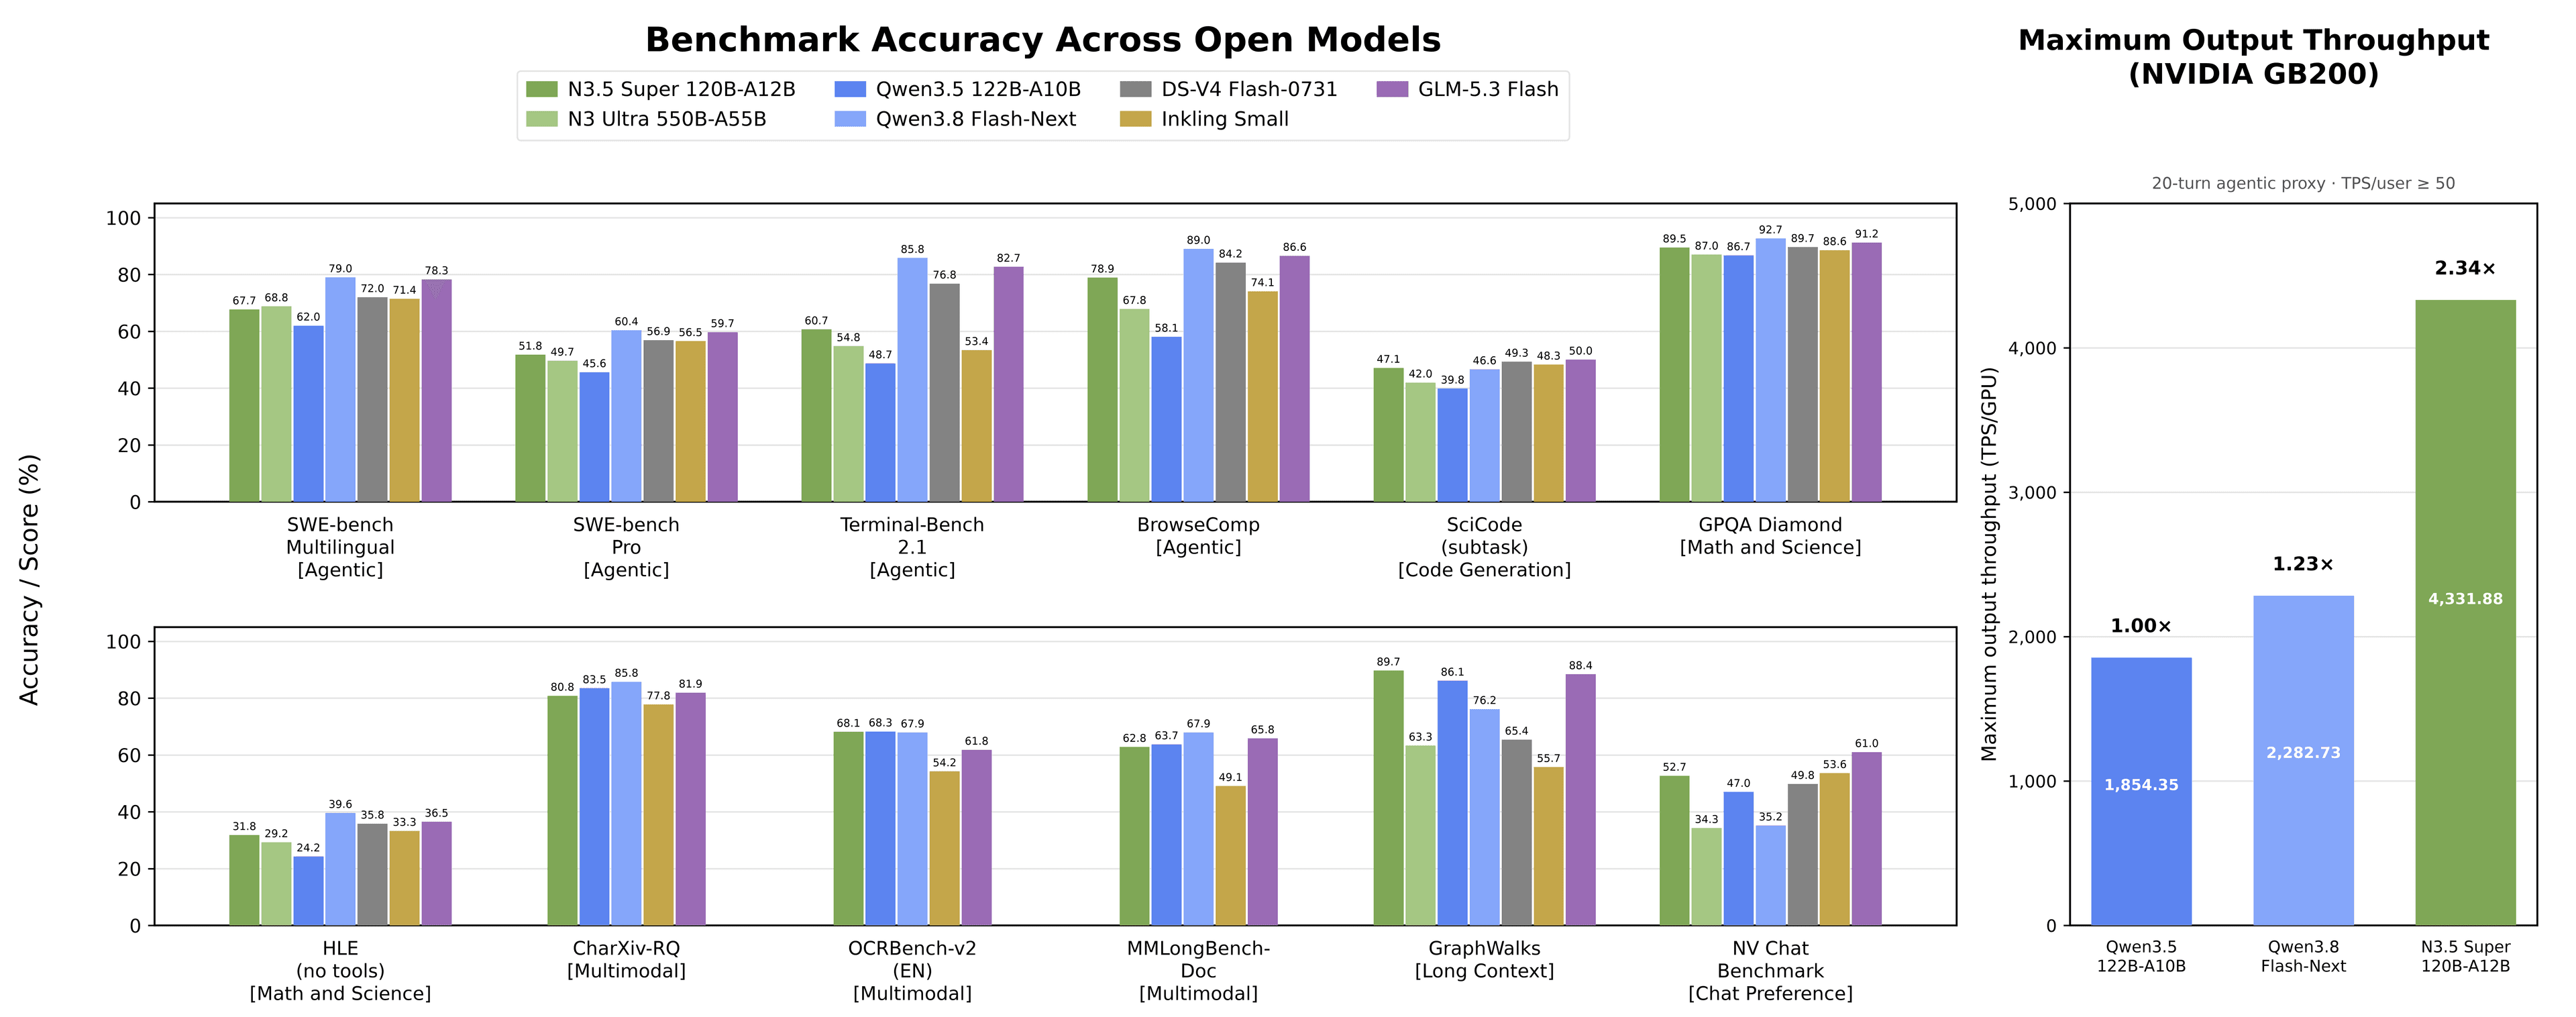
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
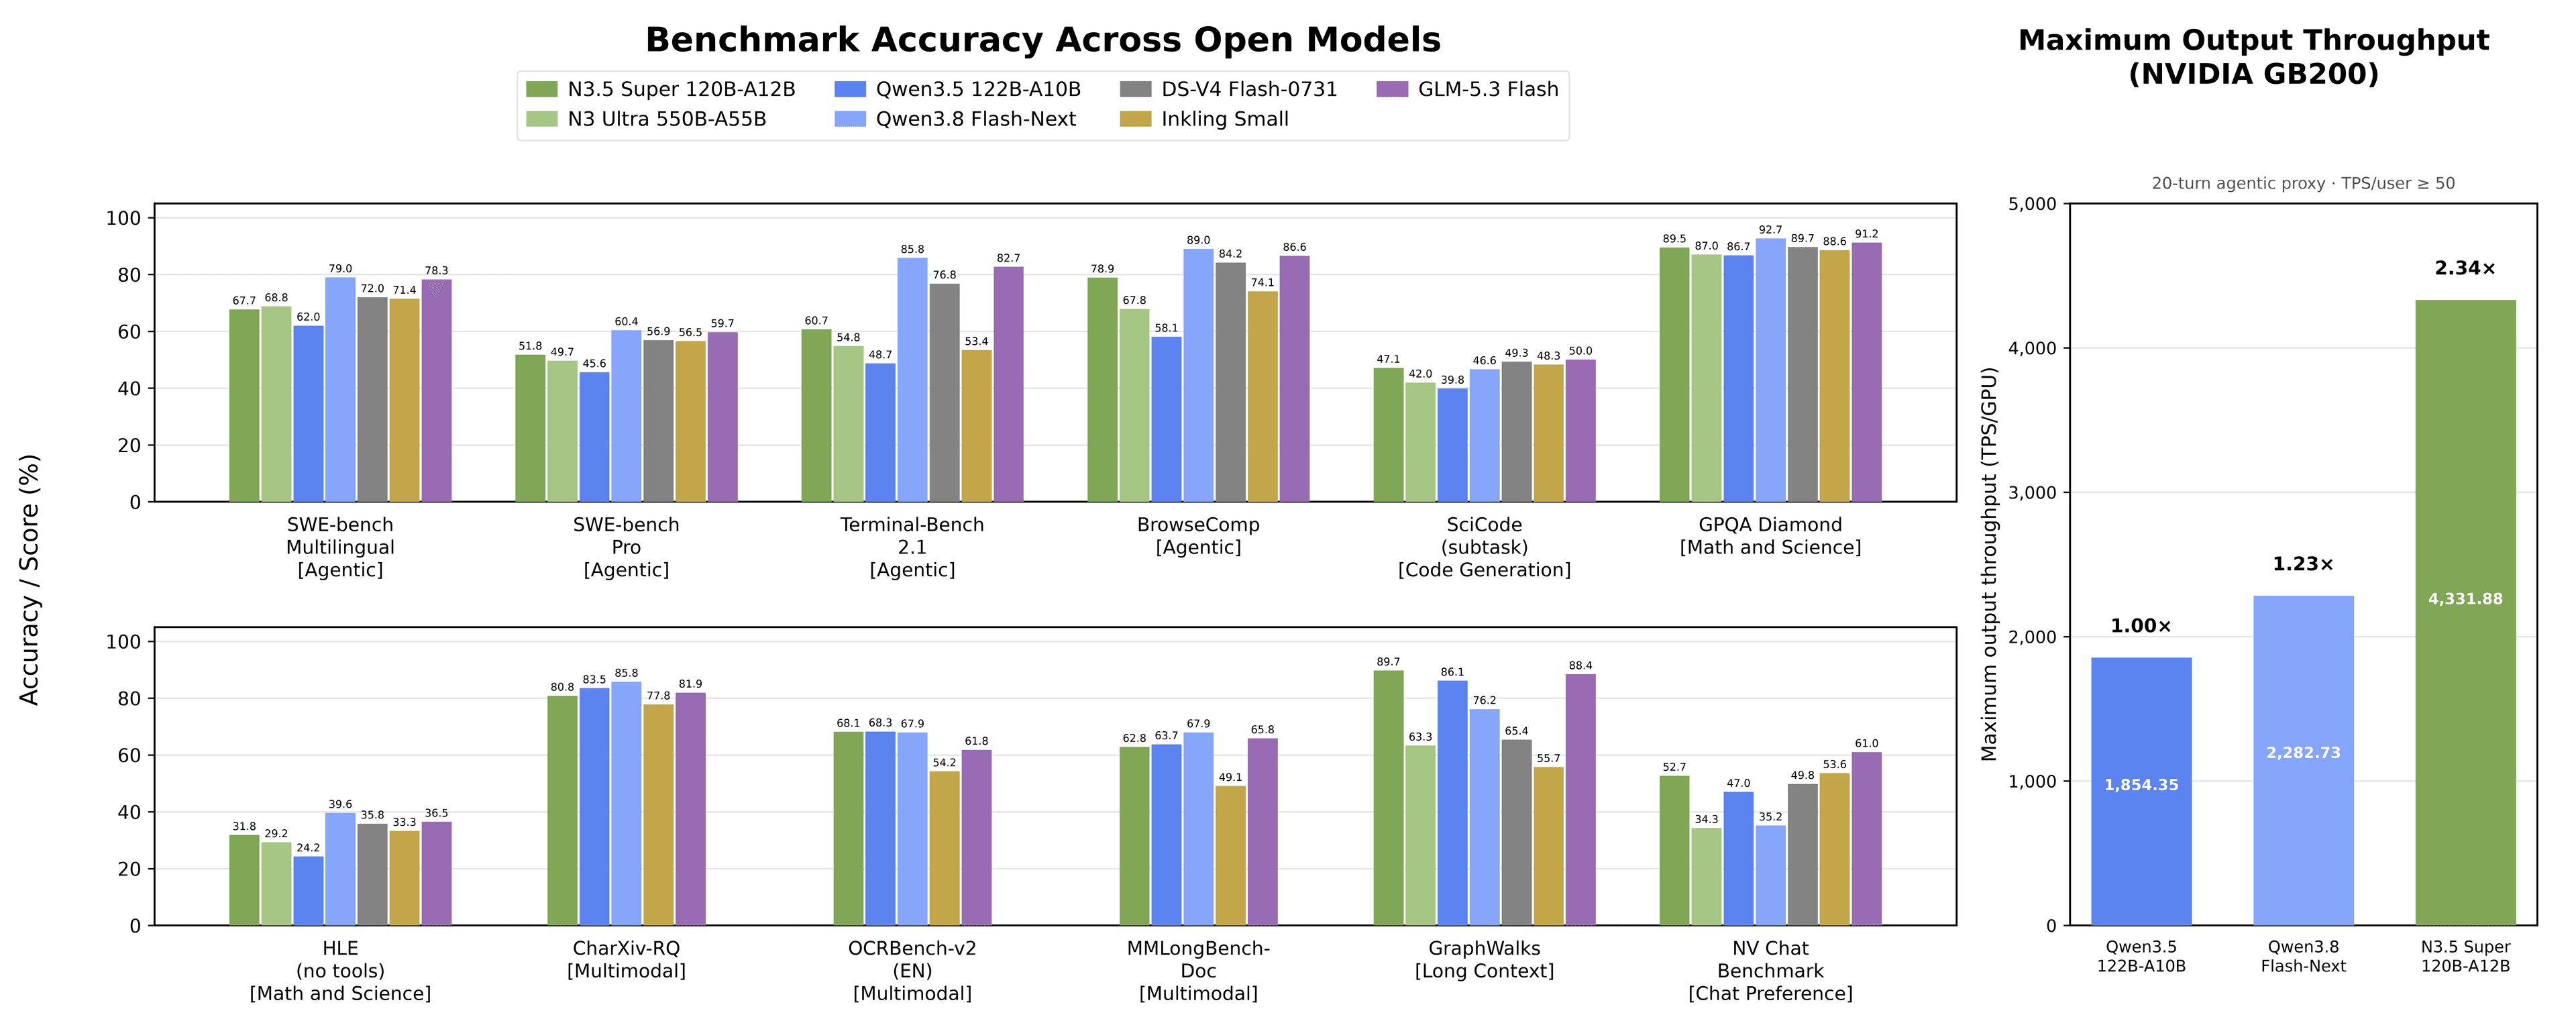
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.