NVIDIA's Nemotron TwoTower mixes diffusion and Mamba
A new 30B mixture-of-experts base model activates just 3B parameters per token and pairs a hybrid diffusion/Mamba design.

NVIDIA has published Nemotron TwoTower 30B-A3B Base, an open-weights language model that leans on a few unusual architectural choices at once. According to its Hugging Face repository, the model is a mixture-of-experts system with 30 billion total parameters but only about 3 billion active per token — the "A3B" in its name — released in BF16 precision.
The more distinctive part is the "TwoTower" design, which the release describes as a hybrid combining diffusion and Mamba-style components. Mamba is a state-space approach that offers an alternative to standard attention, while diffusion-based text generation departs from the autoregressive decoding most large language models rely on. Bringing both into a single MoE base model is an experimental direction rather than a conventional transformer stack.
Why it matters
MoE models like this one are attractive because they decouple capacity from compute cost: you get the knowledge capacity of a larger network while only paying to run a small slice of it per token. Pairing that with state-space and diffusion ideas signals NVIDIA's continued willingness to test architectures beyond the standard playbook.
A few practical notes from the record:
- This is a base model, not an instruction-tuned chat variant
- Listed language coverage is English, Spanish, and French
- It ships under a custom ("other") license, so teams should read the terms before commercial use
Context length isn't specified in the release metadata, and as a base checkpoint it's aimed at researchers and builders who want to fine-tune or study the architecture rather than drop it into production as-is. For anyone tracking how hybrid designs perform at scale, it's a concrete artifact to probe.
Sources
- Visit
nvidia/Nemotron-TwoTower-30B-A3B-Base-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
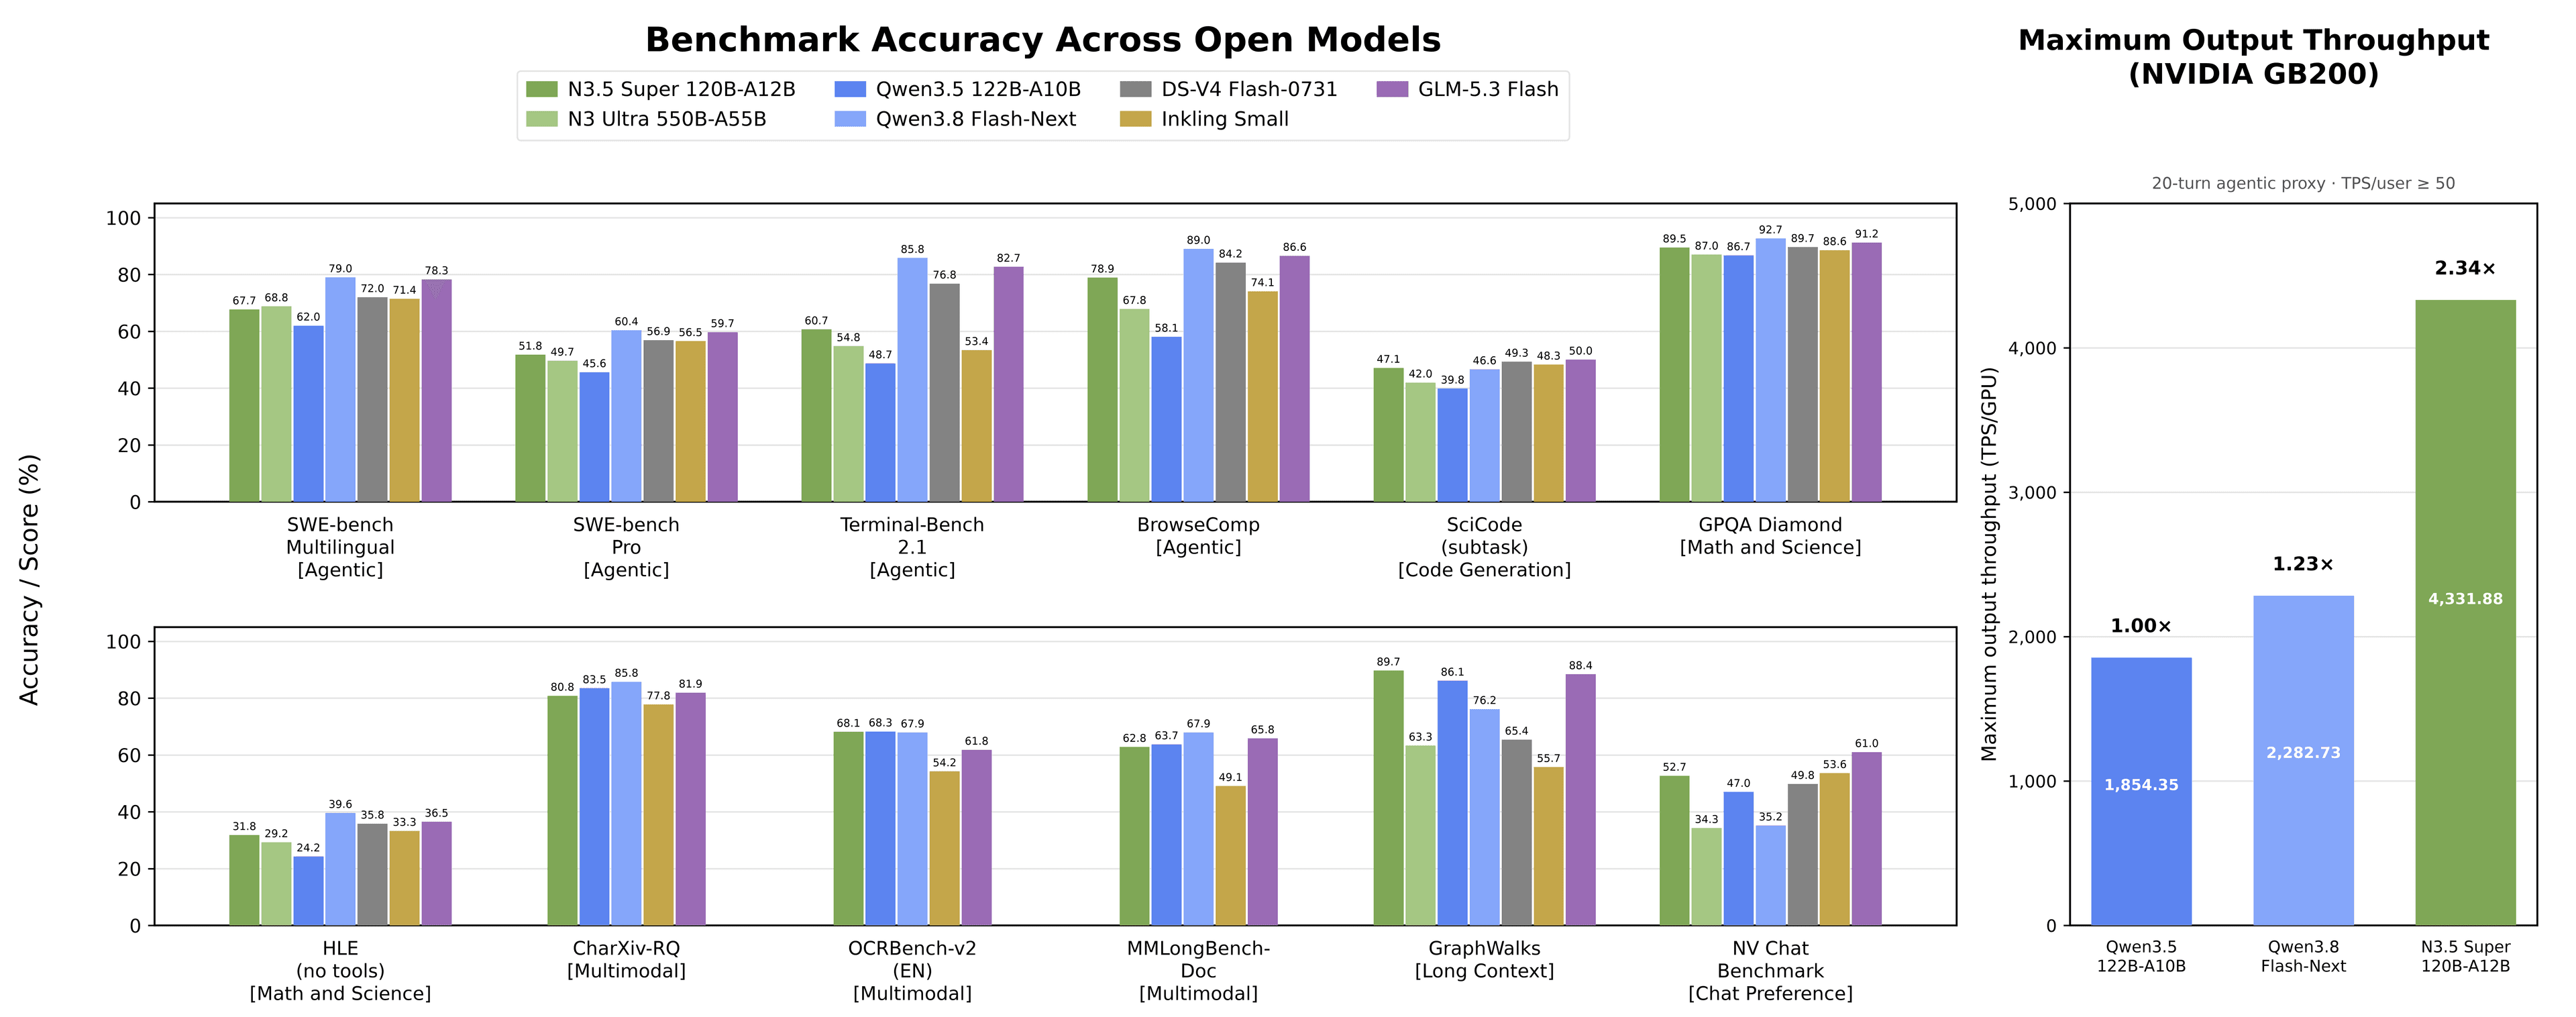
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
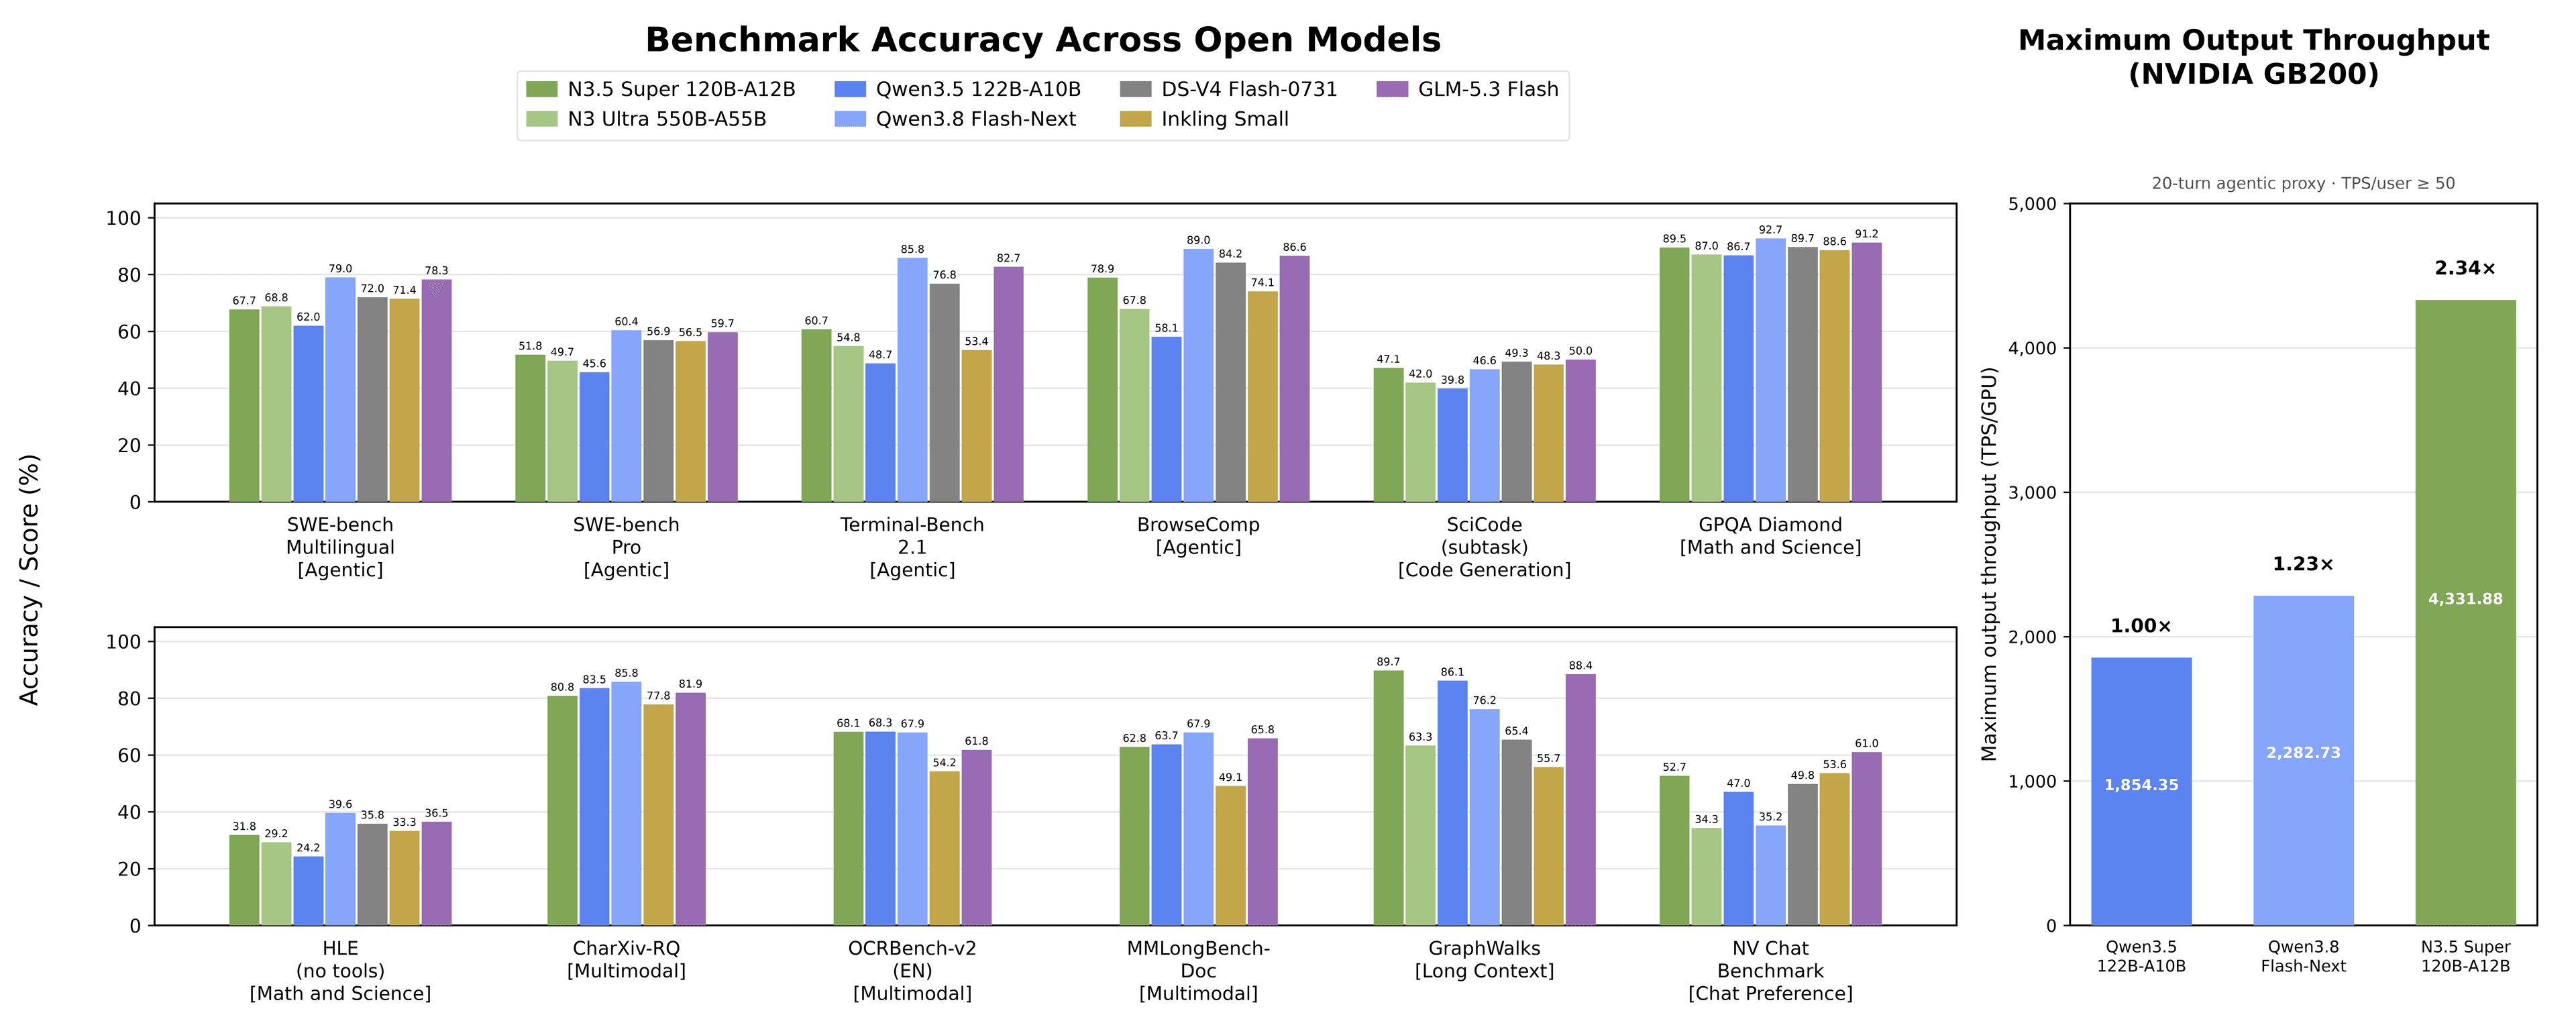
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.