NVIDIA Fuses LLM and ASR in Canary-Qwen 2.5B Model
The 2.5 billion-parameter speech model combines a FastConformer encoder with a Qwen LLM decoder, a hybrid approach to transcription.
NVIDIA has released Canary-Qwen 2.5B, a new model for automatic speech recognition (ASR) that takes a novel architectural approach. Instead of a single, end-to-end network, the 2.5 billion-parameter model pairs a specialized audio encoder with a general-purpose large language model for decoding text.
This hybrid design is the model's key feature. It uses a FastConformer encoder, a component optimized for efficiently processing audio signals, to understand the input speech. The resulting representation is then handed off to a decoder based on a Qwen large language model. This allows the system to leverage the powerful text generation and contextual understanding of an LLM to produce more accurate and natural-sounding transcriptions.
The model is designed to be multilingual and handle tasks like punctuation and capitalization automatically, which are common challenges for ASR systems. This approach of using an LLM as a "brain" for a specialized task reflects a broader trend in AI, where generalist models are adapted to enhance specific applications.
Canary-Qwen 2.5B is available on Hugging Face under a custom community license. Its release provides developers with a powerful new tool for speech-to-text applications and a clear example of how different model architectures can be effectively combined.
Sources
- Visit
nvidia/canary-qwen-2.5b
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
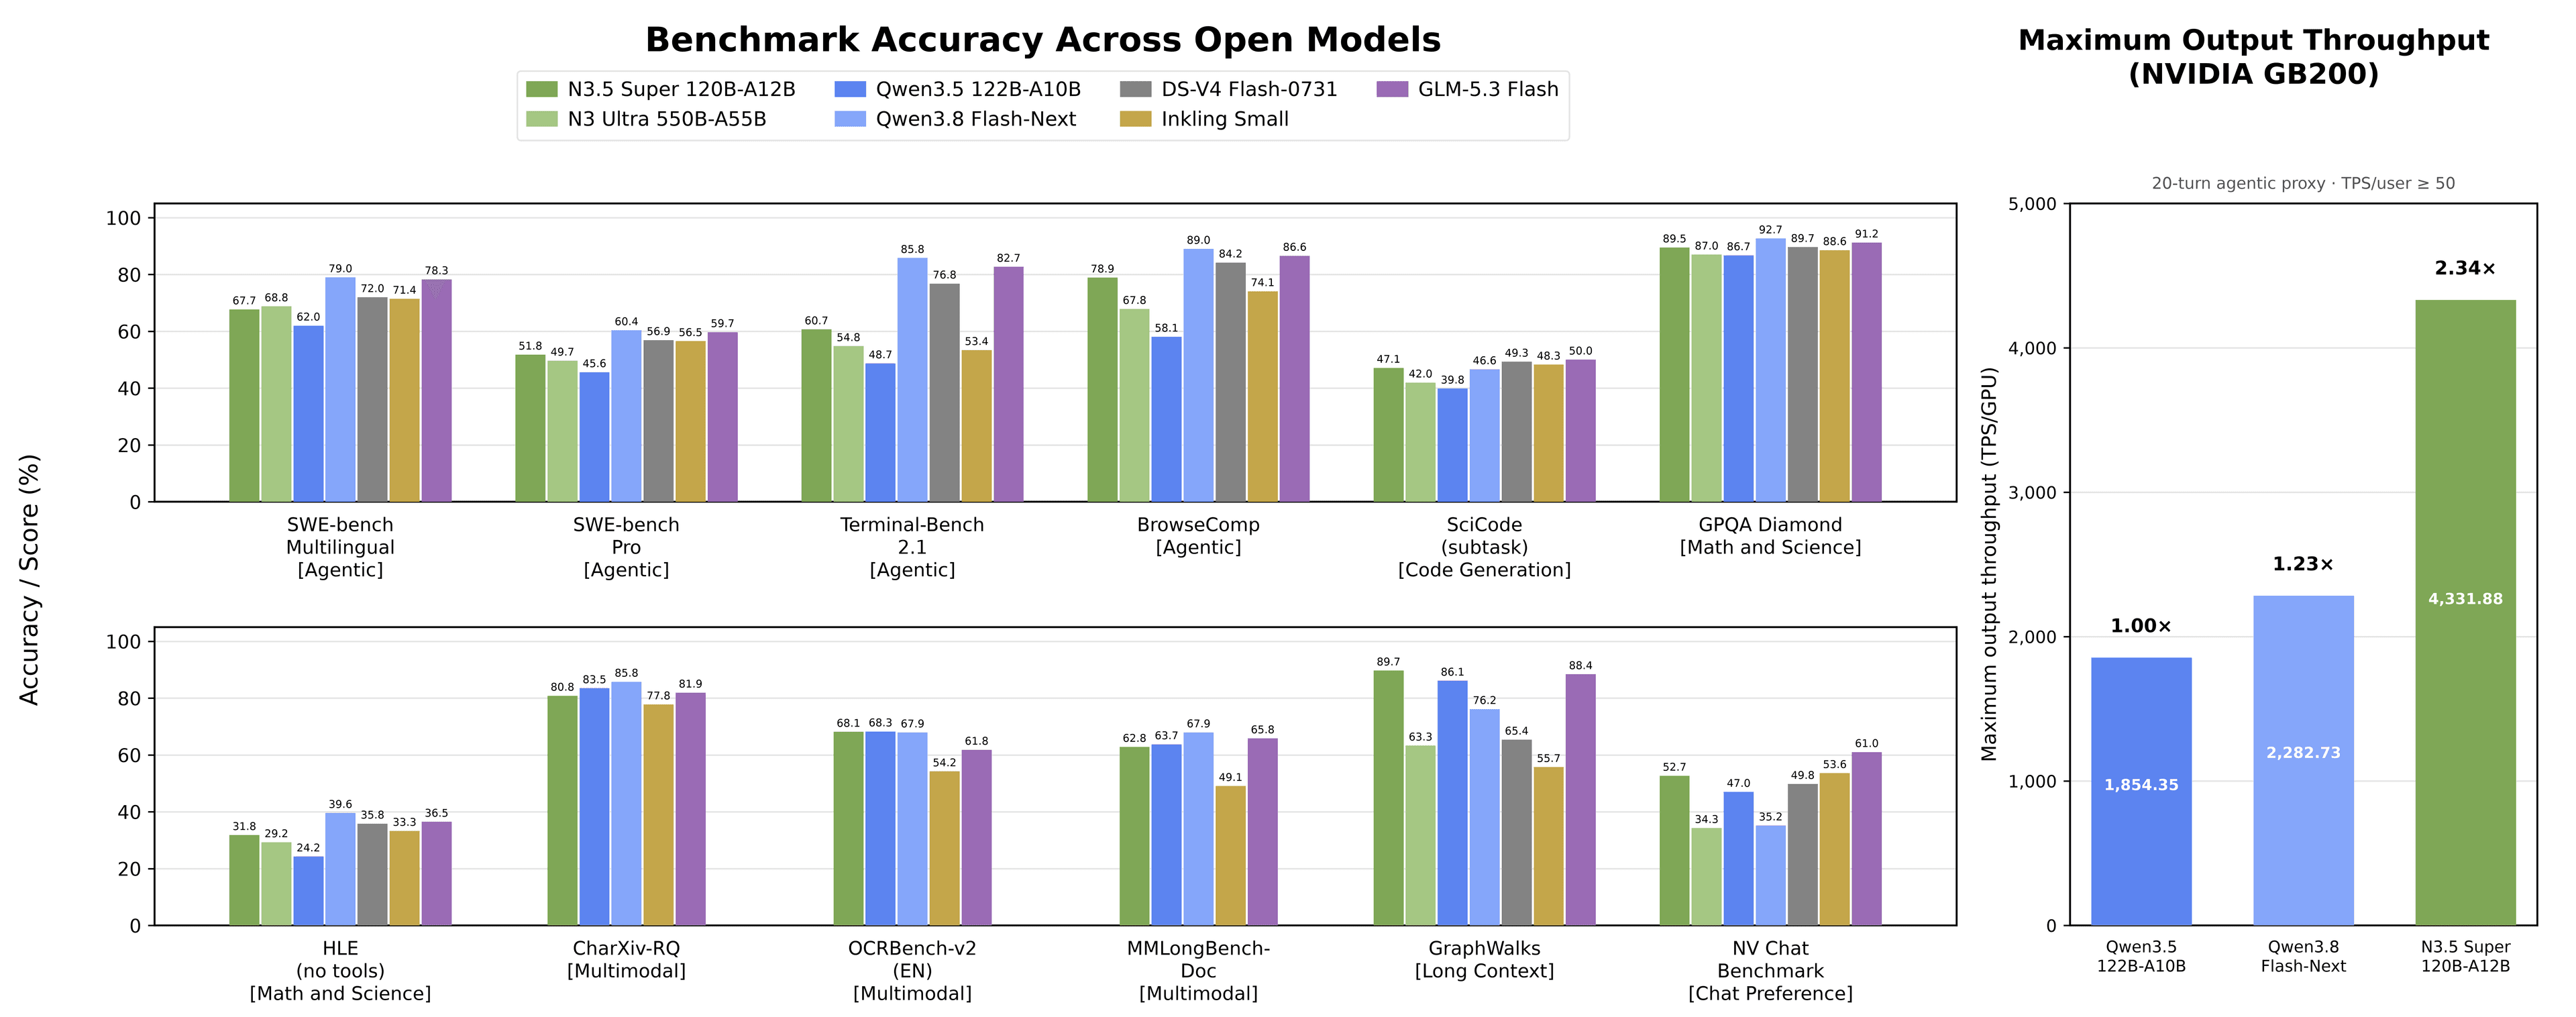
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
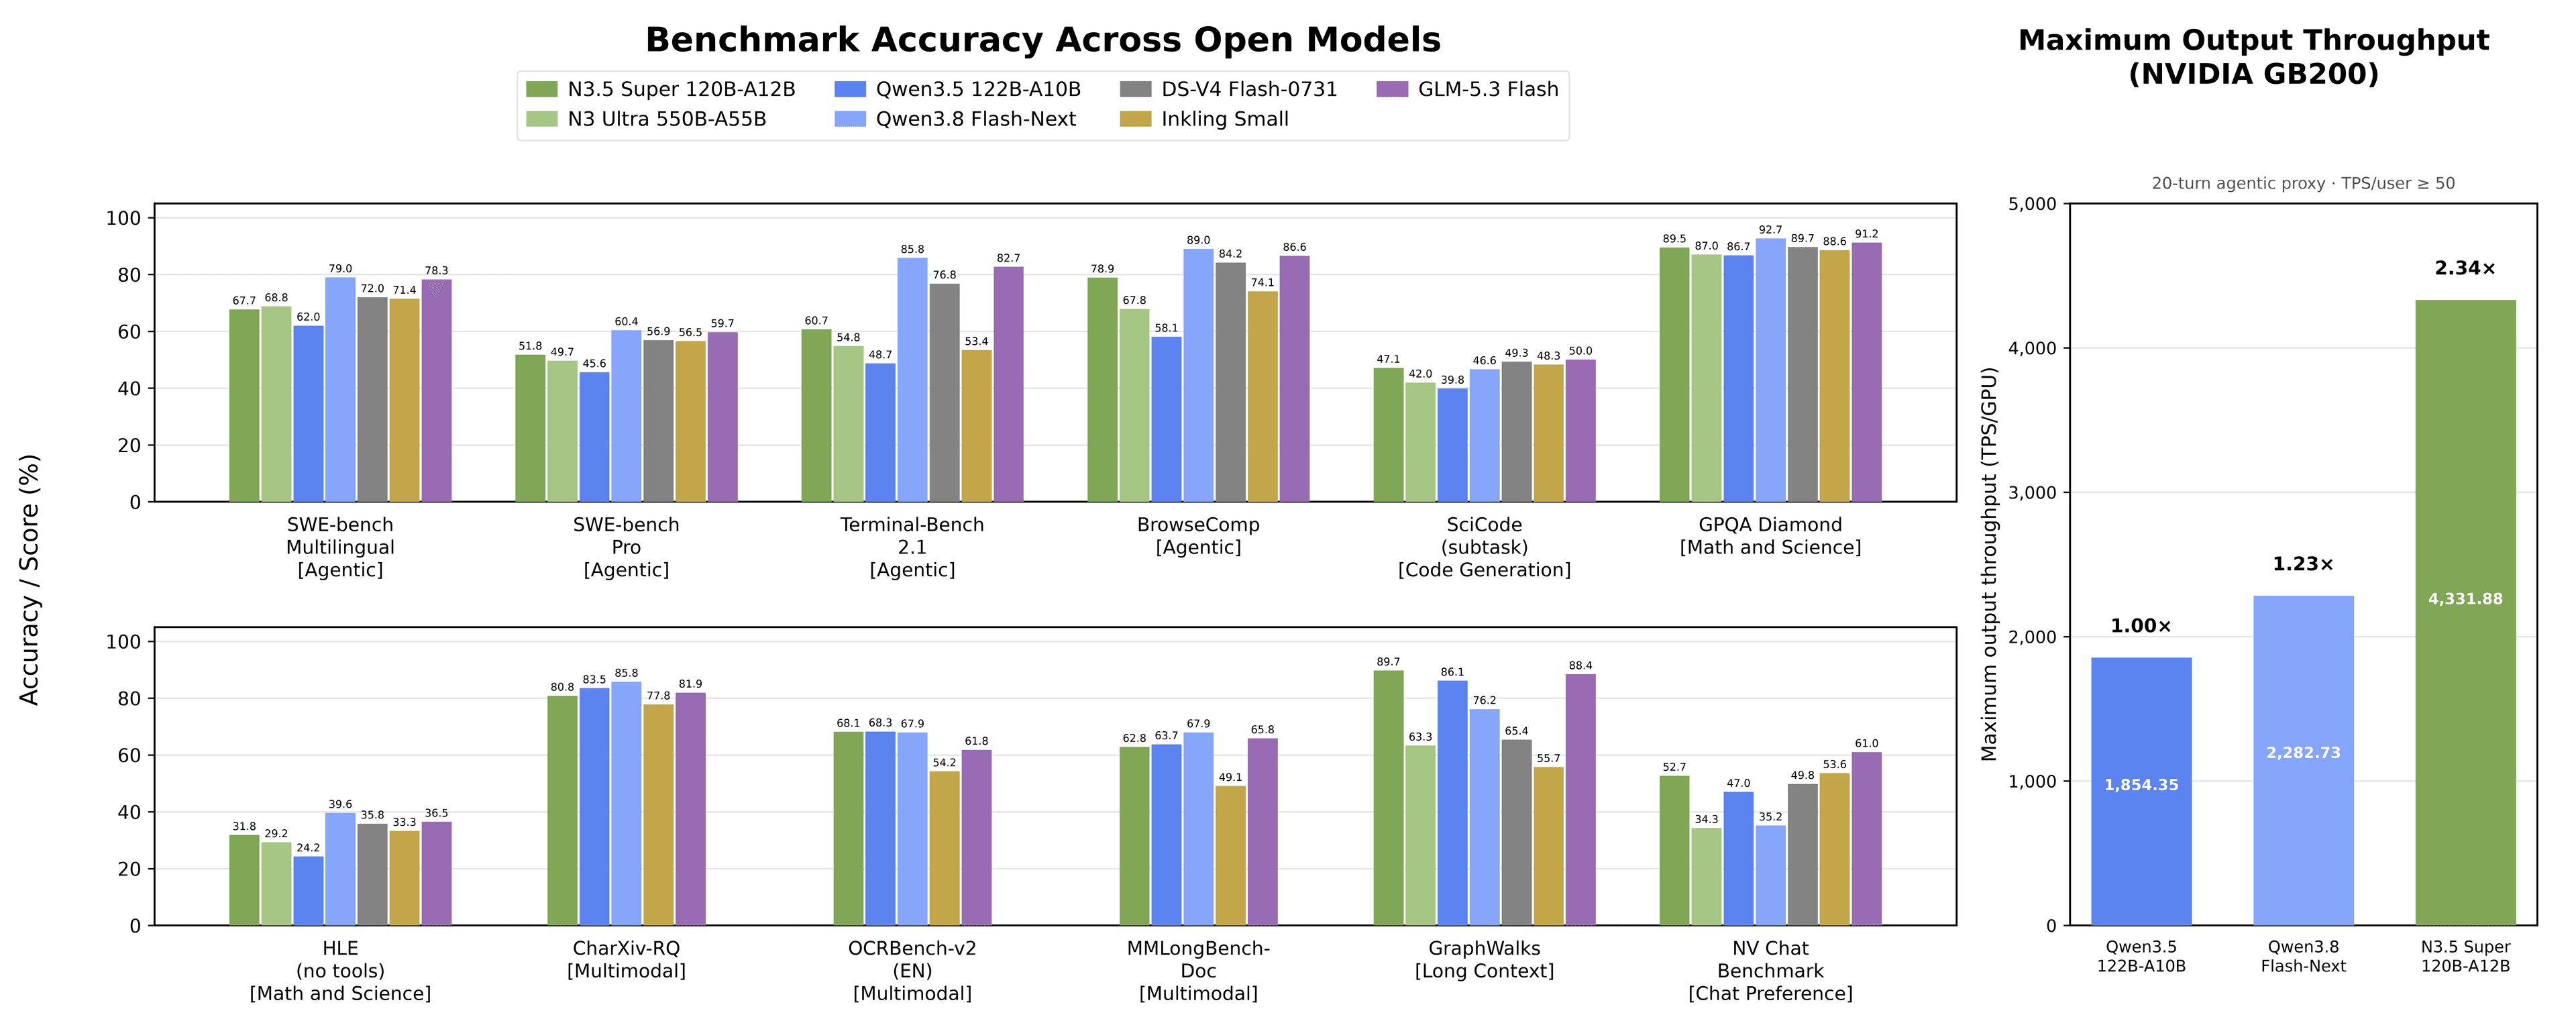
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
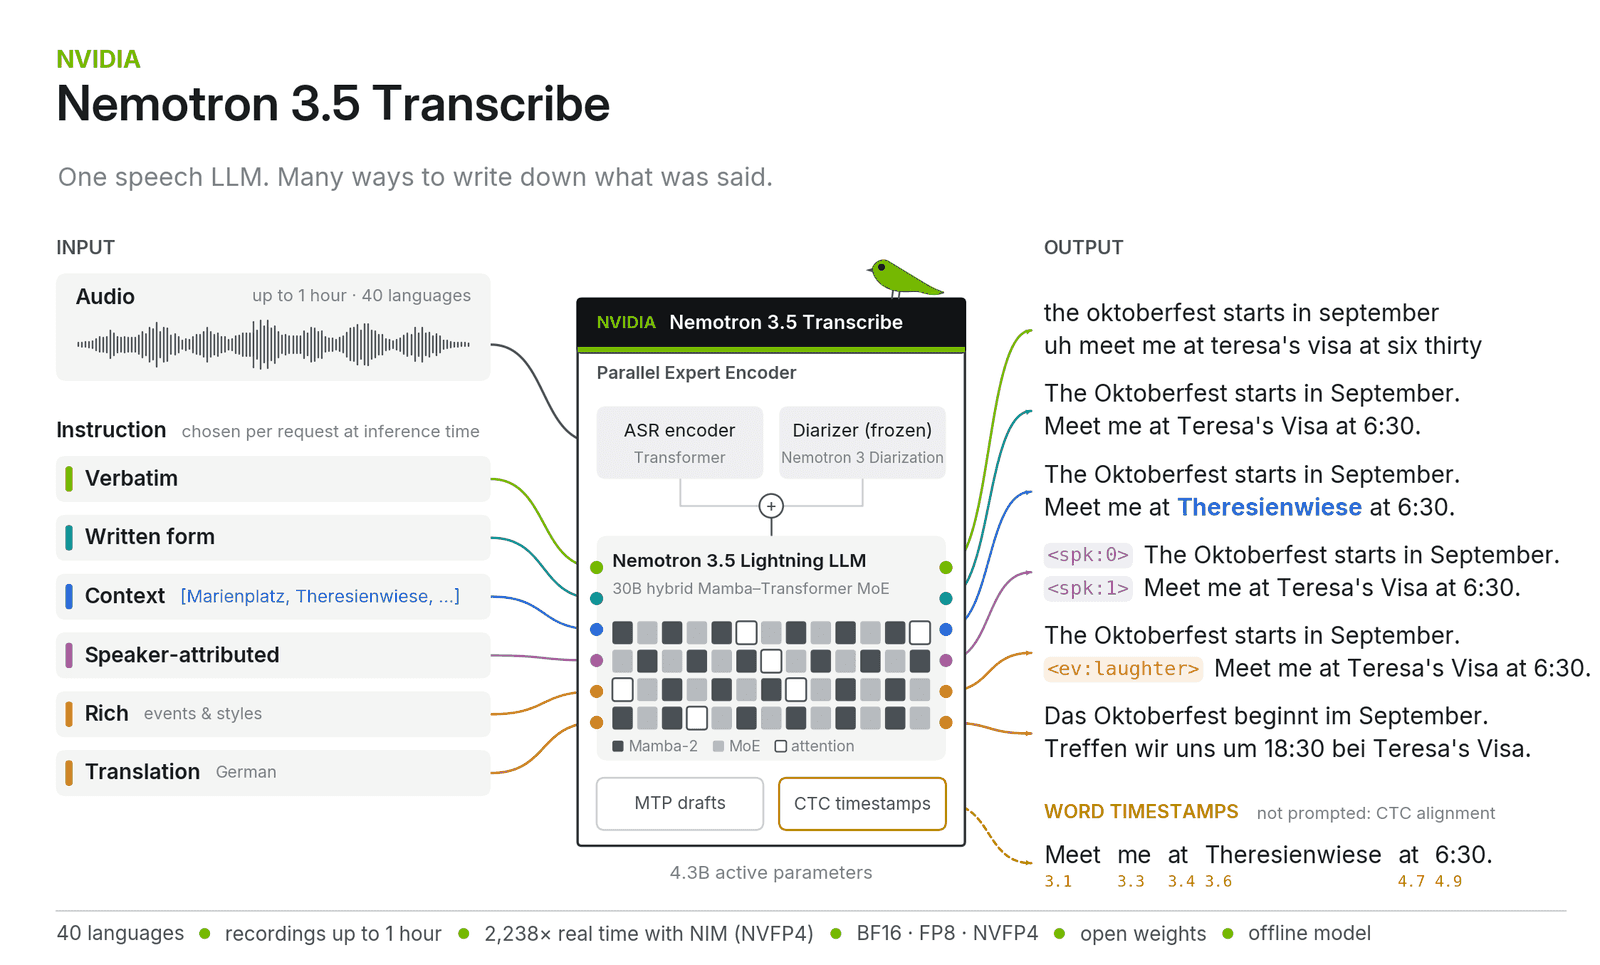
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.