NVIDIA Releases Streaming Speech-to-Text Model
The 600-million-parameter Nemotron model is designed for real-time English transcription using a cache-aware FastConformer architecture.
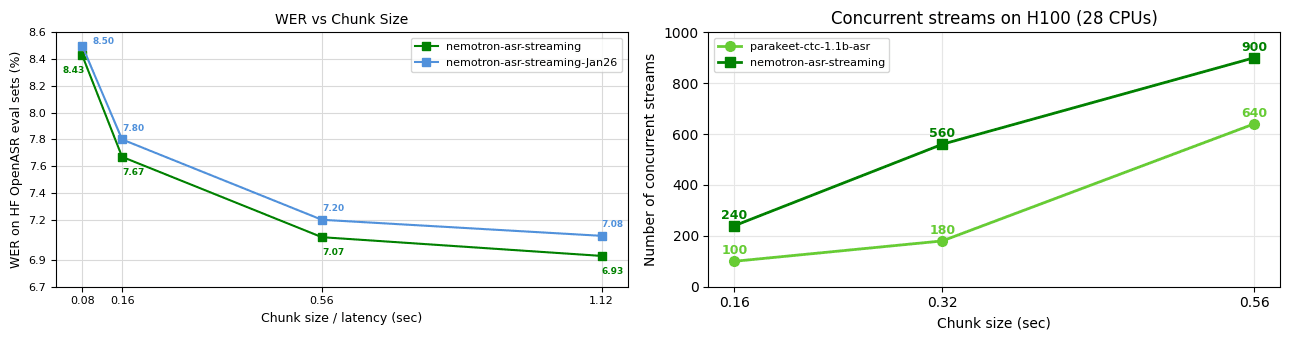
NVIDIA has released a new model for automatic speech recognition (ASR), Nemotron Speech Streaming EN 0.6B. This 600-million-parameter model is specifically engineered for real-time, streaming transcription of English audio, making it suitable for applications that require immediate output.
Built for Real-Time Performance
The model is based on the FastConformer architecture, an effective design for speech recognition. Its key feature is its "cache-aware streaming" capability, which allows it to process audio in small chunks as it arrives rather than waiting for an entire recording. By intelligently managing its internal state, or cache, between these chunks, the model can deliver continuous transcription with minimal delay.
This streaming approach is critical for interactive voice applications. Potential use cases include:
- Live captioning for broadcasts and events
- Responsive voice assistants
- Real-time transcription for meetings or customer service calls
By releasing a specialized model for this task, NVIDIA provides developers with another tool for building responsive, voice-enabled products. The model is available on Hugging Face under the NVIDIA Open Model License Agreement, and interested users can find full details in the official repository.
Sources
- Visit
nvidia/nemotron-speech-streaming-en-0.6b
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
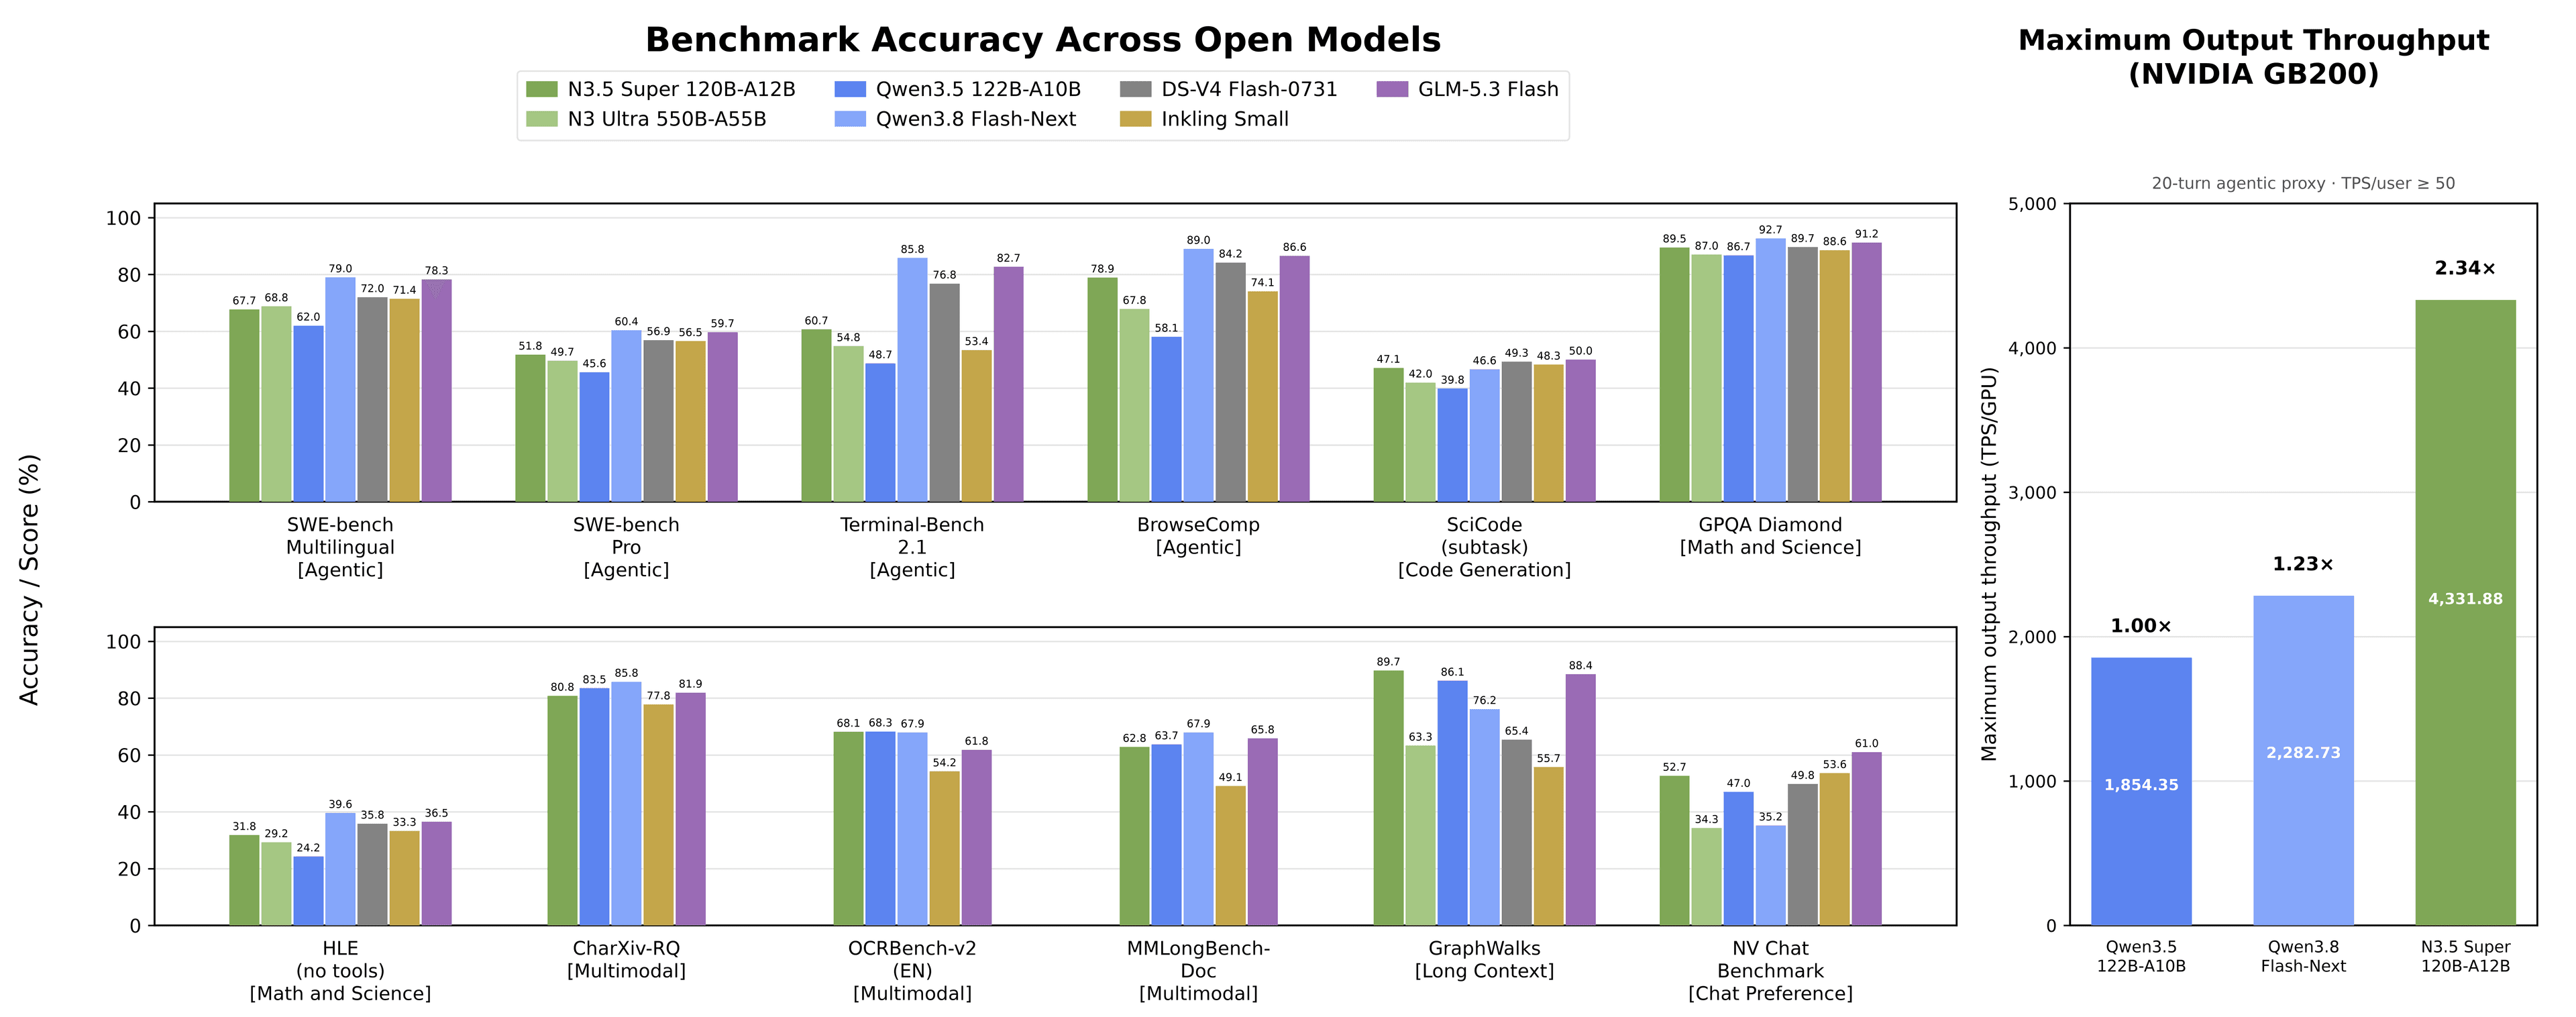
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
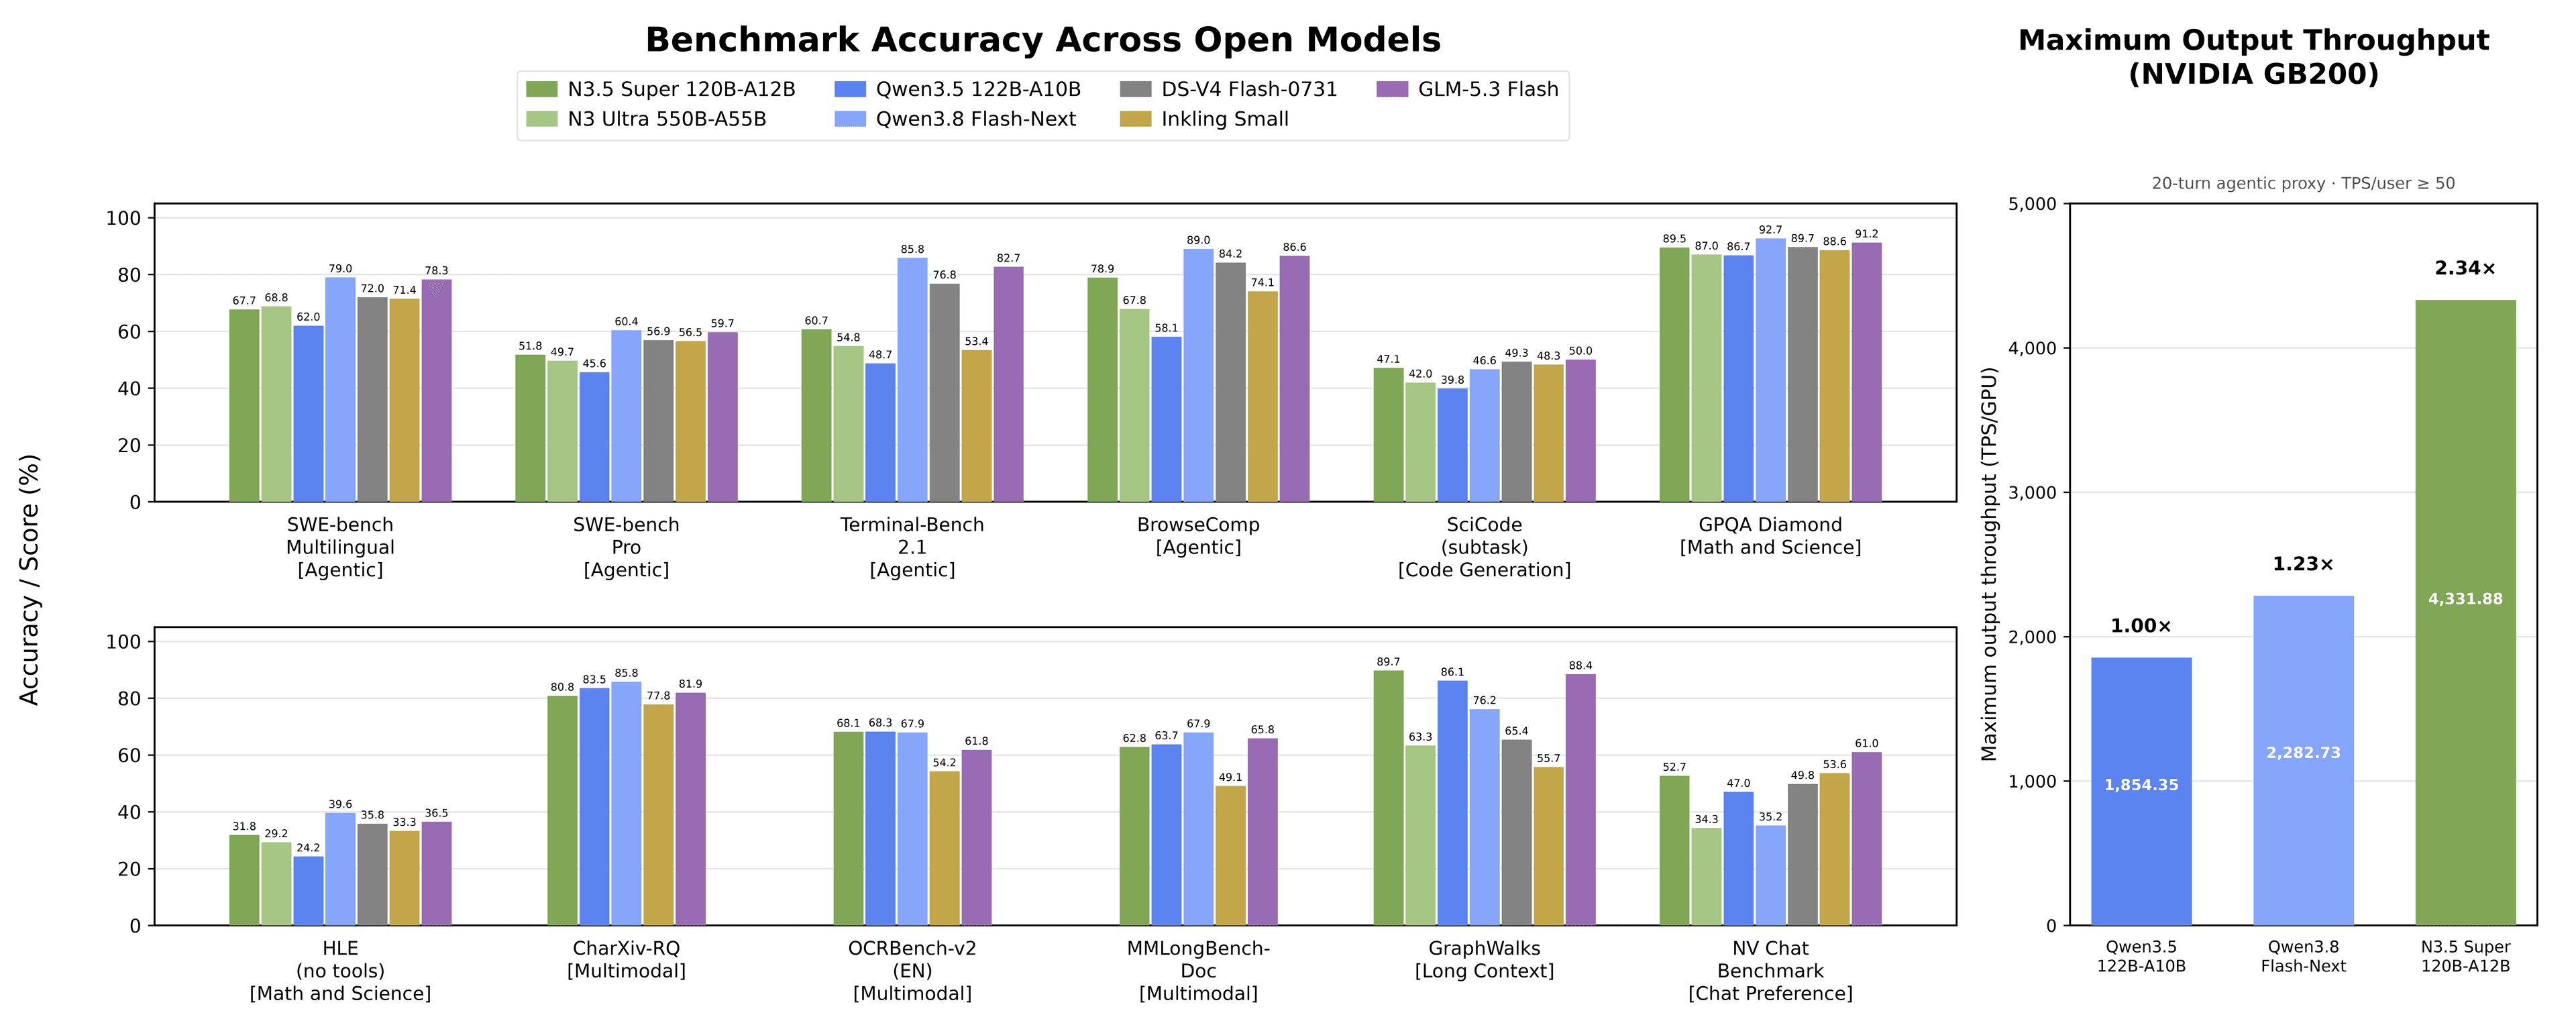
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
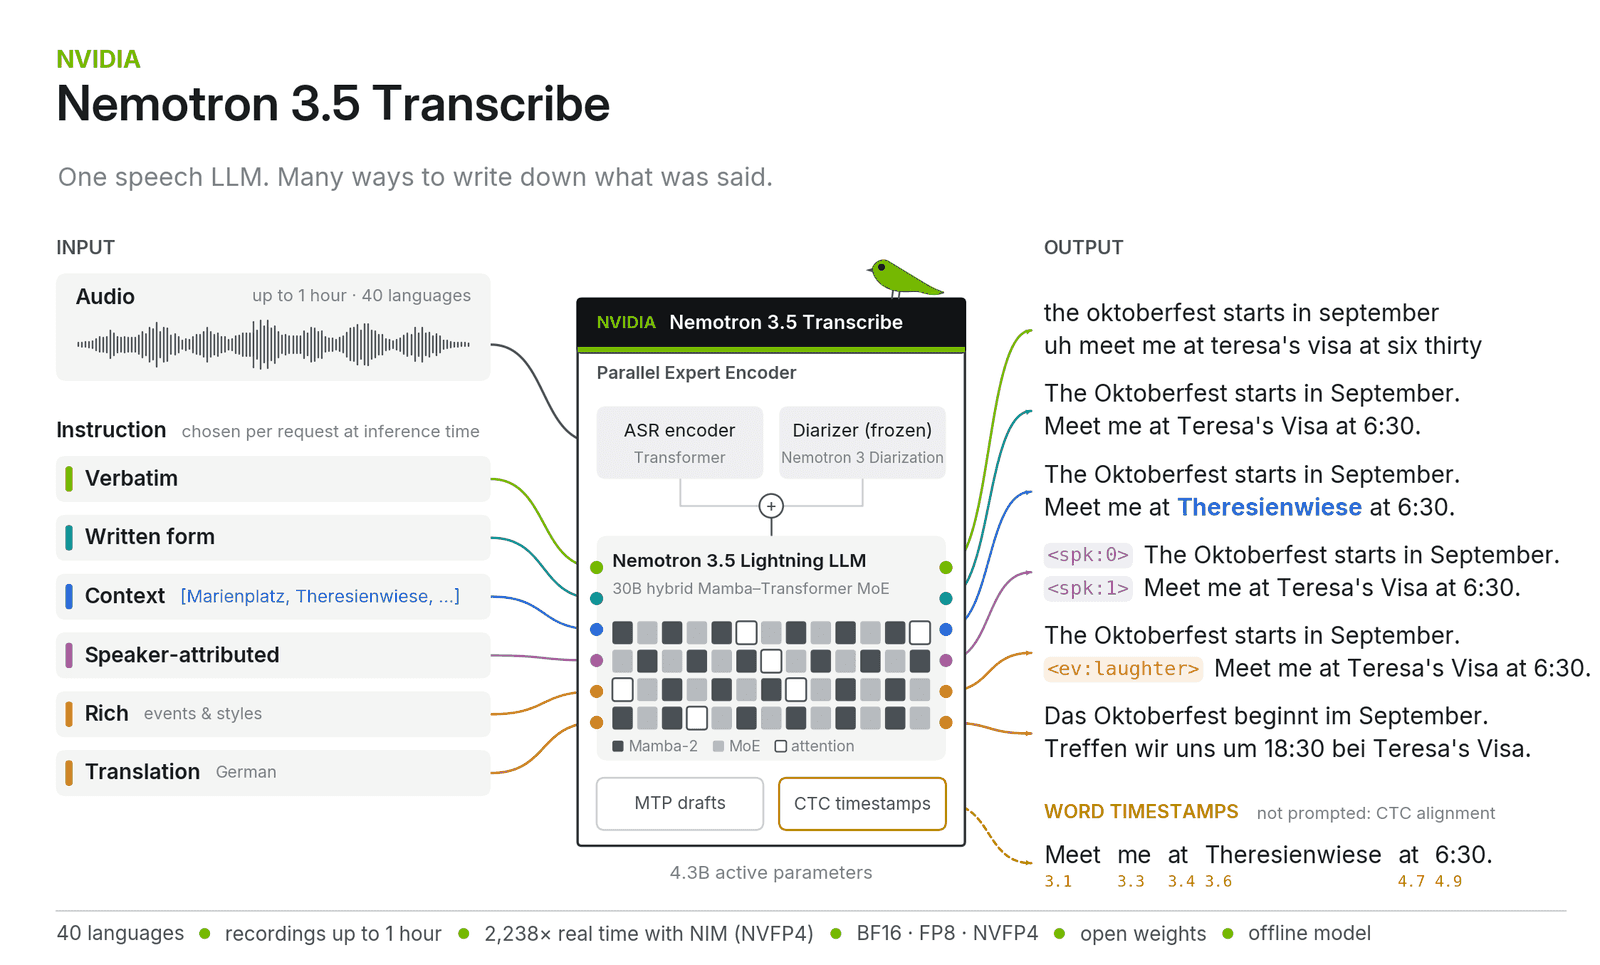
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.