NVIDIA's Nemotron 3 Embed tops the RTEB leaderboard
A compact 1B-parameter text embedding model claims the top overall spot on a retrieval benchmark aimed at reflecting real-world use.
NVIDIA has released Nemotron 3 Embed 1B, a text embedding model that the company says ranks first overall on the Retrieval Embedding Benchmark (RTEB). At roughly one billion parameters, it is small enough to run economically while aiming for state-of-the-art retrieval quality, and it ships in BF16 on Hugging Face.
Embedding models are the quiet workhorses of modern AI systems. They convert text into dense vectors that power semantic search, recommendation, and the retrieval step in retrieval-augmented generation (RAG). A better embedding model directly improves how relevant the documents a system pulls in are, which in turn shapes the quality of everything downstream.
Why it matters
RTEB is designed to measure retrieval performance in ways meant to reflect practical deployment rather than benchmark overfitting, so a top ranking there is a meaningful signal for teams building search and RAG pipelines. A few things stand out about this release:
- It leads the RTEB leaderboard overall despite a modest 1B parameter footprint.
- Its small size makes it cheaper to serve at scale than many larger embedding models.
- NVIDIA is releasing open weights, giving developers a strong self-hostable option.
The model is distributed under a custom NVIDIA license rather than a standard open-source license, so teams should review the terms before production use. Full details and evaluation results are in NVIDIA's announcement post.
Sources
- Visit
nvidia/Nemotron-3-Embed-1B-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
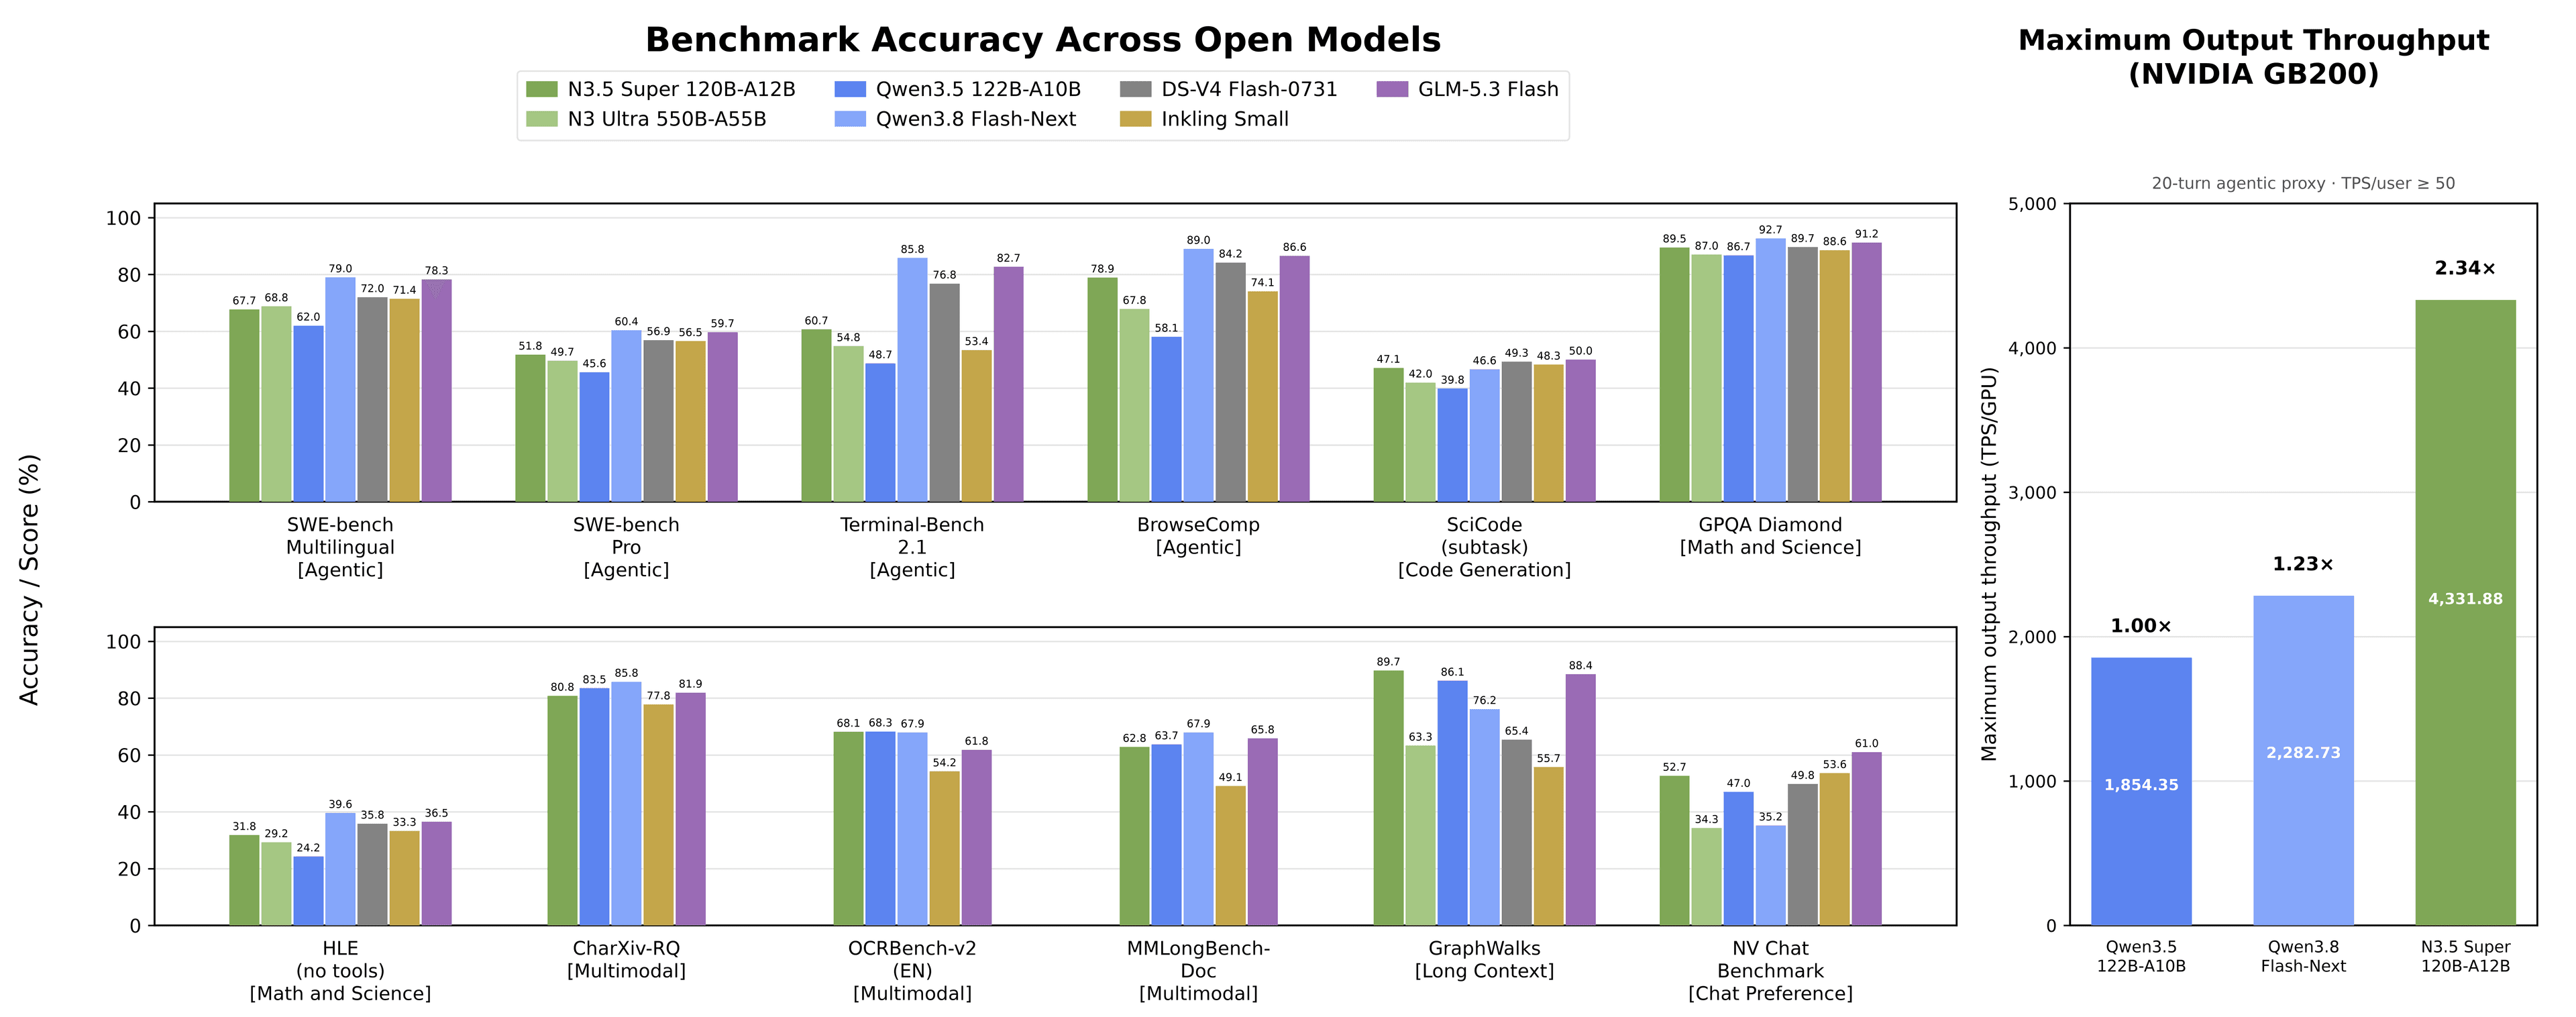
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
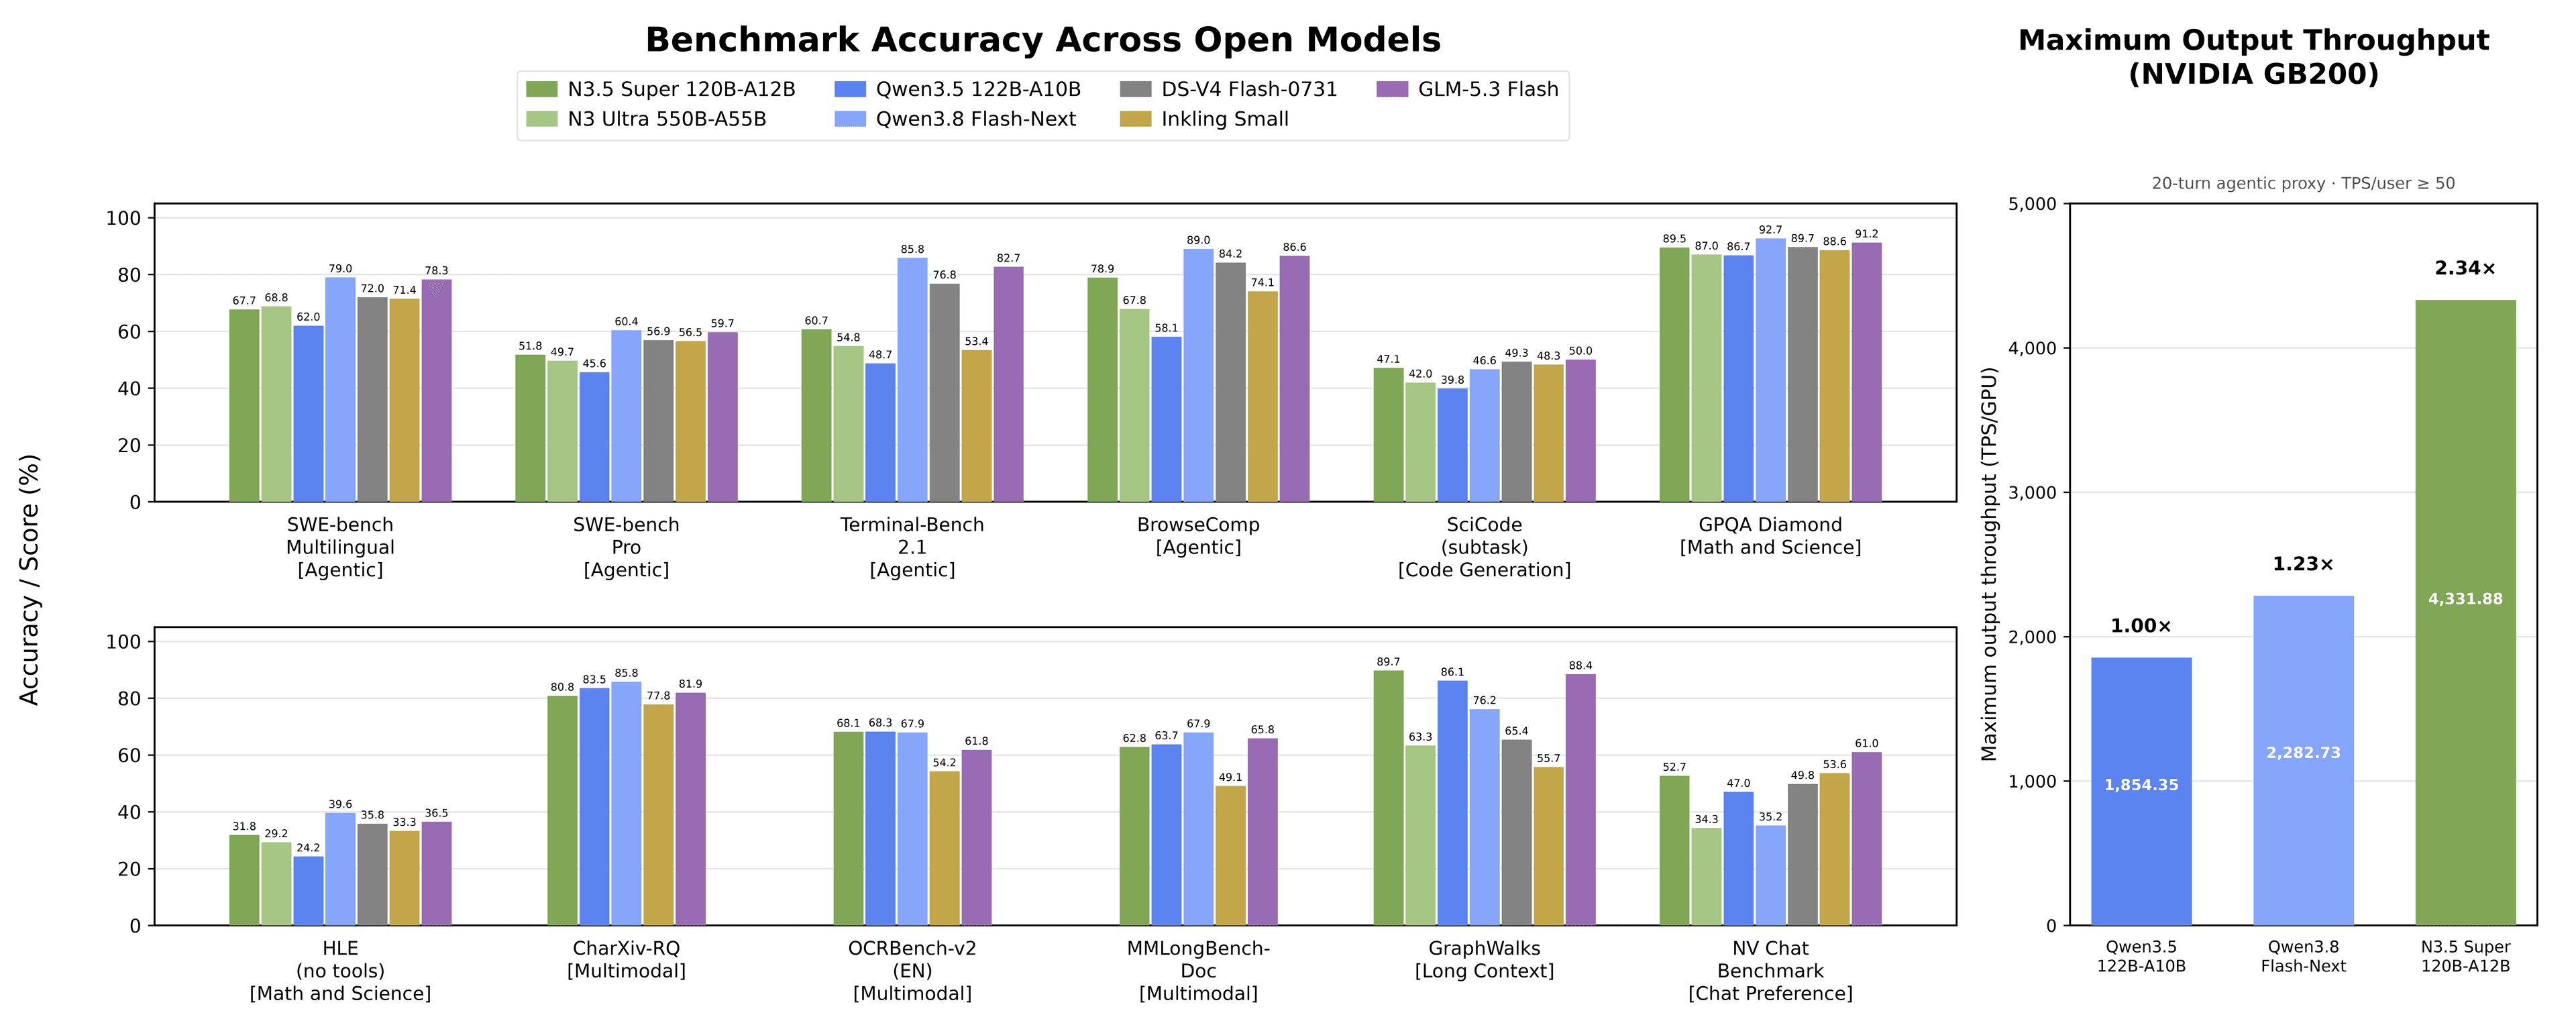
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Embeddings
All Embeddings →
EmbeddingGemma 2 Expands to Any Modality
Google DeepMind's compact embedding model now spans text, vision, audio, and video in a single vector space.
NeoMME: a single-tower multilingual multimodal encoder
A new open encoder aims to make document retrieval faster by treating text and images natively in one model.
H Company's NeoMME rethinks visual document retrieval
A single-tower multimodal encoder aims to make multilingual document search cheaper to fine-tune and run.
0 comments
No comments yet. Be the first to weigh in.