NVIDIA's Nemotron TwoTower is a MoE experiment
An experimental 30B mixture-of-experts base model blends diffusion and Mamba ideas under a two-tower design.
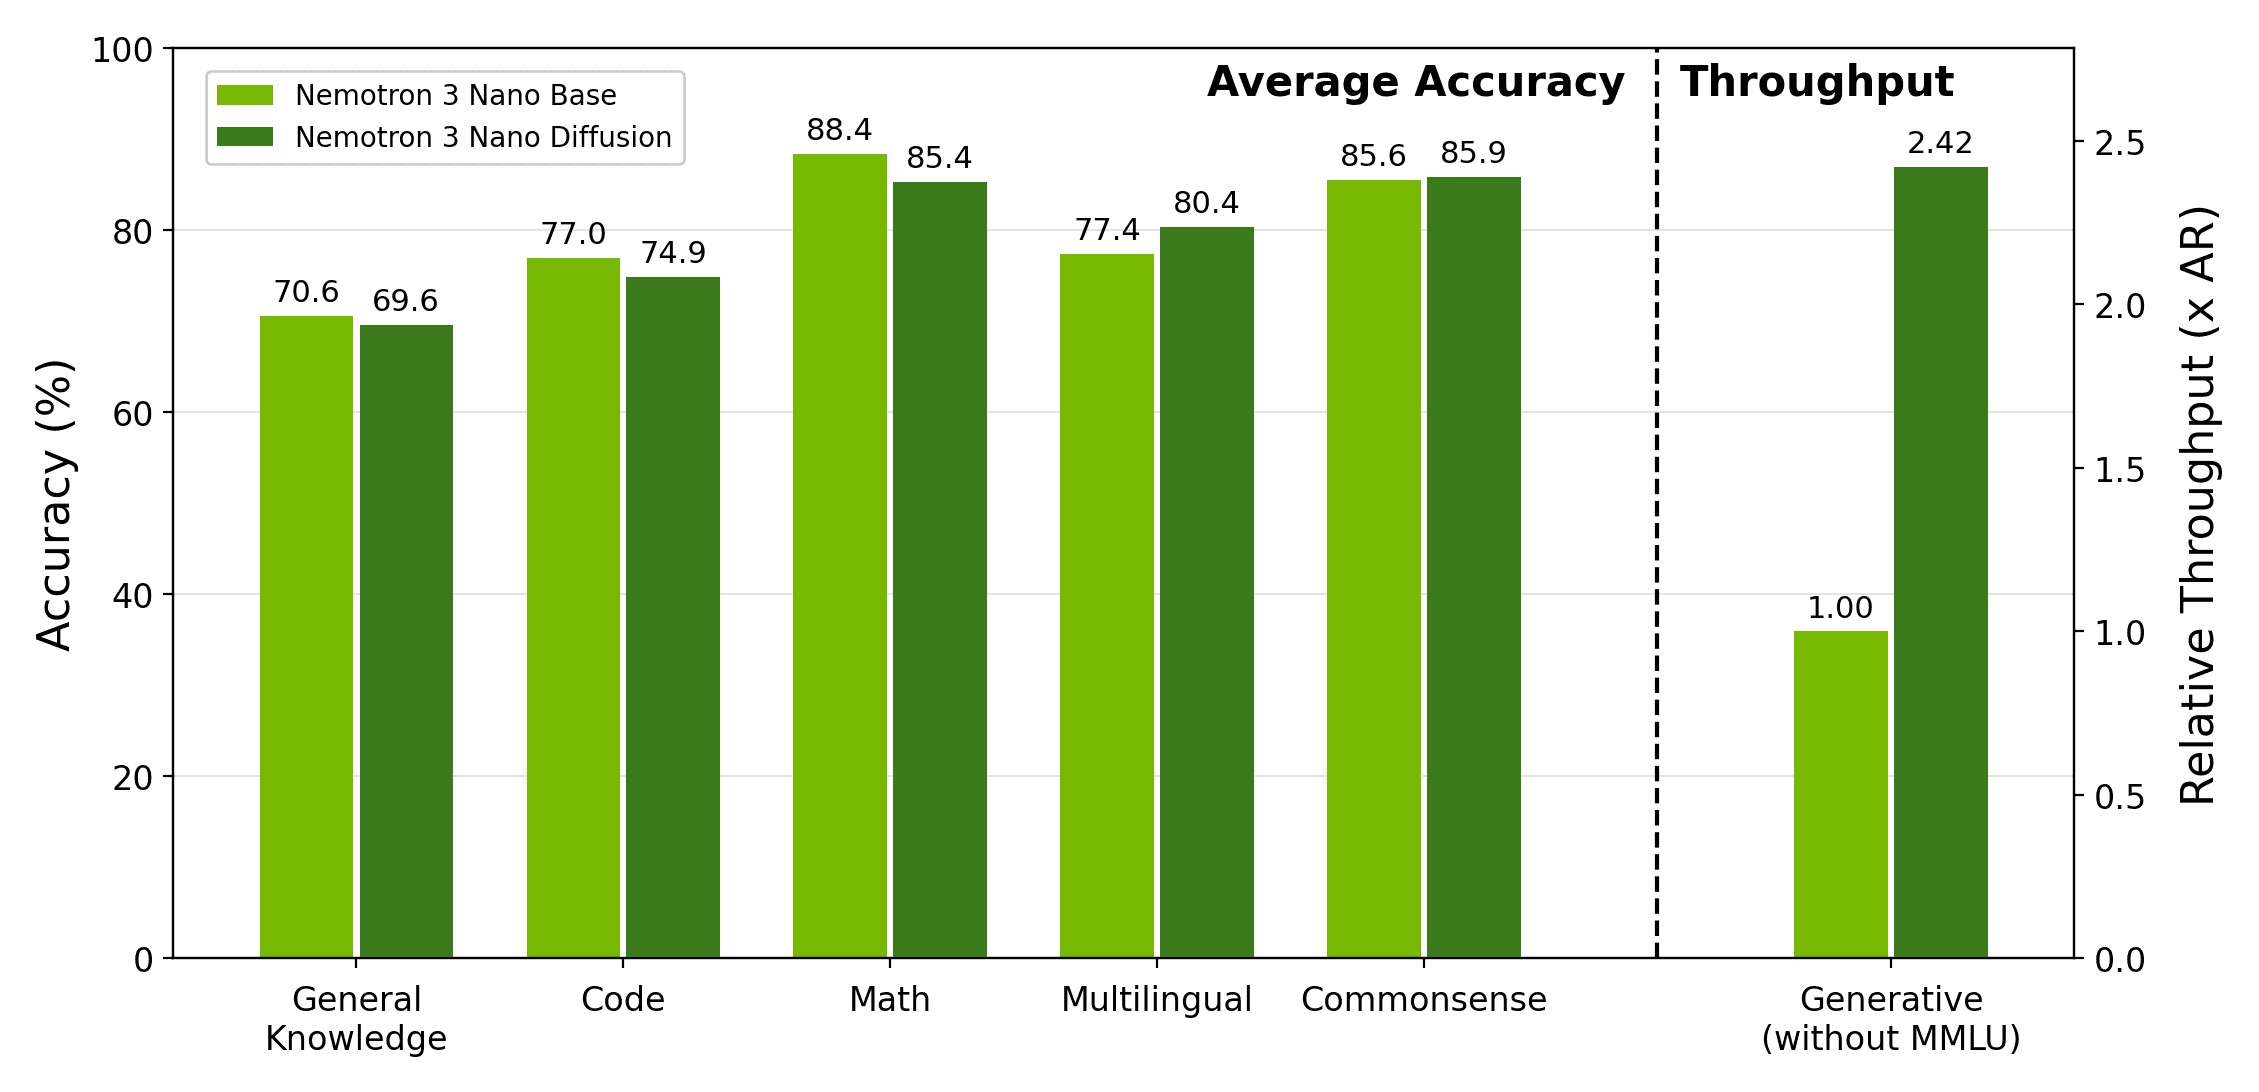
NVIDIA has quietly published Nemotron TwoTower 30B-A3B Base, an experimental language model that departs from the standard transformer recipe. Released on Hugging Face in BF16, it is a base model — meaning it ships without instruction tuning or alignment, intended as a foundation for further research and fine-tuning.
The architecture is where things get interesting. The model is described as a two-tower design that draws on diffusion and Mamba-style approaches, wrapped in a mixture-of-experts (MoE) layout. With 30 billion total parameters but only about 3 billion active per token, it aims for the efficiency profile that has made sparse MoE models attractive: large capacity at a fraction of the inference cost.
Why it matters
Most frontier open-weight models still lean on dense or MoE transformers. NVIDIA's willingness to publish a hybrid that mixes diffusion and state-space (Mamba) components signals continued exploration of alternatives to attention-heavy designs, particularly for long-context and throughput-sensitive workloads.
- 30B total parameters, roughly 3B active per token
- Mixture-of-experts with a two-tower structure
- Base checkpoint in BF16, no instruction tuning
- Released under a custom NVIDIA license
As an experimental, notable-tier release, this is aimed squarely at researchers rather than production users. The unusual architecture makes it a useful testbed for anyone probing how diffusion and Mamba ideas hold up at scale — but expect rough edges, and check the license terms before building on it.
Sources
- Visit
nvidia/Nemotron-Labs-TwoTower-30B-A3B-Base-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
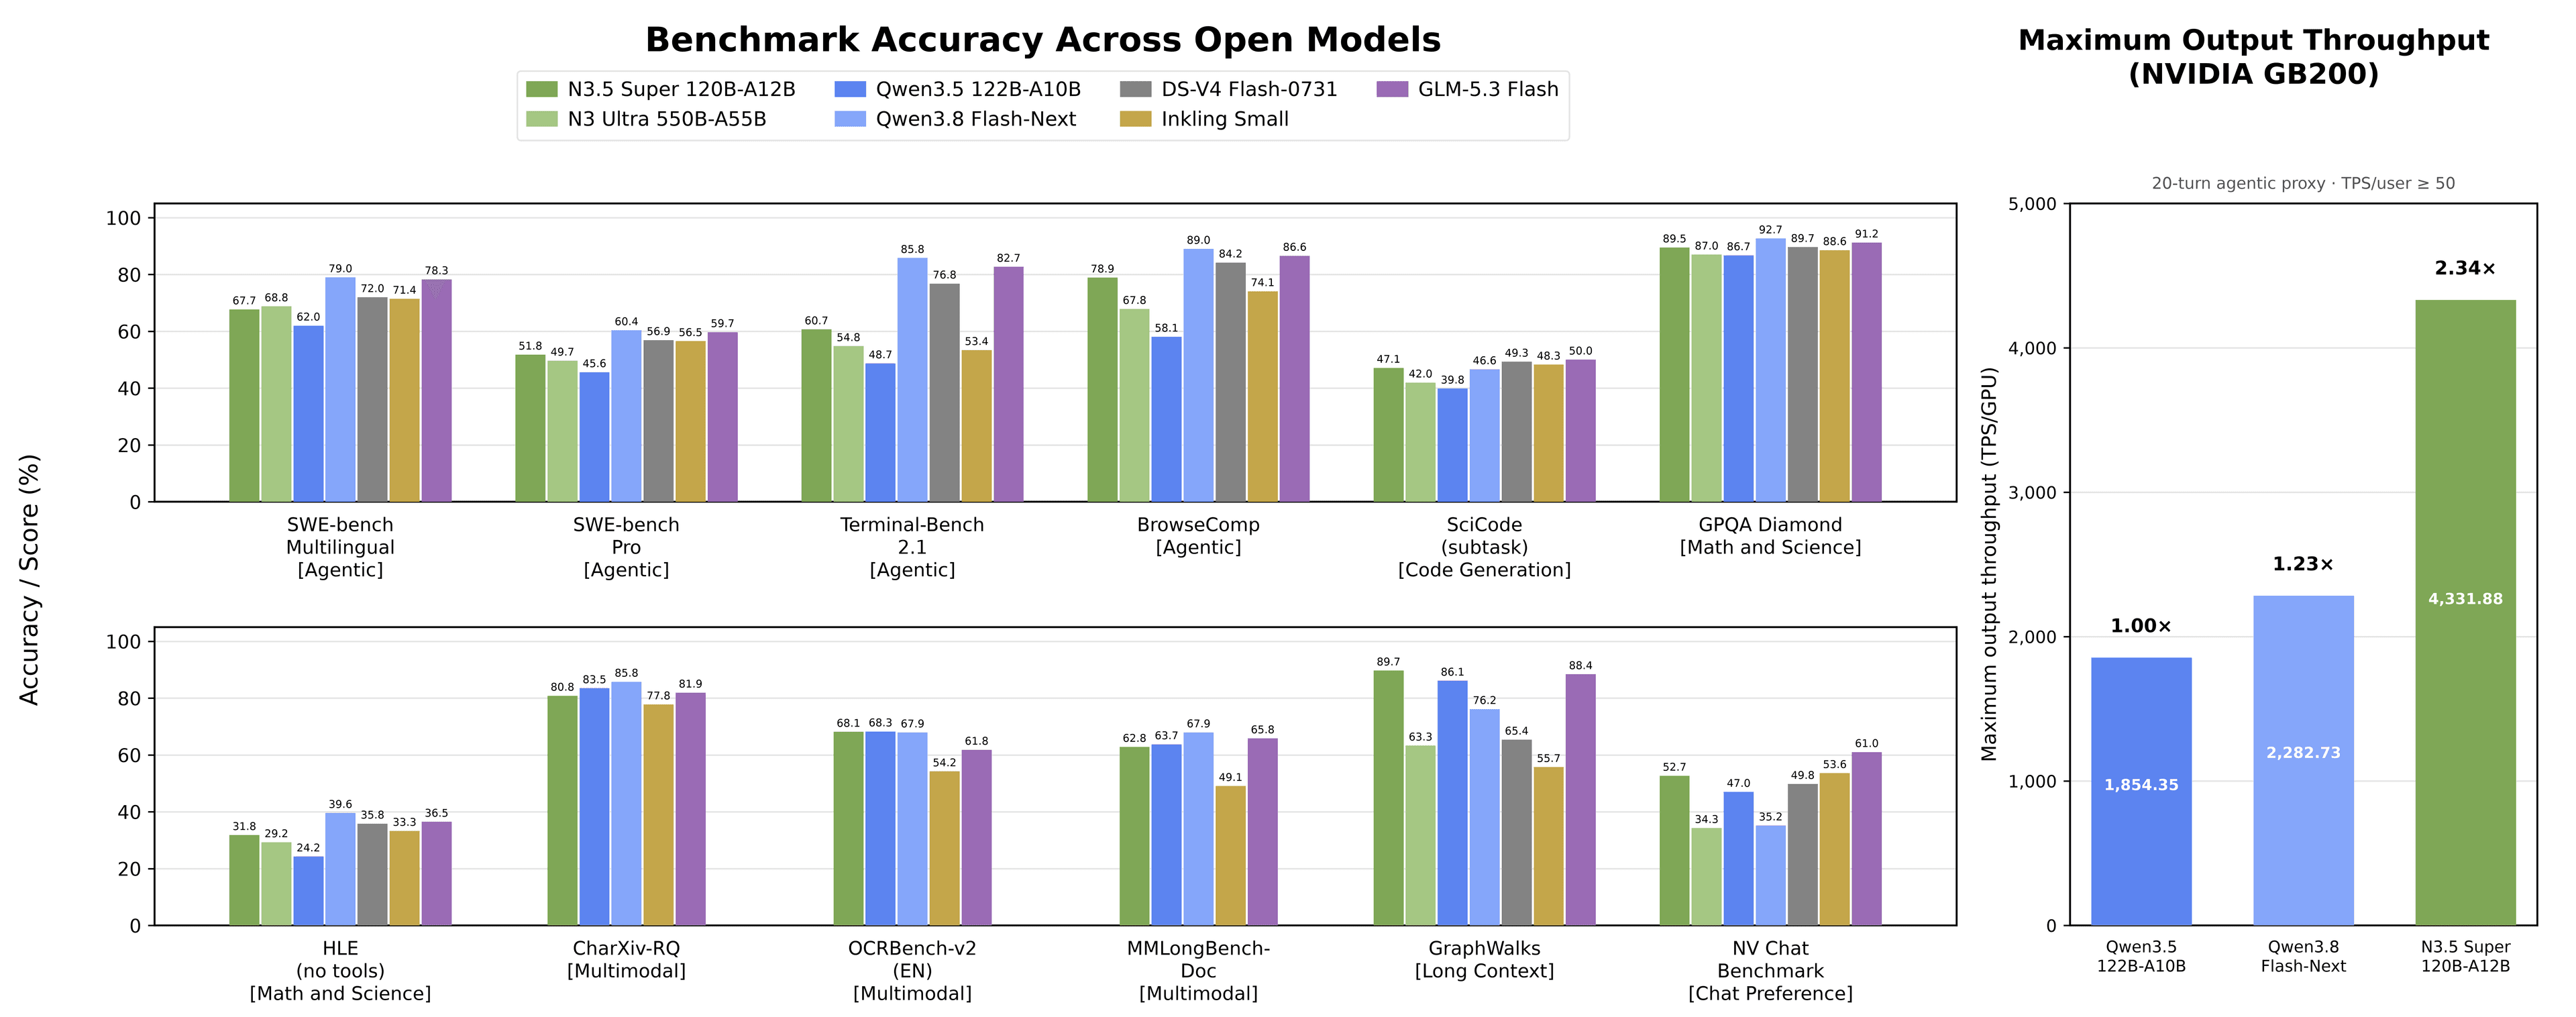
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
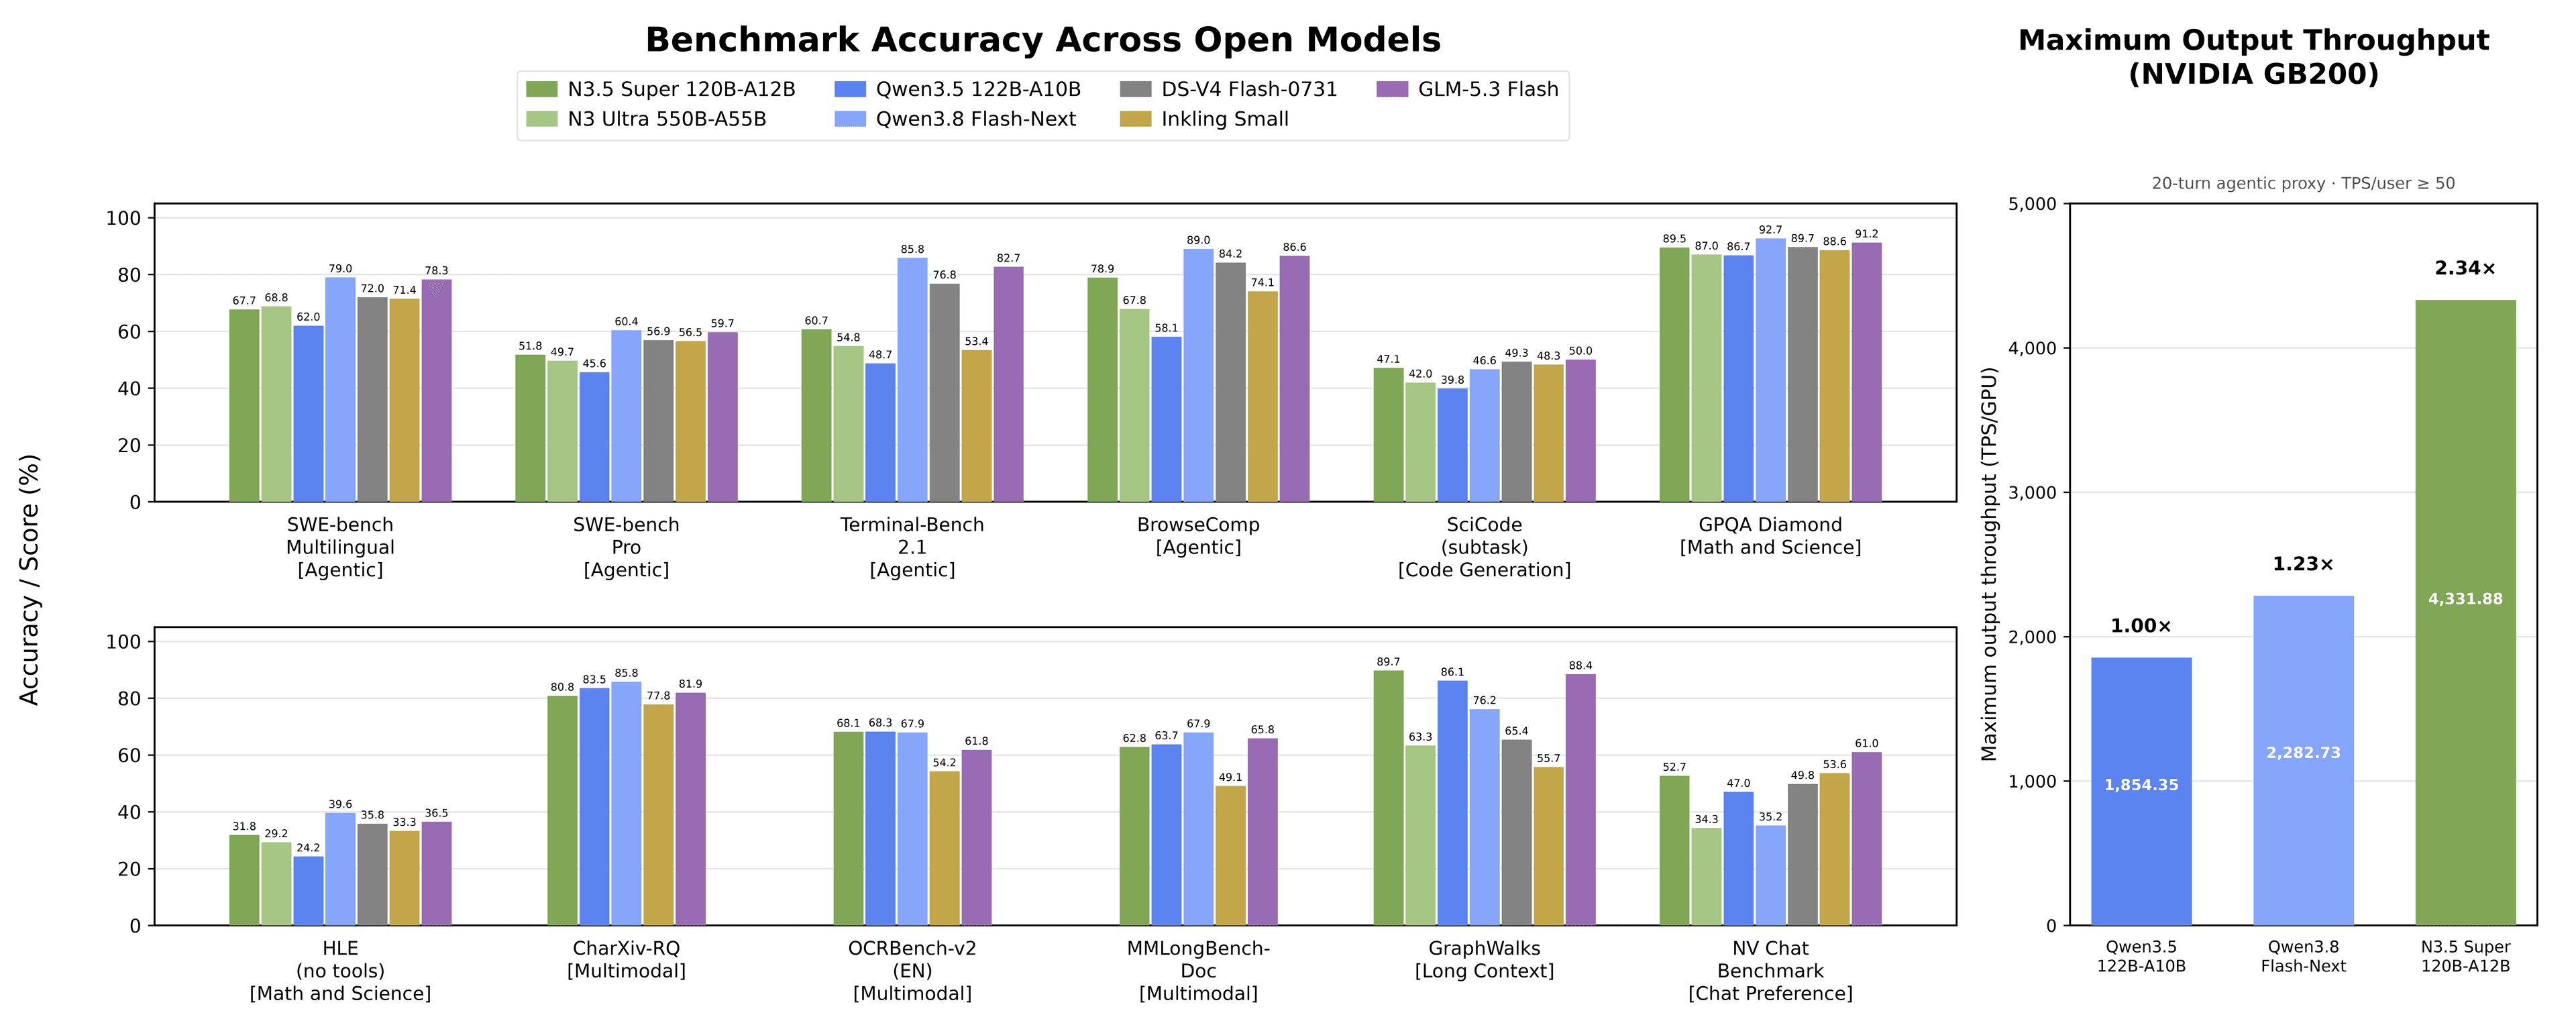
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.