Tencent releases Hunyuan Hy3 under Apache 2.0
The company's latest mixture-of-experts model arrives as an openly licensed conversational LLM on Hugging Face.
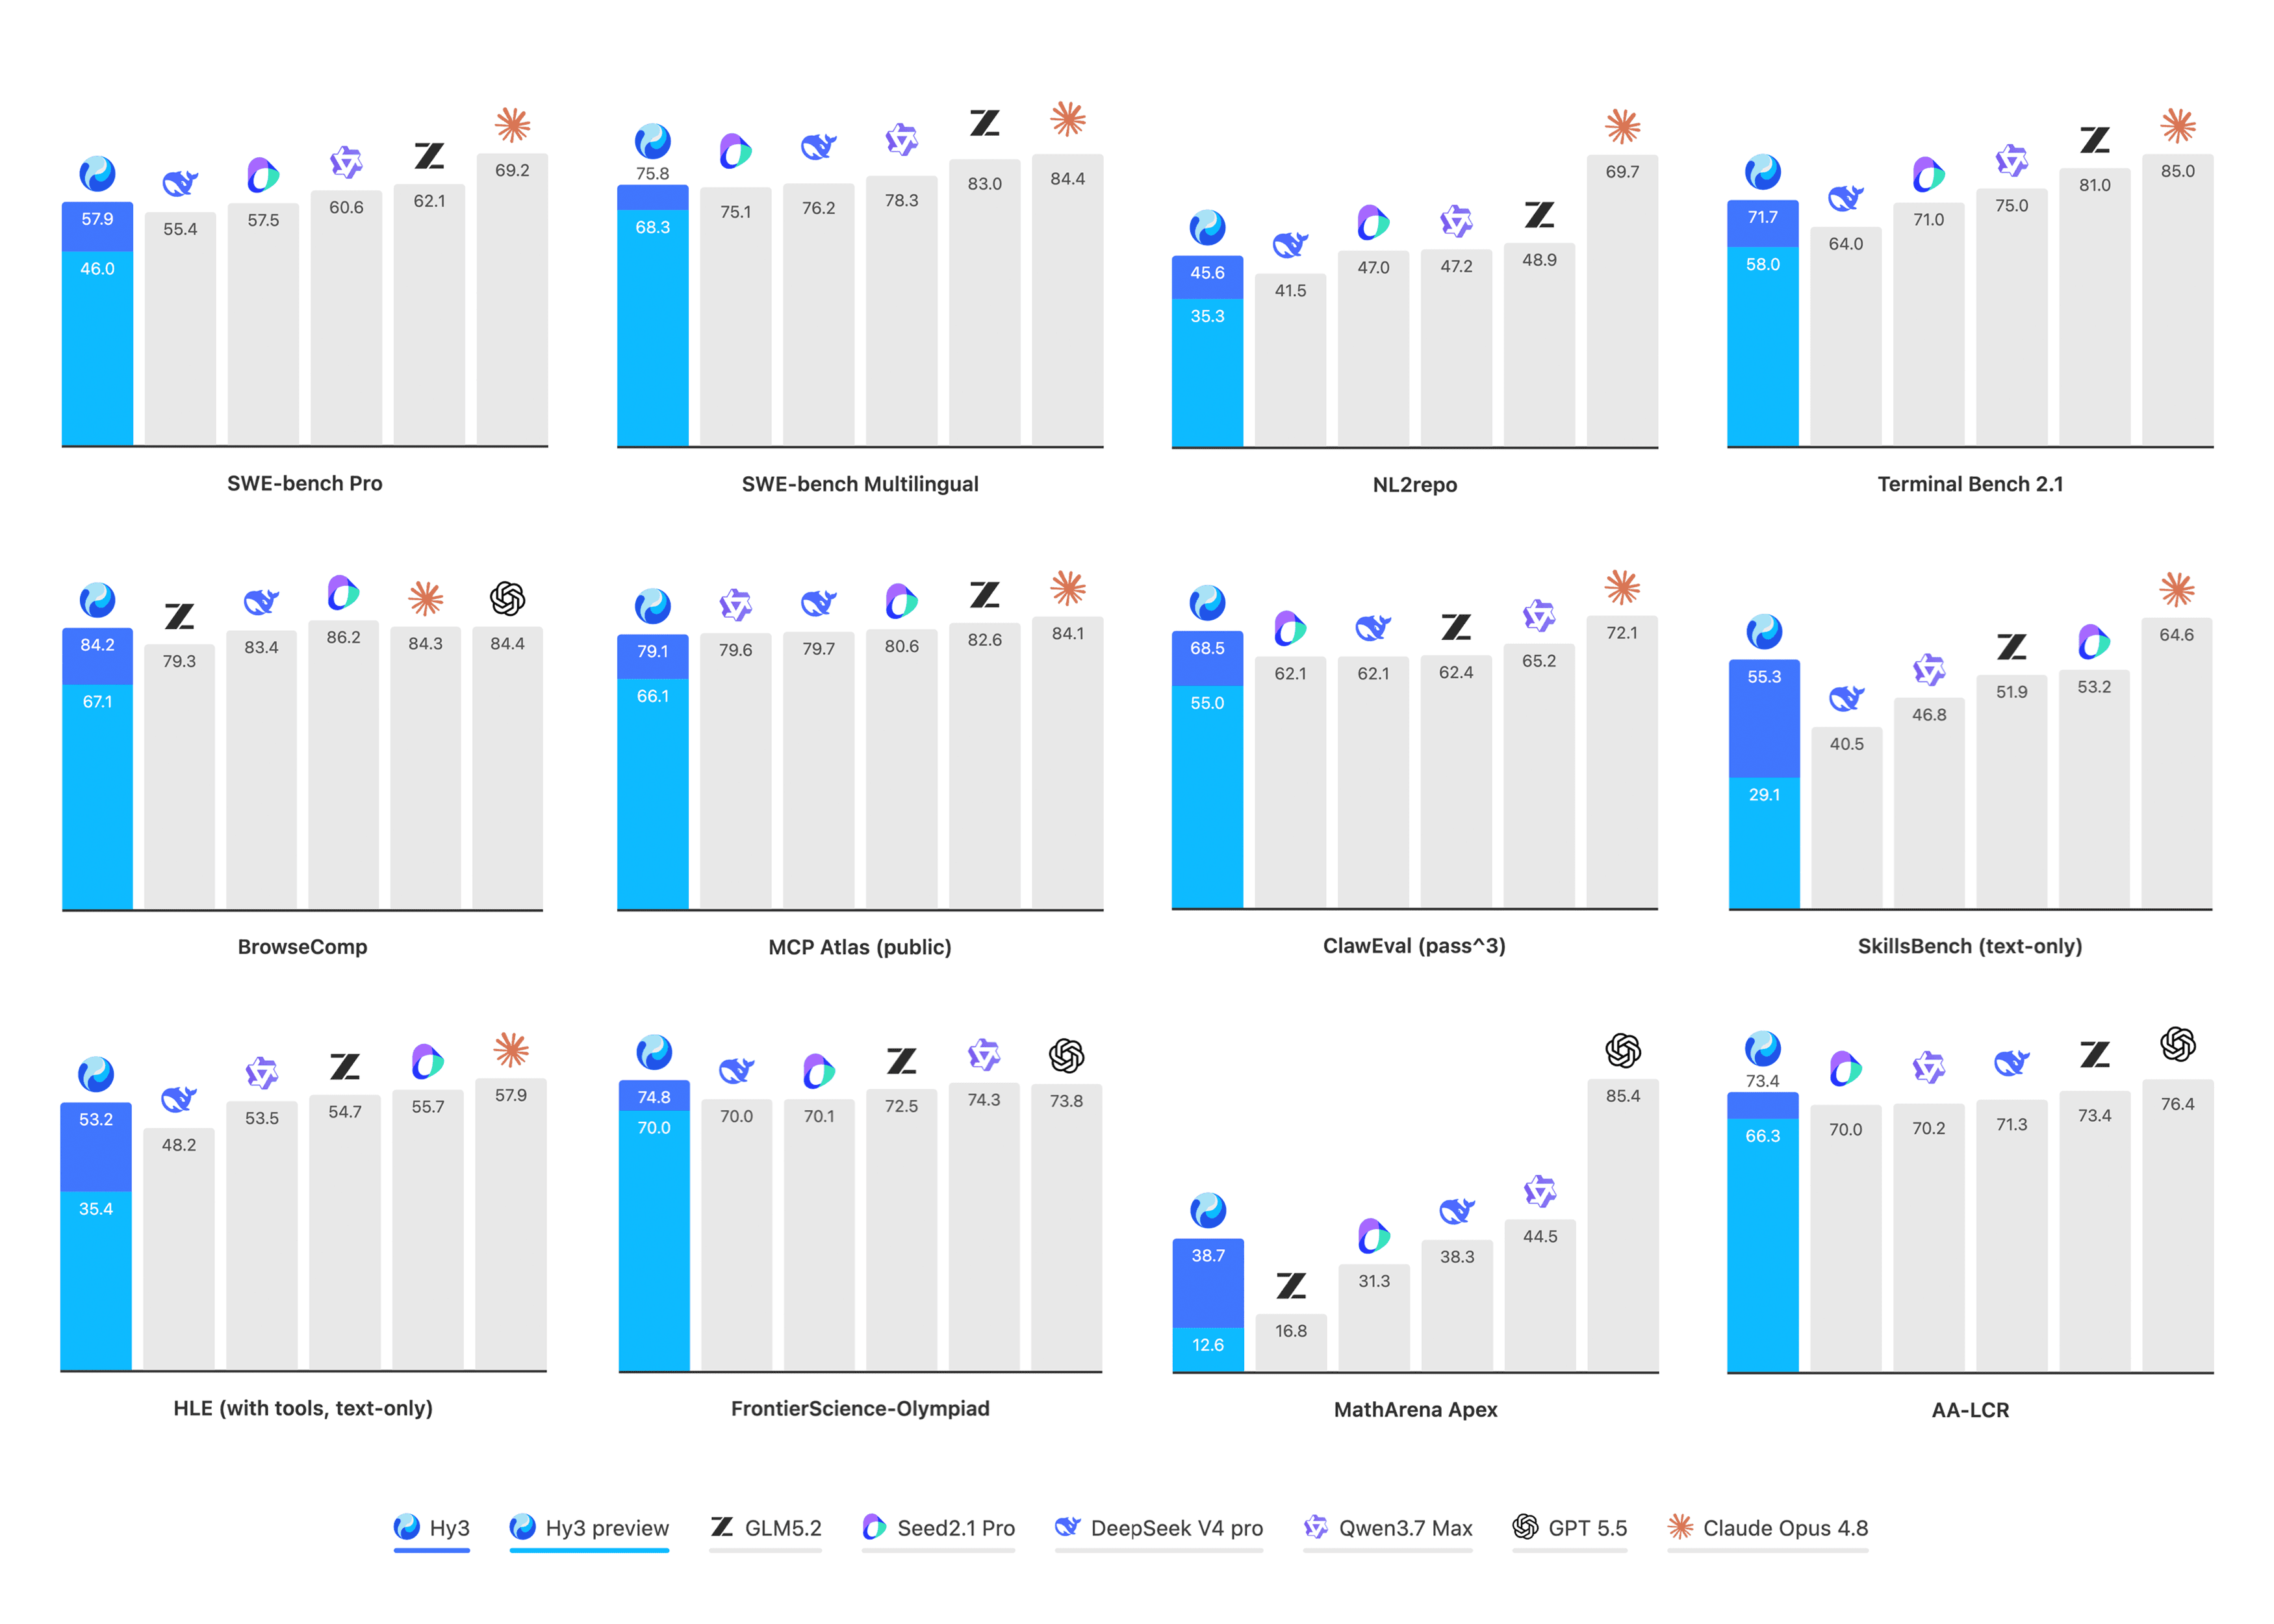
Tencent has published Hunyuan Hy3, a new conversational large language model built on a mixture-of-experts (MoE) architecture, to Hugging Face. The model ships under the Apache-2.0 license, one of the most permissive terms available for commercial and research use.
The MoE design is the notable structural choice here. Rather than activating every parameter for each token, mixture-of-experts models route inputs through a subset of specialized "expert" networks. That approach lets a model carry a large total parameter count while keeping the compute cost of any single inference pass lower than a dense model of comparable size.
Why it matters
Tencent has steadily expanded its Hunyuan family across text, image, and video, and continued open releases give developers outside China a credible alternative to the usual Western and other Chinese open-weight labs. A few practical points stand out:
- Apache-2.0 licensing removes many of the usage restrictions attached to some competing open models.
- MoE architecture signals a focus on efficient scaling rather than brute-force dense parameter growth.
- Conversational focus positions Hy3 as a general-purpose assistant model rather than a narrow specialist.
Tencent has not yet detailed parameter counts, context length, or benchmark results in the initial listing, so a fuller assessment will depend on the model card and independent testing. For now, the release adds another permissively licensed MoE option to a crowded but fast-moving open-weights landscape.
Sources
- Visit
tencent/Hy3
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
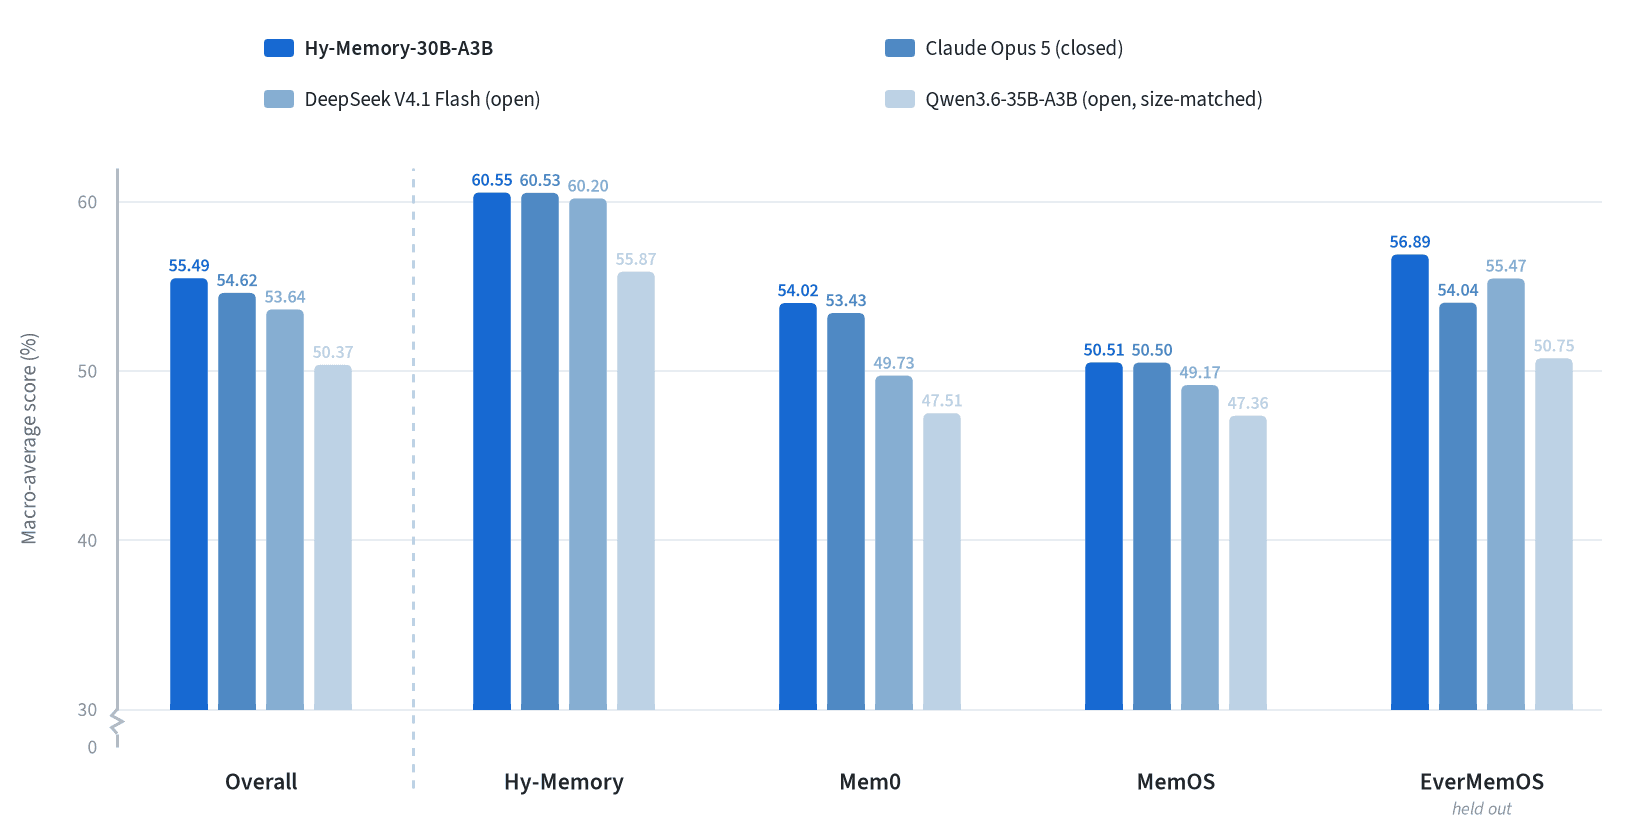
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
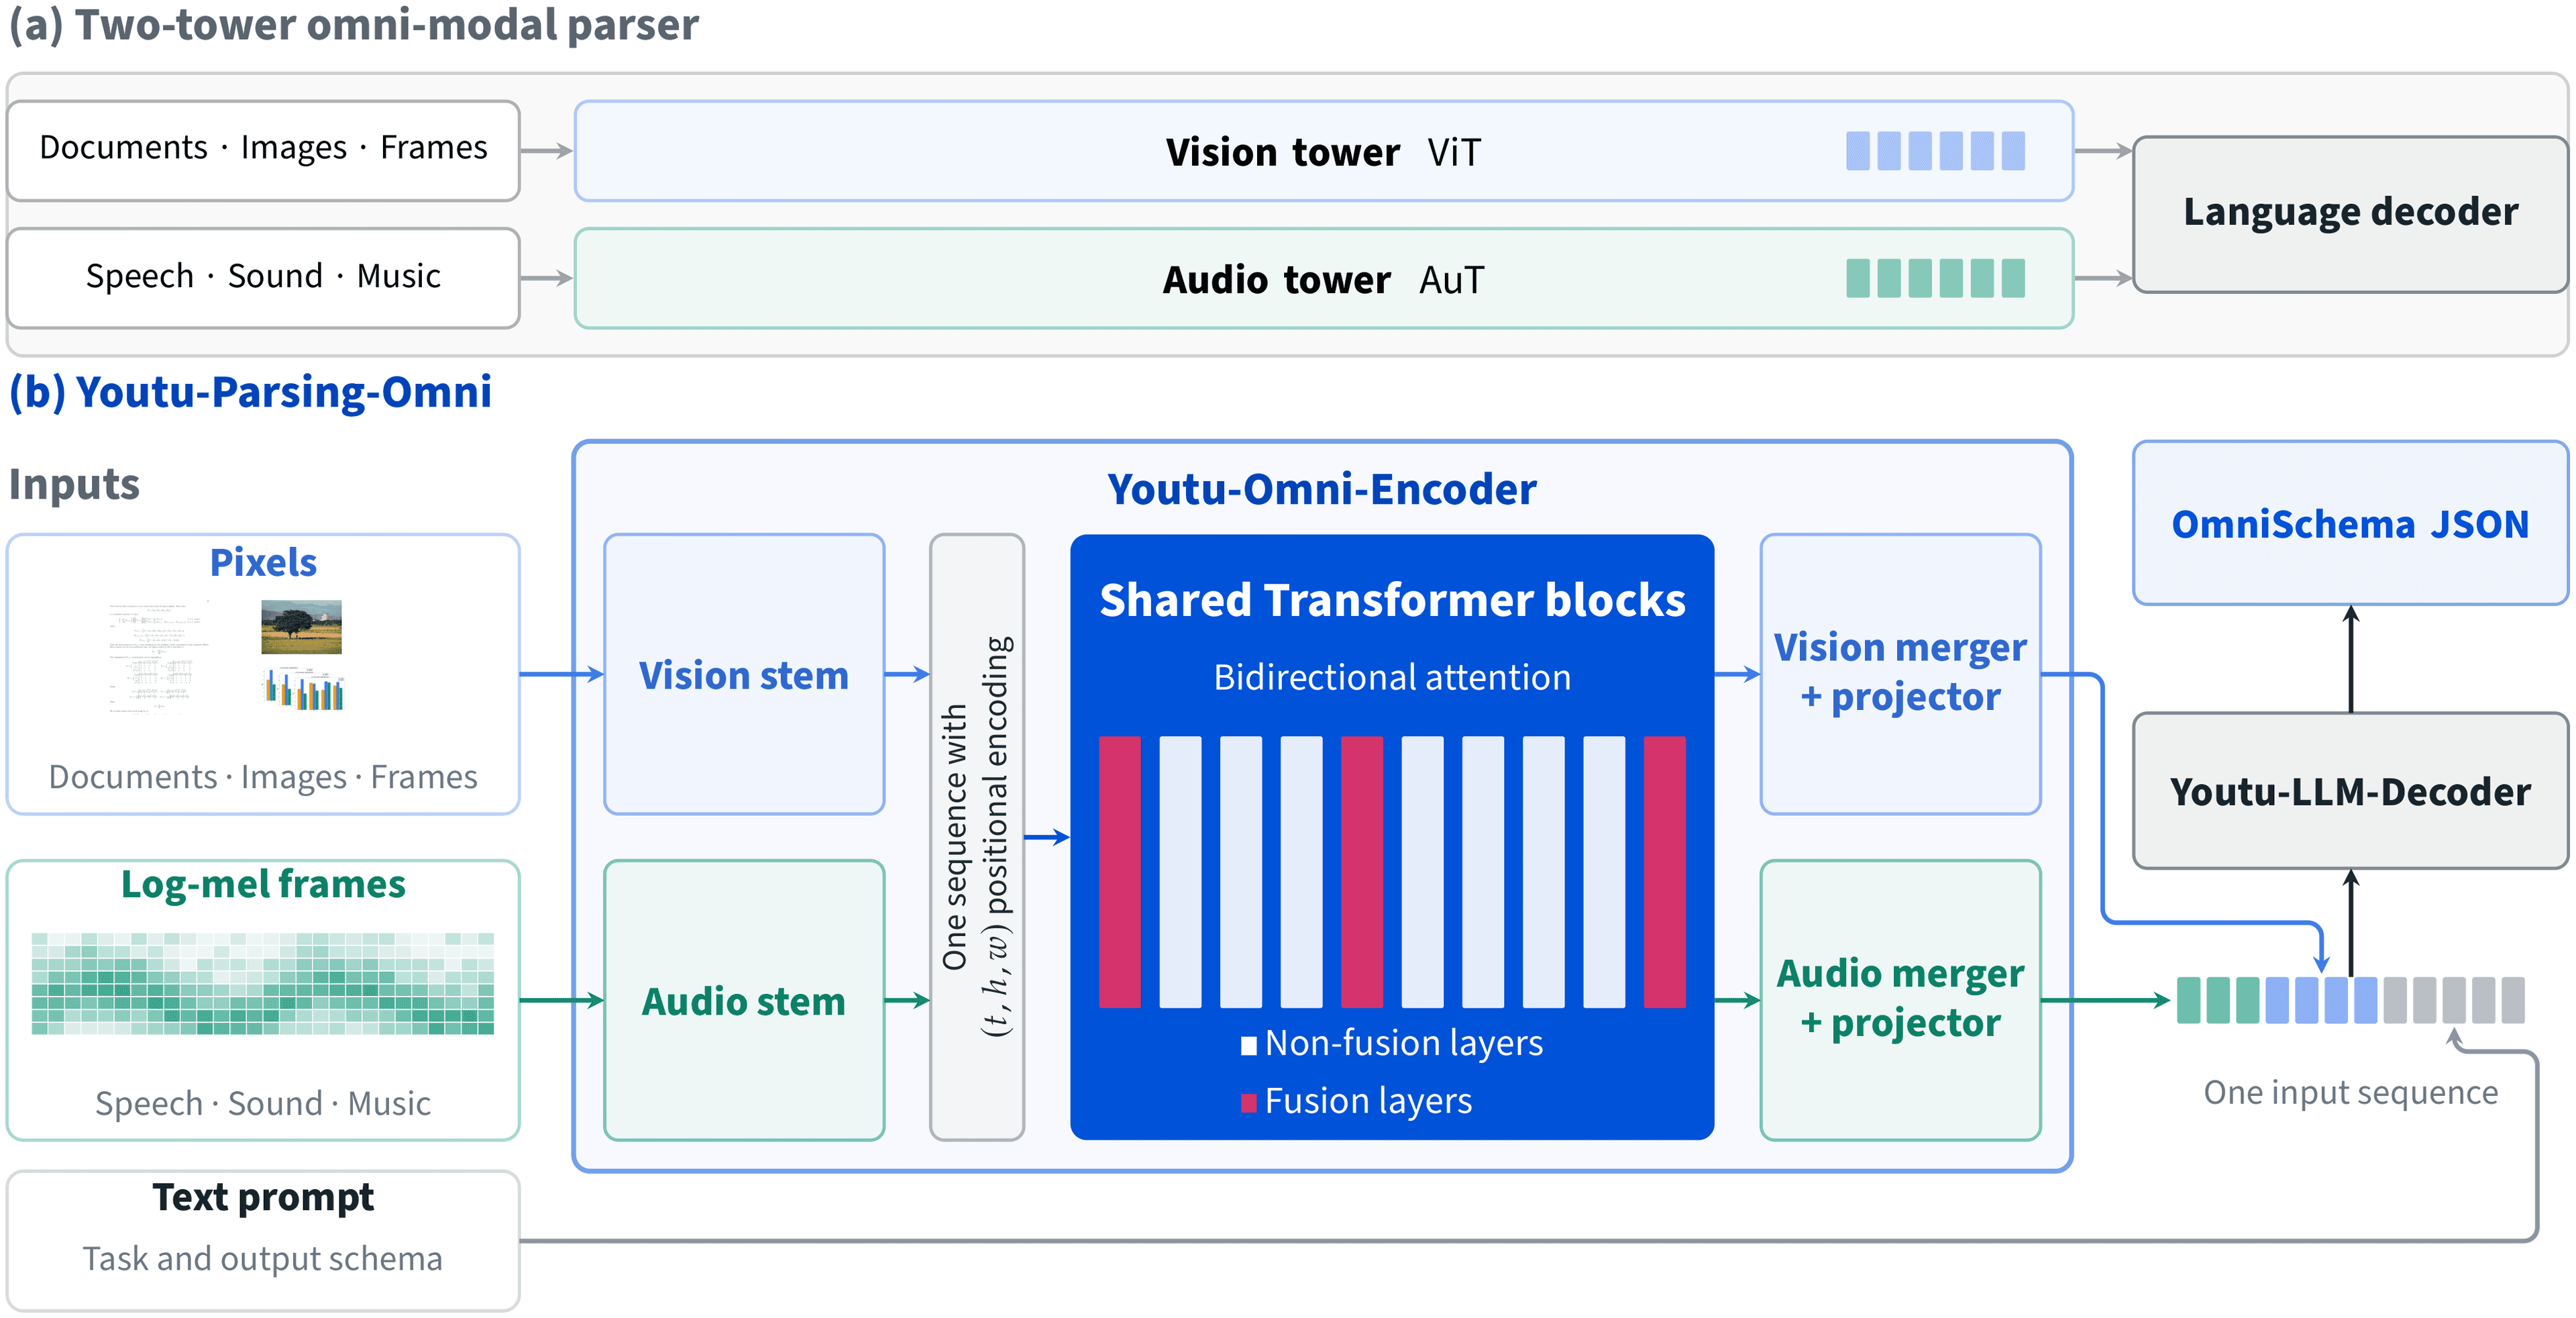
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.