Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
Kandinsky Lab has introduced Kandinsky 6.0 Video, a family of foundation models built to generate video and audio in one pass rather than stitching a soundtrack onto silent footage after the fact. The project is detailed in a paper hosted on Hugging Face.
The release comes in two sizes: a lightweight 3B variant positioned for accessibility and a larger 29B Pro model aimed at higher-quality output. Both target short-form generation, with clips running up to roughly five seconds and audio produced at a 44kHz sample rate.
Why it matters
Most open text-to-video systems treat sound as a separate problem, which makes lip movement, footsteps, and ambient effects hard to line up with on-screen action. By modeling the two modalities jointly, Kandinsky 6.0 aims for native synchronization — a capability that has largely been the domain of closed commercial systems.
A few things worth noting about the launch:
- Two model tiers (3B Lite and 29B Pro) let teams trade compute for fidelity.
- Synchronized audio-video generation is the core differentiator, not an add-on.
- Short clip lengths place it squarely in the current open-source video generation cohort.
The licensing is listed as custom rather than a standard permissive license, so teams planning production use should read the terms closely before building on it. For researchers, the paper and model family offer a concrete look at how joint audio-video modeling can be approached at open scale.
Sources
- Visit
Kandinsky 6.0 Video: Foundation Models for Synchronized Video and Audio Generation
HF Papers
More in Text → Video
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.
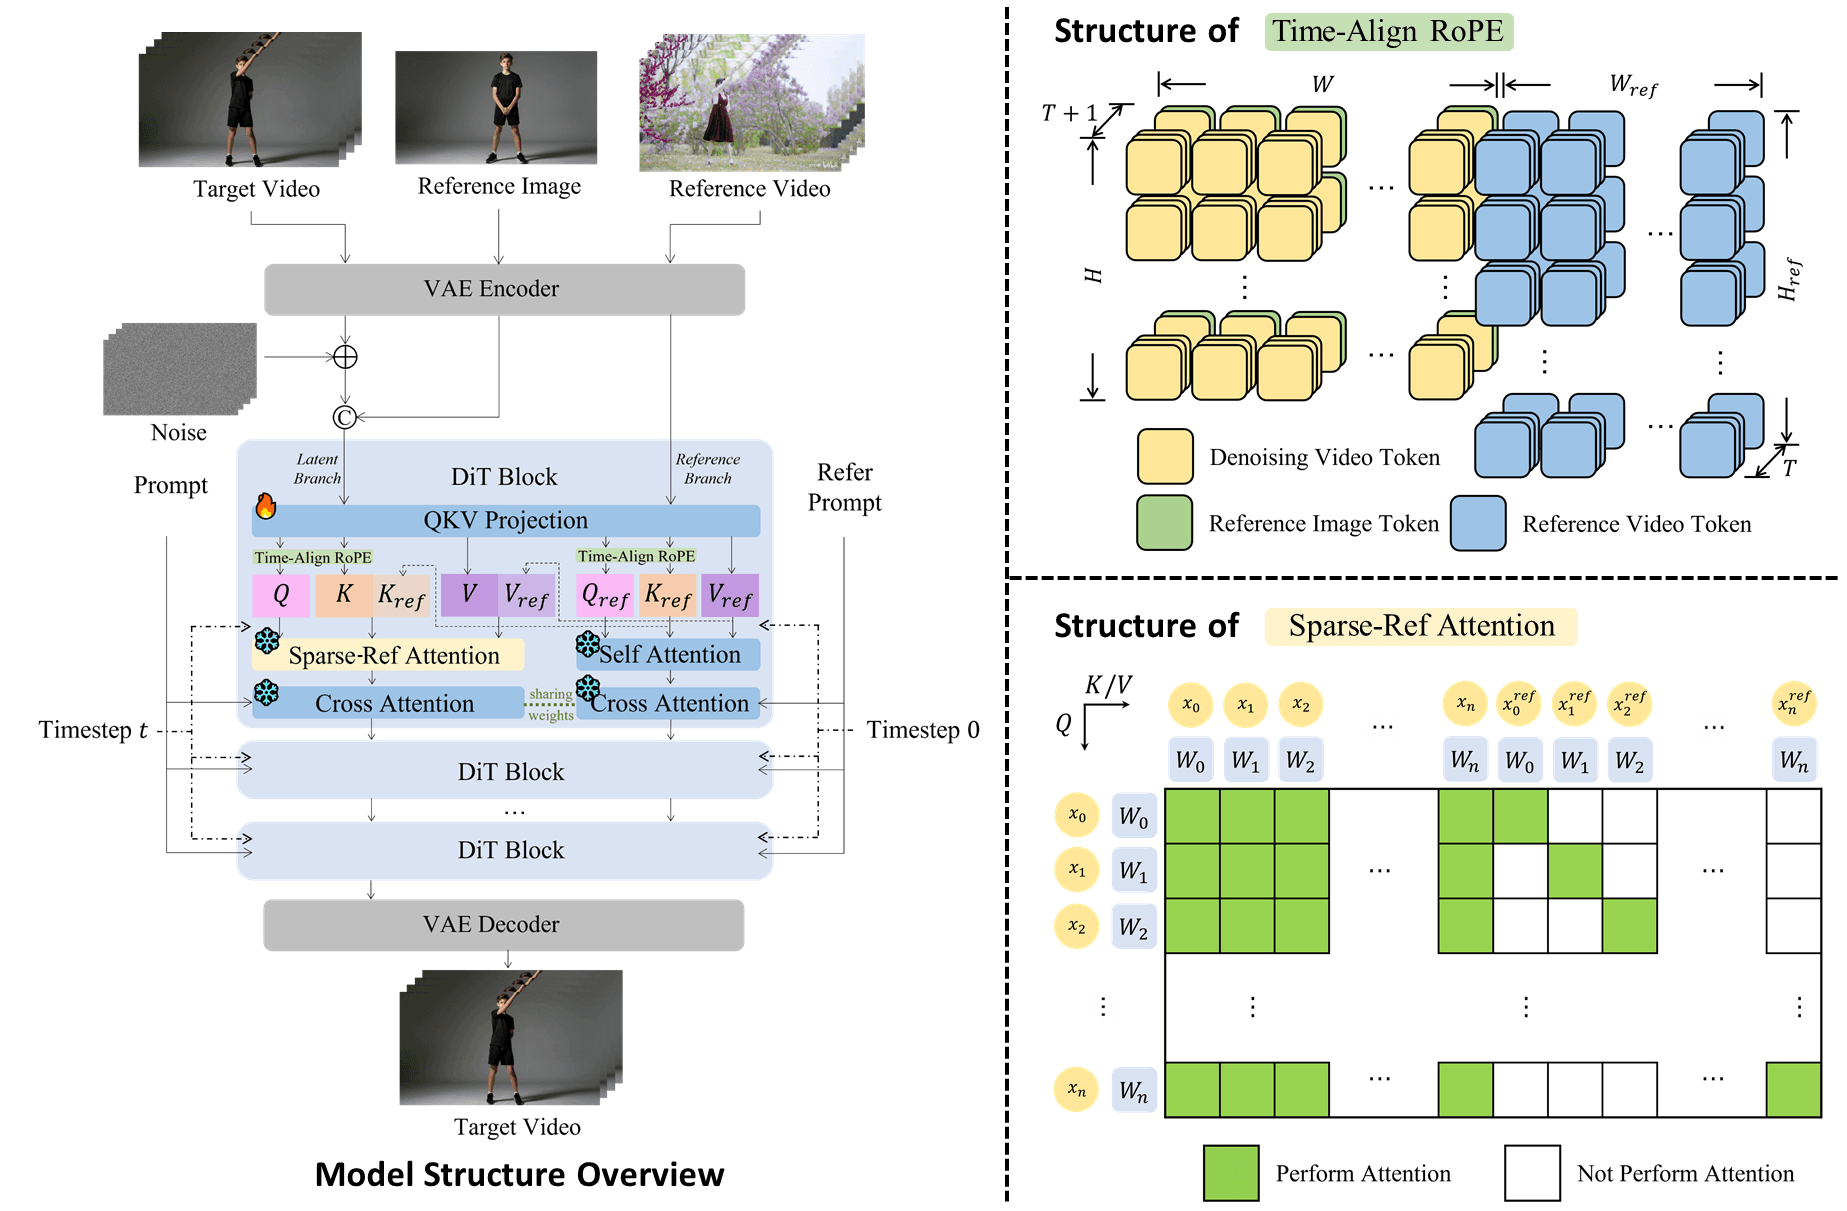
Alibaba's Wan2.2-Animate-2 14B lands under Apache 2.0
A permissively licensed 14B video model aimed at character animation joins the growing Wan family.
0 comments
No comments yet. Be the first to weigh in.