NVIDIA's Nemotron 3.5 Bolt Targets 4GB Devices
The compact 4-billion-parameter text model is tuned for multilingual work on memory-constrained hardware.
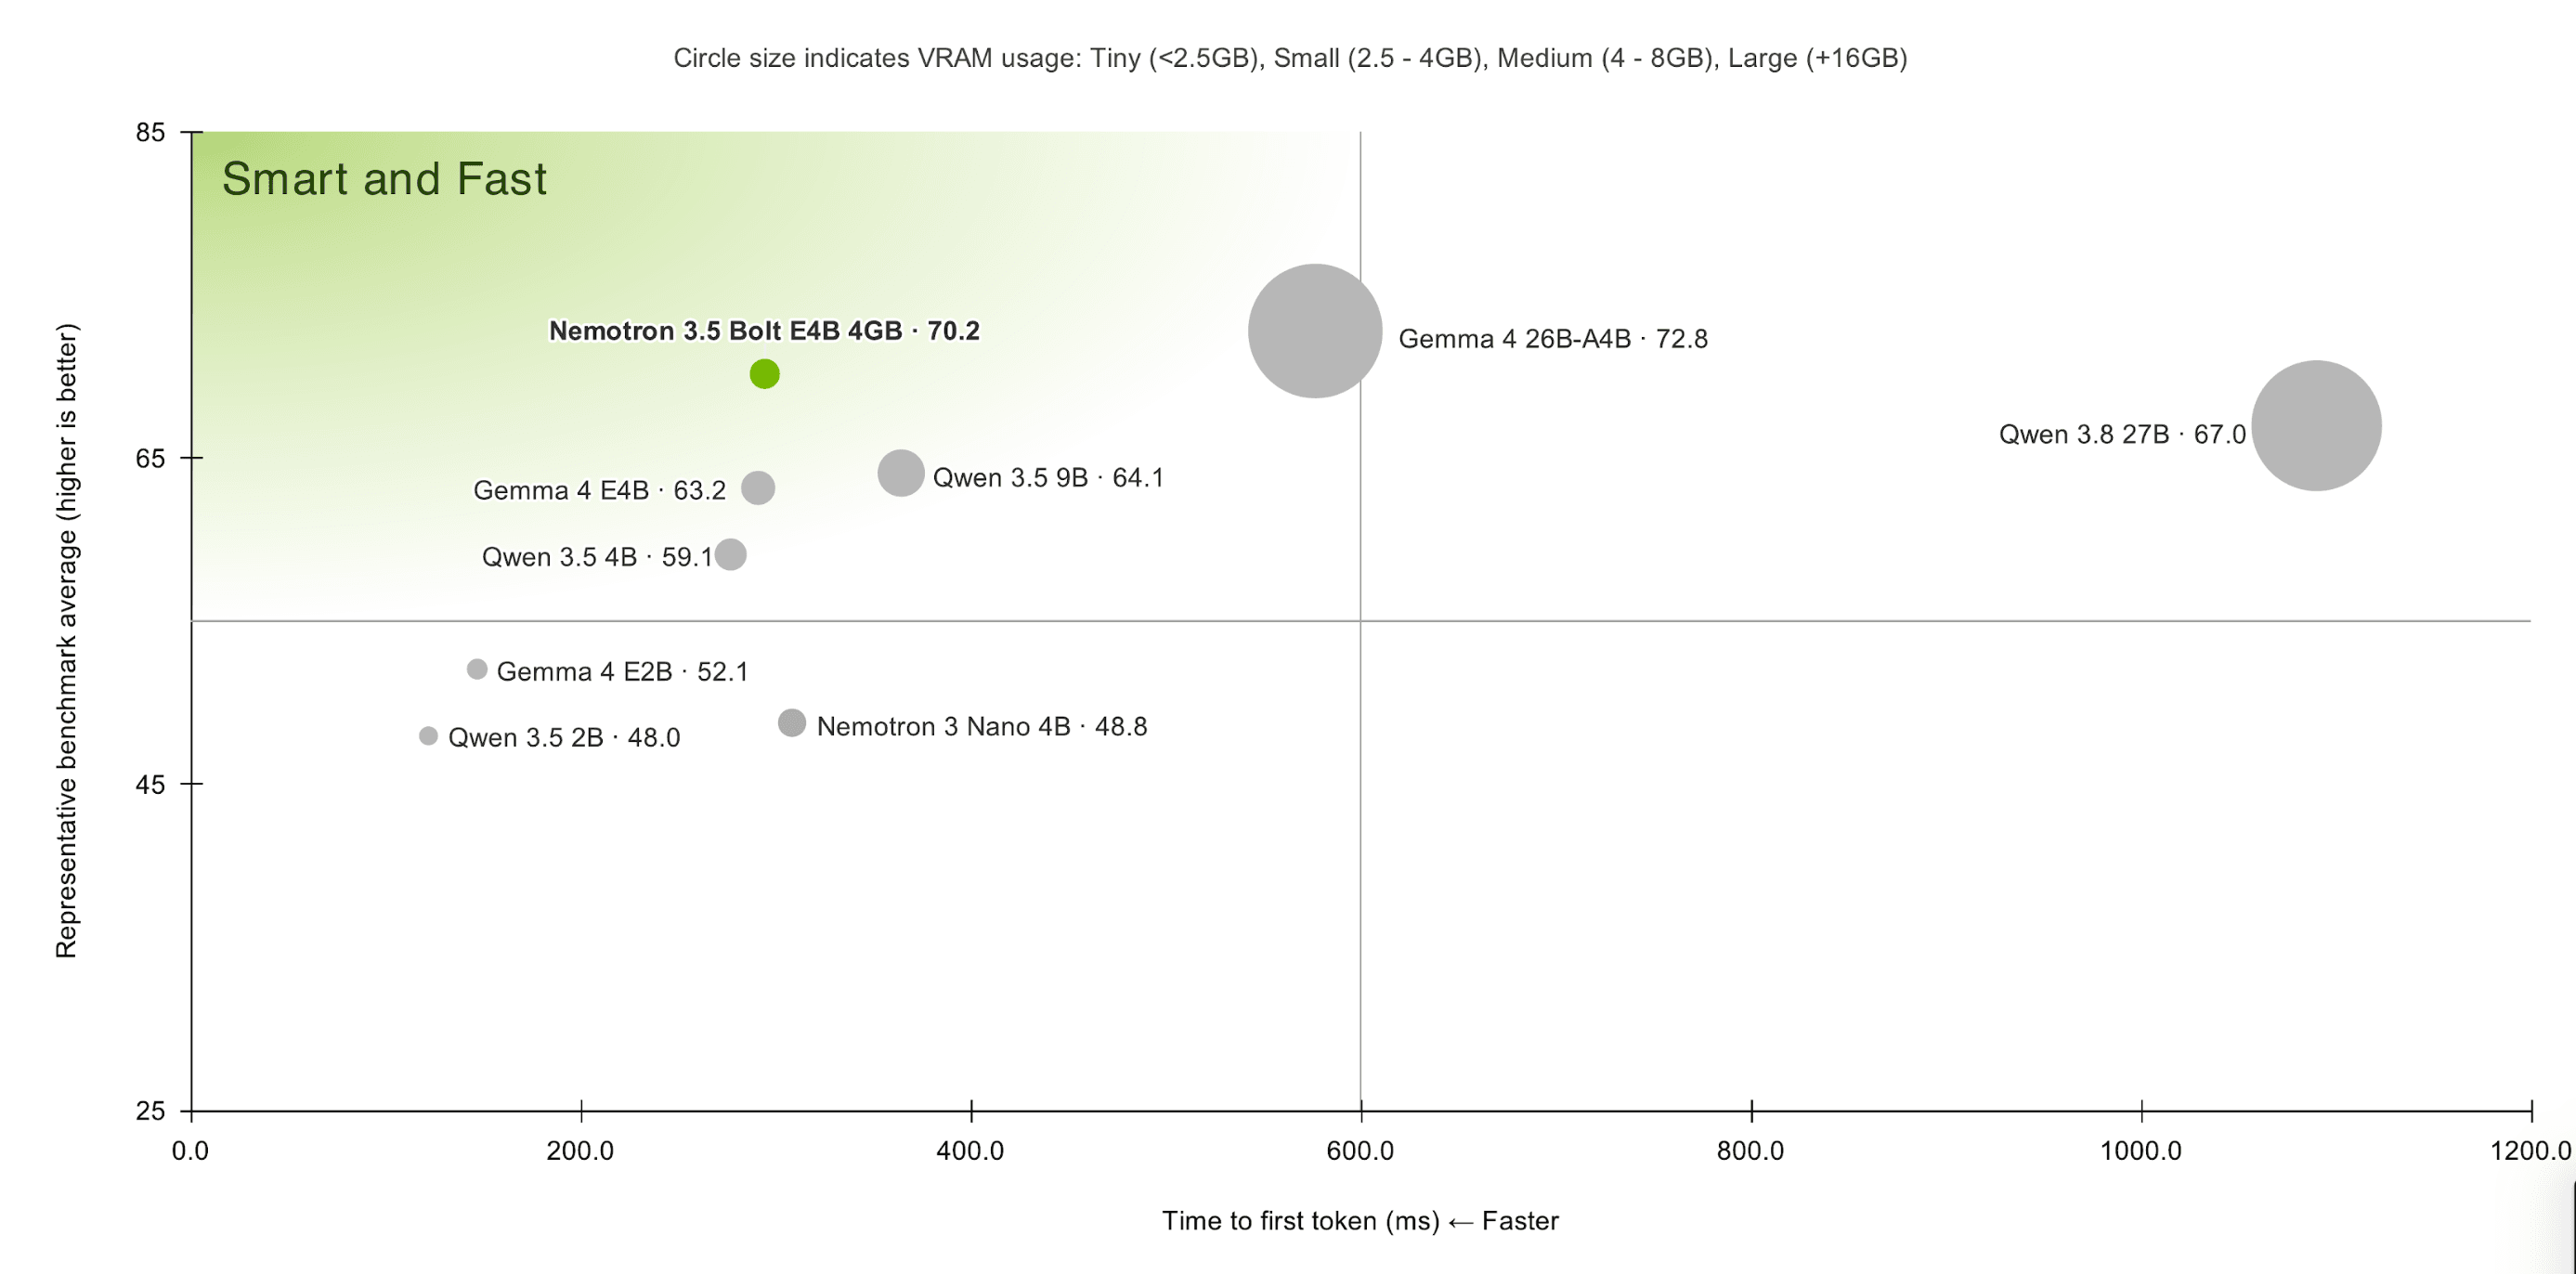
NVIDIA has published Nemotron 3.5 Bolt E4B on Hugging Face, a compact text model that trades raw scale for the ability to run where memory is tight. At roughly 4 billion parameters, it is a dense model aimed squarely at deployments that need to fit within a 4GB footprint, as the repository name suggests.
The model is positioned as a multilingual general-purpose language model, extending NVIDIA's Nemotron line downward into territory where edge devices, consumer GPUs, and cost-sensitive inference matter more than leaderboard-topping performance. The "Bolt" naming points to an emphasis on speed and efficiency rather than frontier capability.
Why it matters
Small models that stay useful across languages are increasingly where the practical action is. A 4B model that can run in constrained memory opens a few doors:
- On-device and offline assistants without a cloud round-trip
- Cheaper batch inference for high-volume text tasks
- Easier fine-tuning and experimentation on modest hardware
NVIDIA has steadily expanded the Nemotron family across sizes and modalities, and a sub-5B entry fills an obvious gap for developers who found larger variants impractical to serve. The model is released under a custom license, so teams should review the terms on the model card before building on it. Full specifications, including context length and benchmark results, were not detailed in the release record.
Sources
- Visit
nvidia/NVIDIA-Nemotron-3.5-Bolt-E4B-4GB
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
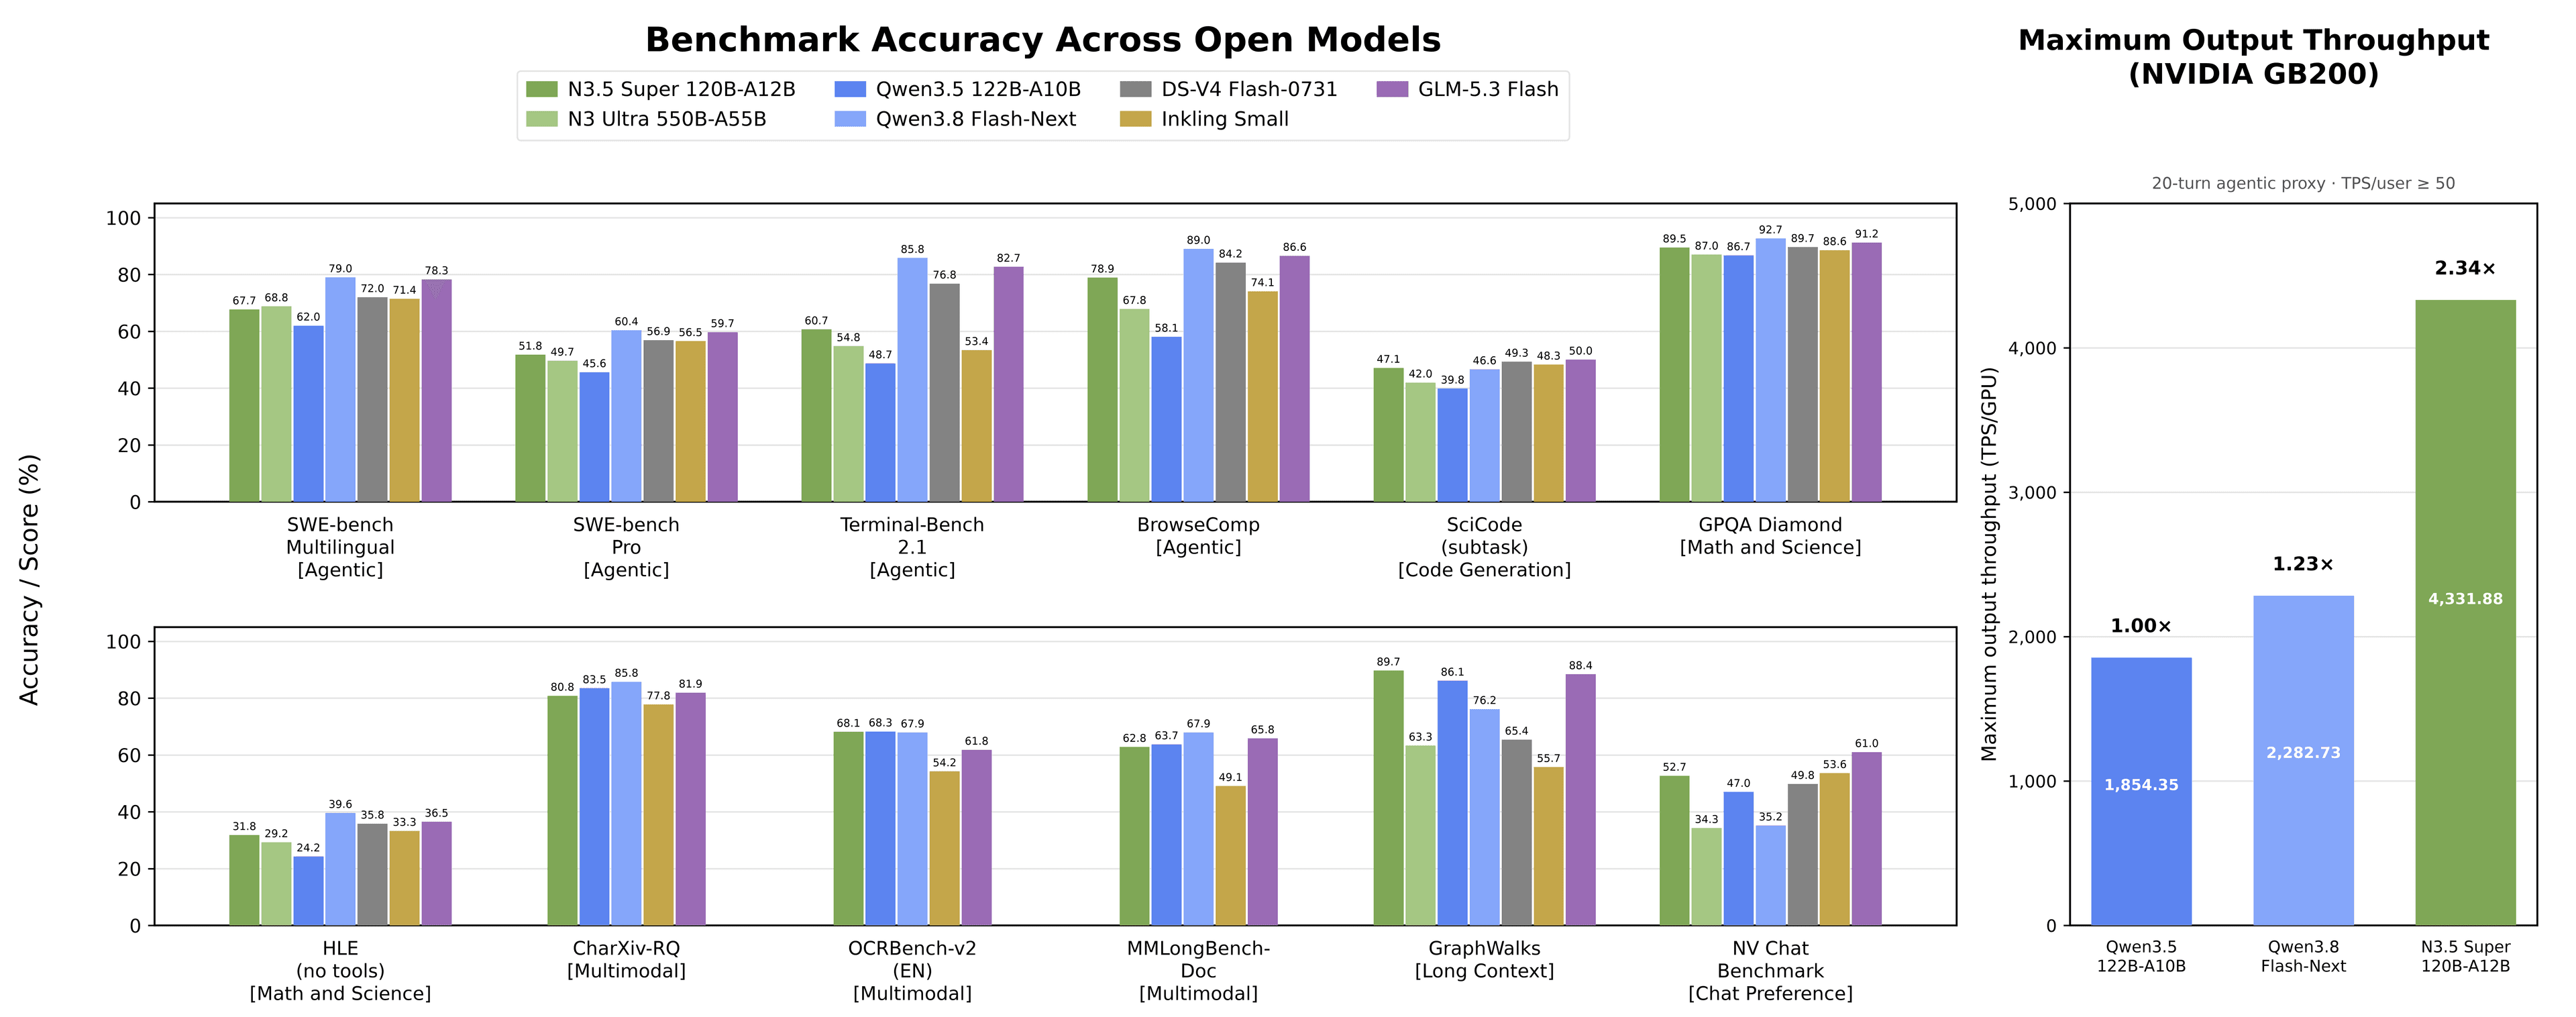
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
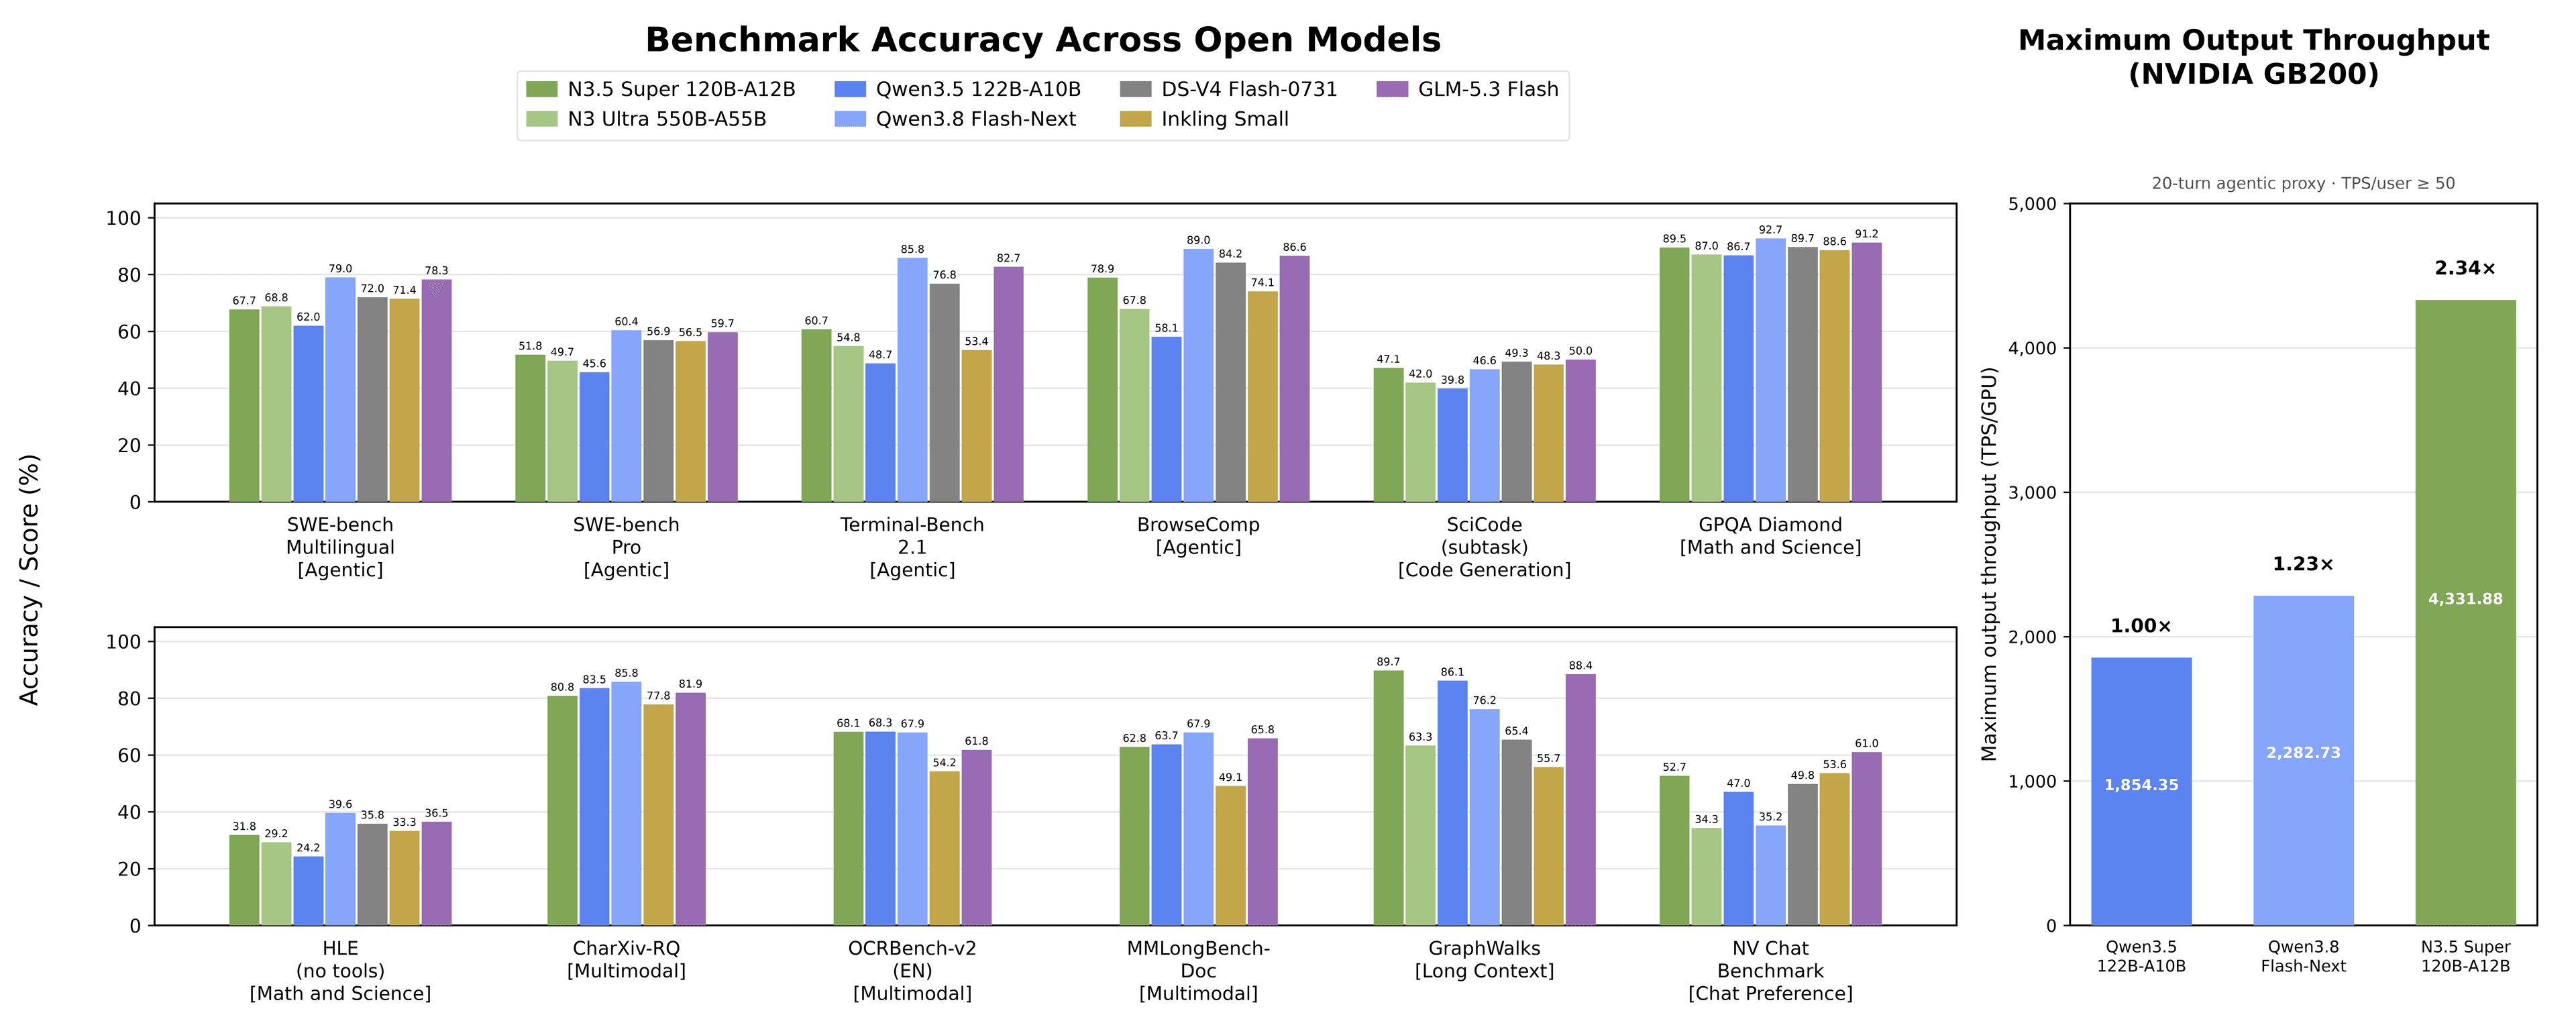
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text / LLM
All Text / LLM →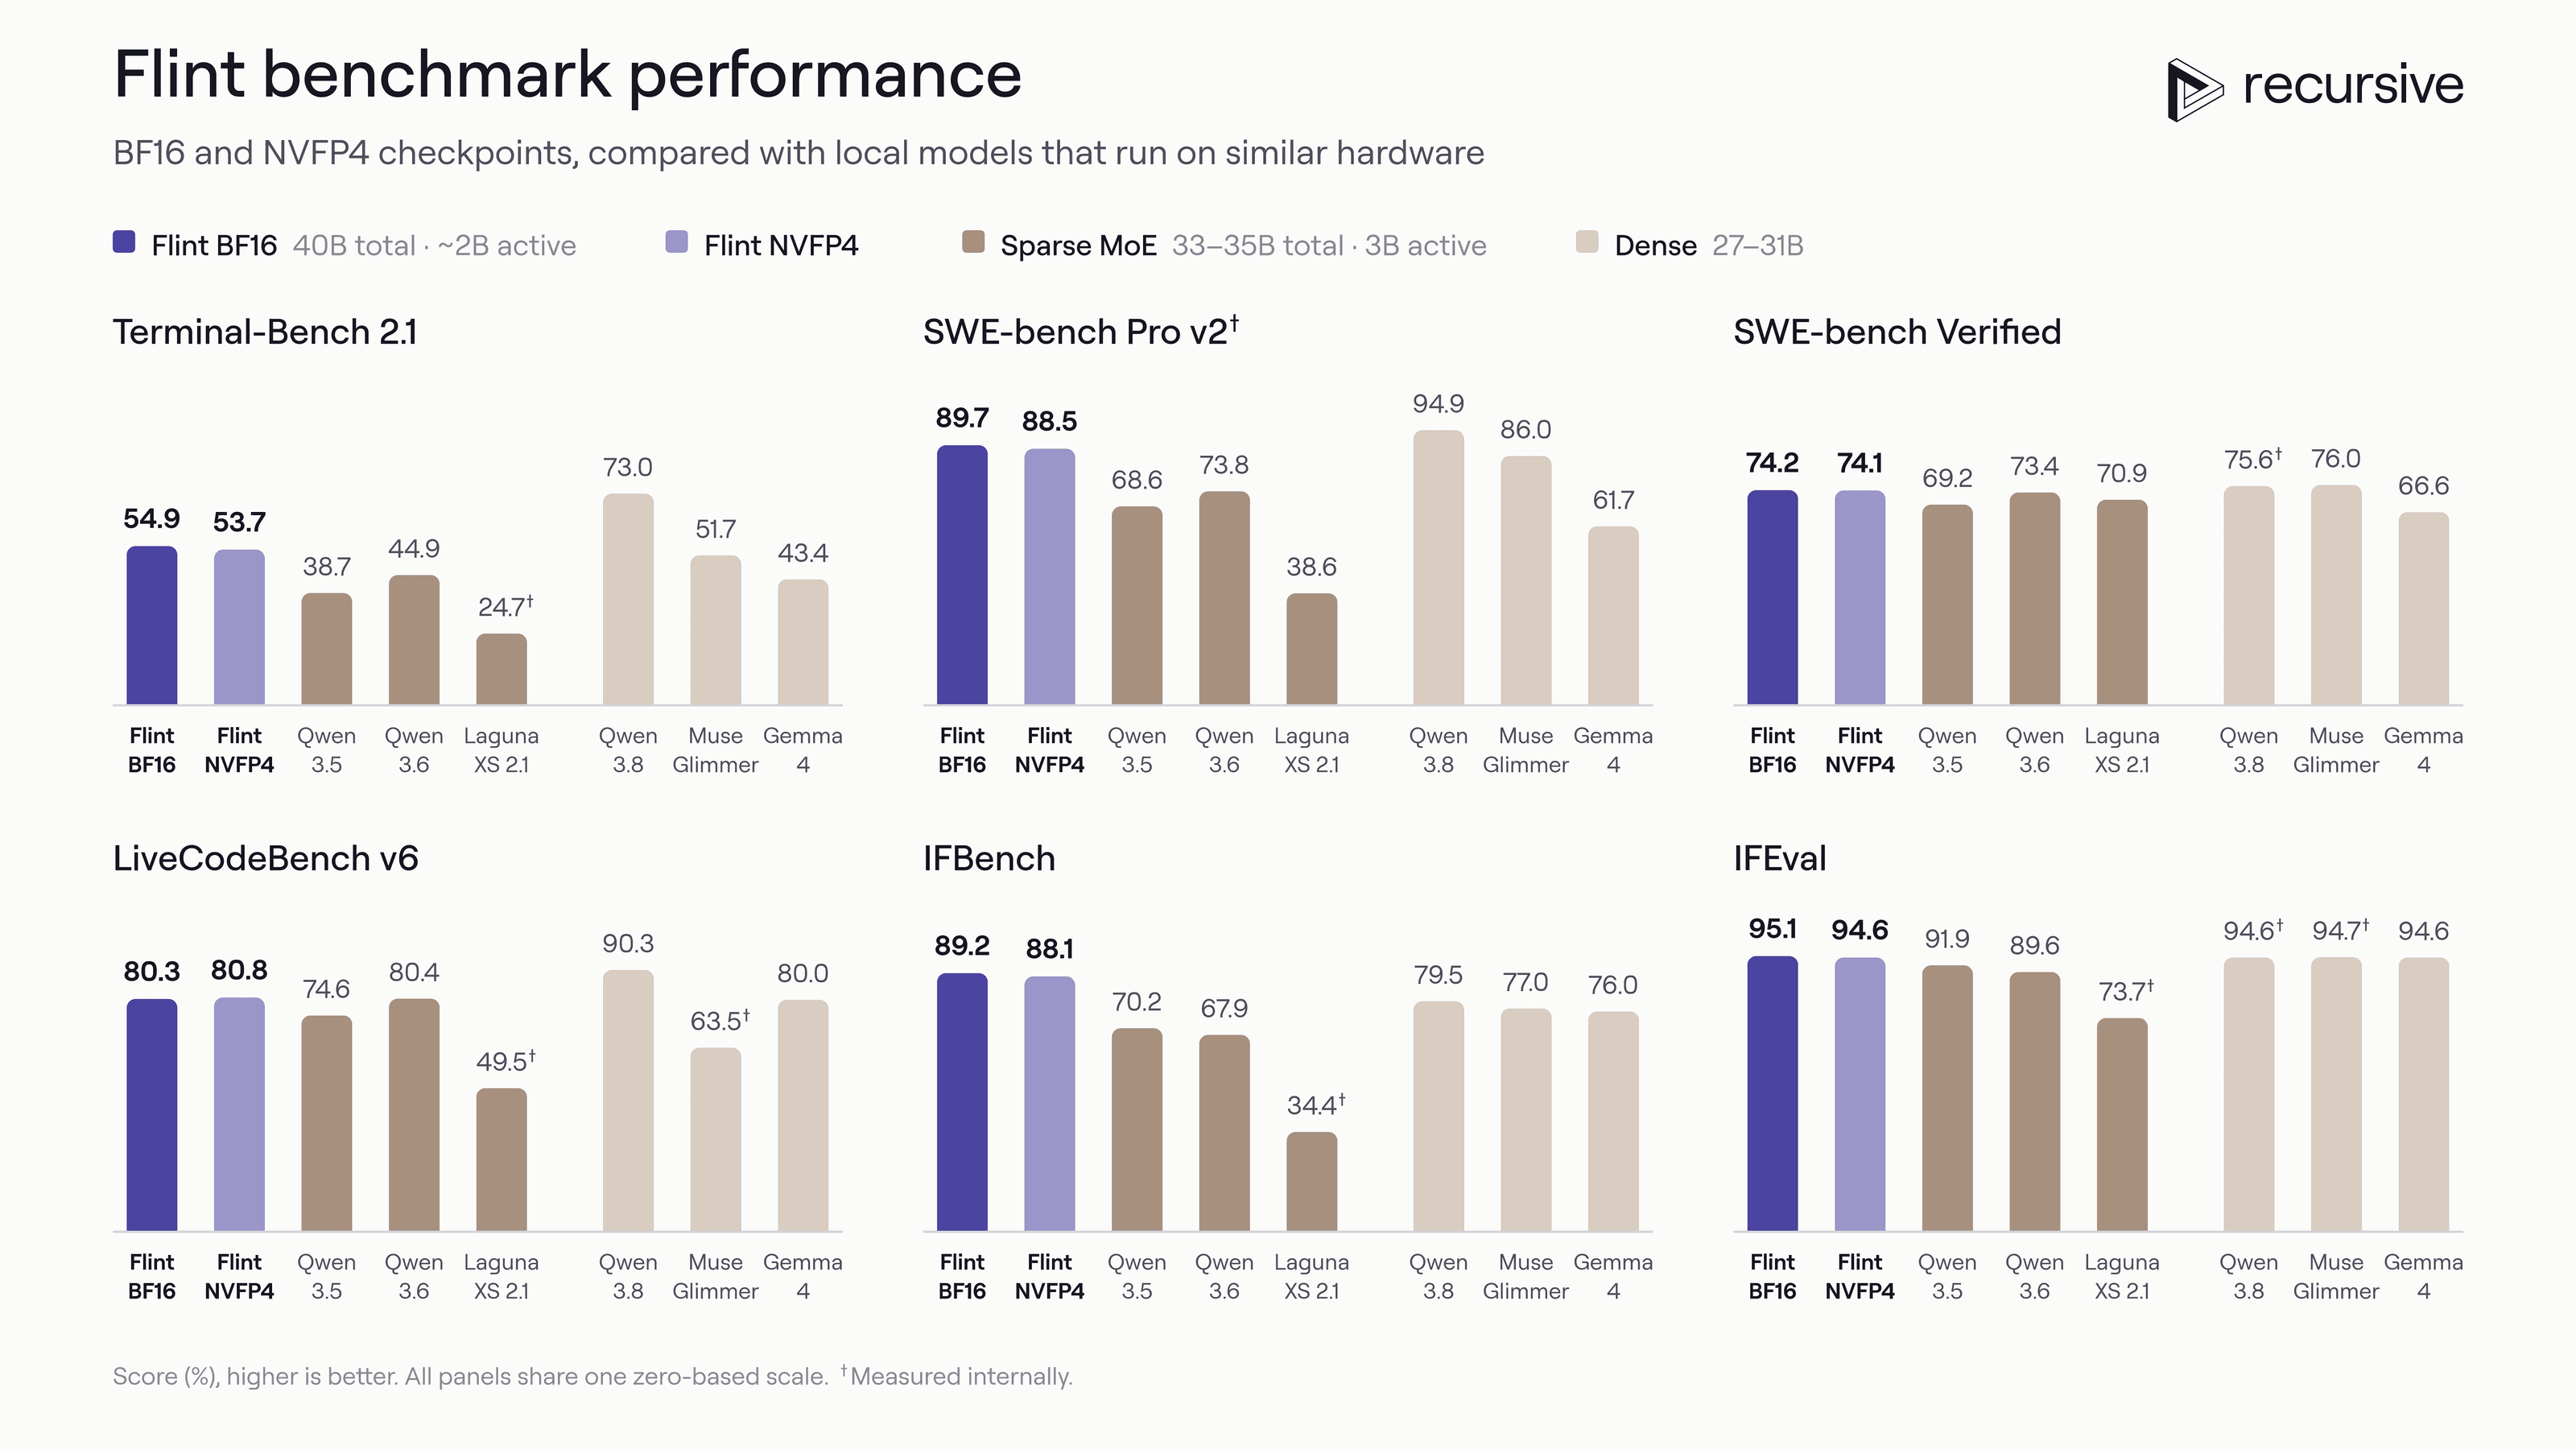
Recursive releases Flint, an Apache-2.0 chat model
The new conversational LLM ships under a permissive license with community GGUF builds already available for local use.
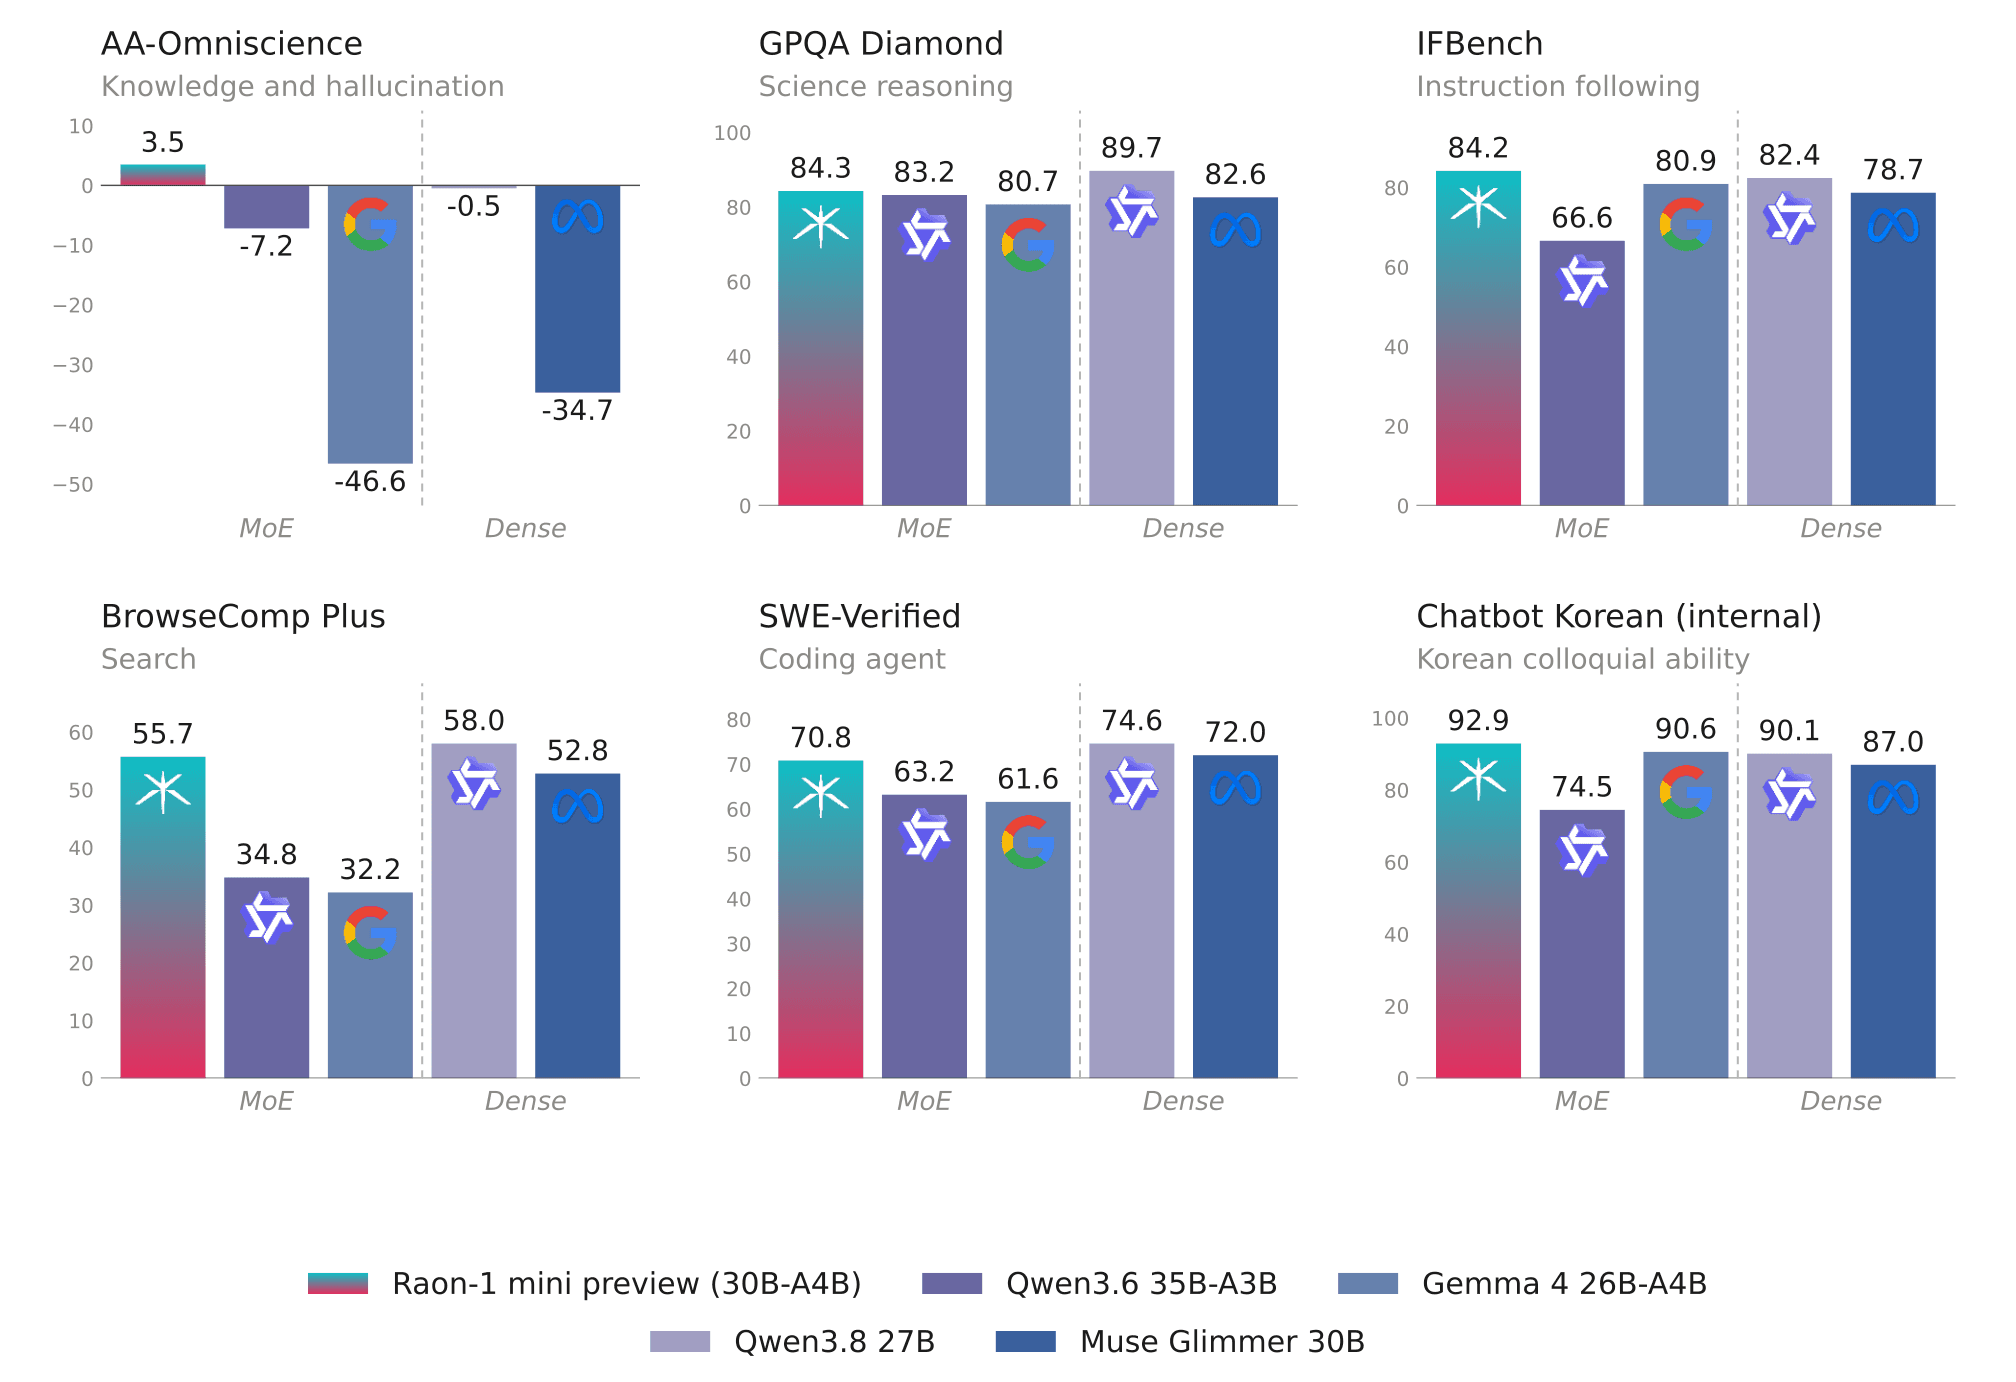
KRAFTON releases Raon-1-mini preview under Apache 2.0
The Korean game studio behind PUBG puts out a compact, permissively licensed language model as an early preview.

DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
0 comments
No comments yet. Be the first to weigh in.