Wan-Dancer-14B turns still images into dance videos
Alibaba's Wan team releases an Apache-2.0 image-to-video model built for music-driven dance generation.

Alibaba's Wan team has published Wan-Dancer-14B, a 14-billion-parameter image-to-video model aimed squarely at a specific creative task: generating dance sequences driven by music. Rather than producing generic video clips, the model is tuned to animate a source image into choreographed movement, a niche that combines motion synthesis with the tricky problem of keeping a subject coherent across frames.
The release lands under the permissive Apache 2.0 license, which matters for anyone hoping to build on it. That licensing choice means developers and studios can experiment, fine-tune, and deploy the model commercially without the usage restrictions that accompany many video generation systems.
Why it matters
Music-driven dance generation has been one of the harder frontiers in video synthesis, requiring models to sync motion to audio timing while preserving the identity and appearance of the input subject. A dedicated open-weights model in this space gives researchers and creators a reproducible starting point instead of relying on closed APIs.
- Image-to-video generation from a single source image
- Focused on music-driven dance and choreography
- 14B parameters, released under Apache 2.0
Wan-Dancer-14B extends the Wan family's push into open video models. As always with a fresh release, the practical questions — output length, resolution, and how well motion holds up over time — will be answered as the community puts the weights, available now on Hugging Face, through its paces.
Sources
- Visit
Wan-AI/Wan-Dancer-14B
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
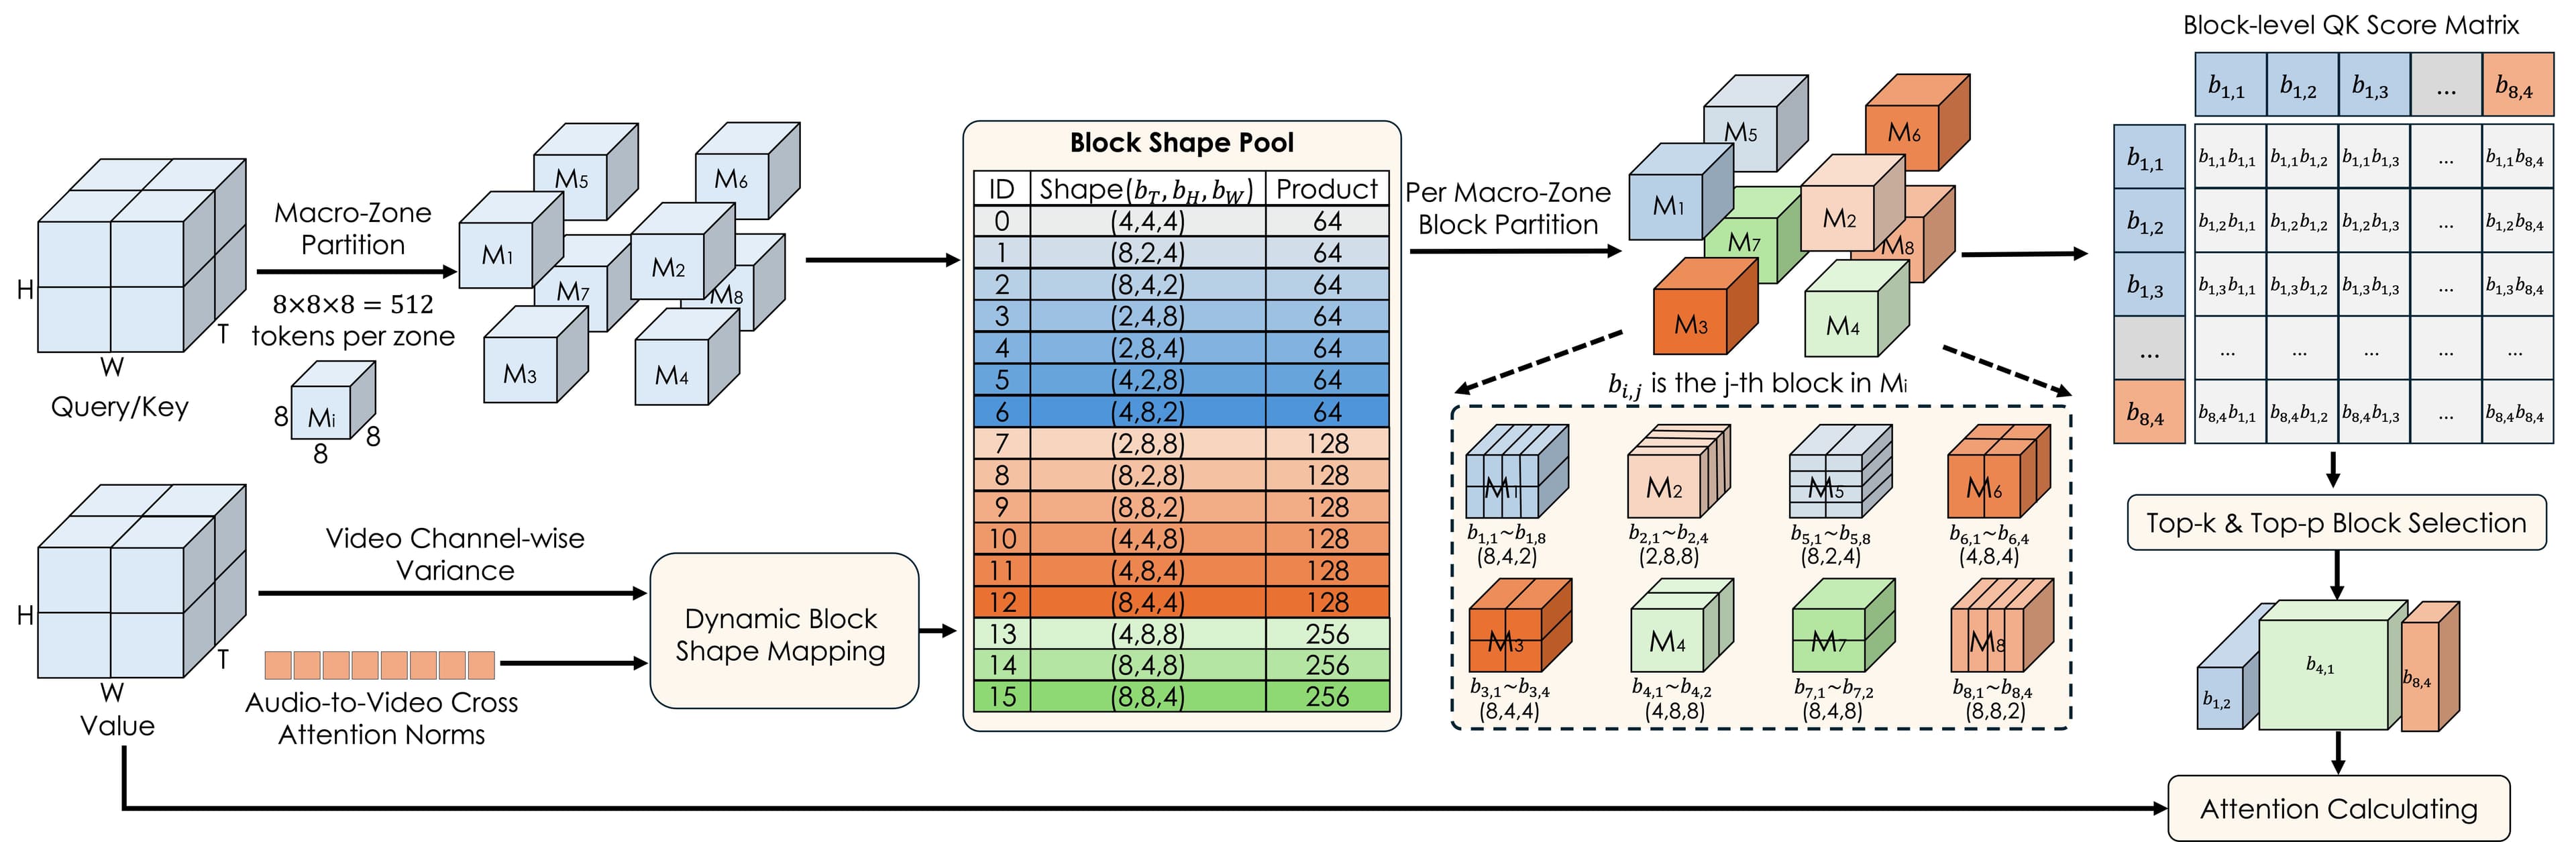
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.