Qwen Enters Music Generation With Qwen-Music
Alibaba's Qwen team debuts a text-to-song model that produces high-fidelity tracks complete with vocals.
Alibaba's Qwen team has released Qwen-Music, its first model aimed at generating complete songs. According to the technical report, the model produces high-fidelity audio that includes sung vocals, taking text descriptions, lyrics, and musical prompts as inputs.
The pitch is straightforward: rather than generating instrumental beds or short loops, Qwen-Music targets full songs where the words a user supplies are actually sung. That combination of lyric-conditioned vocals and instrumental backing places it alongside a small but growing group of systems attempting end-to-end music creation.
Why it matters
Qwen has become one of the most prolific open-model families, spanning text, vision, and audio. Extending the brand into music signals that Alibaba sees generative audio as part of its broader multimodal strategy, and it gives developers another option outside the handful of well-known music generators.
- Inputs span text, lyrics, and musical prompts
- Output is high-fidelity song audio with vocals
- Released under Qwen's own license as a version 1.0
As an initial release, the details that will matter most — training data, evaluation against rival systems, and practical licensing limits — are worth scrutinizing as the model reaches wider use. For now, Qwen-Music establishes a foothold in a category the team has not previously entered.
Sources
- Visit
Qwen-Music Technical Report
HF Papers
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Music
All Music →StepFun's StepAudio 3 Music Plans Before It Plays
The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.
StepFun's StepAudio 3 Gen Unifies TTS and Music
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
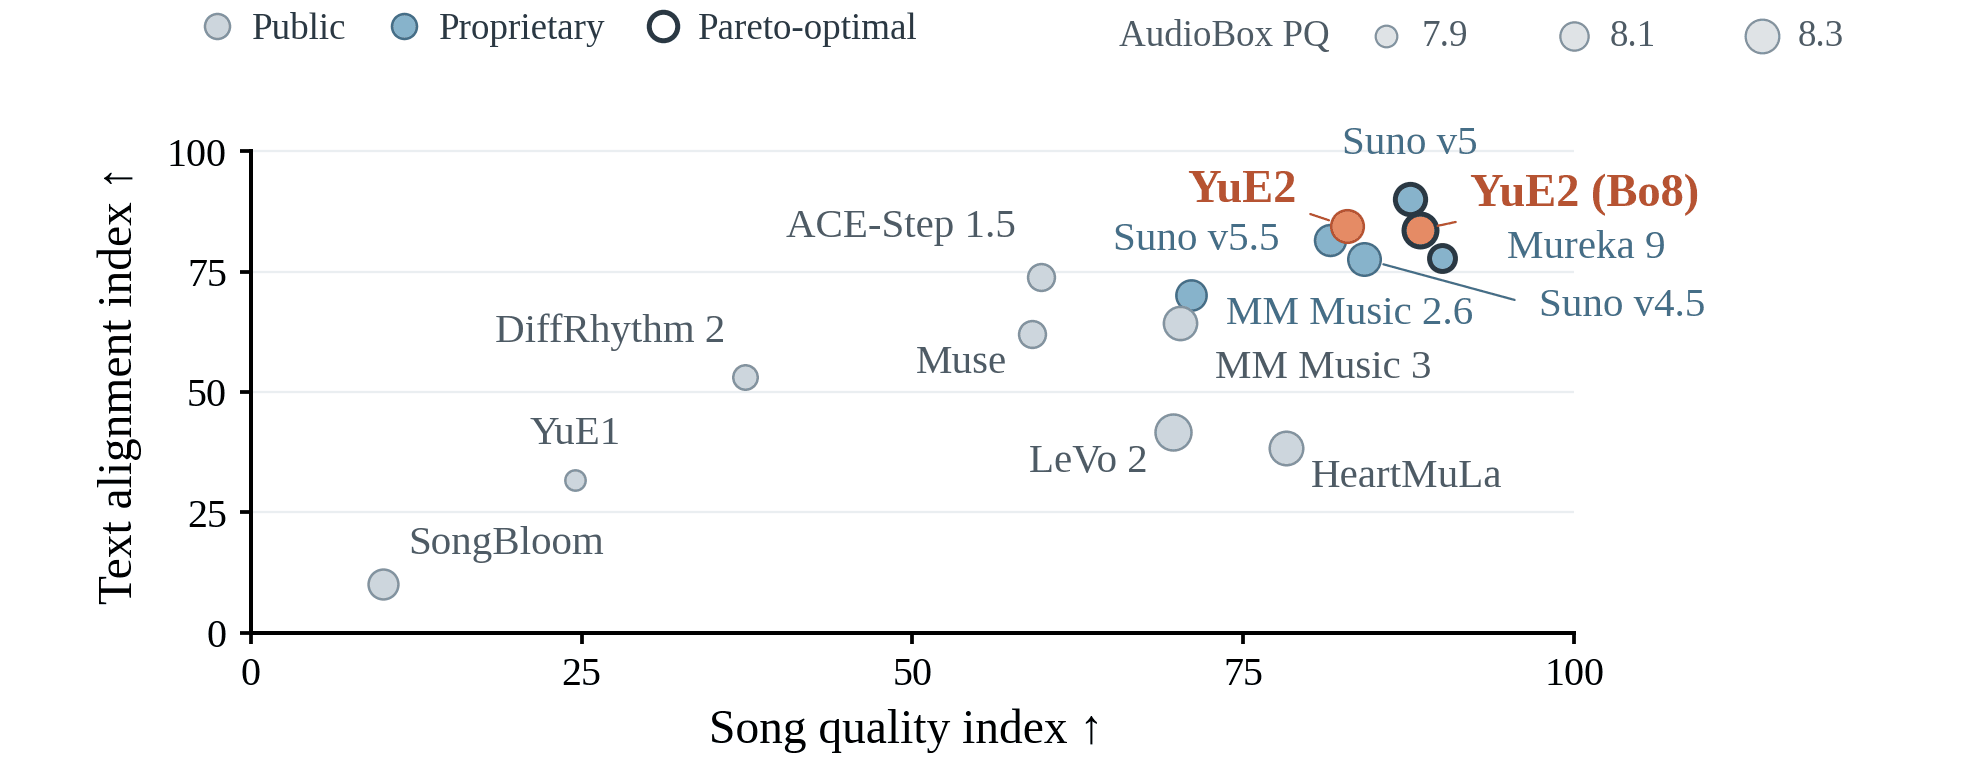
OpenMOSS Unveils YuE2-3B Music Generation Model
The 3-billion-parameter model adds symbolic planning and agentic editing to open-source music generation.
0 comments
No comments yet. Be the first to weigh in.