Lightricks Releases LTX-2 Multimodal Video Generator
The new diffusion model from the creative app company can generate short video clips from text, images, audio, and even other videos.
Lightricks, the company behind popular creative apps like Facetune and Videoleap, has released LTX-2, a powerful multimodal model for video synthesis. Unlike many generators that focus on a single input type, LTX-2 is designed for versatility, capable of creating video clips from a wide range of prompts including text descriptions, still images, audio tracks, and existing videos.
The model is built on a latent video diffusion architecture. It uses a suite of specialized encoders to interpret different inputs: a T5-based encoder for text, a CLIP encoder for images, and a CLAP encoder for audio. These components work together within a U-Net backbone to translate multimodal concepts into coherent video sequences.
Open Under a Responsible AI License
Lightricks has made the model weights available on Hugging Face, but its use is governed by a CreativeML Open RAIL-M license. This is a “Responsible AI License” that permits commercial use but includes specific restrictions against certain applications, such as generating misinformation or content for malicious purposes. This licensing strategy is part of a growing trend where developers aim to balance open access with safeguards against misuse.
While LTX-2 represents another step forward for accessible video generation tools, the creators note its limitations. Like many current video models, it can sometimes produce visual artifacts and may struggle with perfect temporal consistency over longer clips. The model is available for download and experimentation on the Hugging Face Hub.
Sources
- Visit
Lightricks/LTX-2
Hugging Face
More from Lightricks
All Lightricks releases →
Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.

Lightricks Releases LoRA for AI Lip-Dubbing
The new 'Identity-Control' adapter fine-tunes the company's LTX-2.3 video model to create realistic lip-syncing for dubbing workflows.
Lightricks LTX-2.3 Generates Video and Audio Together
The new model, based on Stable Video Diffusion, can create video and a corresponding soundtrack simultaneously from text, image, or audio prompts.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
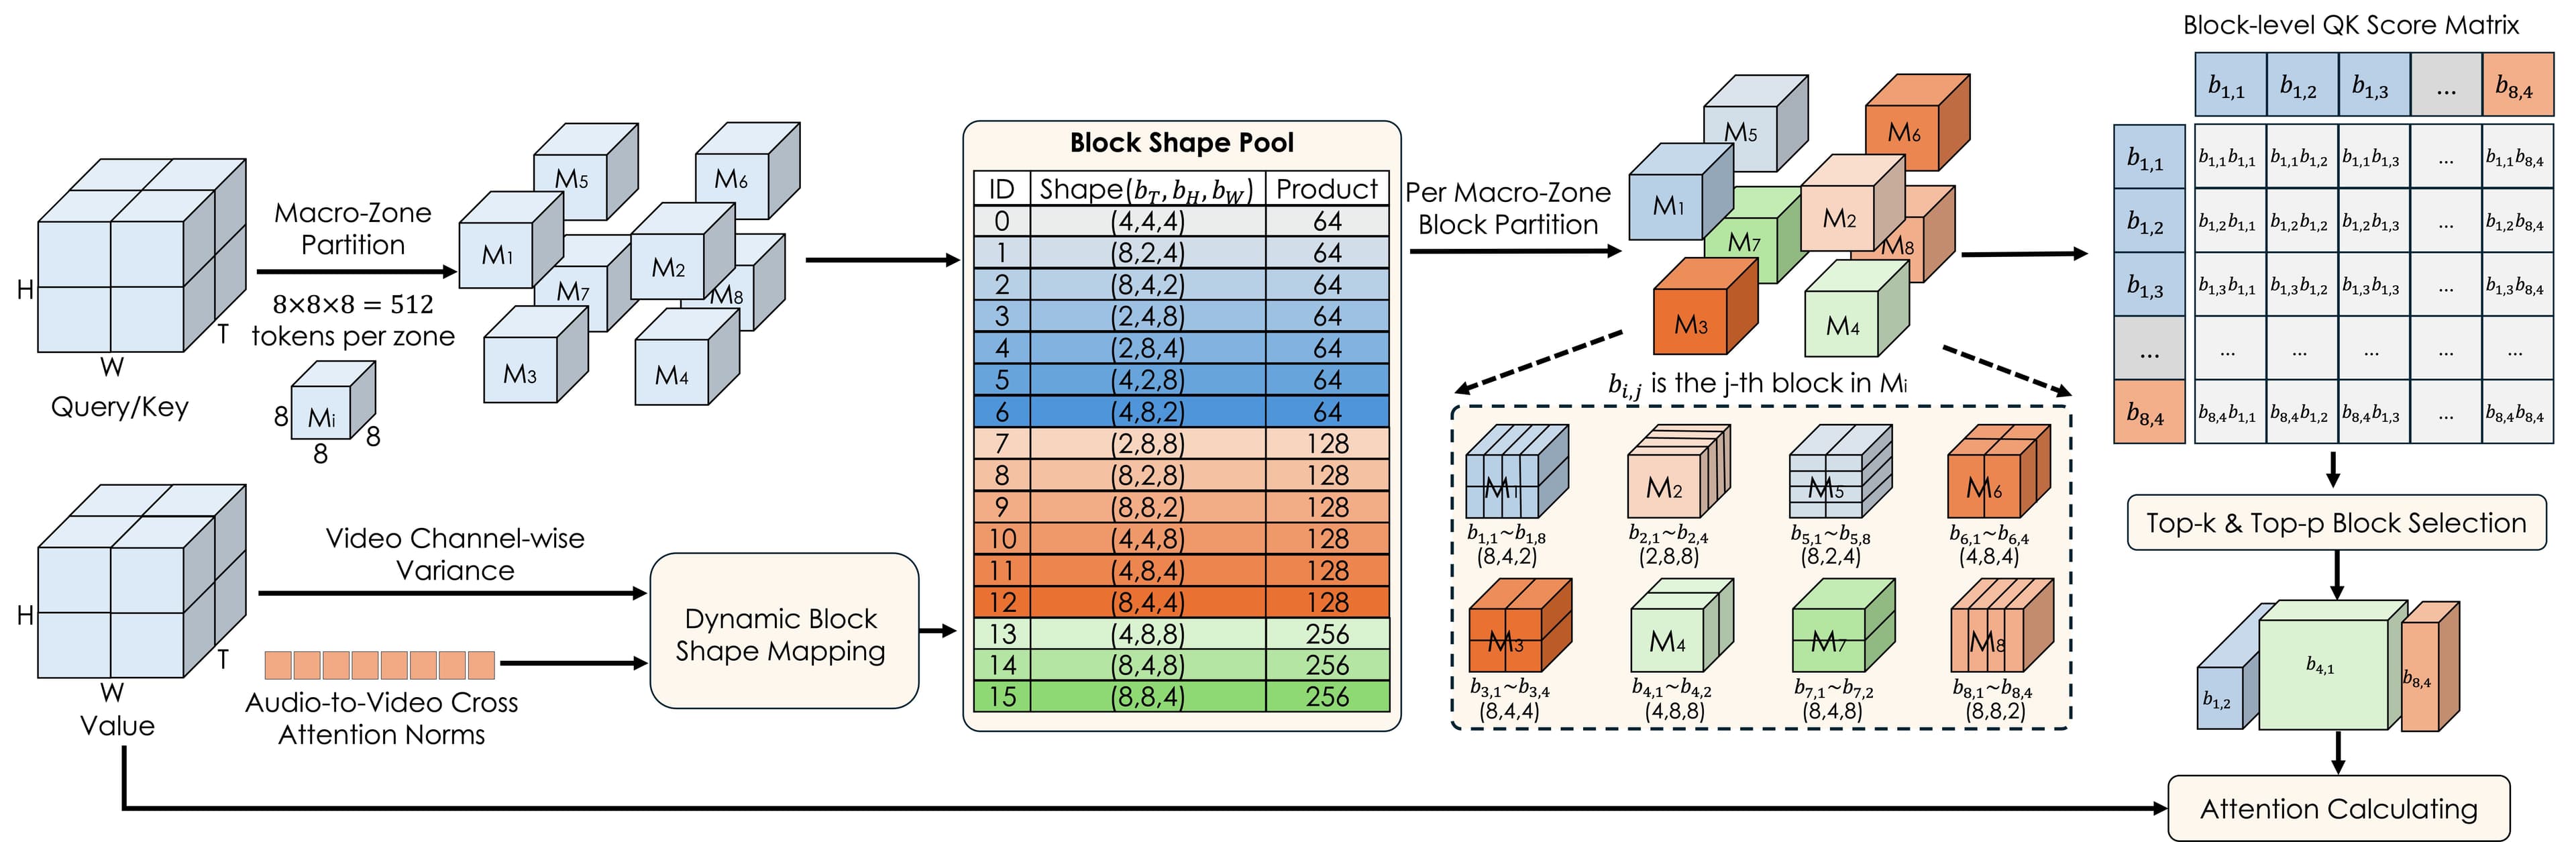
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.