Upstage's Solar Open2 arrives as a 250B MoE model
The Korean AI firm's latest open release scales to 250 billion parameters with a mixture-of-experts design tuned for English and Korean.
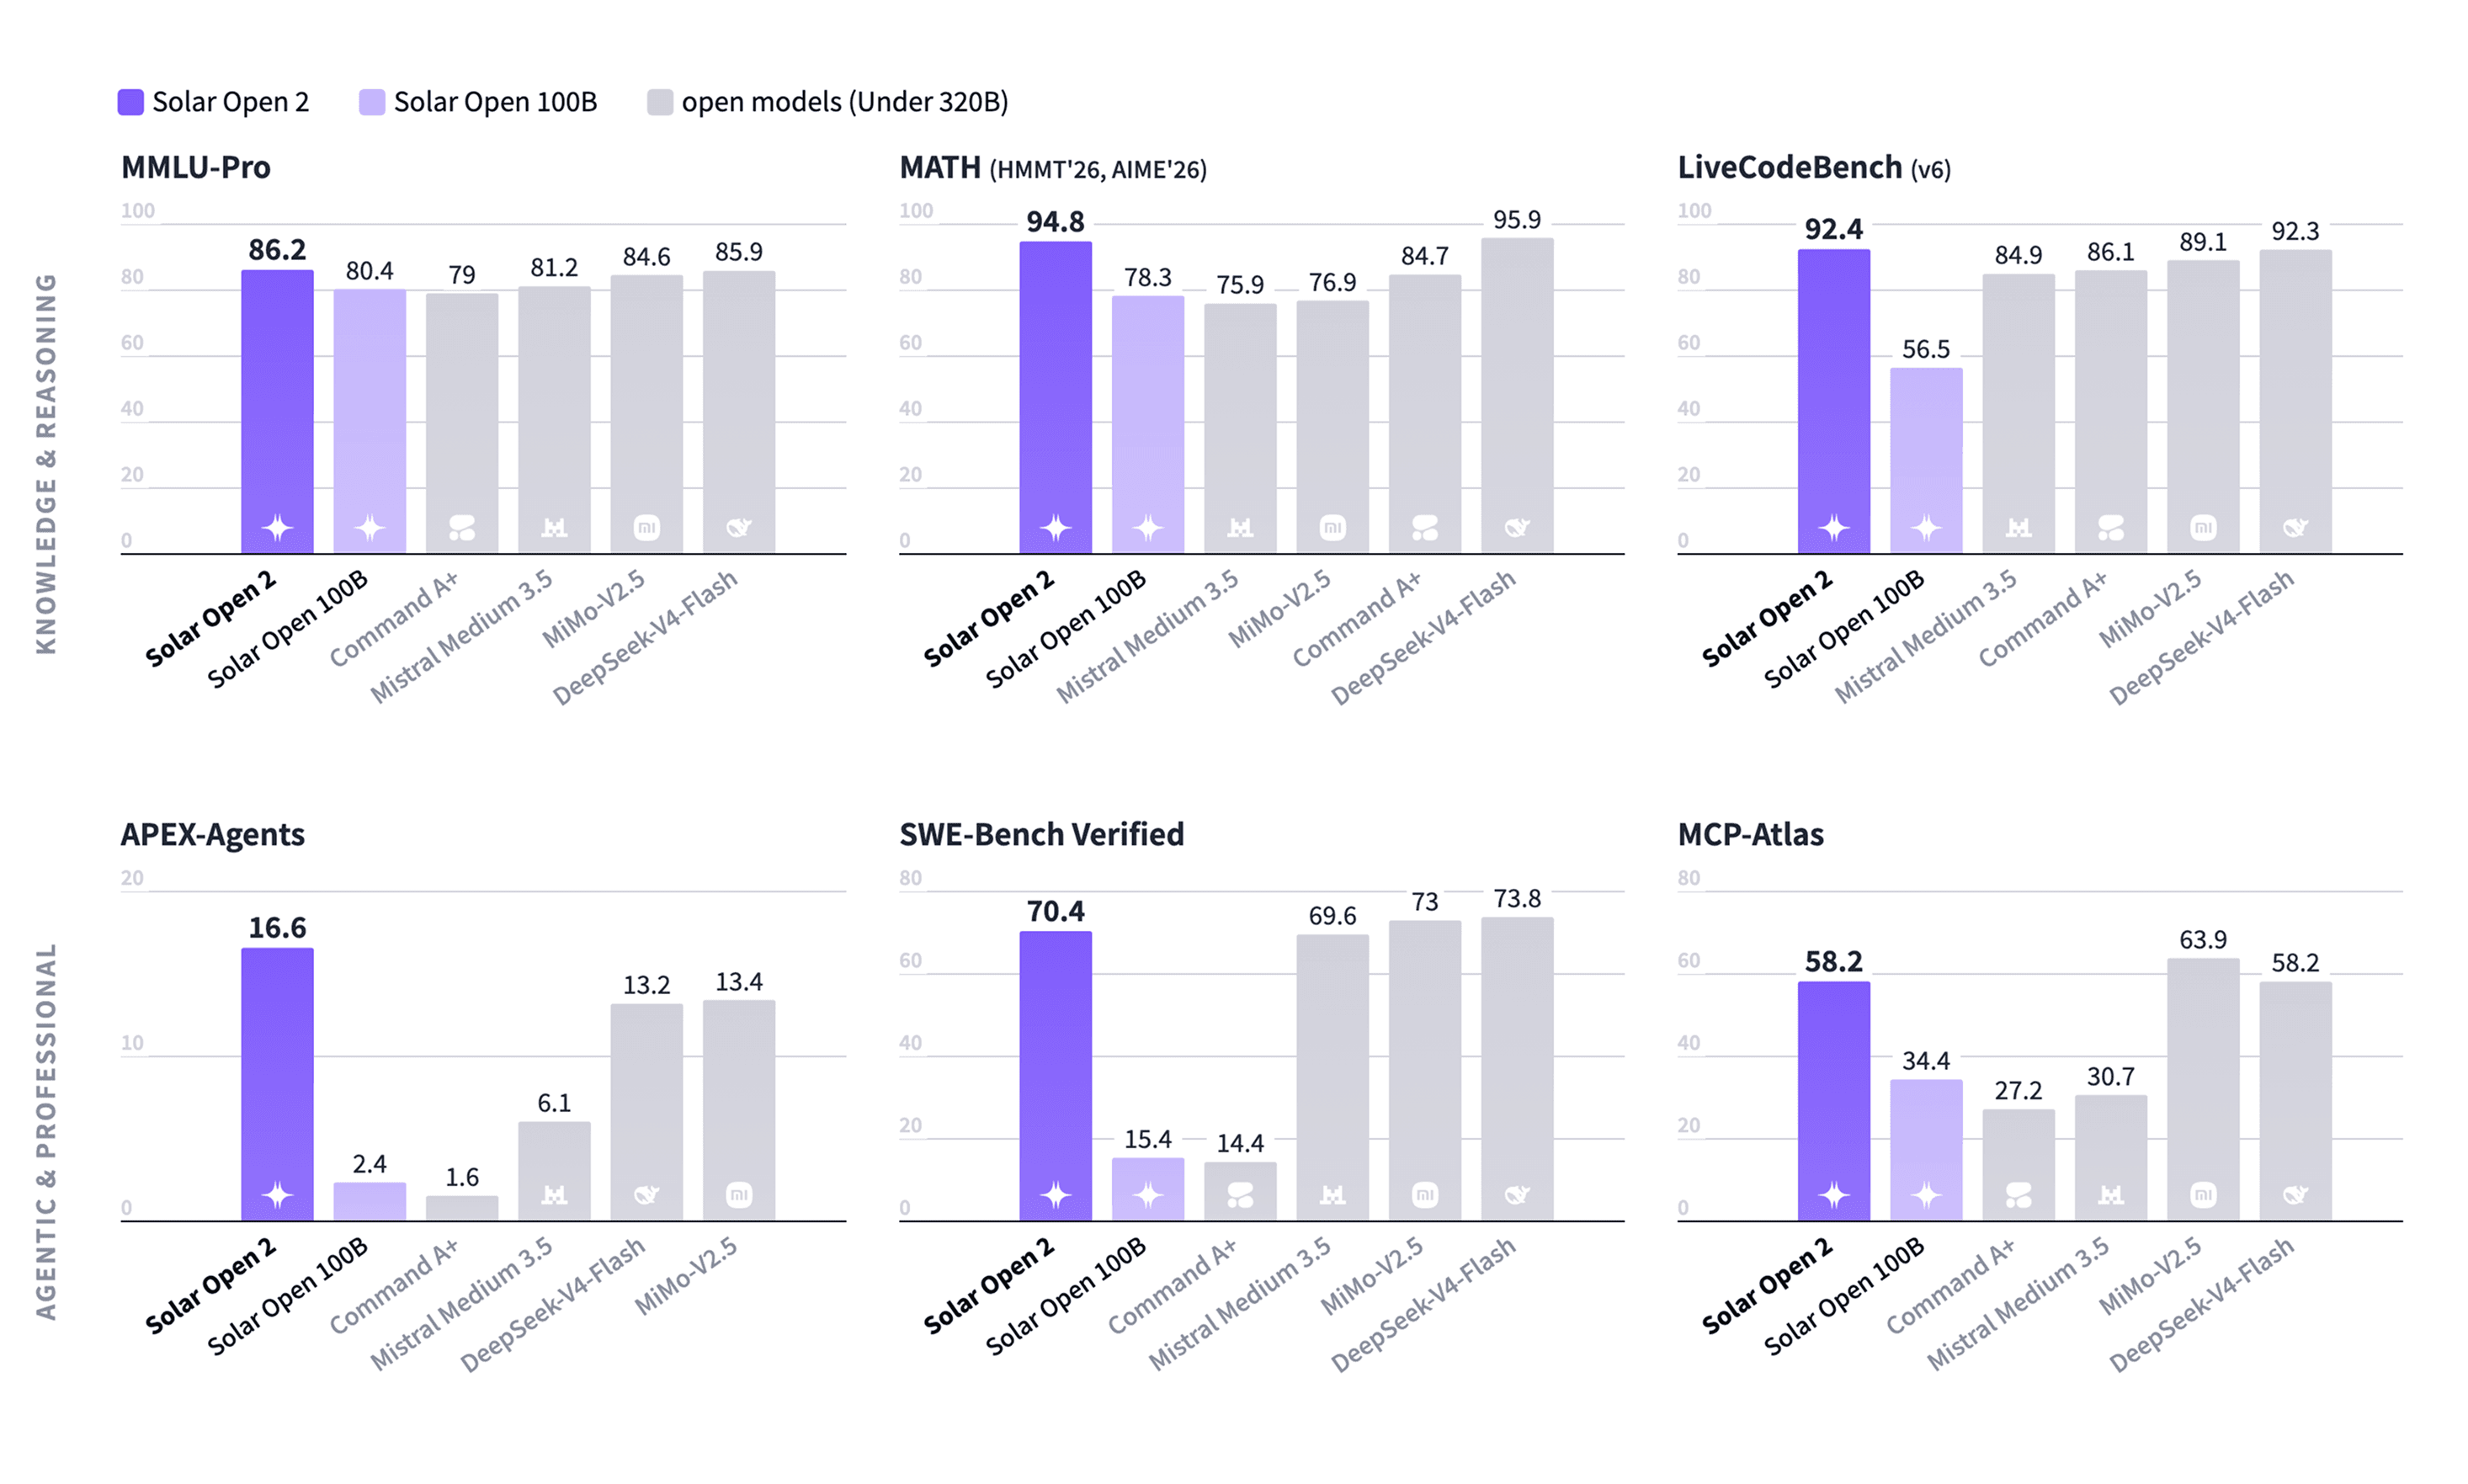
Upstage has released Solar Open2 250B, a text-generation model built on a mixture-of-experts (MoE) architecture and made available on Hugging Face. The release marks a notable step up in scale for the Korean company's open Solar line, which has focused on delivering competitive language models outside the largest US labs.
The headline figure is a 250-billion-parameter footprint. As an MoE system, the model routes each token through a subset of specialized expert networks rather than activating every parameter at once — an approach that lets developers pursue large total capacity while keeping inference costs more manageable than a comparably sized dense model.
Bilingual by design
Solar Open2 is aimed squarely at English and Korean workloads. That bilingual focus has been a consistent thread for Upstage, whose earlier Solar models earned attention for punching above their size, and it positions the release as a practical option for teams building products for Korean-language users where many Western open models underperform.
A few details worth noting from the release:
- Distributed openly under a custom ("other") license, so teams should review the terms before commercial use.
- Weights are hosted directly on Hugging Face for download and self-hosting.
- Context length and detailed benchmark figures were not specified in the initial listing.
Why it matters: Large open MoE models remain relatively rare, and most of the highest-profile ones come from a handful of labs. A 250B bilingual release from Upstage widens the field and gives Korean-focused developers a large-scale option they can inspect and run themselves rather than access only through an API.
Sources
- Visit
upstage/Solar-Open2-250B
Hugging Face
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.