Tencent Releases 2B Vision Model for Robotics
The new HY-Embodied 0.5 is a vision-language model designed specifically for multi-object tracking in dynamic, real-world environments.
Tencent's Hunyuan team has released HY-Embodied 0.5, a new 2-billion-parameter vision-language model aimed at the growing field of embodied AI.
Unlike many general-purpose VLMs that focus on static image captioning, HY-Embodied is built on an end-to-end Multi-object Tracking (MoT) architecture. This allows the model to perceive and follow multiple distinct objects through video sequences—a critical capability for robots and other autonomous agents that need to understand dynamic scenes.
A Foundation for Physical Agents
The model's specialized design bridges the gap between passive visual understanding and the active interaction required in robotics. By providing a unified system for tracking objects over time, HY-Embodied could enable more sophisticated behaviors in applications like:
- Robotic navigation and manipulation
- Autonomous vehicle systems
- Advanced video analysis
The release signals a move towards creating foundational models for specific, complex domains beyond simple text and image generation. The HY-Embodied 0.5 model is available on Hugging Face under a custom license agreement.
Sources
- Visit
tencent/HY-Embodied-0.5
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
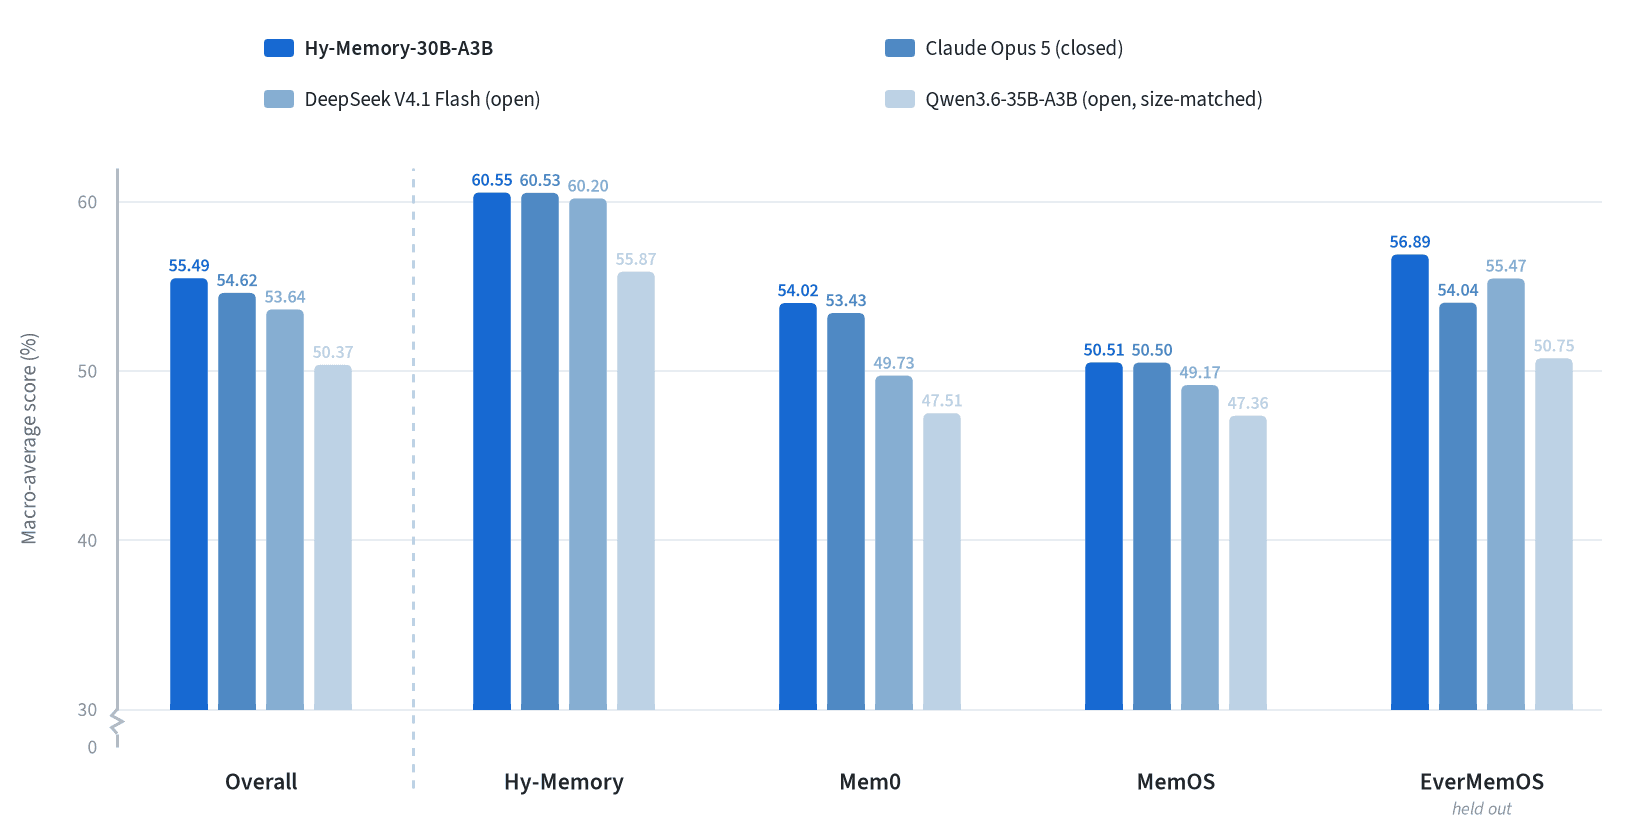
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
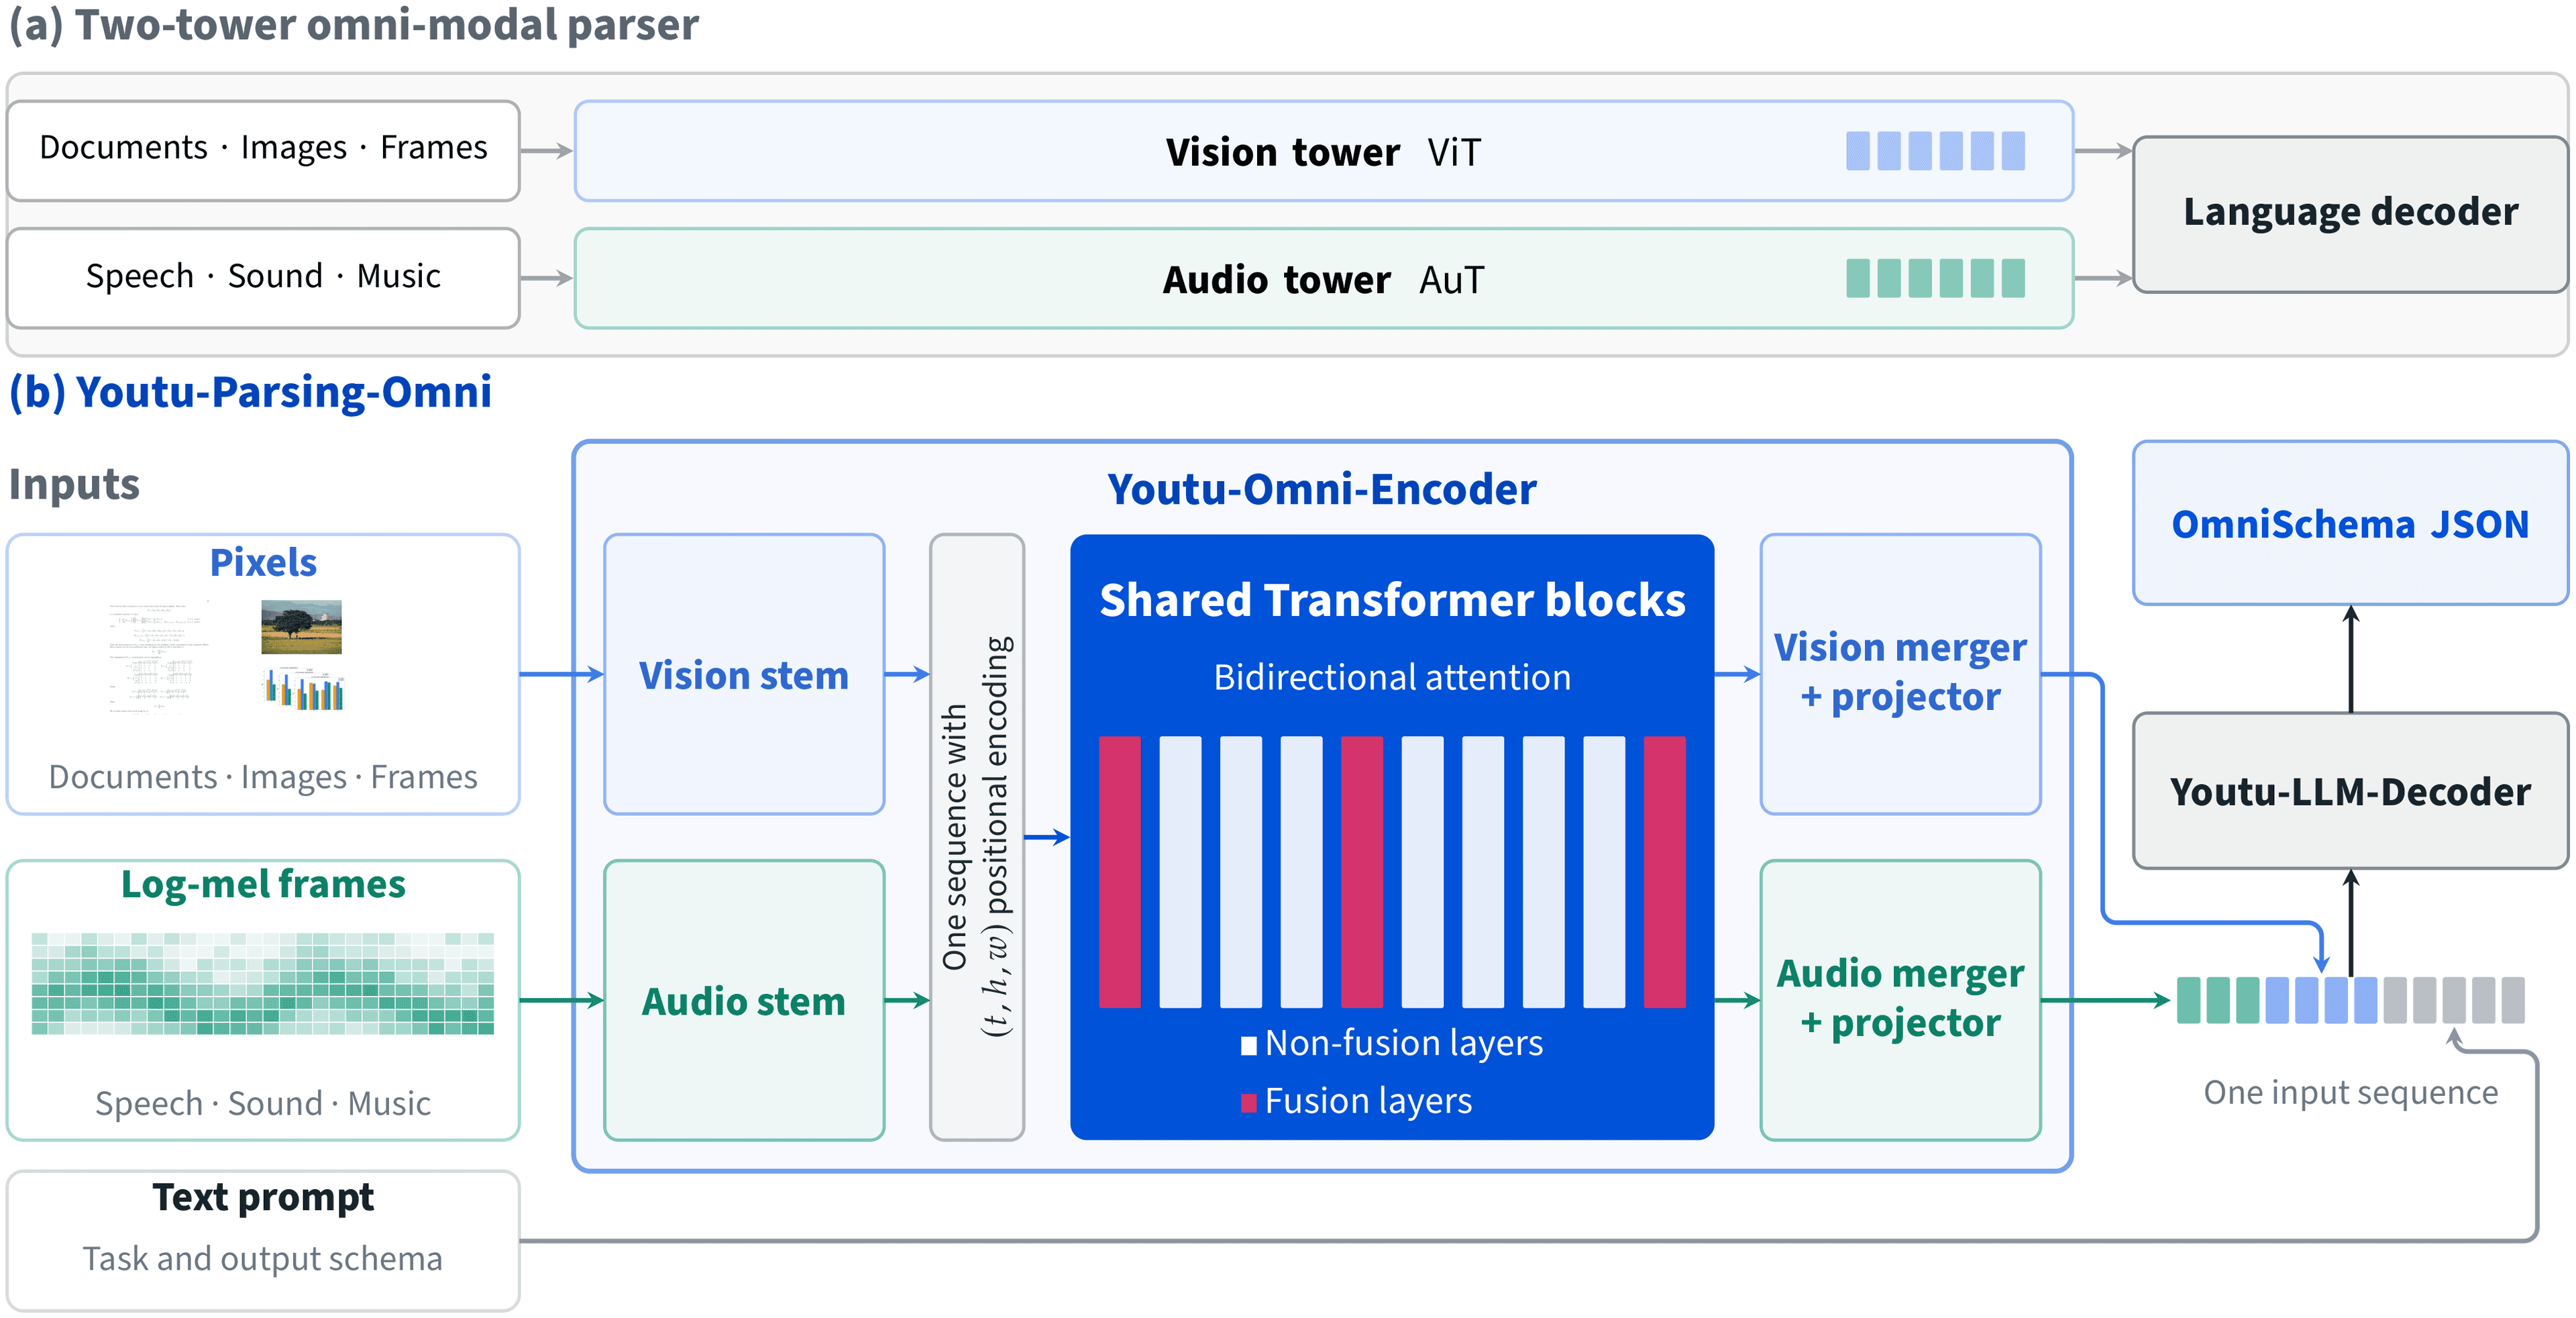
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Vision-Language
All Vision-Language →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
0 comments
No comments yet. Be the first to weigh in.