Tencent Releases HunyuanImage 3.0 Text-to-Image Model
The new text-to-image generator from the Chinese tech giant uses a Mixture-of-Experts architecture for improved efficiency and output quality.
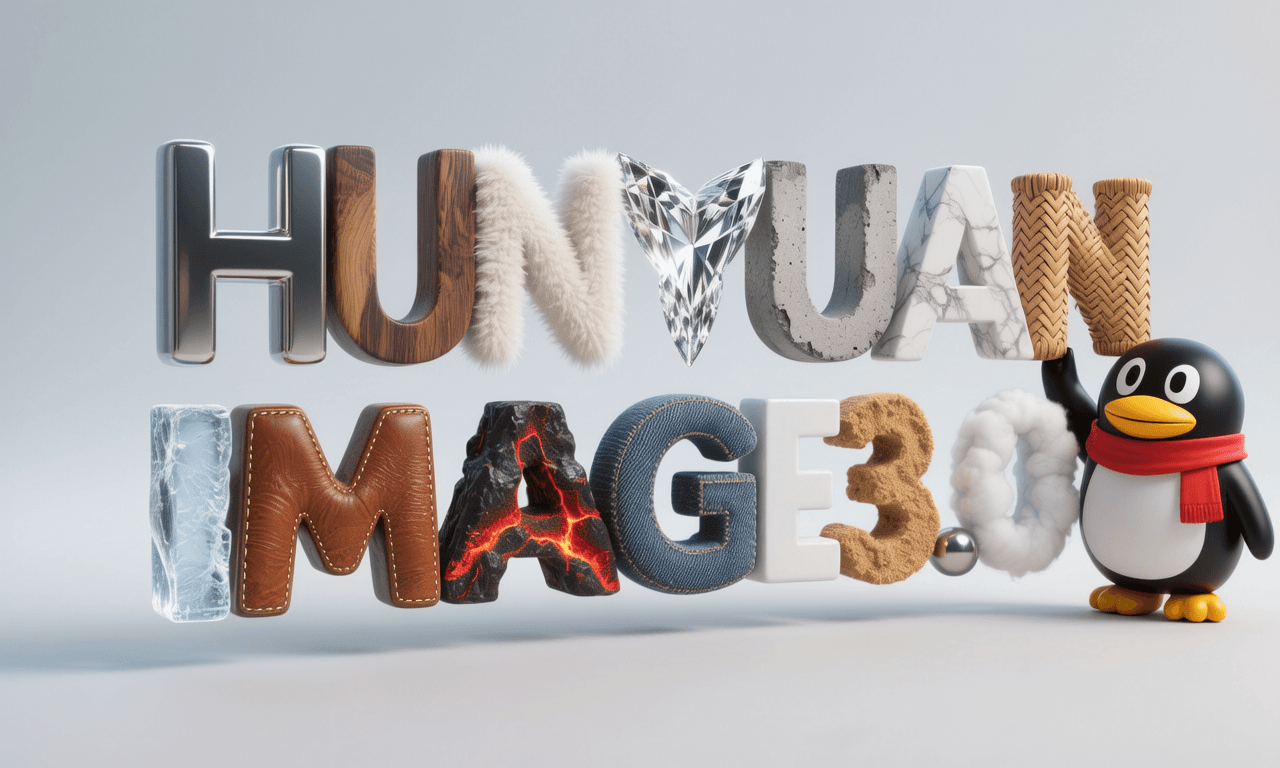
Tencent has released the weights for HunyuanImage 3.0, its latest generative model for creating images from text prompts. This release marks a significant entry into the open-weights image generation space from the multinational tech company, offering a sophisticated new tool for researchers and developers.
The model's core architecture is a Diffusion Transformer (DiT) that incorporates a Mixture-of-Experts (MoE) approach. Unlike monolithic models, an MoE architecture activates specialized sub-networks based on the input prompt. This allows HunyuanImage 3.0 to handle a diverse range of concepts more efficiently and can lead to higher-quality, more detailed outputs.
Enhanced Prompt Understanding
A key feature of HunyuanImage 3.0 is its use of a multimodal large language model to refine and rewrite user prompts before the image generation process begins. According to Tencent, this step significantly improves the model's ability to interpret and adhere to complex instructions. The model is also designed to be fully bilingual, with strong capabilities in both Chinese and English, and shows a particular strength in generating imagery with Asian cultural elements.
The complete model weights are available on the Hugging Face Hub for download. It's important to note that the model is released under a custom license that permits academic research and non-commercial use only. This makes it a valuable resource for experimentation but restricts its application in commercial products.
Sources
- Visit
tencent/HunyuanImage-3.0
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
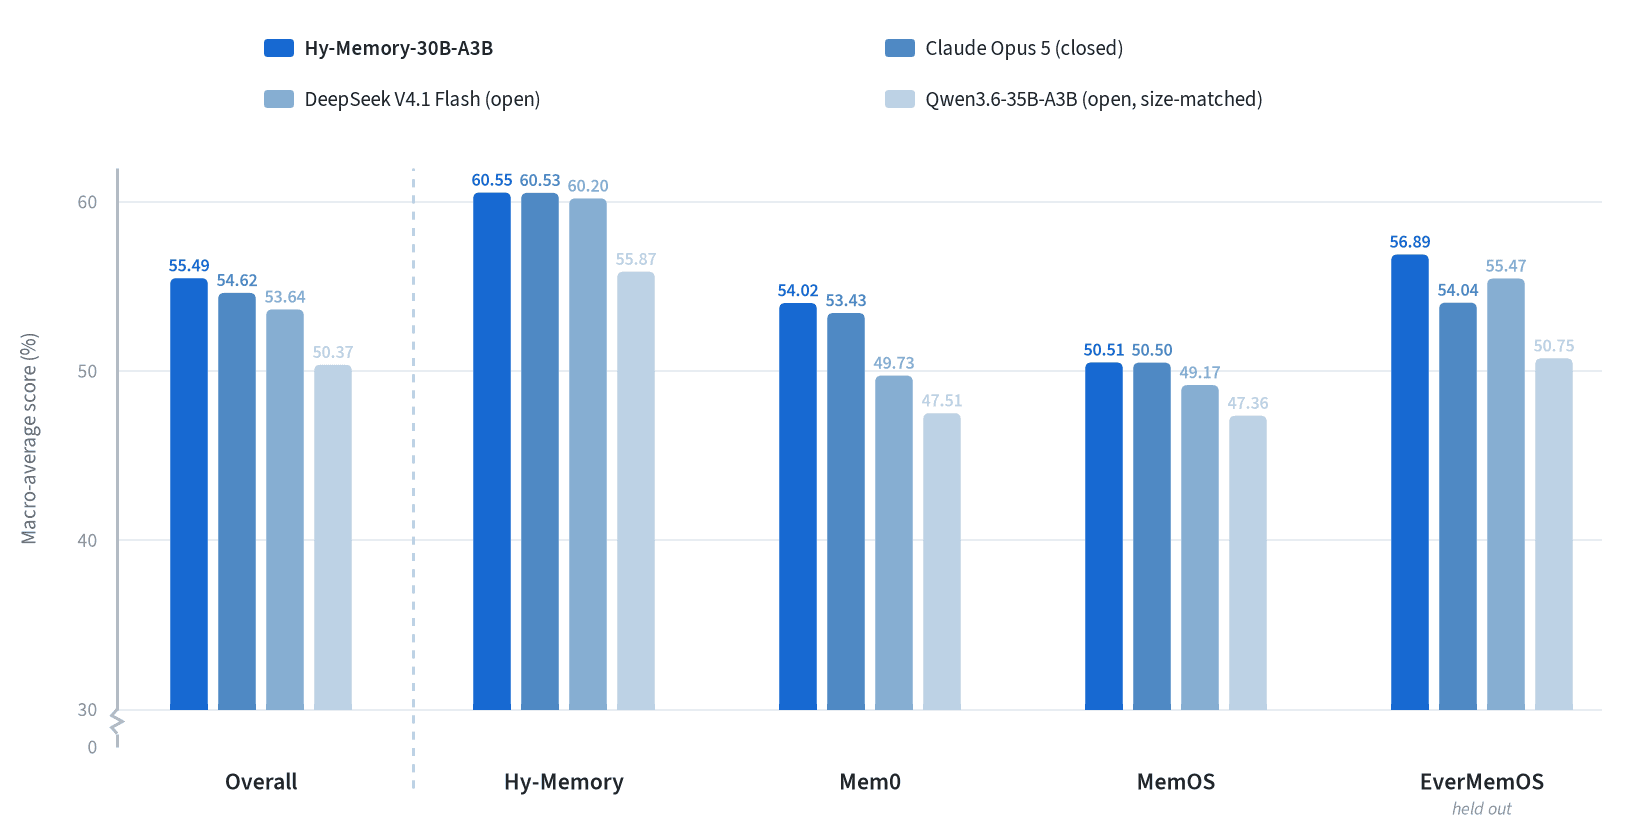
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
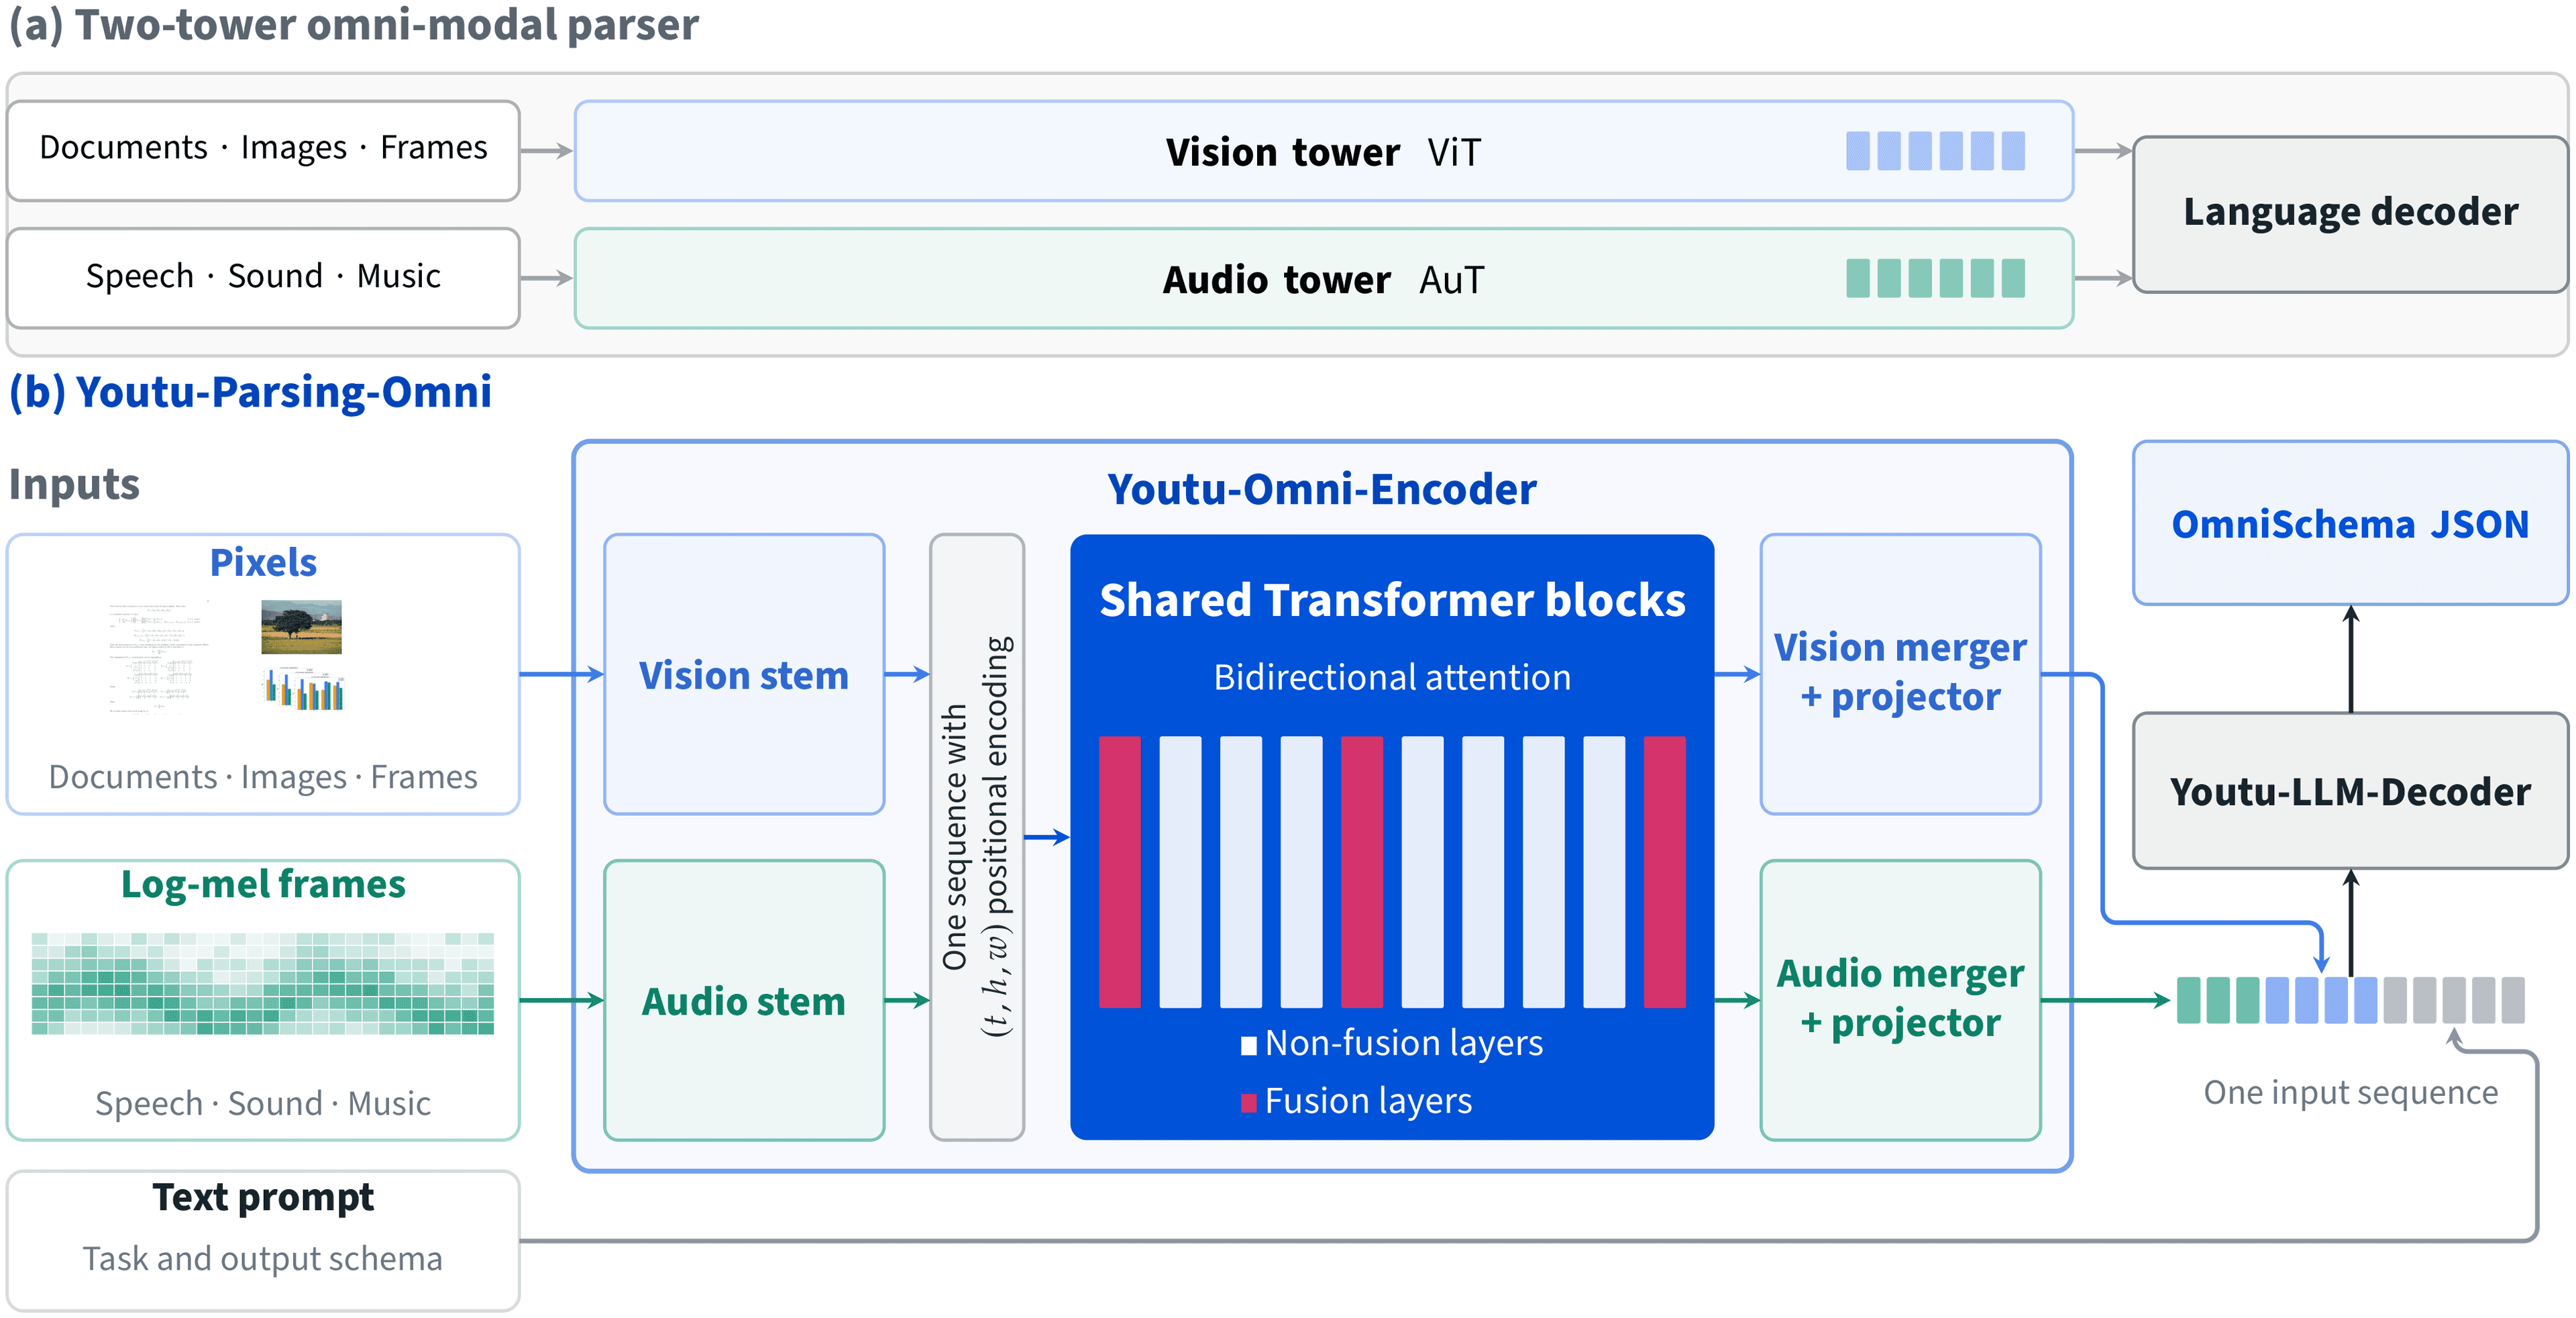
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.