Tencent Debuts HunyuanImage 3.0 with MoE Design
The new text-to-image generator from the Chinese tech giant uses a Mixture-of-Experts architecture for more efficient and detailed image creation.
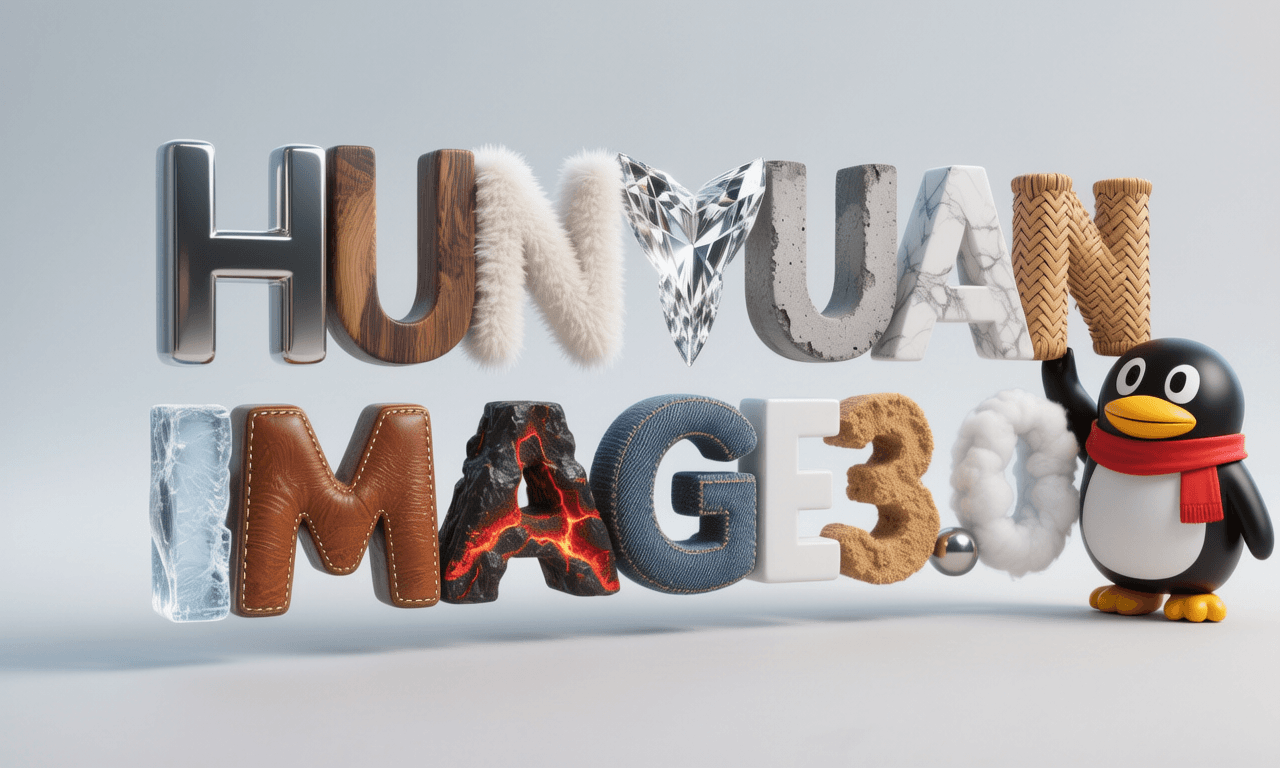
Tencent has released HunyuanImage 3.0 Instruct, a new text-to-image model that brings an architectural design more commonly seen in large language models to the world of image generation. The model is part of the company's Hunyuan series and is now available for researchers and developers to explore.
An Expert Approach to Pixels
The key innovation in HunyuanImage 3.0 is its use of a Mixture-of-Experts (MoE) framework. This allows the model to activate only the most relevant parts of its network for a given task, potentially leading to more efficient processing and higher-quality outputs. By combining this with an instruction-tuned approach, the model is designed to better understand and execute complex, multi-part prompts.
The model's architecture is built on a transformer backbone called Hunyuan-DiT. According to Tencent's release notes, this enables strong performance in areas like following detailed instructions and even engaging in multi-turn, dialogue-based image creation, making the generation process more conversational.
While the weights are publicly accessible on the Hugging Face Hub, they are released under a custom license. Users should review the specific terms of the "Hunyuan-Image-3.0-Instruct License Agreement" before using the model in their projects. This release marks another significant entry from a major tech firm into the open-weights AI landscape, pushing new architectures into different modalities.
Sources
- Visit
tencent/HunyuanImage-3.0-Instruct
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
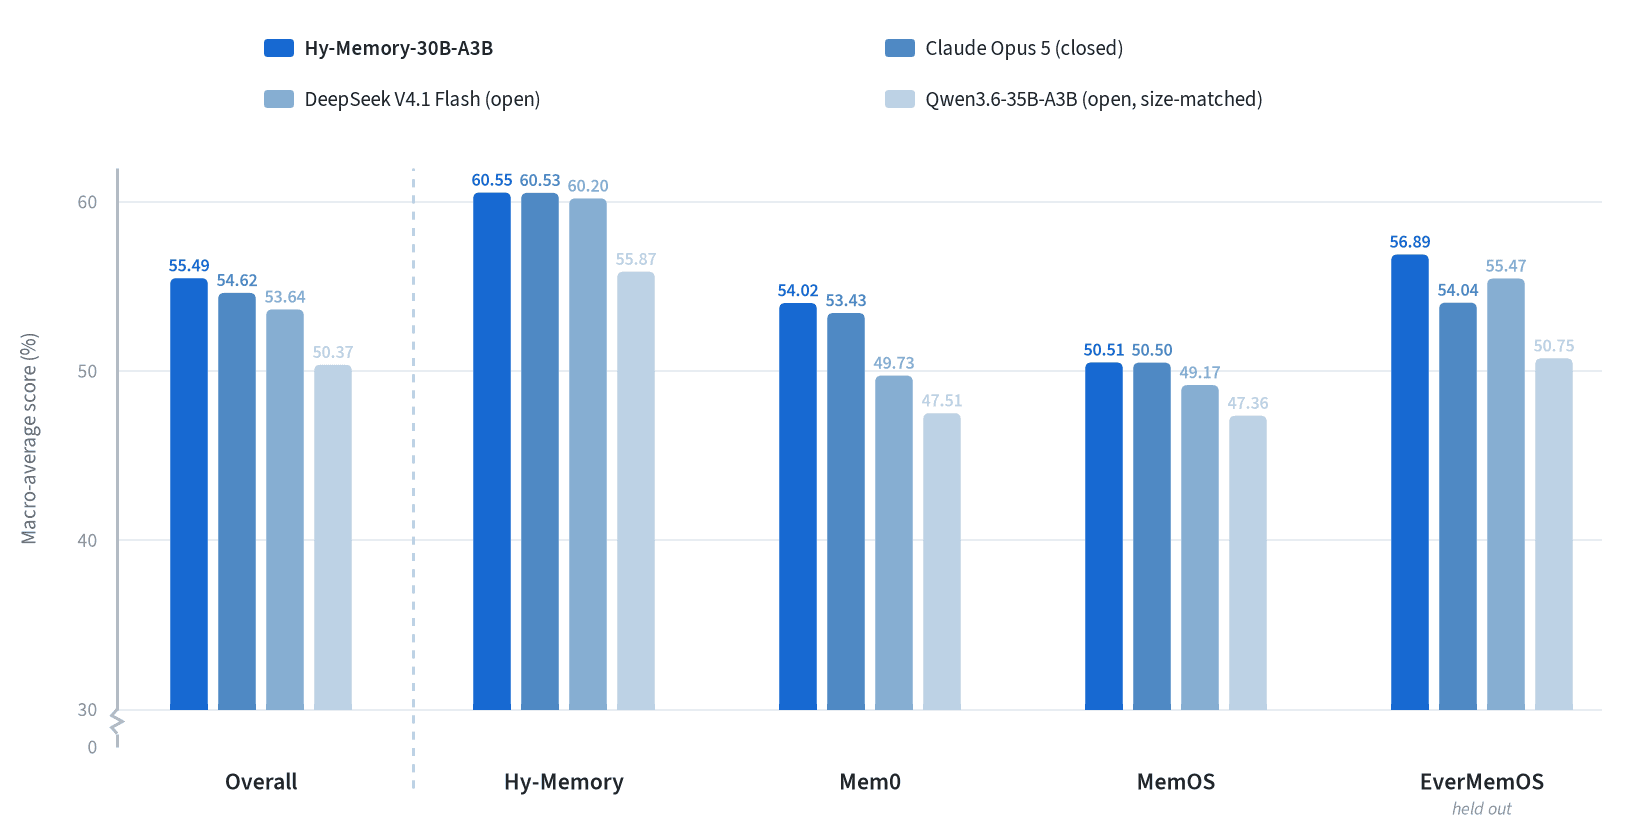
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
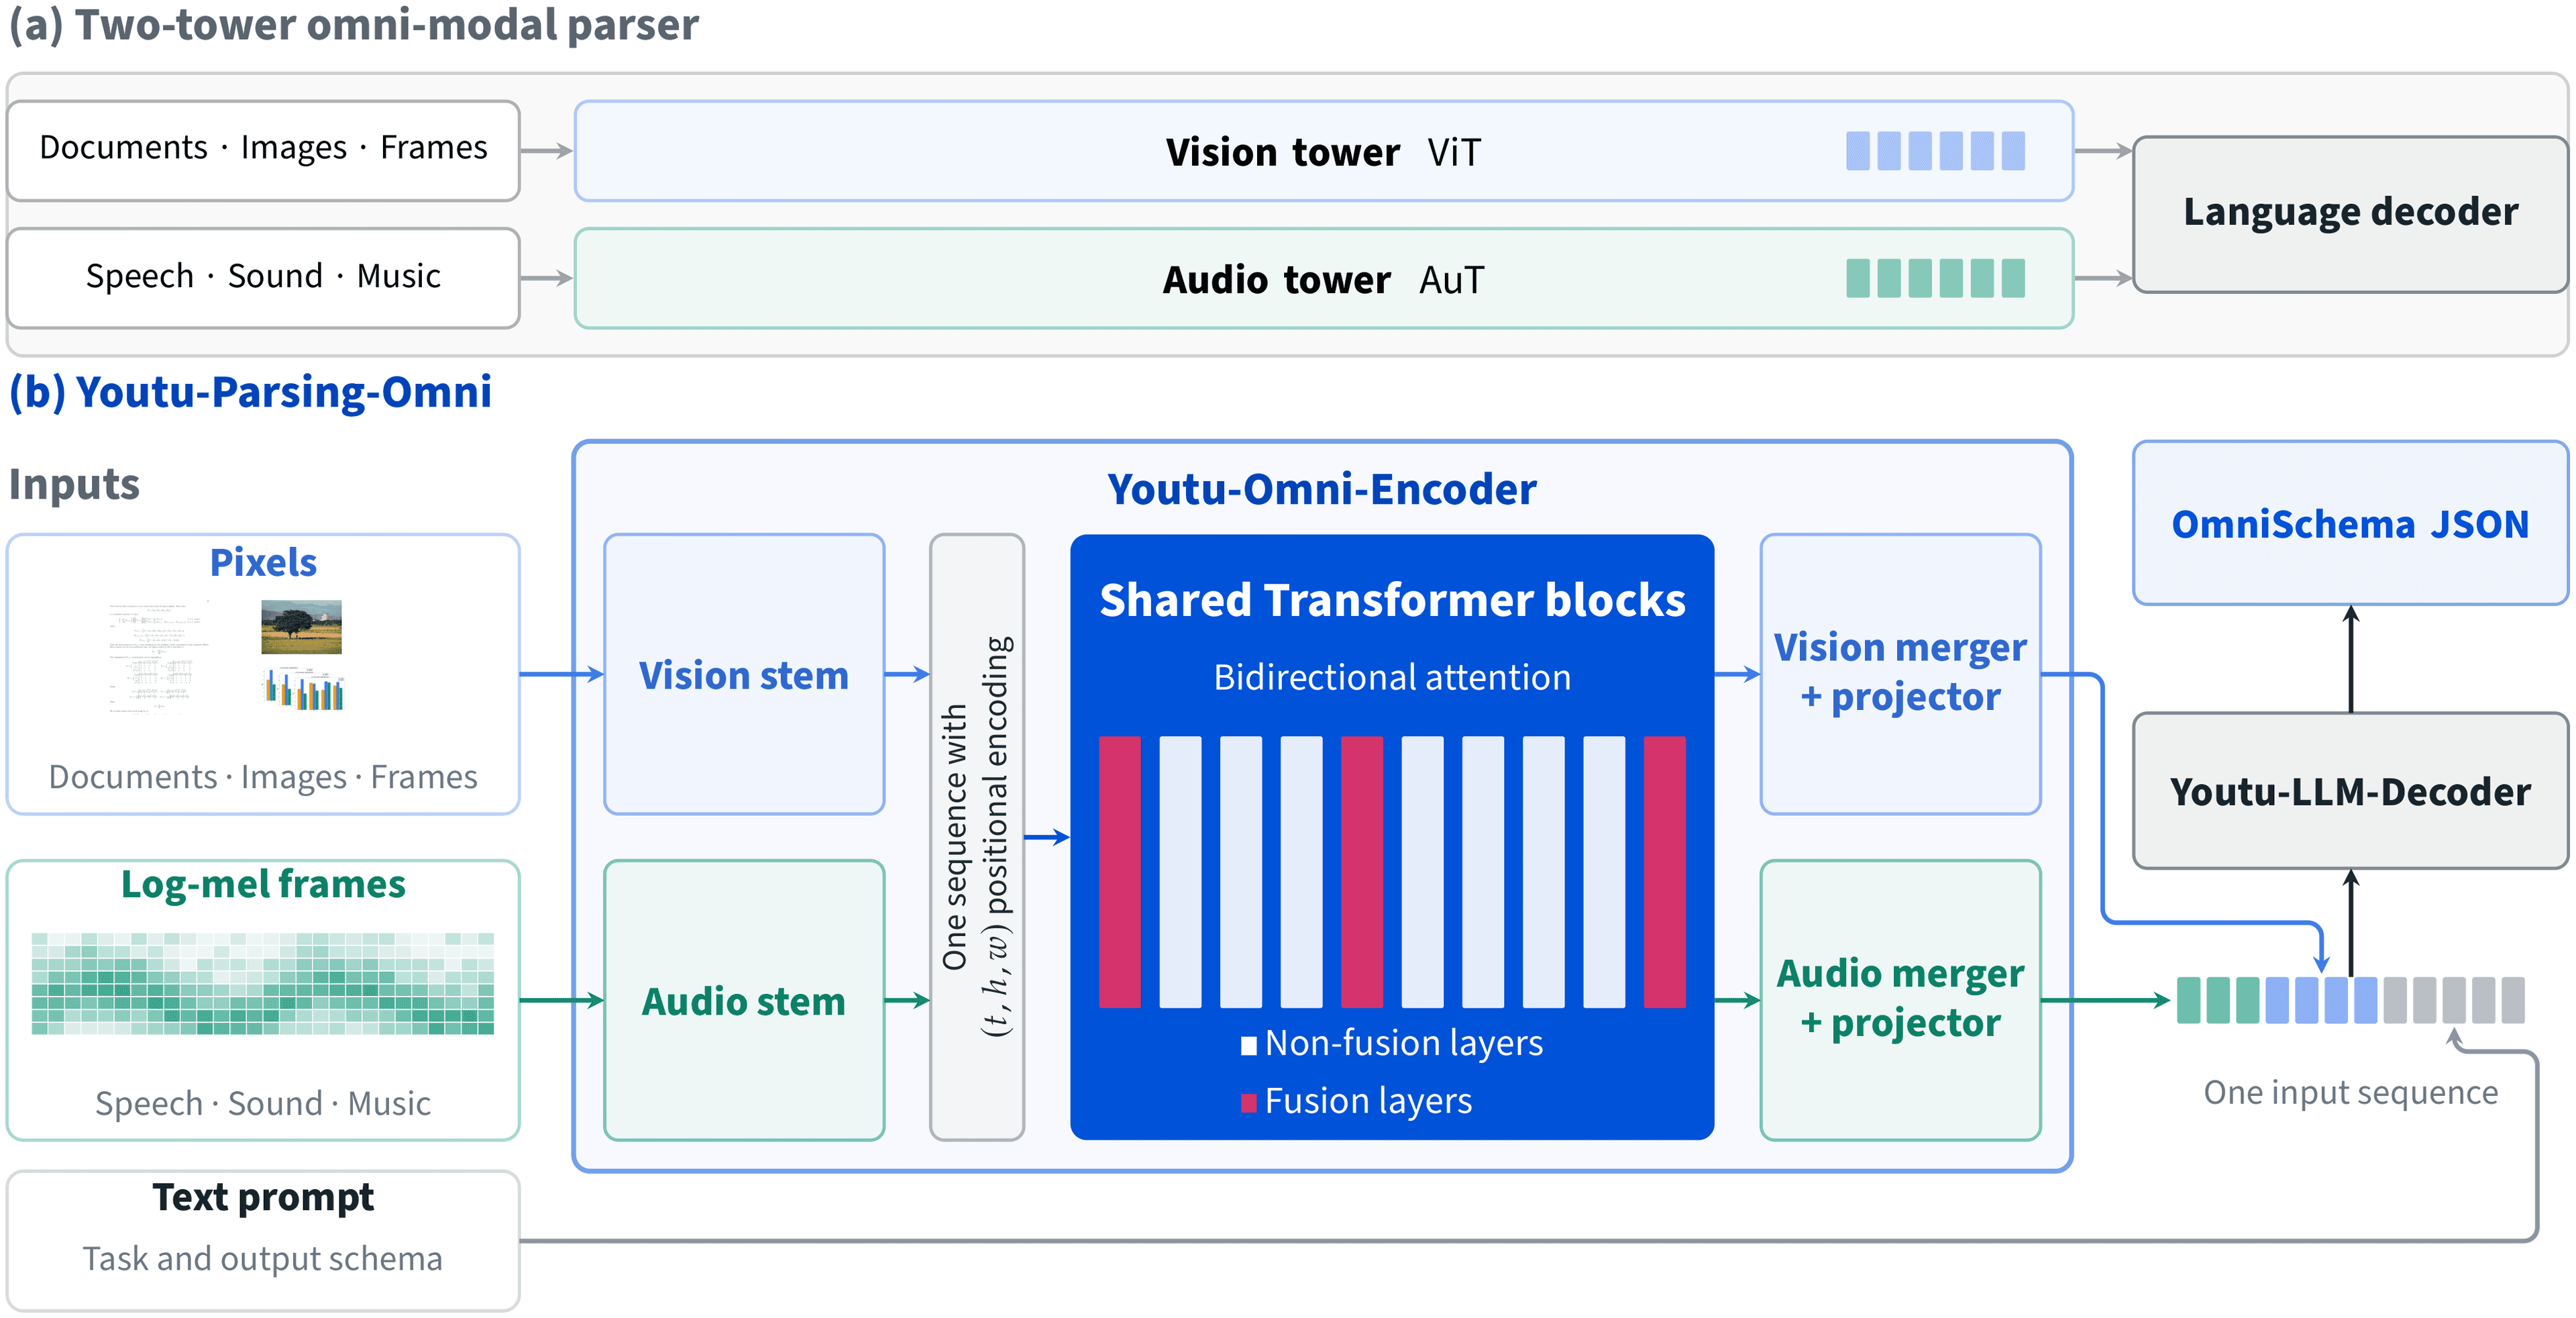
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.