ByteDance Releases Lynx for Identity-Preserving Video
The new model from the TikTok parent company generates short video clips that maintain a person's likeness from a single reference image.
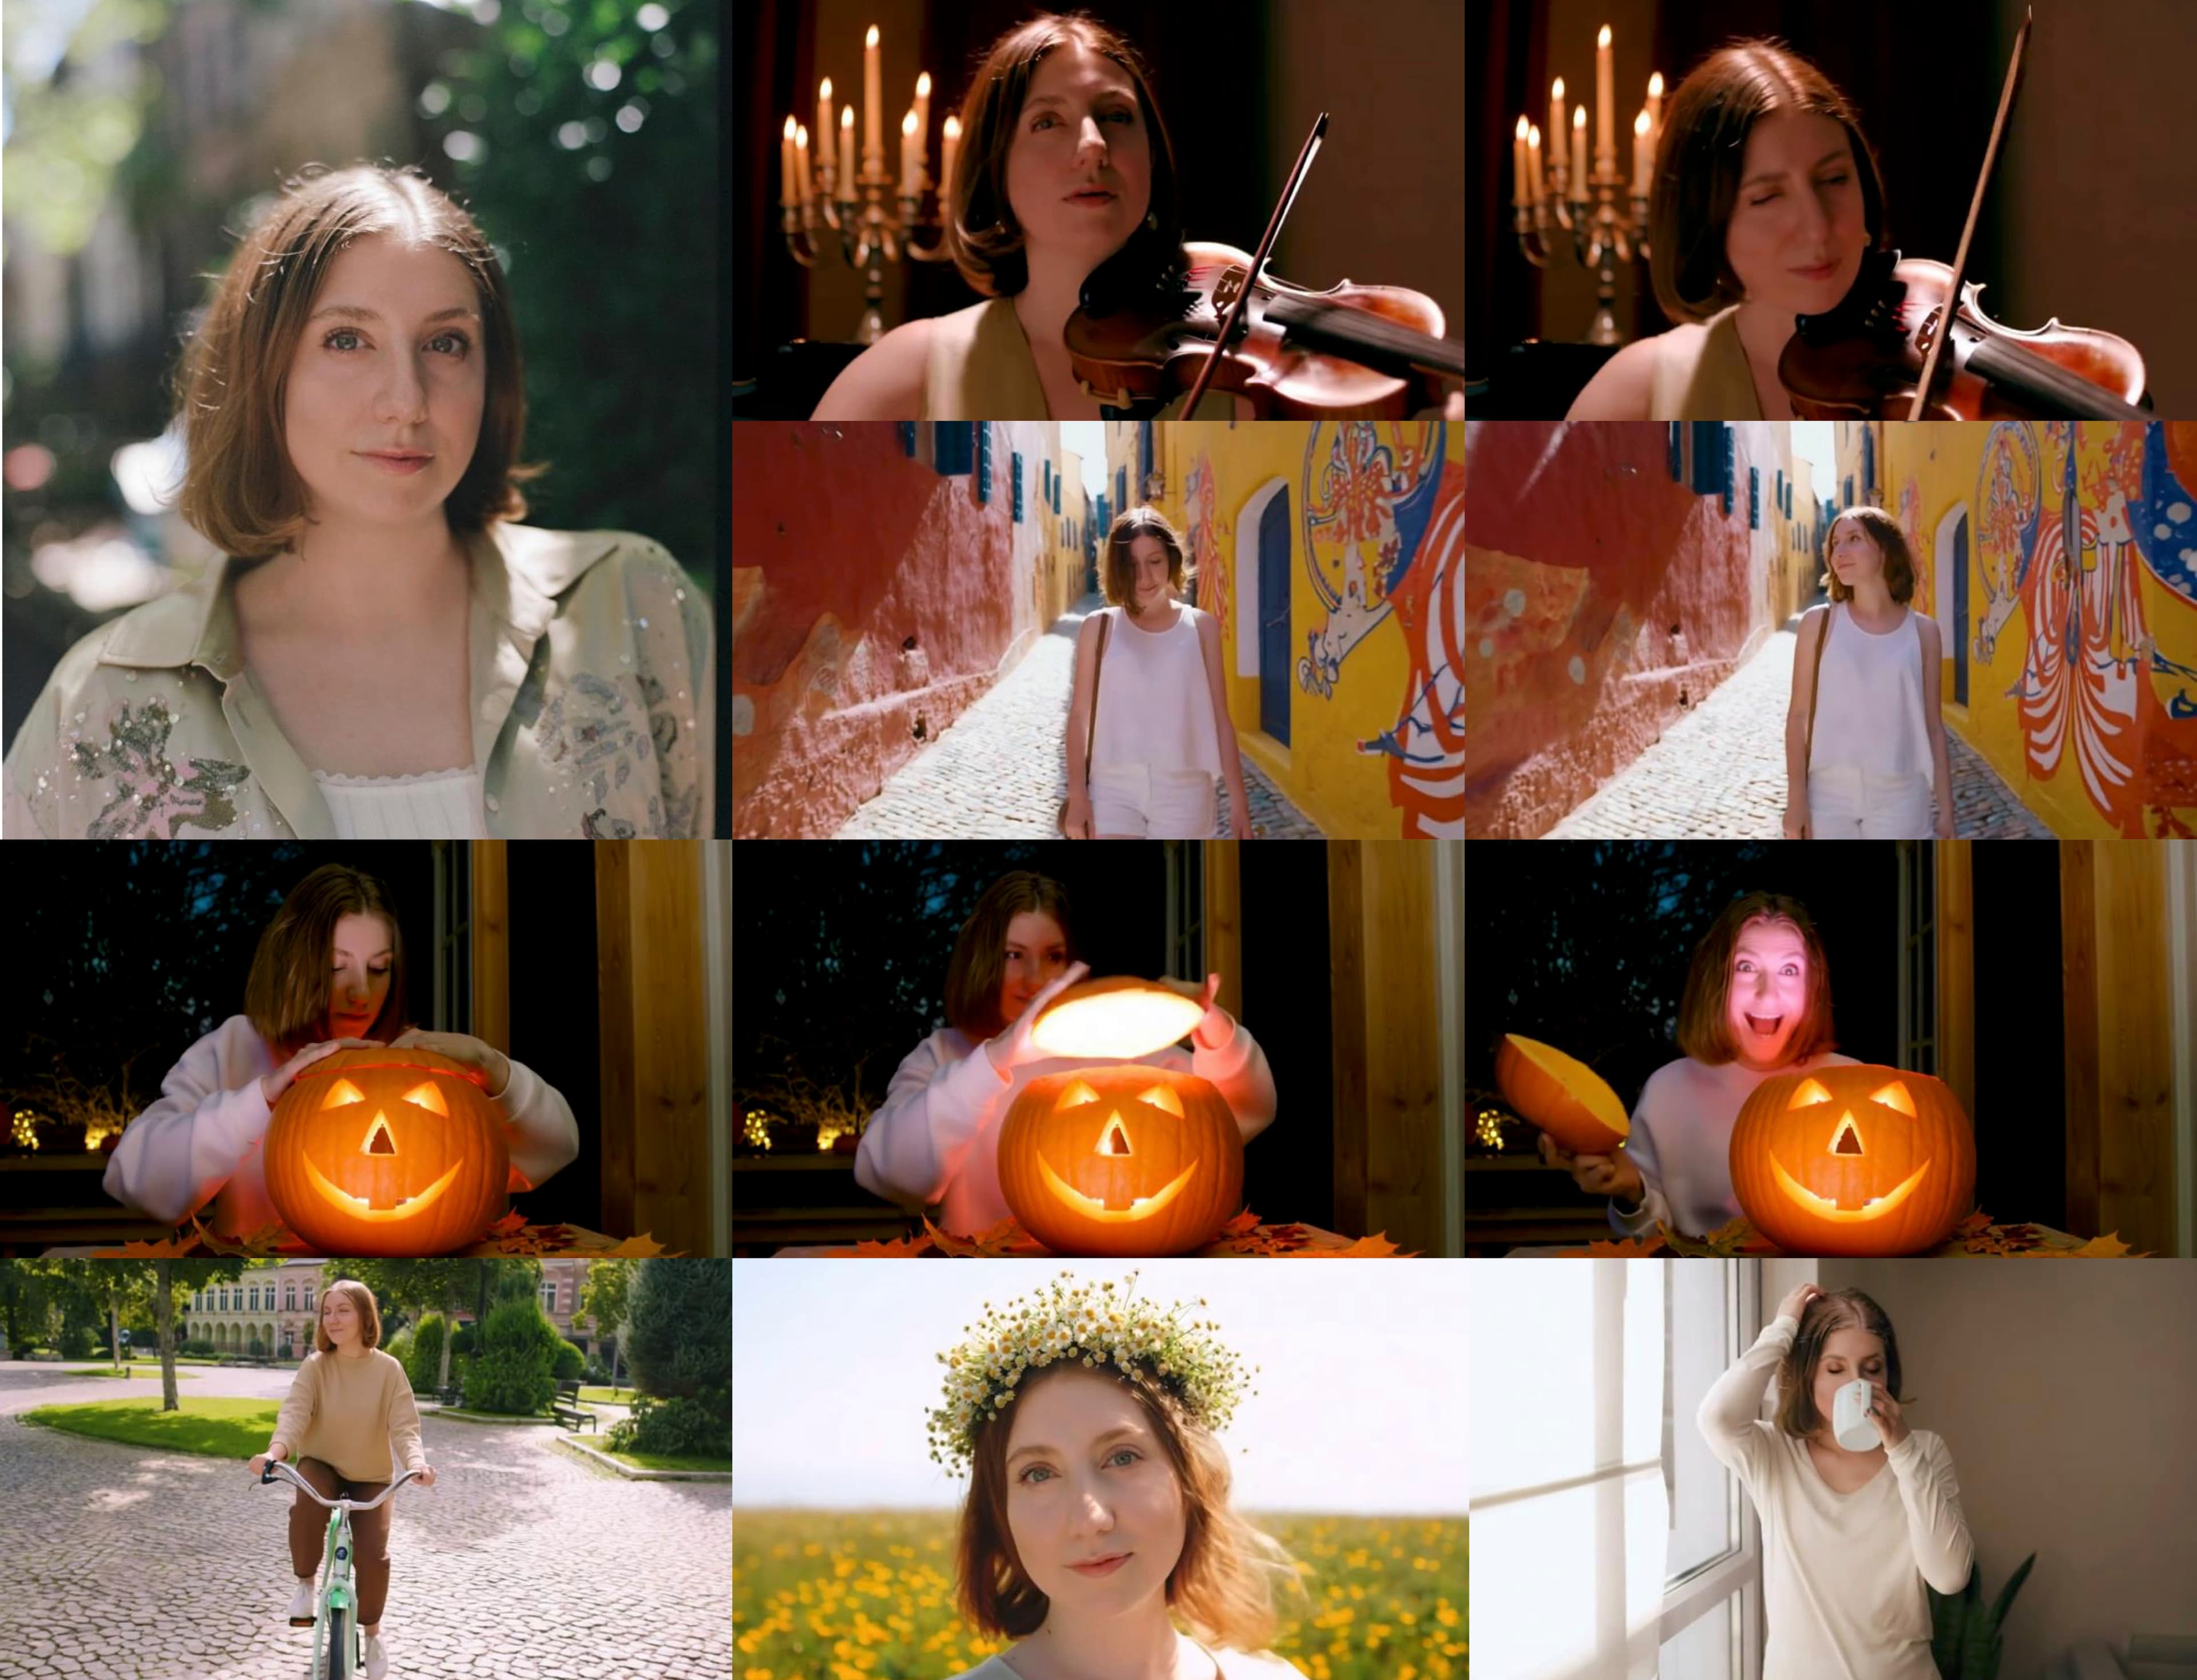
ByteDance has released Lynx, a new open-source model focused on generating personalized video clips. Published under a permissive Apache 2.0 license, Lynx is designed to create short videos that preserve the identity of a subject from a single reference photo.
The model works by combining a detailed reference image of a person with a text prompt describing a desired action or scene. Built upon the Wan2.1-T2V-14B text-to-video foundation, Lynx uses this information to animate the subject, aiming for consistent facial features and identity throughout the generated clip.
While many text-to-video models can generate generic human figures, Lynx's specific focus on subject consistency is notable. This release provides researchers and developers with an open tool for exploring applications in personalized content creation and digital avatars. The model and code are available on Hugging Face for experimentation.
Sources
- Visit
ByteDance/lynx
Hugging Face
More from ByteDance
All ByteDance releases →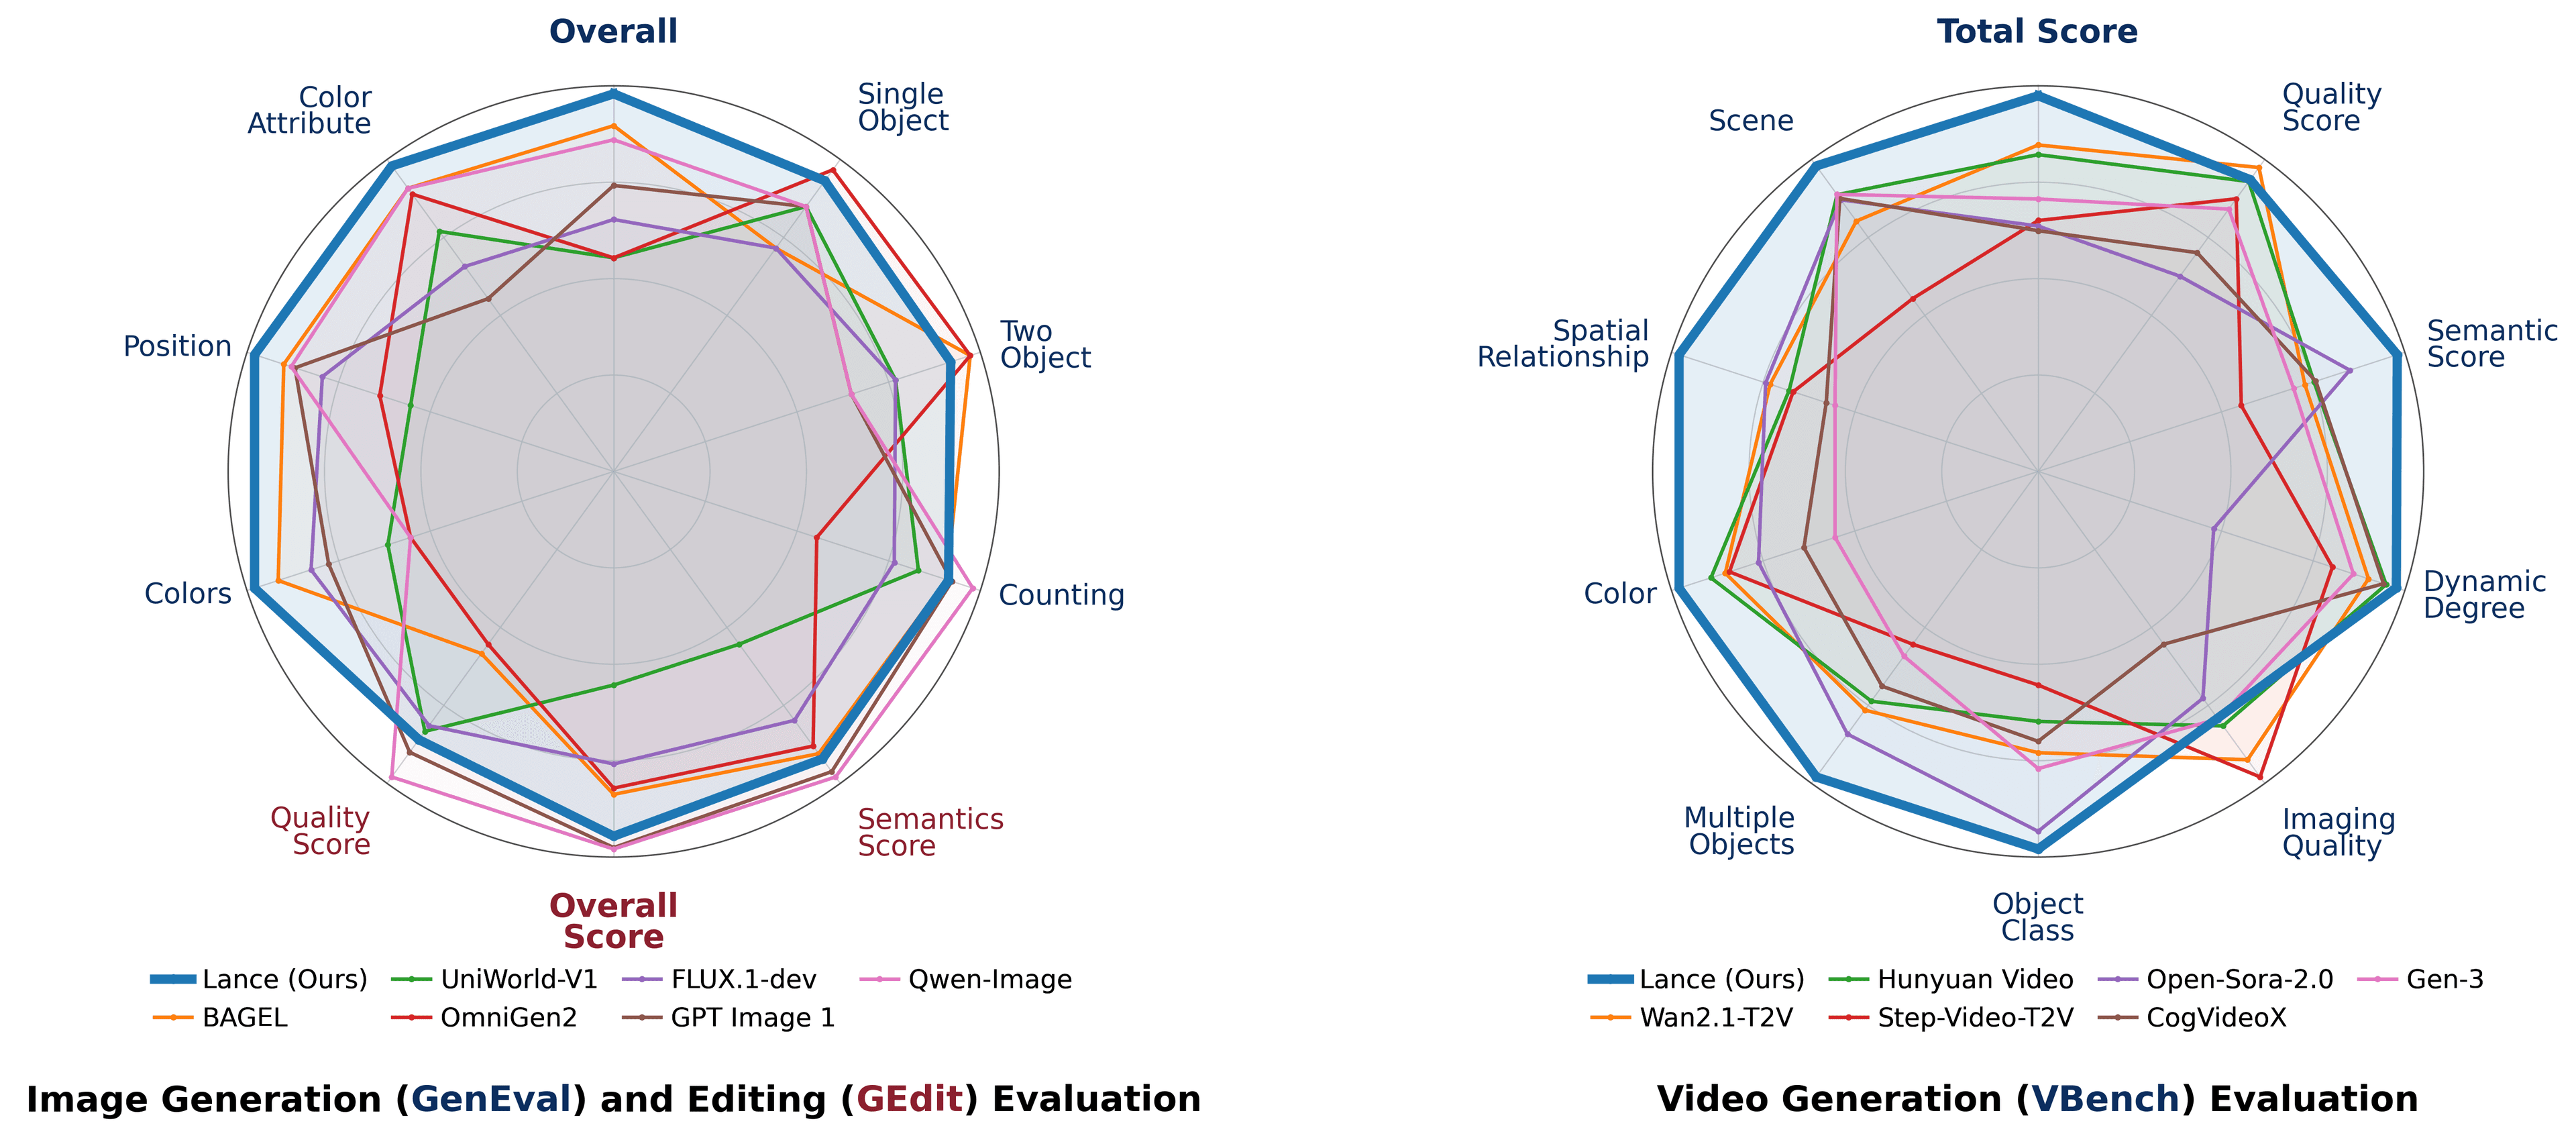
ByteDance Releases Lance, a Unified Generative AI Model
The 3-billion-parameter model handles image and video generation, editing, and understanding from a single set of weights under a permissive license.
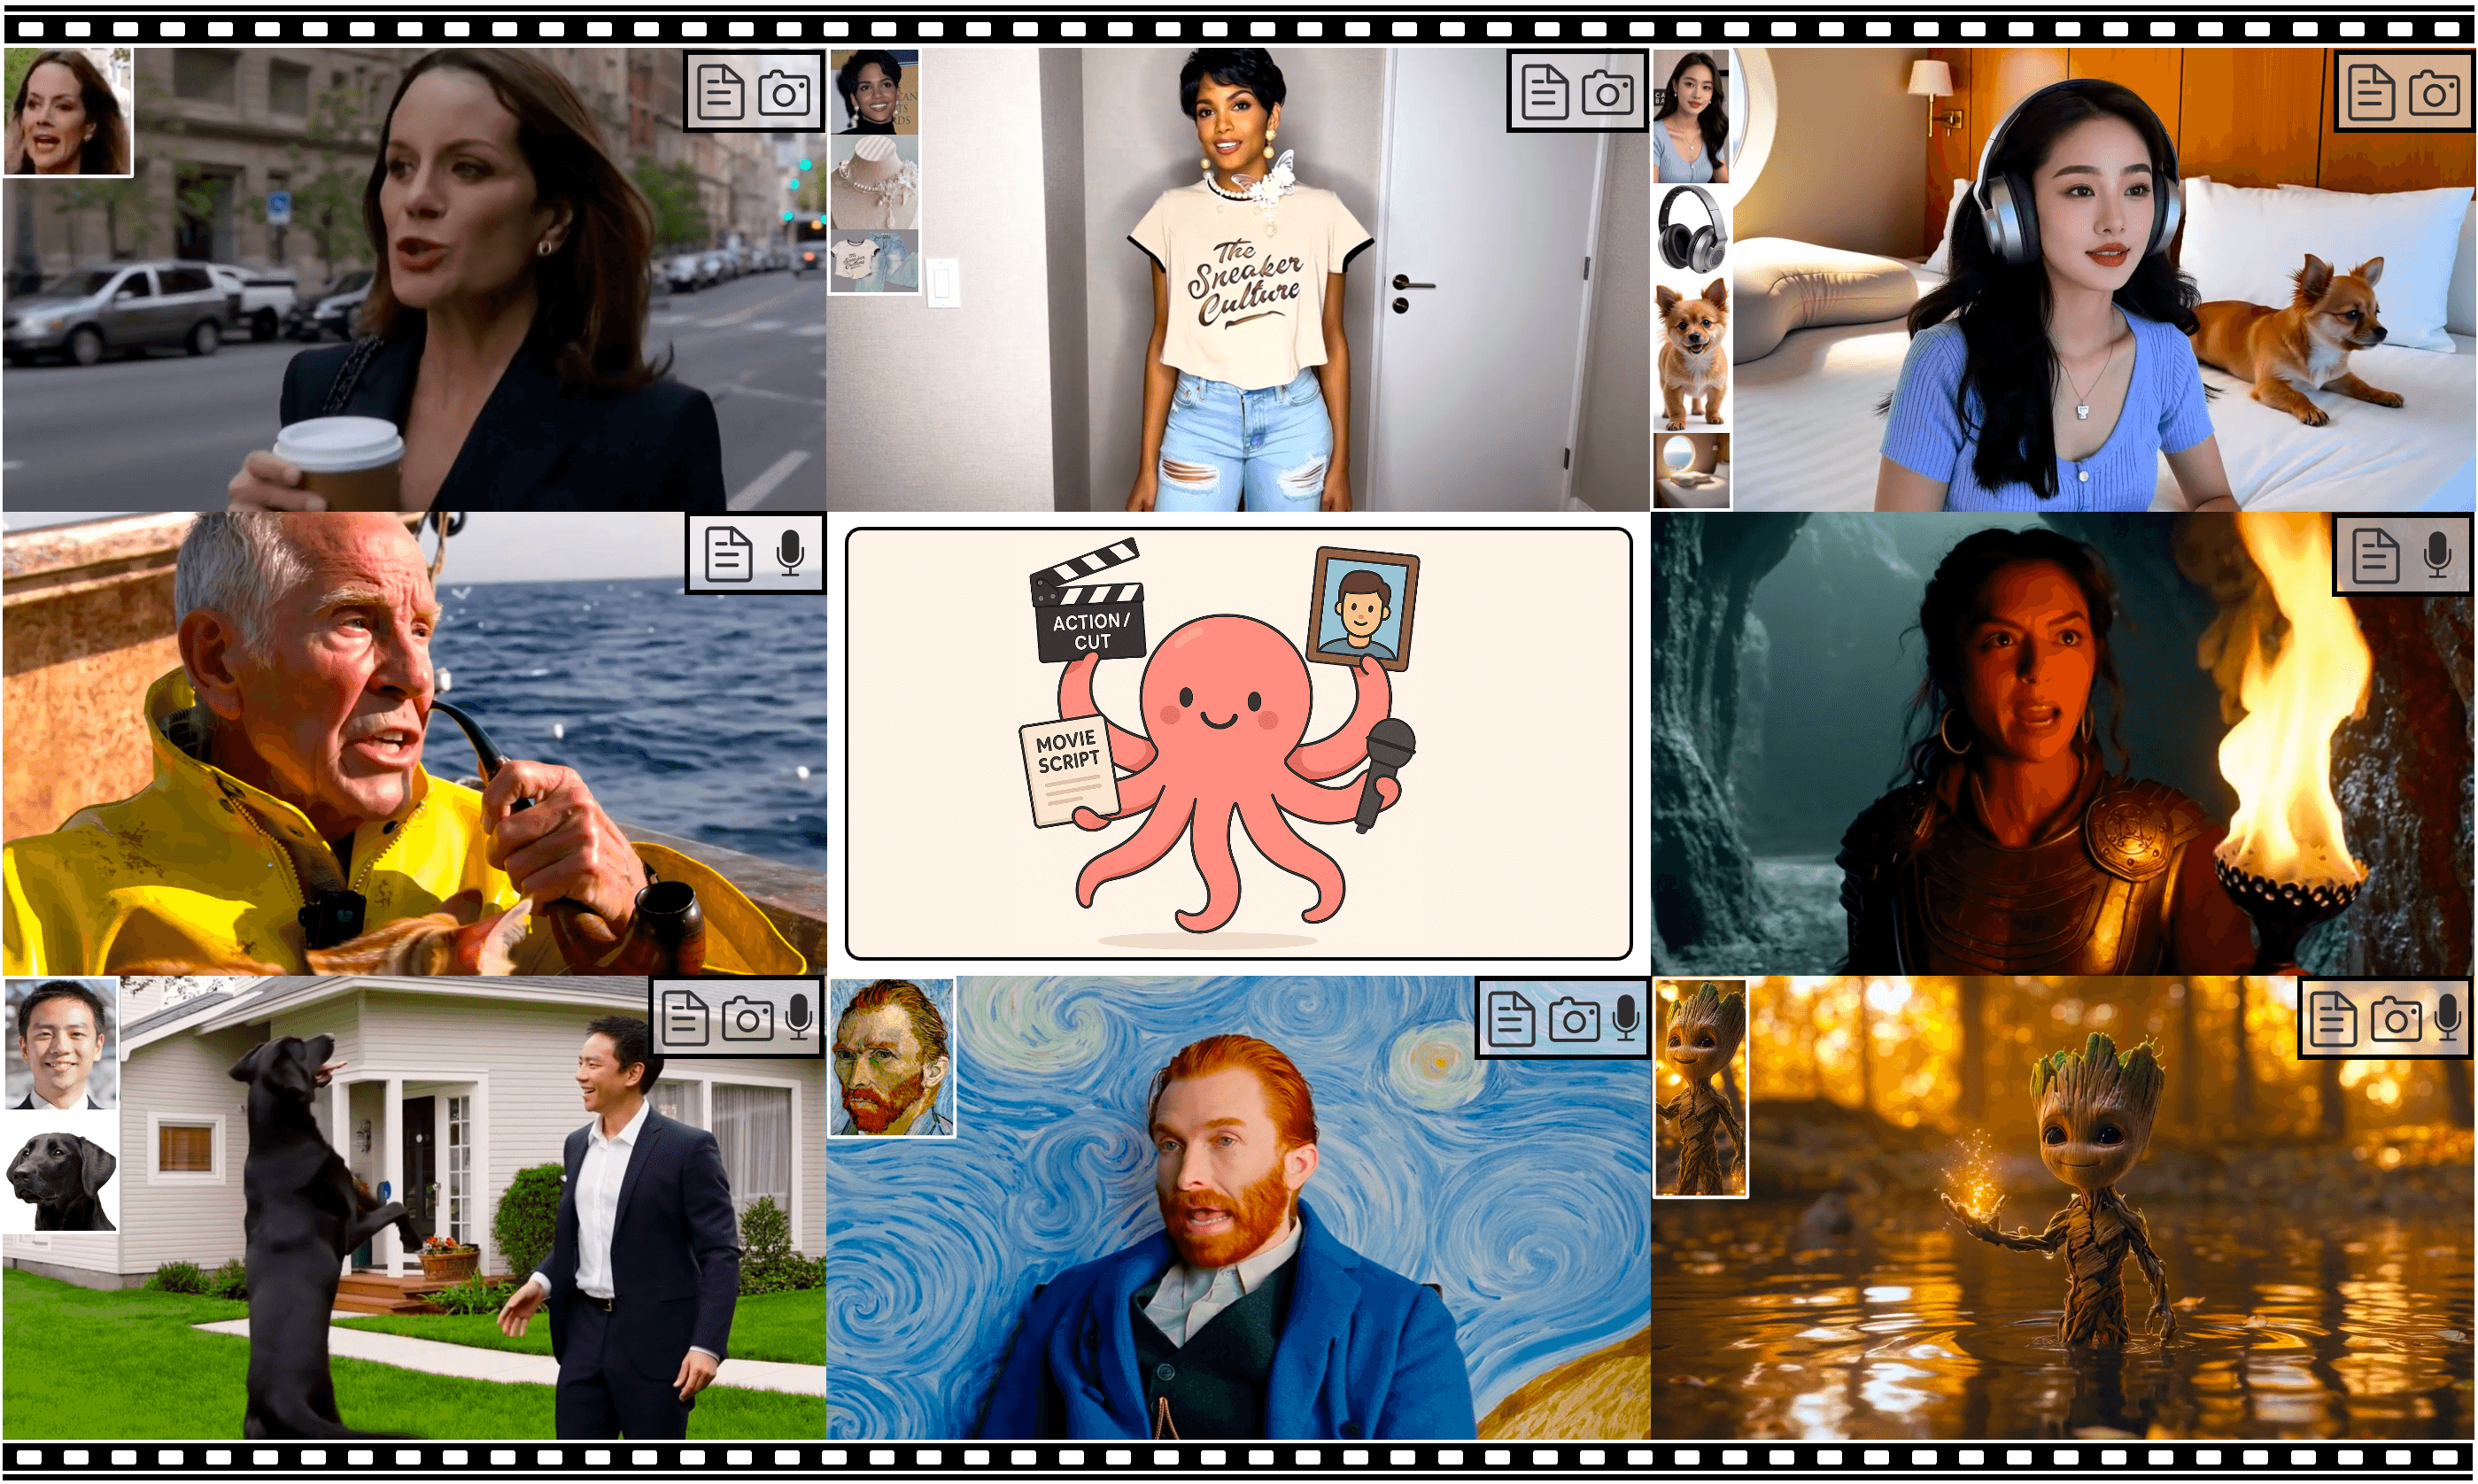
ByteDance Releases HuMo for Human Video Generation
The new open-source model specializes in creating realistic videos of people, separating appearance from motion for greater control.
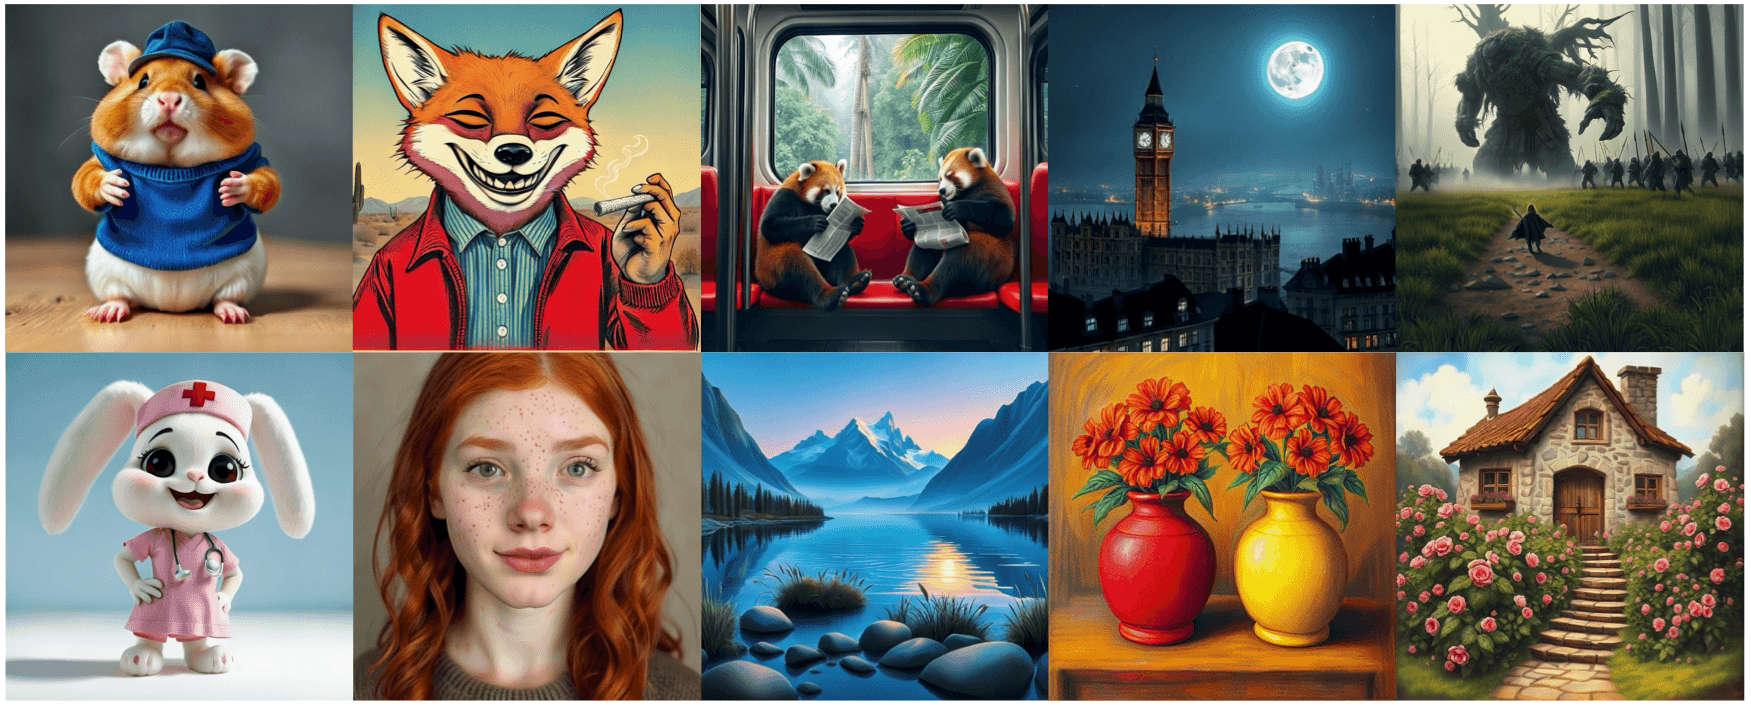
ByteDance Releases Tar-7B for 'Any-to-Any' Multimodality
The new 7-billion-parameter model from the company's SEED team can process and generate a mix of text, images, audio, and video in a single unified framework.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
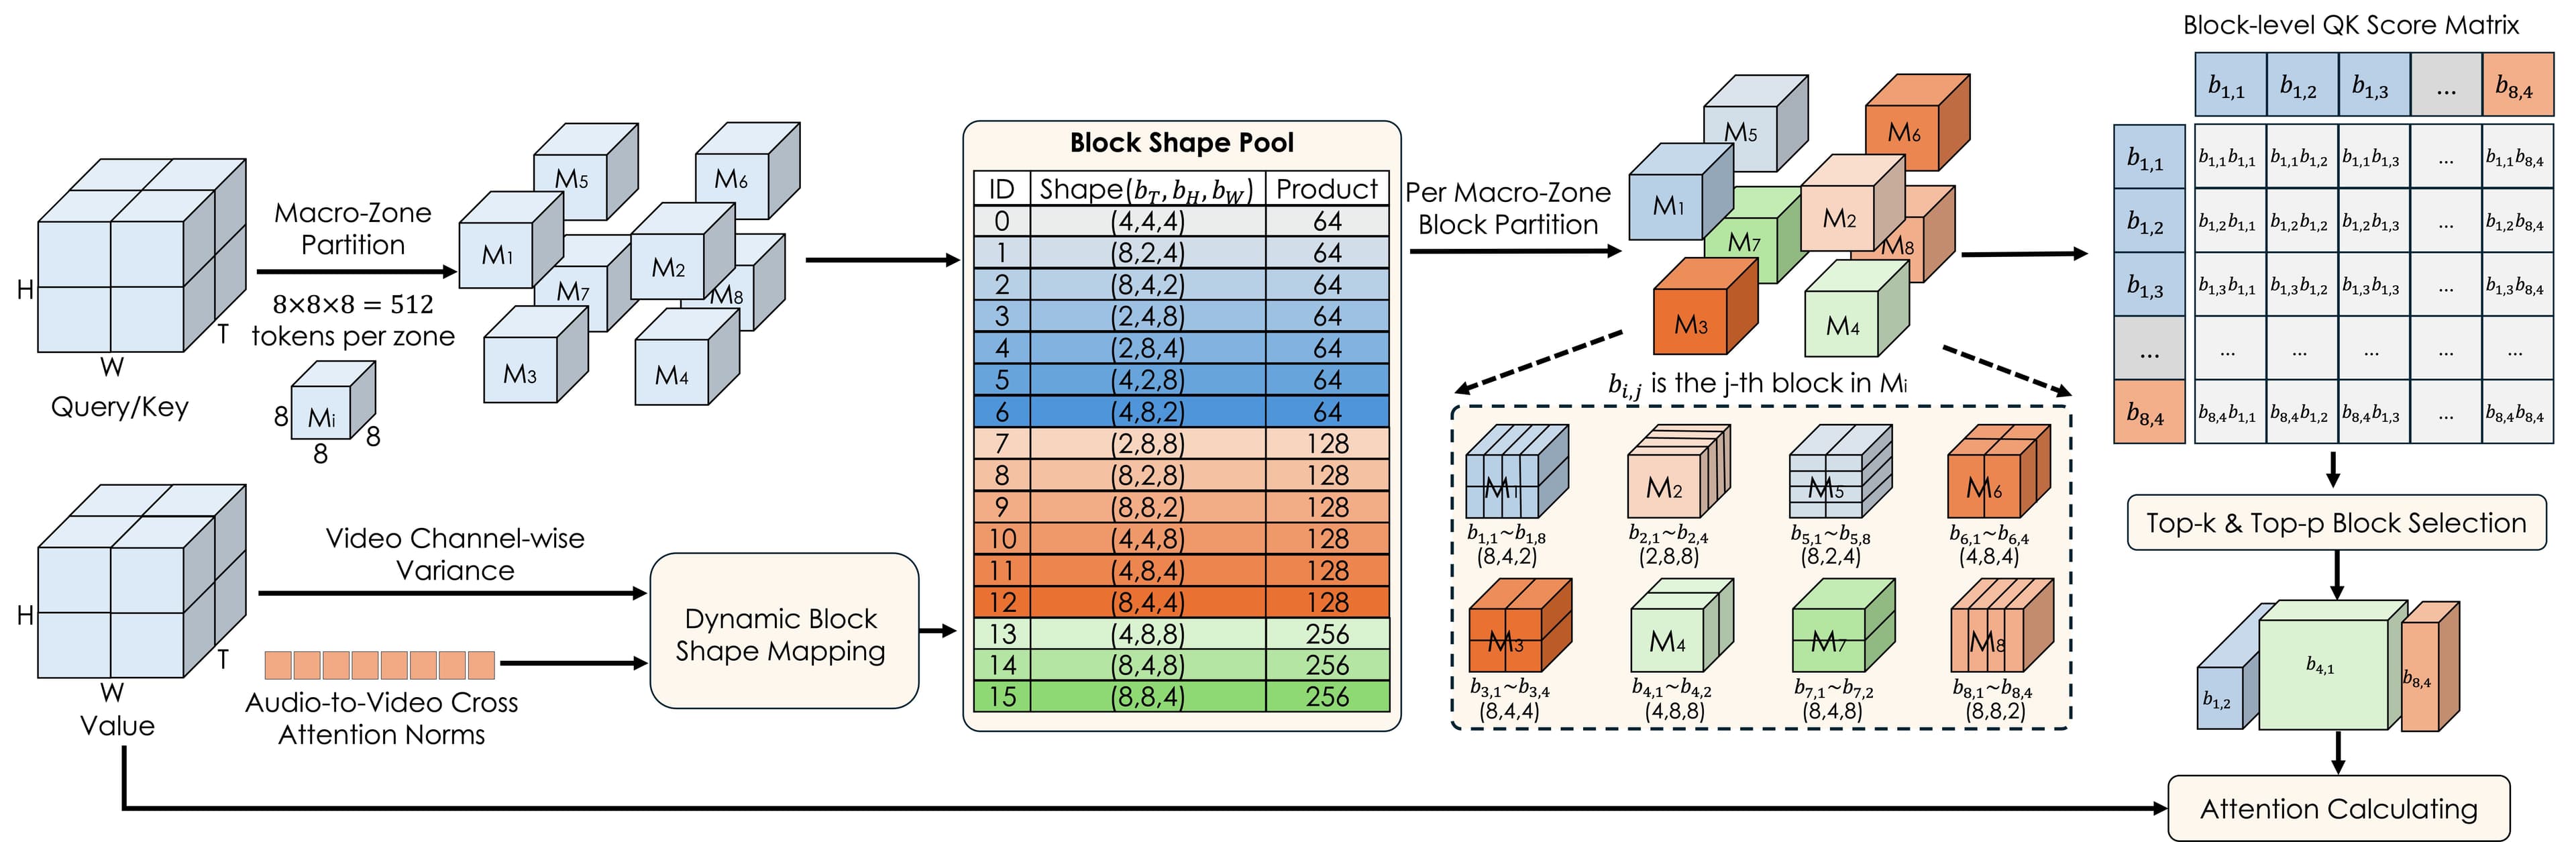
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.