ByteDance Releases HuMo for Human Video Generation
The new open-source model specializes in creating realistic videos of people, separating appearance from motion for greater control.
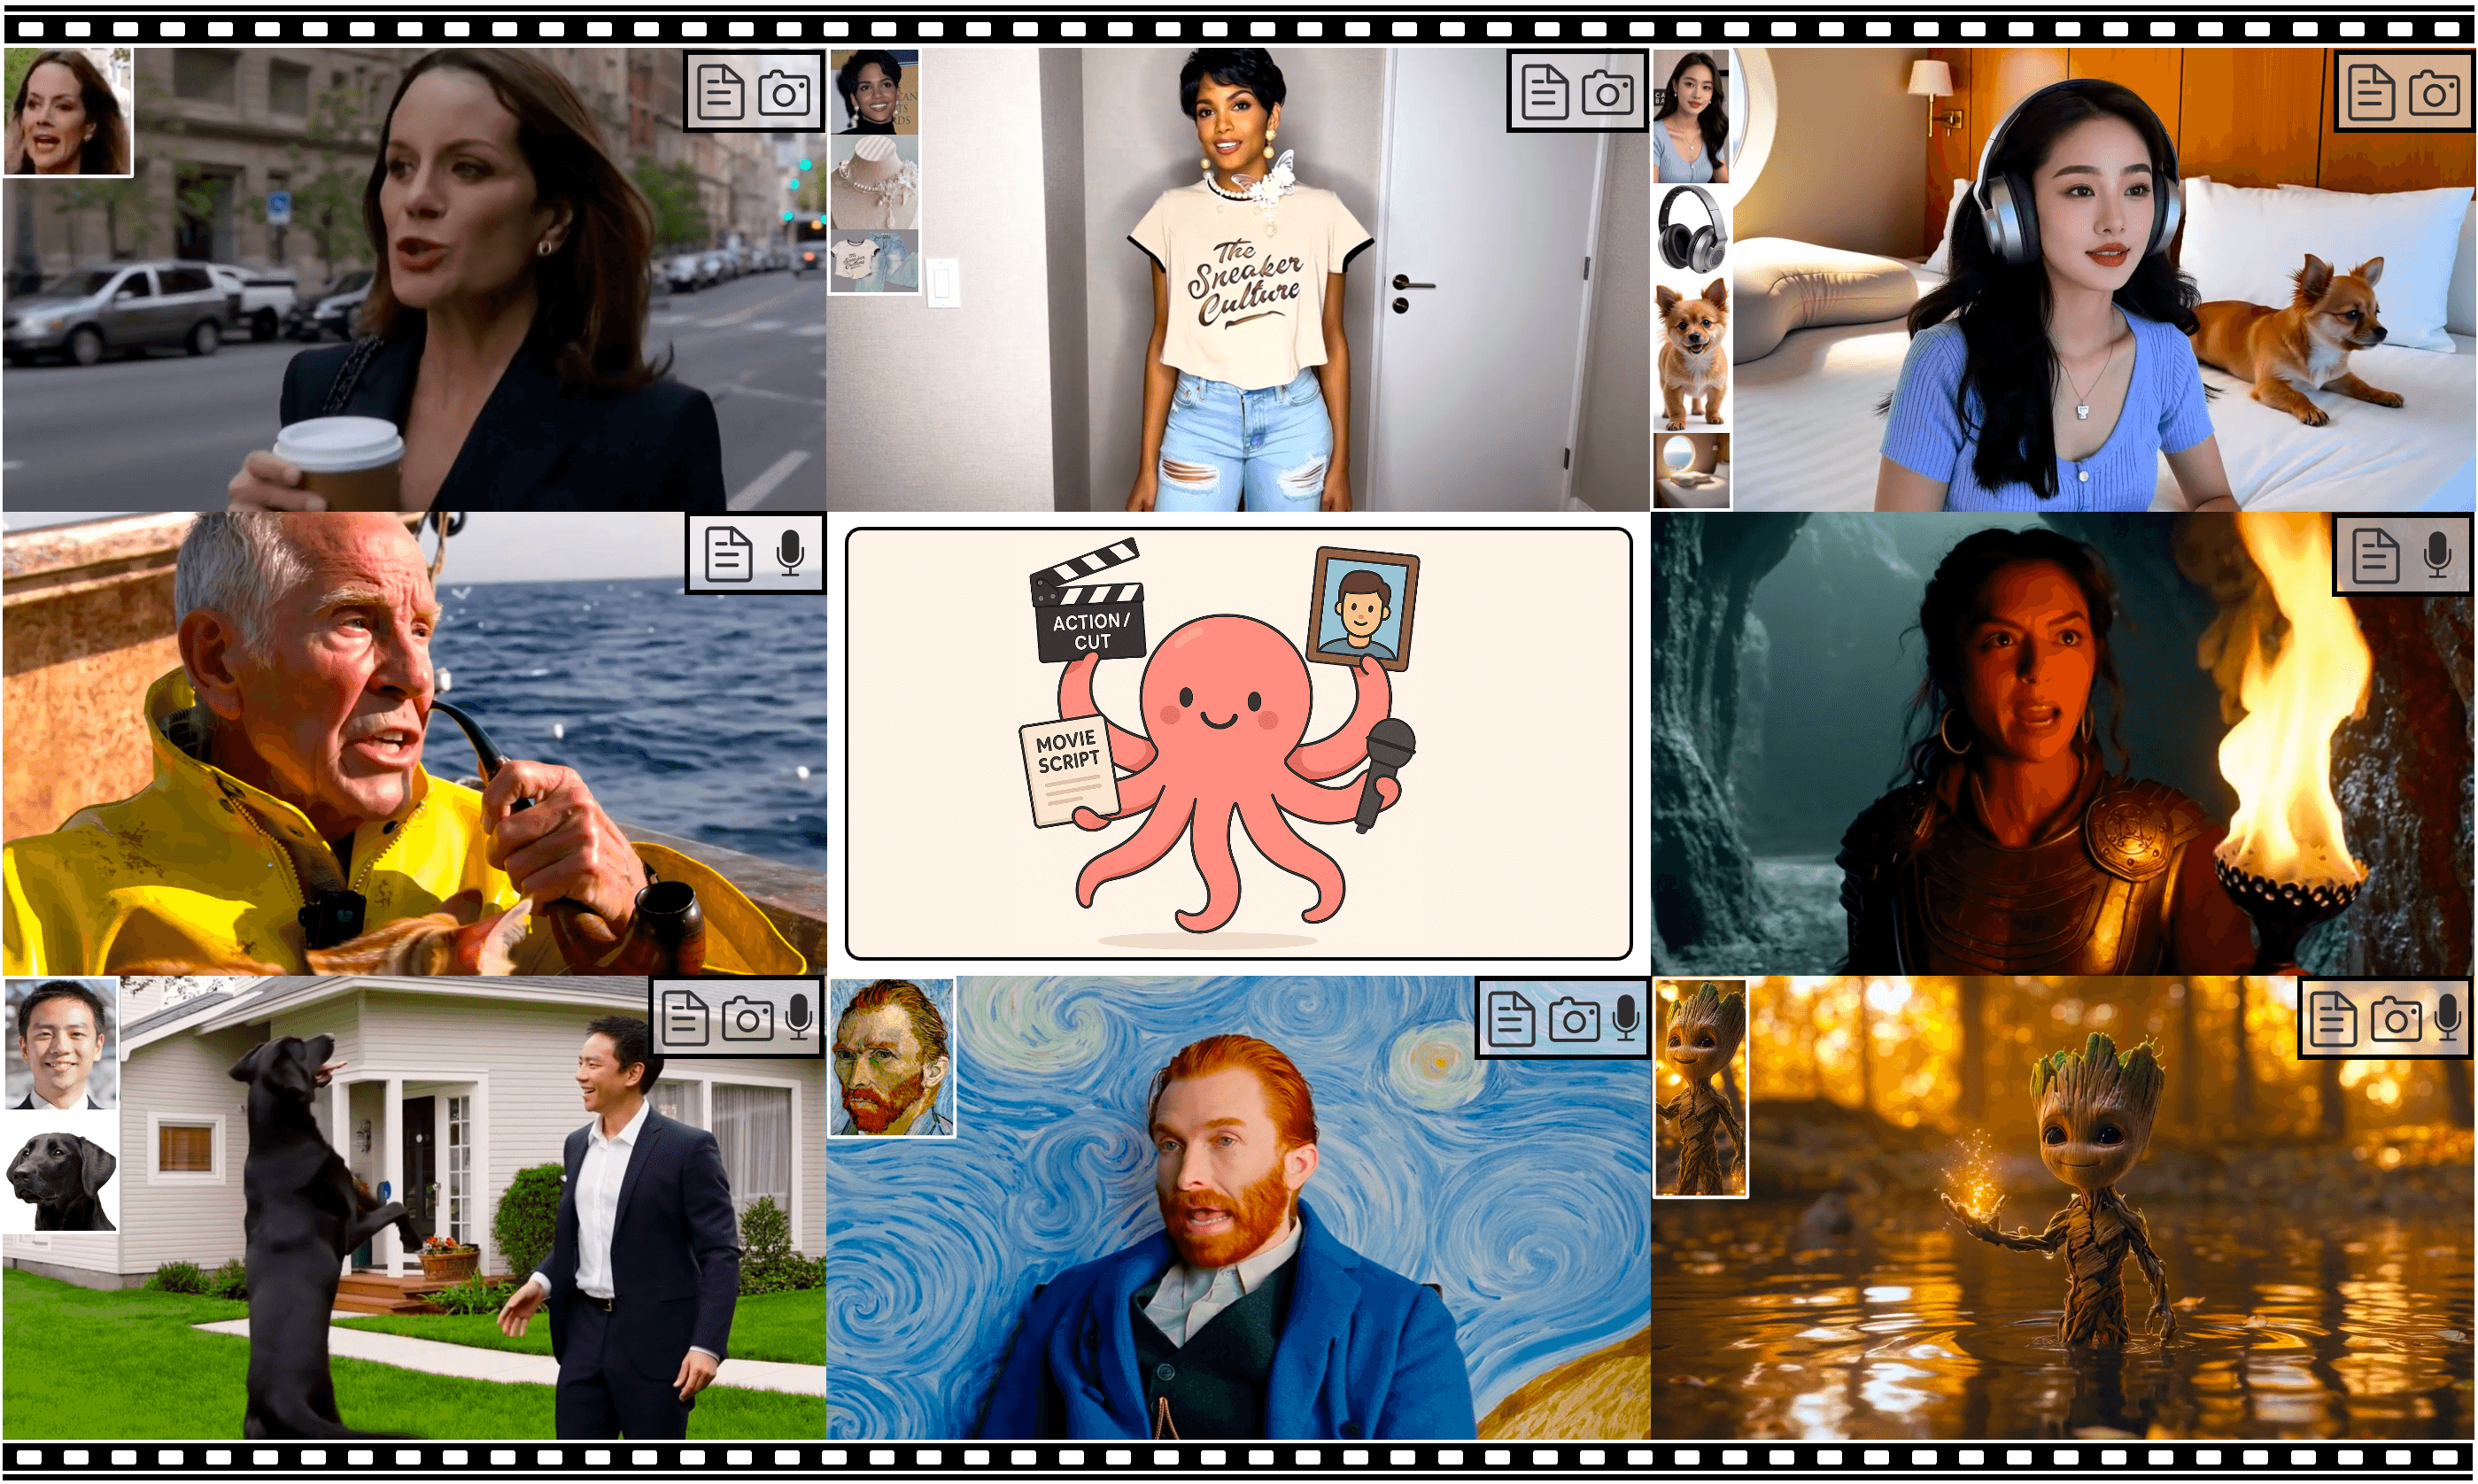
ByteDance Research has released HuMo, an open-source model focused on a notoriously difficult task in AI: generating realistic videos of humans. The model can create short video clips from either a text description or a reference image, marking a new entry in the competitive field of AI video synthesis. The weights and code are available on Hugging Face under a permissive Apache 2.0 license.
A Focus on Motion and Anatomy
Unlike general-purpose video models, HuMo is specifically designed to understand and render the human form in motion. According to the project's documentation, it uses a diffusion-based architecture that separates a subject's appearance from their movement. A "human prior encoder" helps maintain anatomical consistency, while a "motion-guidance module" allows for more precise control over the action in the generated clip.
This specialized approach enables several key capabilities:
- Text-to-Video: Generating a video of a person performing an action described in a prompt.
- Image-to-Video: Animating a person from a single still photograph.
- Motion Control: Guiding the generation process with specific motion sequences for more directed outputs.
The release is significant because generating plausible human movement without uncanny or distorted results remains a major hurdle for AI video. By focusing on this specific domain and releasing the model openly, ByteDance provides researchers and creators with a powerful new tool. The Apache 2.0 license further encourages experimentation and potential integration into commercial applications, from creative software to virtual character animation.
Sources
- Visit
bytedance-research/HuMo
Hugging Face
More from ByteDance
All ByteDance releases →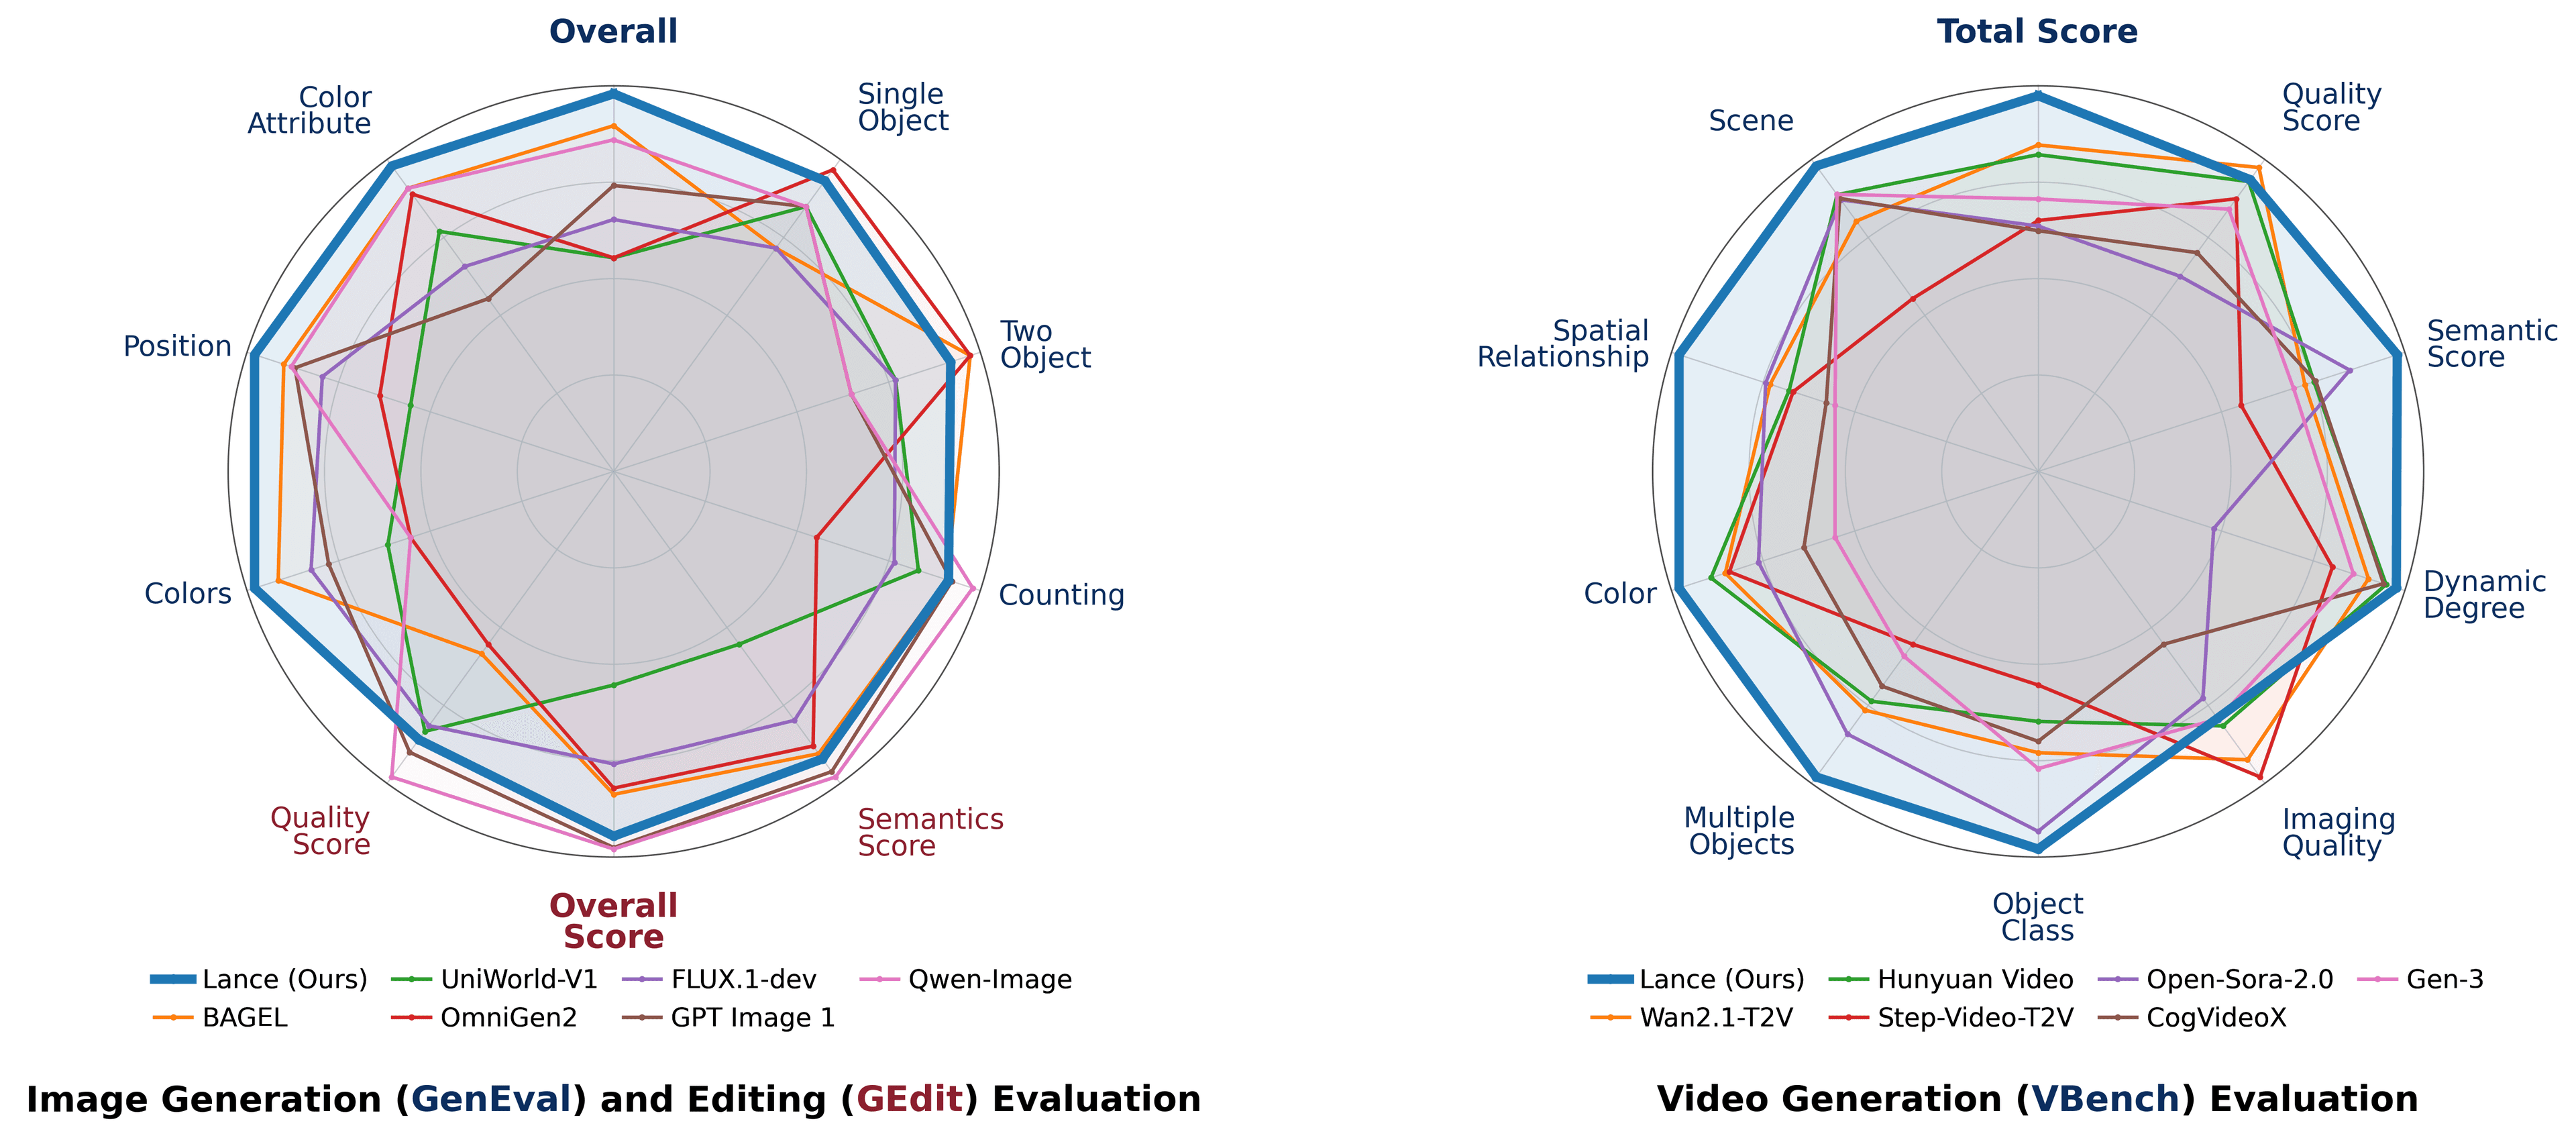
ByteDance Releases Lance, a Unified Generative AI Model
The 3-billion-parameter model handles image and video generation, editing, and understanding from a single set of weights under a permissive license.

ByteDance Releases Lynx for Identity-Preserving Video
The new model from the TikTok parent company generates short video clips that maintain a person's likeness from a single reference image.
ByteDance Releases Tar-7B for 'Any-to-Any' Multimodality
The new 7-billion-parameter model from the company's SEED team can process and generate a mix of text, images, audio, and video in a single unified framework.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
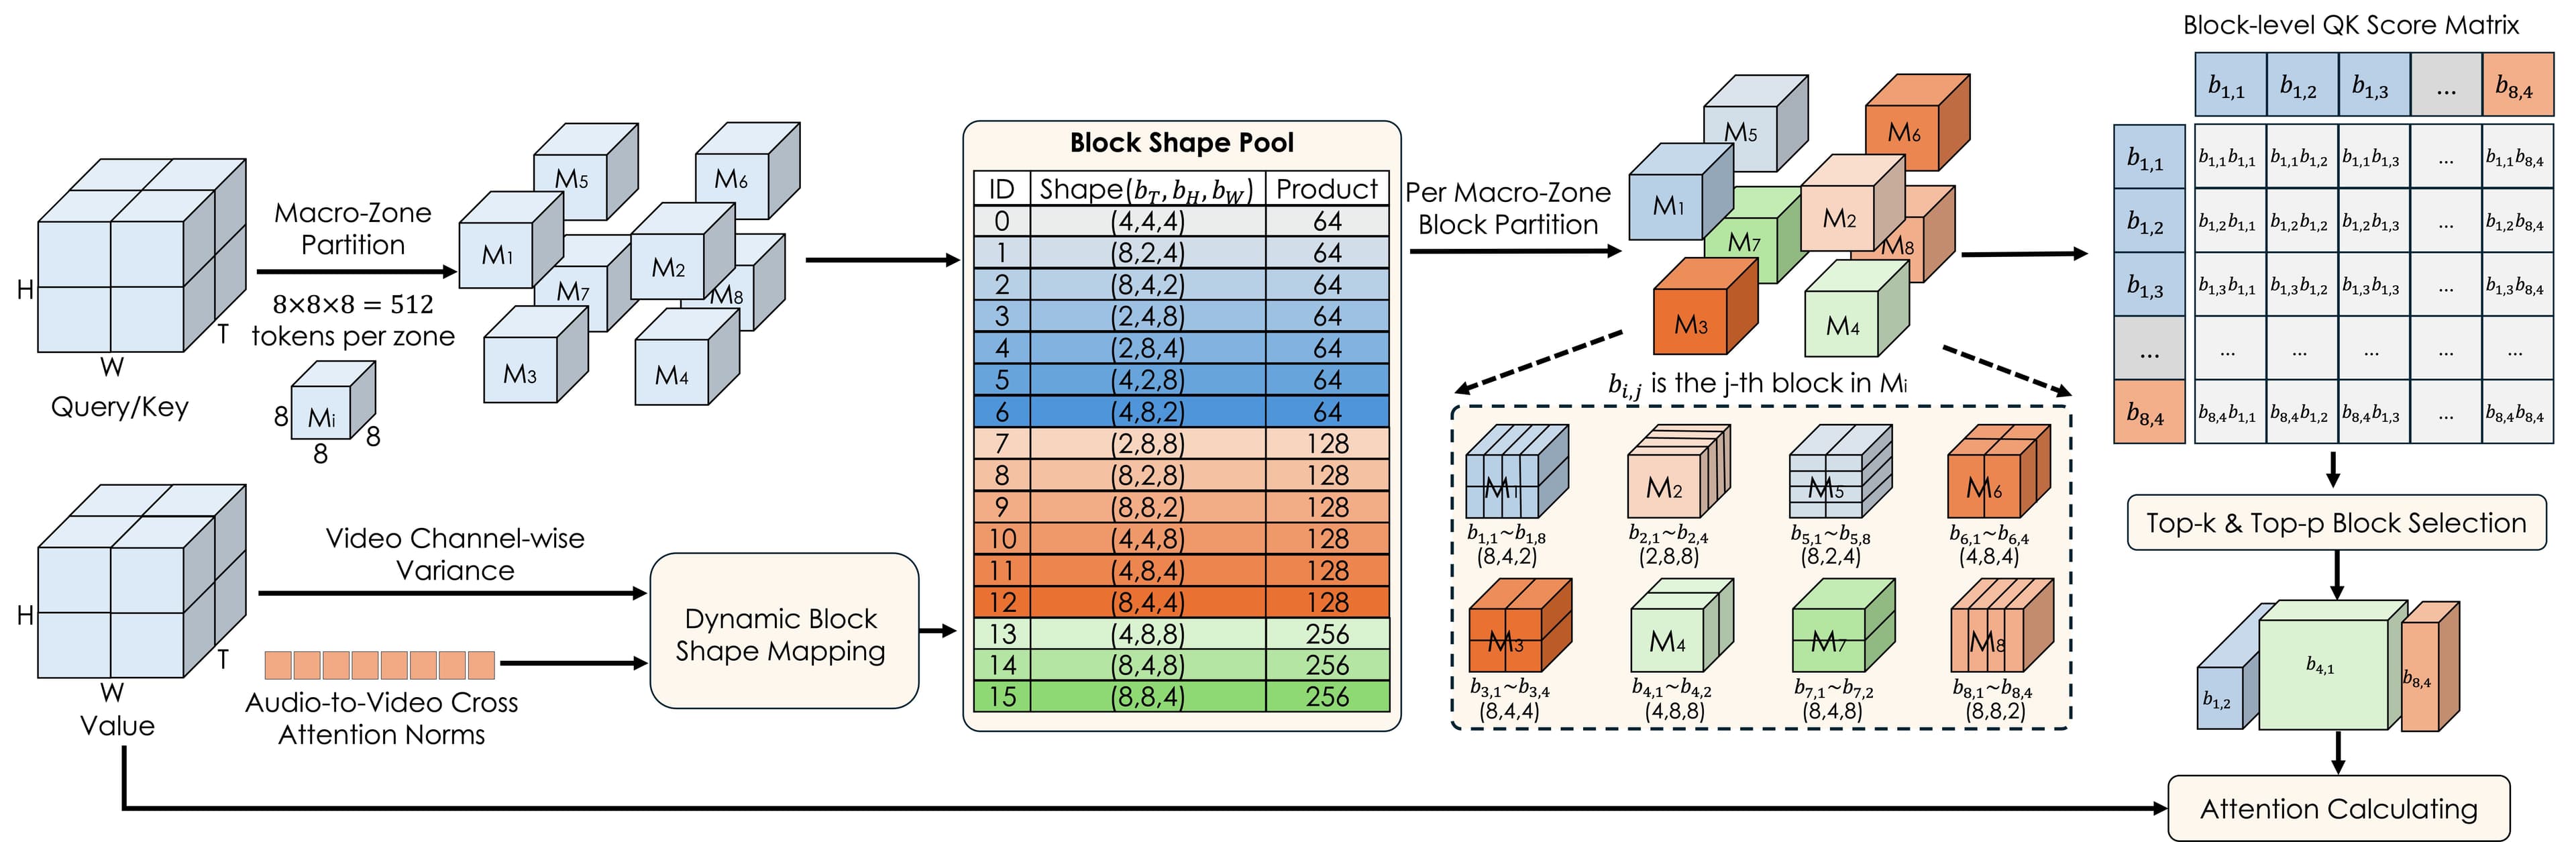
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.