Tencent Releases Wan2.2, a 14B MoE Video Model
The new Apache 2.0-licensed generator uses a Mixture-of-Experts architecture and is available in the popular Diffusers library format for easier integration.

Tencent has released Wan2.2, a powerful new text-to-video model, making it available to the public on the Hugging Face Hub. The model, officially named Wan2.2-T2V-A14B, stands out with its 14-billion-parameter scale and a sophisticated architecture, all provided under a permissive Apache 2.0 license.
An Efficient Architecture
At its core, Wan2.2 employs a Mixture-of-Experts (MoE) design. This approach allows the model to be very large in terms of total parameters while only activating a fraction of them for any given task. The result is more computationally efficient inference compared to a dense model of similar size. Its release in the popular Diffusers library format also simplifies integration for developers and researchers looking to build on the technology.
This release marks another significant contribution to the open-source AI video landscape. By providing a large, advanced model with a permissive license, Tencent is fueling the innovation happening outside of closed, proprietary systems. It provides a new foundation for developers creating applications in media, entertainment, and beyond, adding more competition and diversity to the field of generative video.
Sources
- Visit
Wan-AI/Wan2.2-T2V-A14B-Diffusers
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
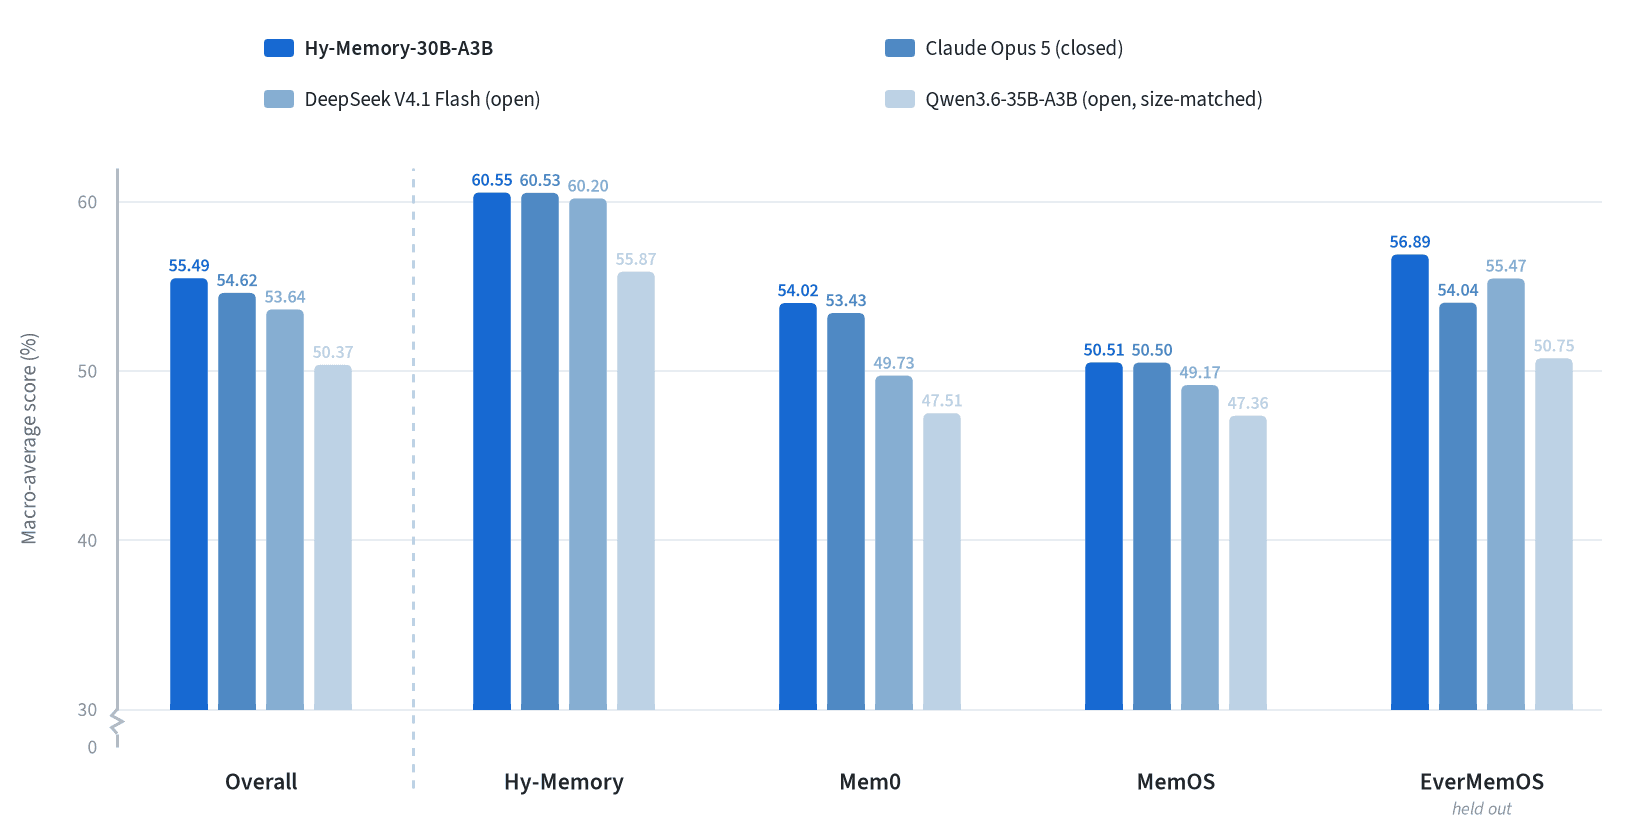
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
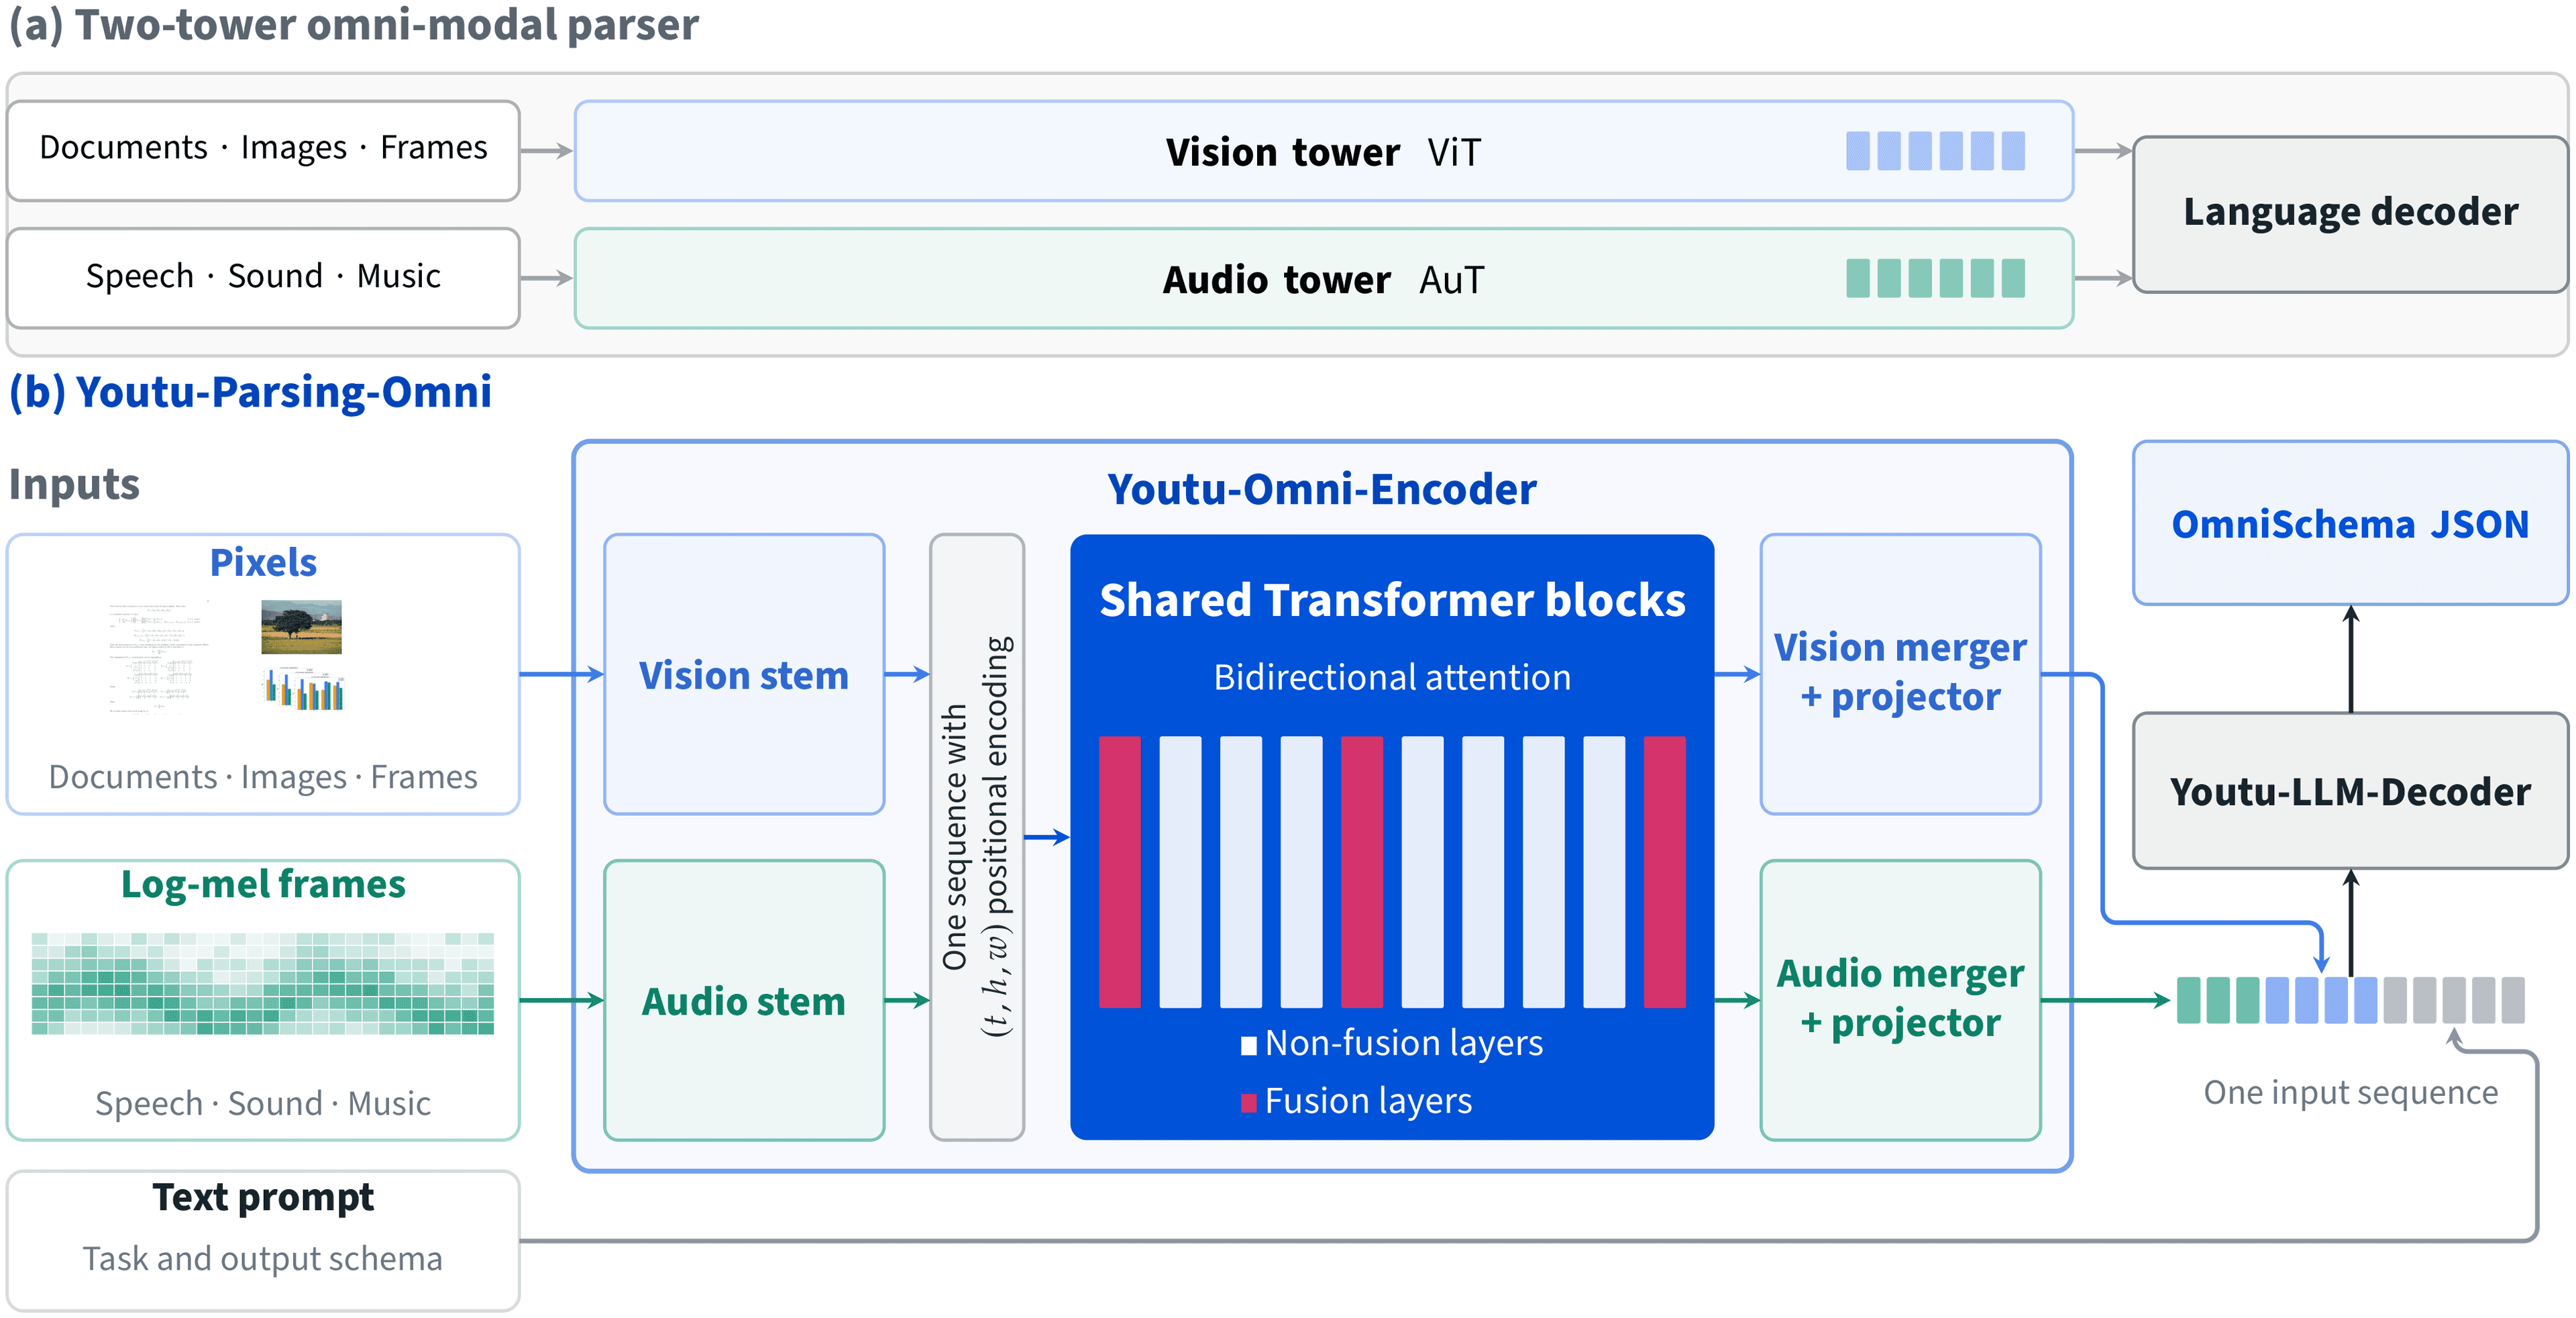
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Text → Video
All Text → Video →Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.
0 comments
No comments yet. Be the first to weigh in.