Alibaba Releases Wan2.2, a 14B MoE Video Model
The new open-source diffusion model from the team behind Qwen uses a Mixture-of-Experts architecture to animate still images.

Alibaba's Qwen team has introduced a new contender in the open-source video generation space with the release of Wan2.2-I2V-A14B. This 14-billion parameter diffusion model is designed to animate still images, turning them into short video clips. It's available under a permissive Apache 2.0 license, encouraging broad adoption and experimentation.
What sets Wan2.2 apart is its use of a Mixture-of-Experts (MoE) architecture. While MoE has become a popular technique for efficiently scaling large language models, its application in video diffusion is less common. This approach allows the model to selectively activate parts of its network for a given task, potentially offering a more computationally efficient path to high-quality video generation at a large scale.
The model has been released in the popular Diffusers format, making it readily accessible for developers and researchers. This simplifies integration into existing pipelines and encourages experimentation within the community. The full model weights and usage instructions are available on the project's Hugging Face repository.
The arrival of Wan2.2 signifies a notable architectural experiment from a major AI lab. As the community pushes the boundaries of open video generation, exploring techniques like MoE could prove crucial for creating more powerful and efficient models that can compete with leading closed-source alternatives.
Sources
- Visit
Wan-AI/Wan2.2-I2V-A14B-Diffusers
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
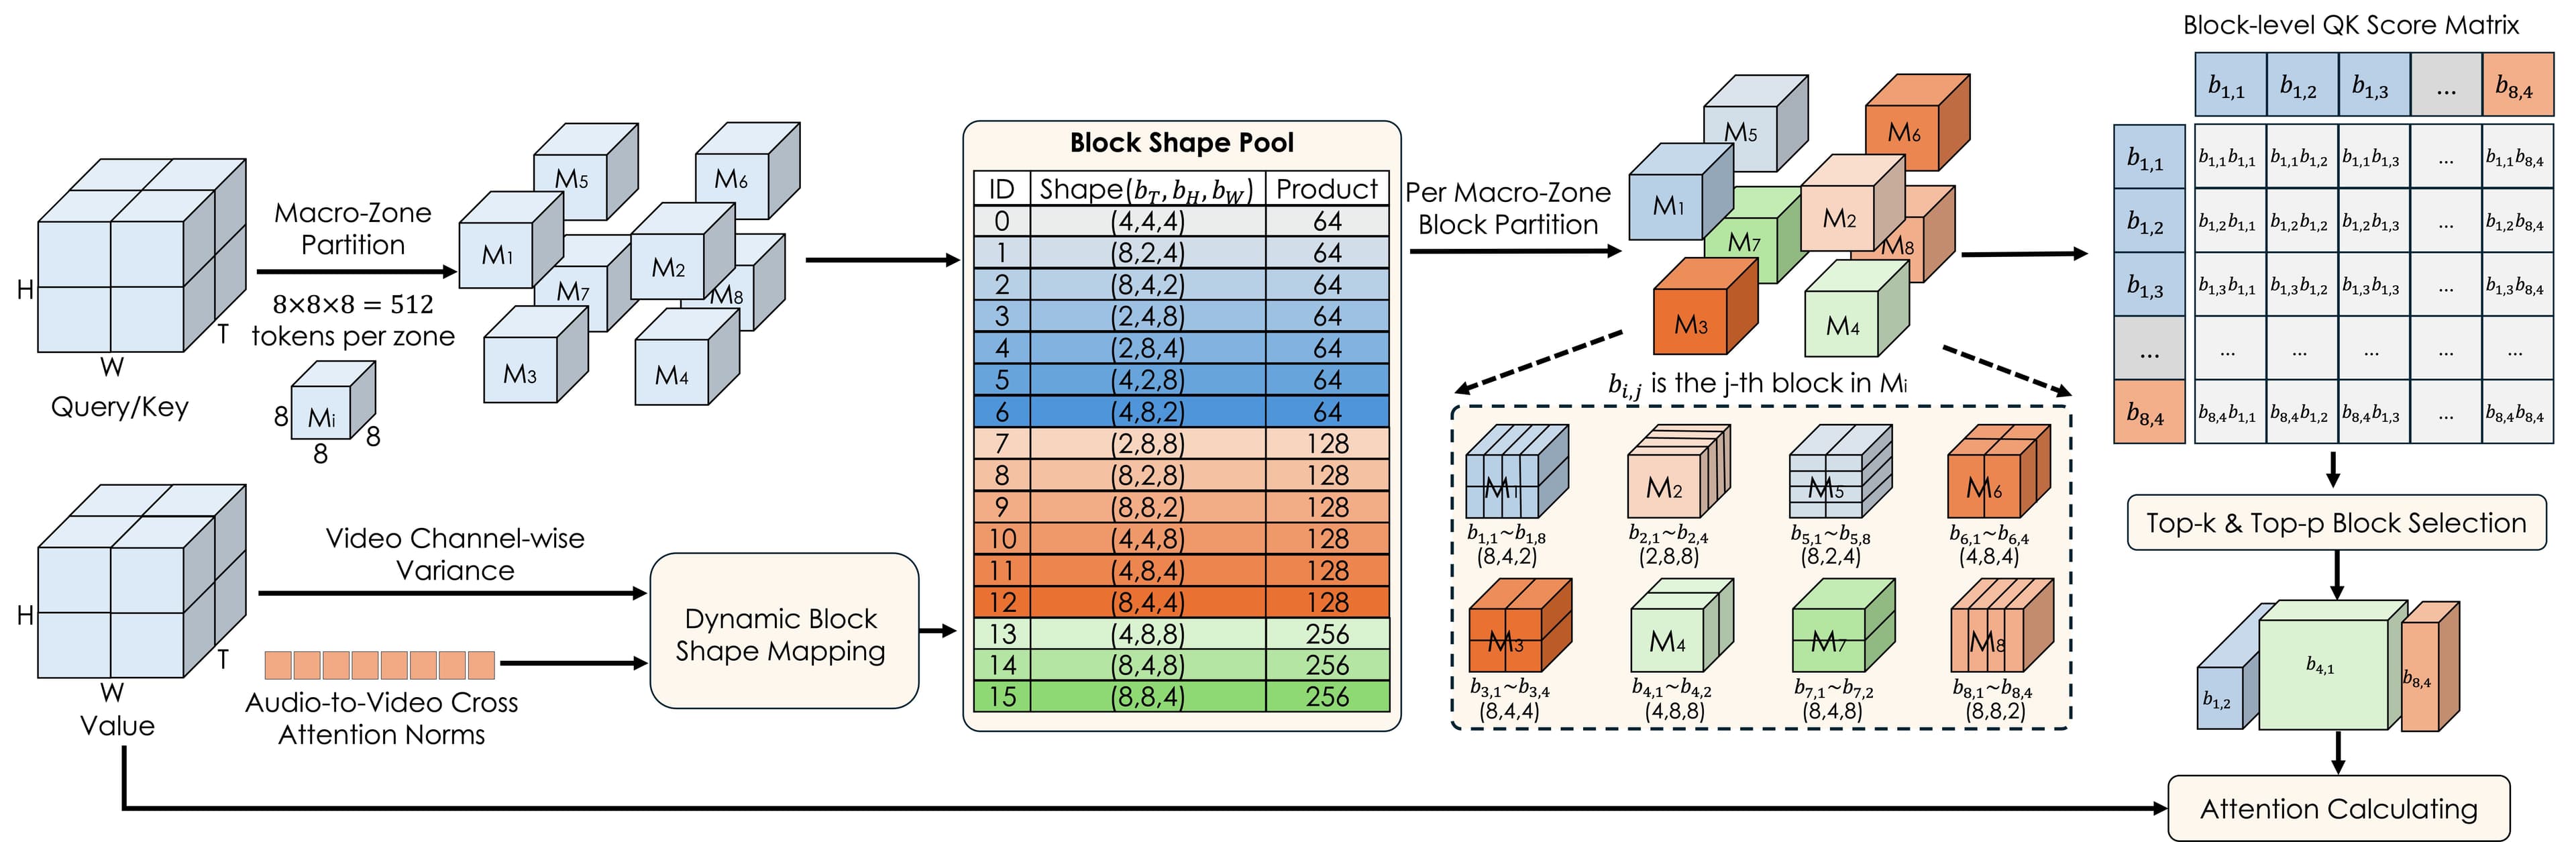
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.