Tencent Releases HunyuanImage 2.1 for Bilingual AI Art
The new text-to-image model from the Chinese tech giant is designed to understand both Chinese and English prompts at high resolutions.
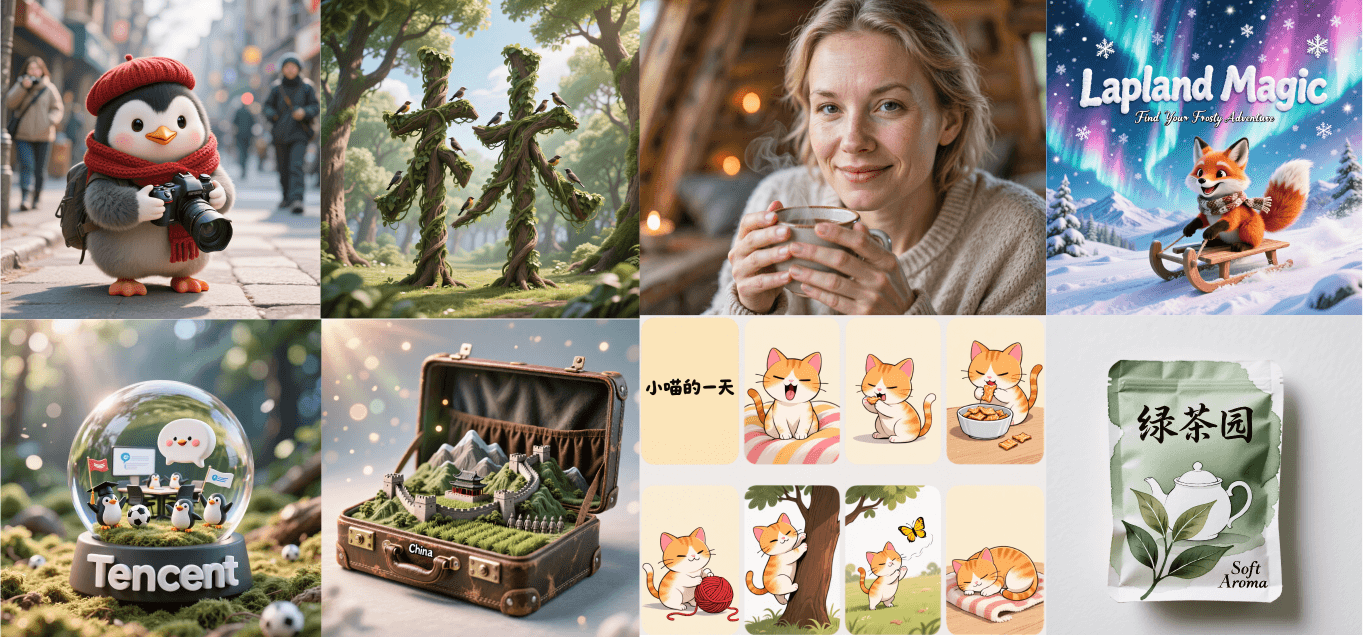
Tencent has released HunyuanImage 2.1, a powerful text-to-image diffusion model with a strong focus on bilingual capabilities. The model is engineered to interpret prompts in both Chinese and English, aiming to generate high-quality images that accurately reflect complex cultural and linguistic nuances.
Built on a diffusion U-Net architecture, the model uses a sophisticated bilingual text encoder that combines CLIP and T5 to better understand user intent. It natively generates images at a 1024x1024 resolution, placing it in line with other high-resolution open-source generators.
Conversational Image Generation
A standout feature of HunyuanImage 2.1 is its ability to engage in multi-turn dialogue. This allows users to iteratively refine an image through conversation, providing follow-up instructions to modify a previously generated picture. This conversational context is a significant step beyond the single-shot prompting common in most image models.
The model weights and code are available on Hugging Face and are designed for use with the diffusers library. HunyuanImage 2.1 is released under a custom Tencent Hunyuan Model License Agreement, which permits non-commercial research use and outlines a separate application process for commercial licensing.
Sources
- Visit
tencent/HunyuanImage-2.1
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
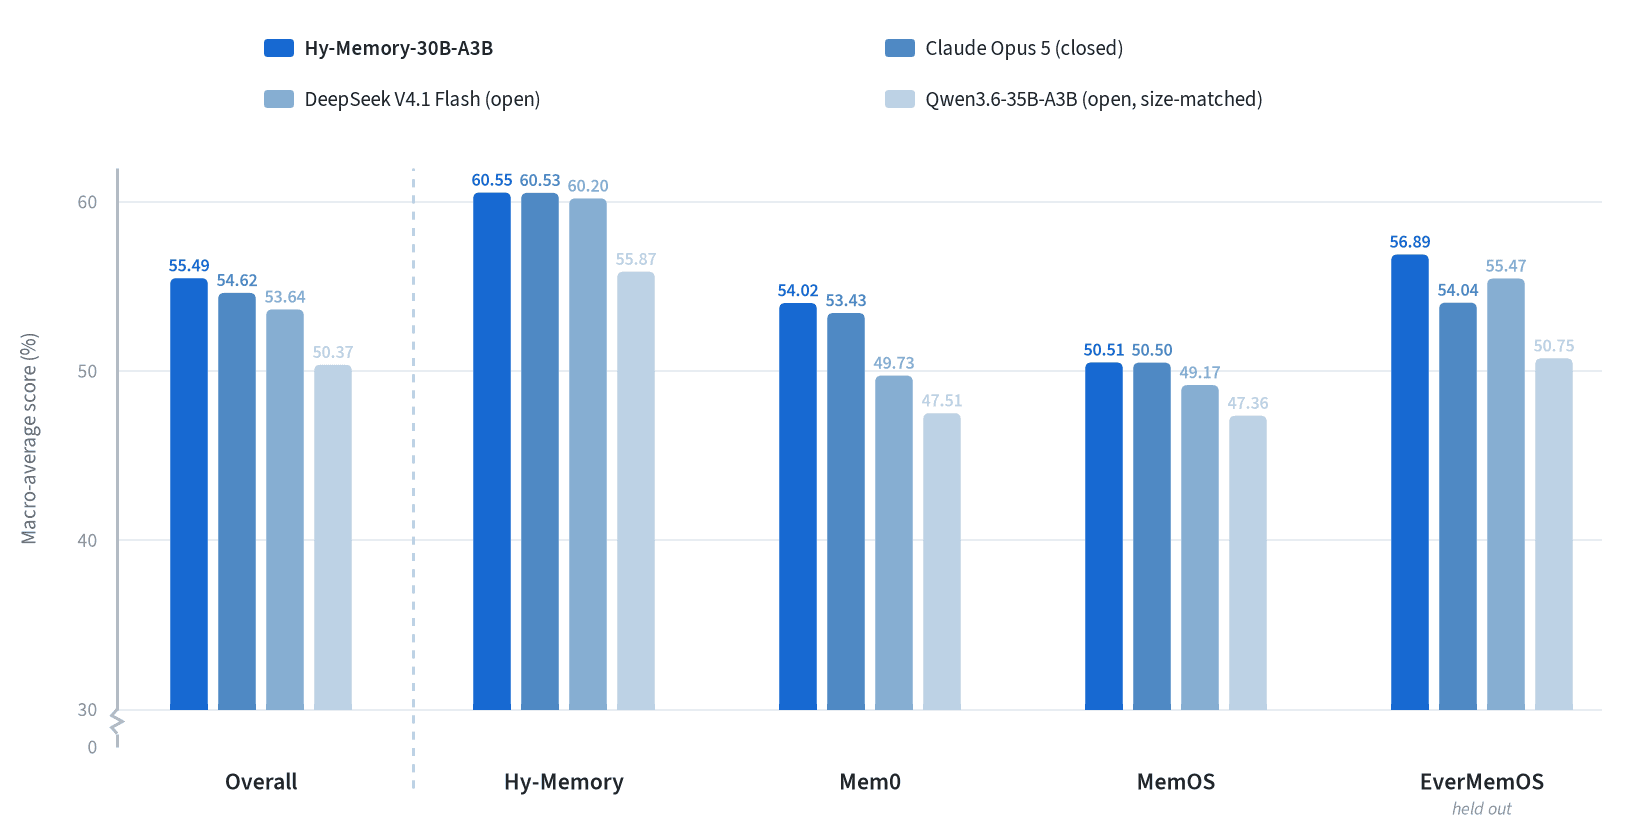
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
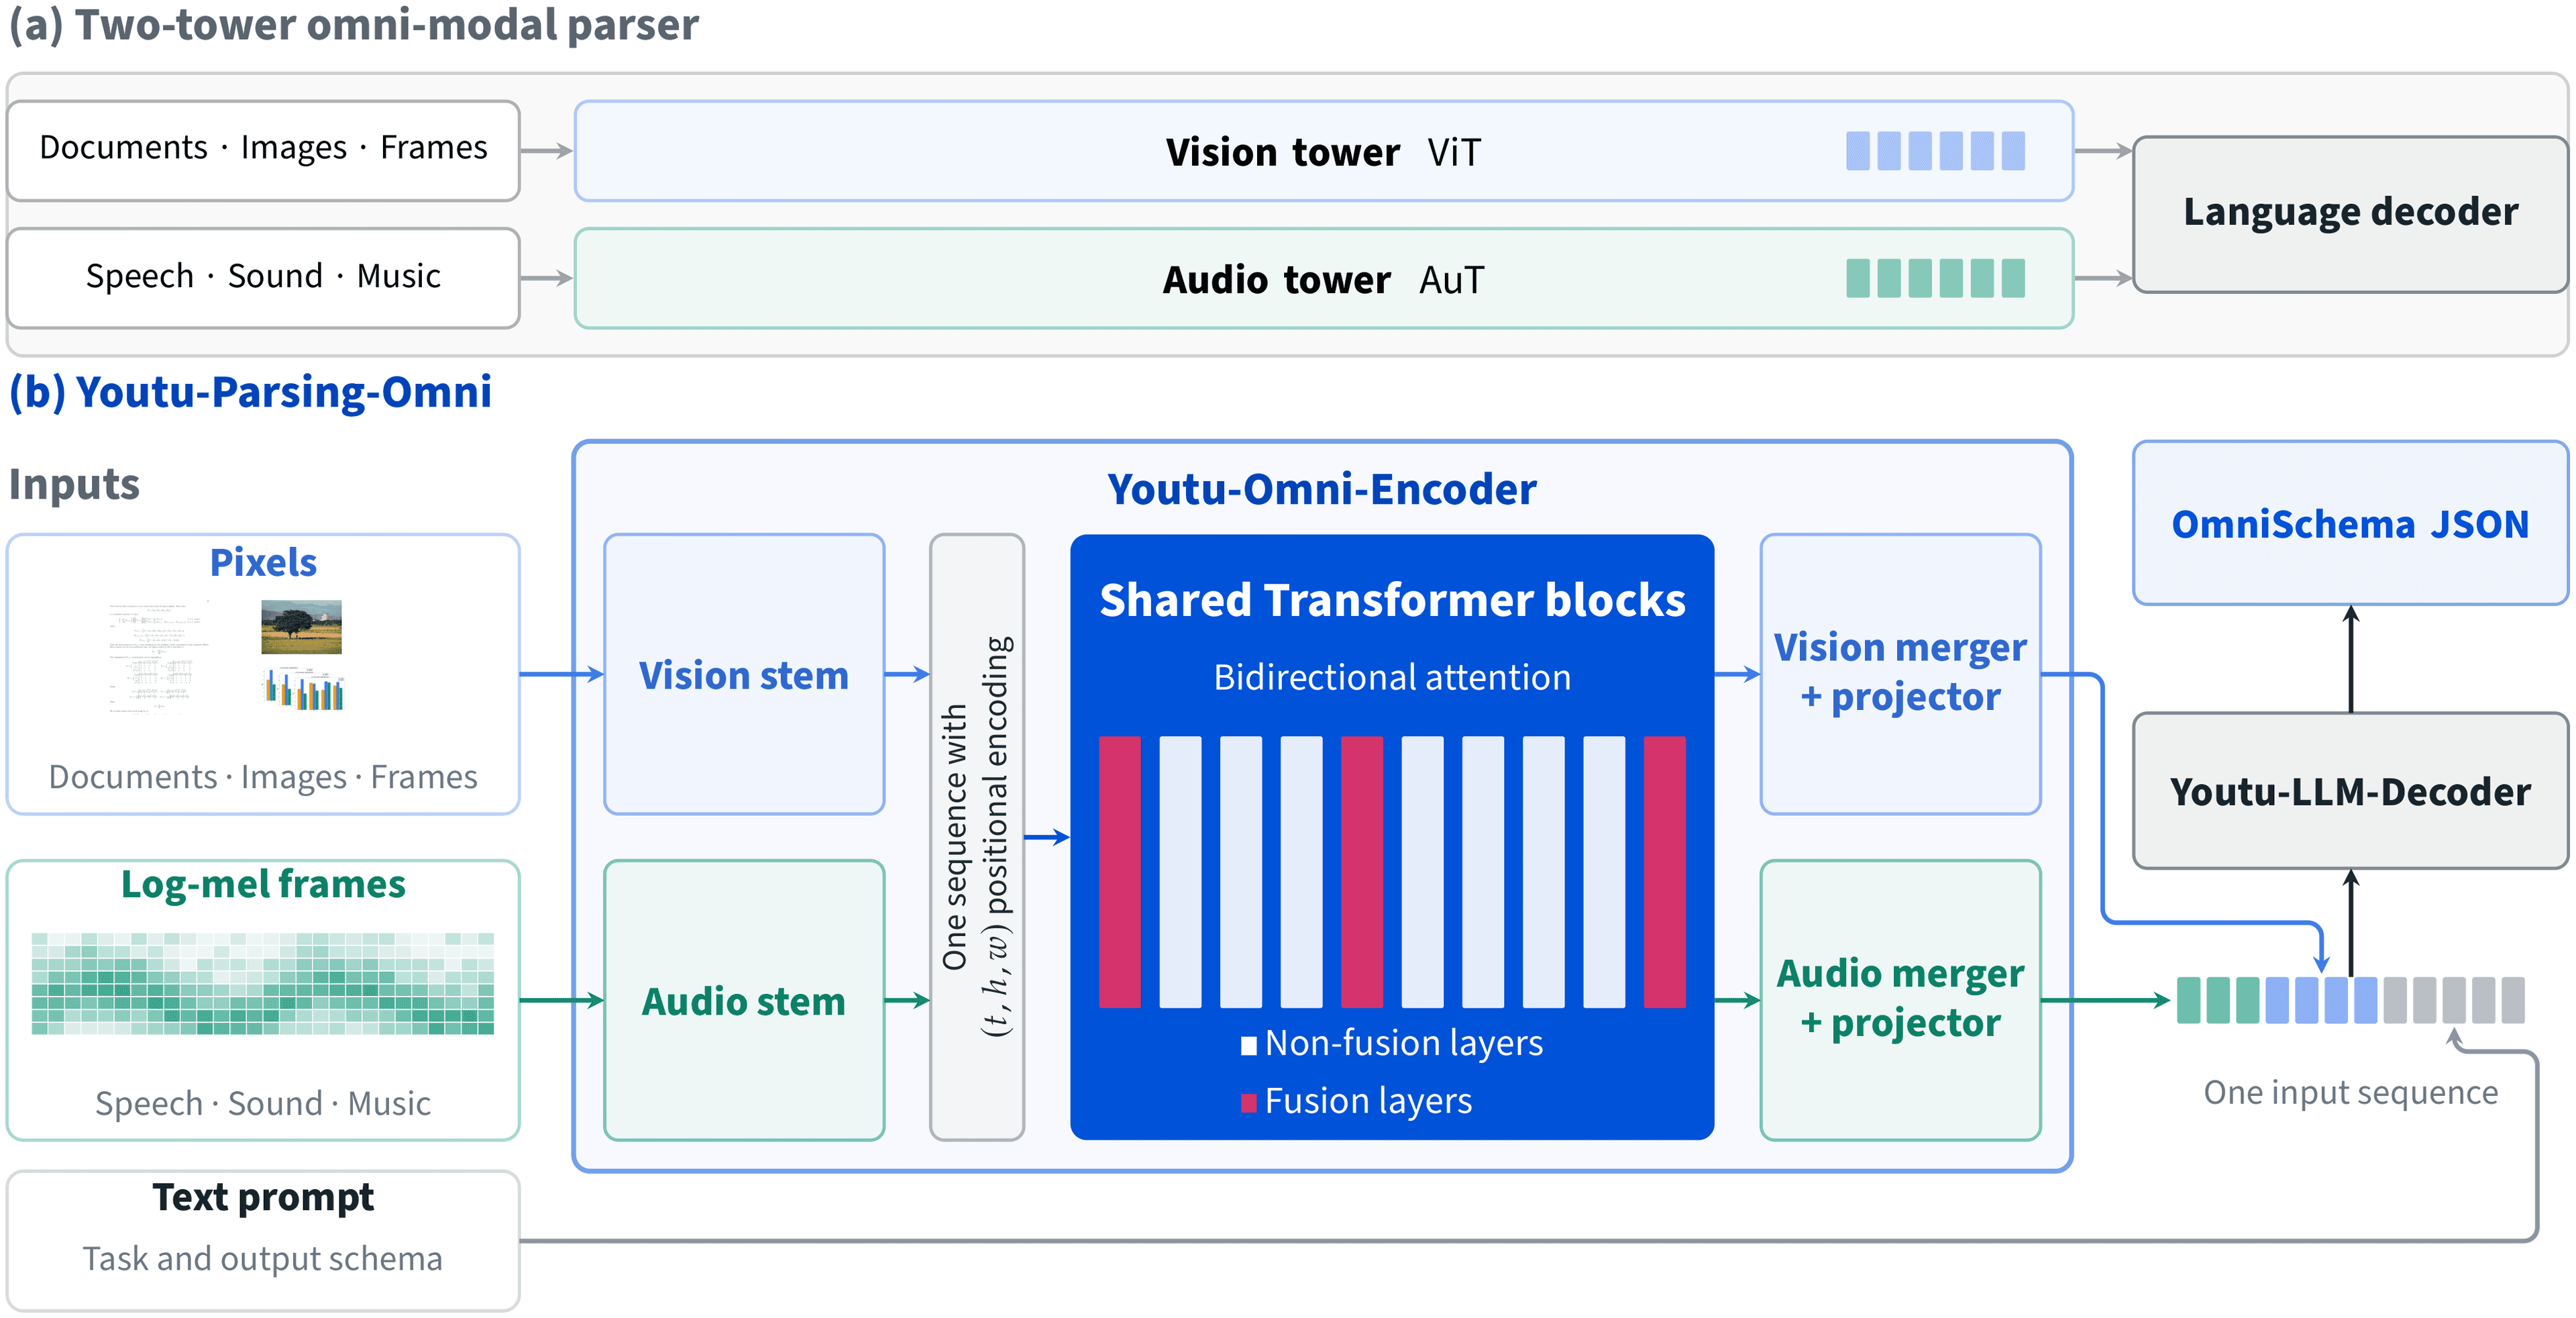
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.