Microsoft Releases VibeVoice, a 7B Podcast TTS Model
The new 7-billion-parameter model is designed for generating long-form, multi-speaker audio in English and Chinese under a permissive MIT license.
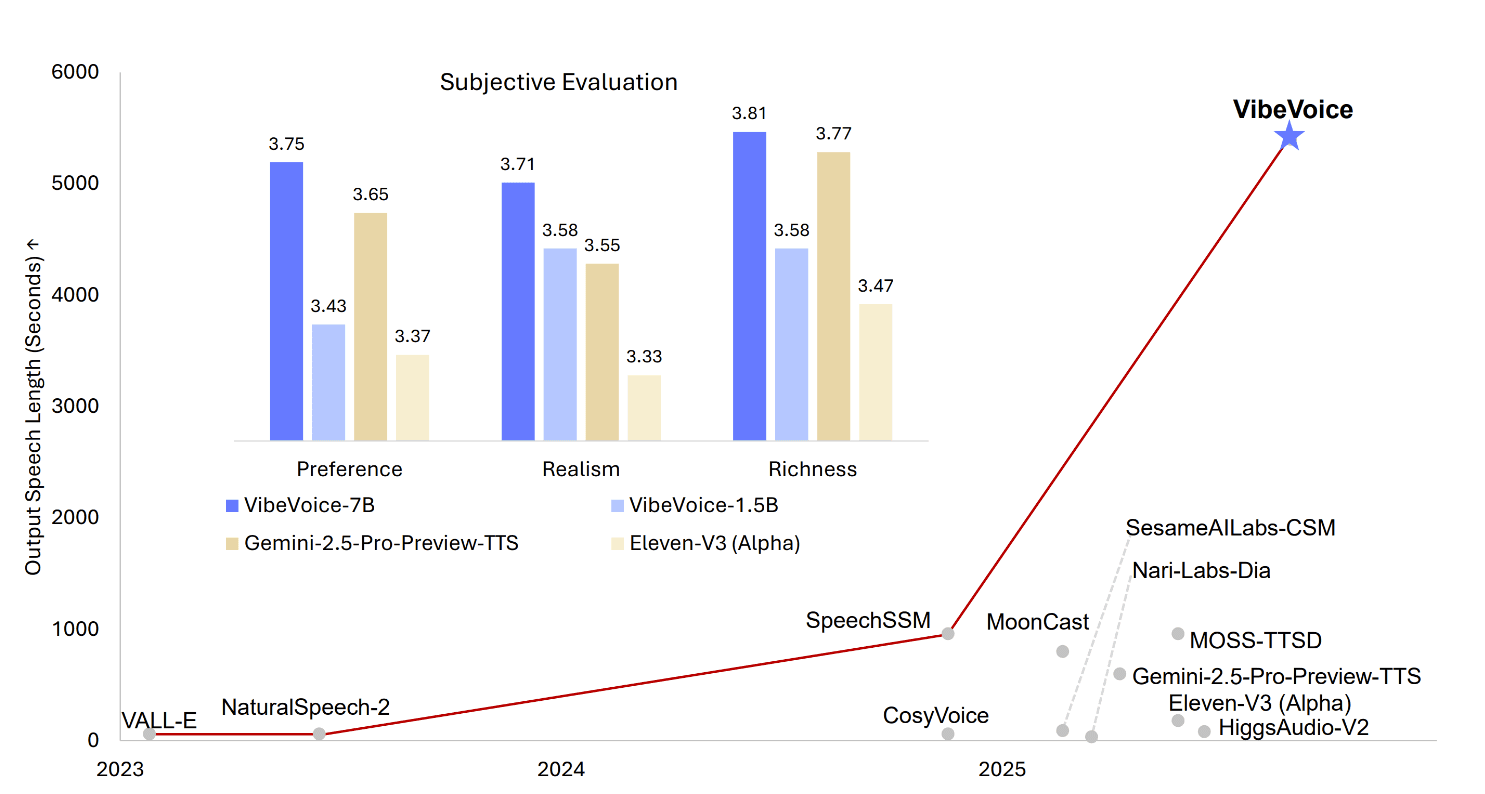
Microsoft has entered the open-source audio space with VibeVoice-7B, a large text-to-speech (TTS) model designed for creating complex, conversational audio. At 7 billion parameters, it represents a significant new entry in a field where high-quality, open models are still less common than their text-based counterparts.
The model's primary strength is its ability to generate long-form, multi-speaker content that mimics the style of a podcast. This capability addresses a key challenge in synthetic audio: maintaining vocal consistency and natural turn-taking over extended durations. VibeVoice-7B supports both English and Chinese, broadening its potential applications.
Key Capabilities
- Multi-Speaker Generation: Creates conversational audio with distinct voices.
- Long-Form Synthesis: Optimized for generating extended content like articles or audiobooks.
- Bilingual Support: Capable of producing speech in both English and Chinese.
- Permissive Licensing: Released under the MIT license, allowing for wide-ranging commercial and research use.
What makes this release particularly notable is the combination of its scale and permissive license. While proprietary TTS services offer high quality, a powerful open-source alternative like VibeVoice gives developers and creators more control and flexibility. This could accelerate innovation in areas like automated content production, accessibility tools, and dynamic virtual assistants. The model is available for download and experimentation on its Hugging Face repository.
Sources
- Visit
vibevoice/VibeVoice-7B
Hugging Face
More in Text → Speech
All Text → Speech →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.

Fish Audio's Drama 3 brings MoE to open TTS
The open-source speech model pairs a 35B mixture-of-experts backbone with voice cloning and directed performance control.
0 comments
No comments yet. Be the first to weigh in.