Microsoft Releases VibeVoice, a Podcast-Ready TTS Model
The new open-source model specializes in generating long-form, multi-speaker audio in both English and Mandarin, mimicking a natural podcast conversation.
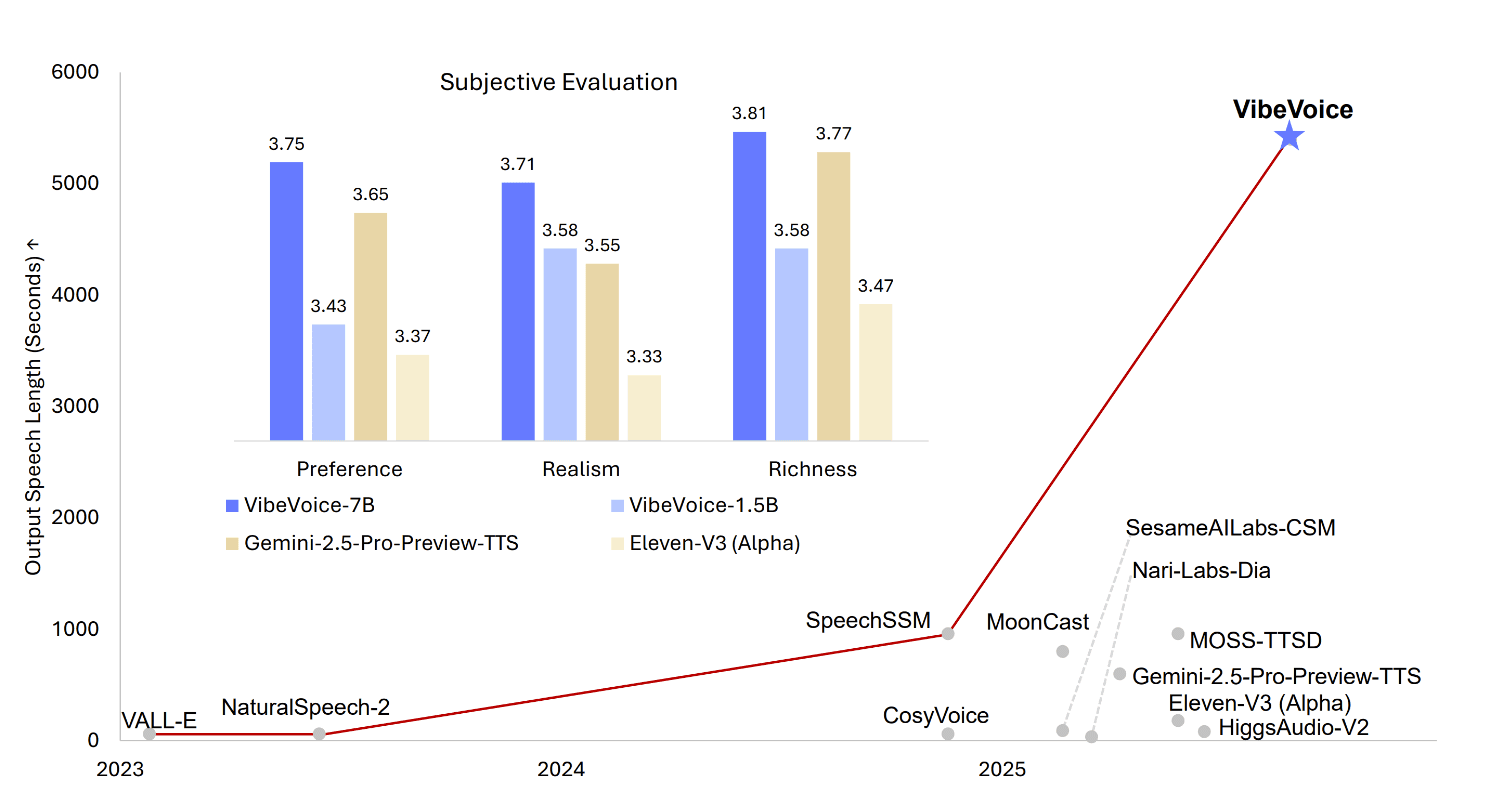
Microsoft has introduced a new open-source model for text-to-speech synthesis, VibeVoice Large, designed specifically for creating realistic, long-form audio content. Released under the permissive MIT license, the model aims to tackle one of the more challenging frontiers in speech generation: natural, multi-speaker conversations.
Unlike many TTS models optimized for short, single-speaker responses, VibeVoice is built to generate audio that mimics the dynamic flow of a podcast. According to the release materials on Hugging Face, it can handle extended passages of text and differentiate between multiple speakers within the same audio track, supporting both English and Mandarin Chinese.
Why It Matters
The release of VibeVoice addresses a key gap in the open-source AI ecosystem. Creating high-quality, long-form spoken content, especially with multiple voices, has often required complex, proprietary systems or extensive manual editing. By providing a specialized tool for this purpose, Microsoft is enabling developers and creators to build more sophisticated applications, from automated podcast production and audiobook narration to more dynamic virtual assistants.
The model's focus on conversational audio represents a move toward more naturalistic human-computer interaction. As AI becomes more integrated into daily life, the ability to generate speech that is not just clear but also contextually appropriate and engaging is increasingly important. VibeVoice Large is available for download and experimentation now.
Sources
- Visit
aoi-ot/VibeVoice-Large
Hugging Face
More in Text → Speech
All Text → Speech →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
Fish Audio's Drama 3 brings MoE to open TTS
The open-source speech model pairs a 35B mixture-of-experts backbone with voice cloning and directed performance control.
0 comments
No comments yet. Be the first to weigh in.