Tencent Releases 1.8B Model for Multilingual Translation
The 1.8 billion-parameter model from the Chinese tech giant is designed for high-quality translation across a wide range of language pairs.
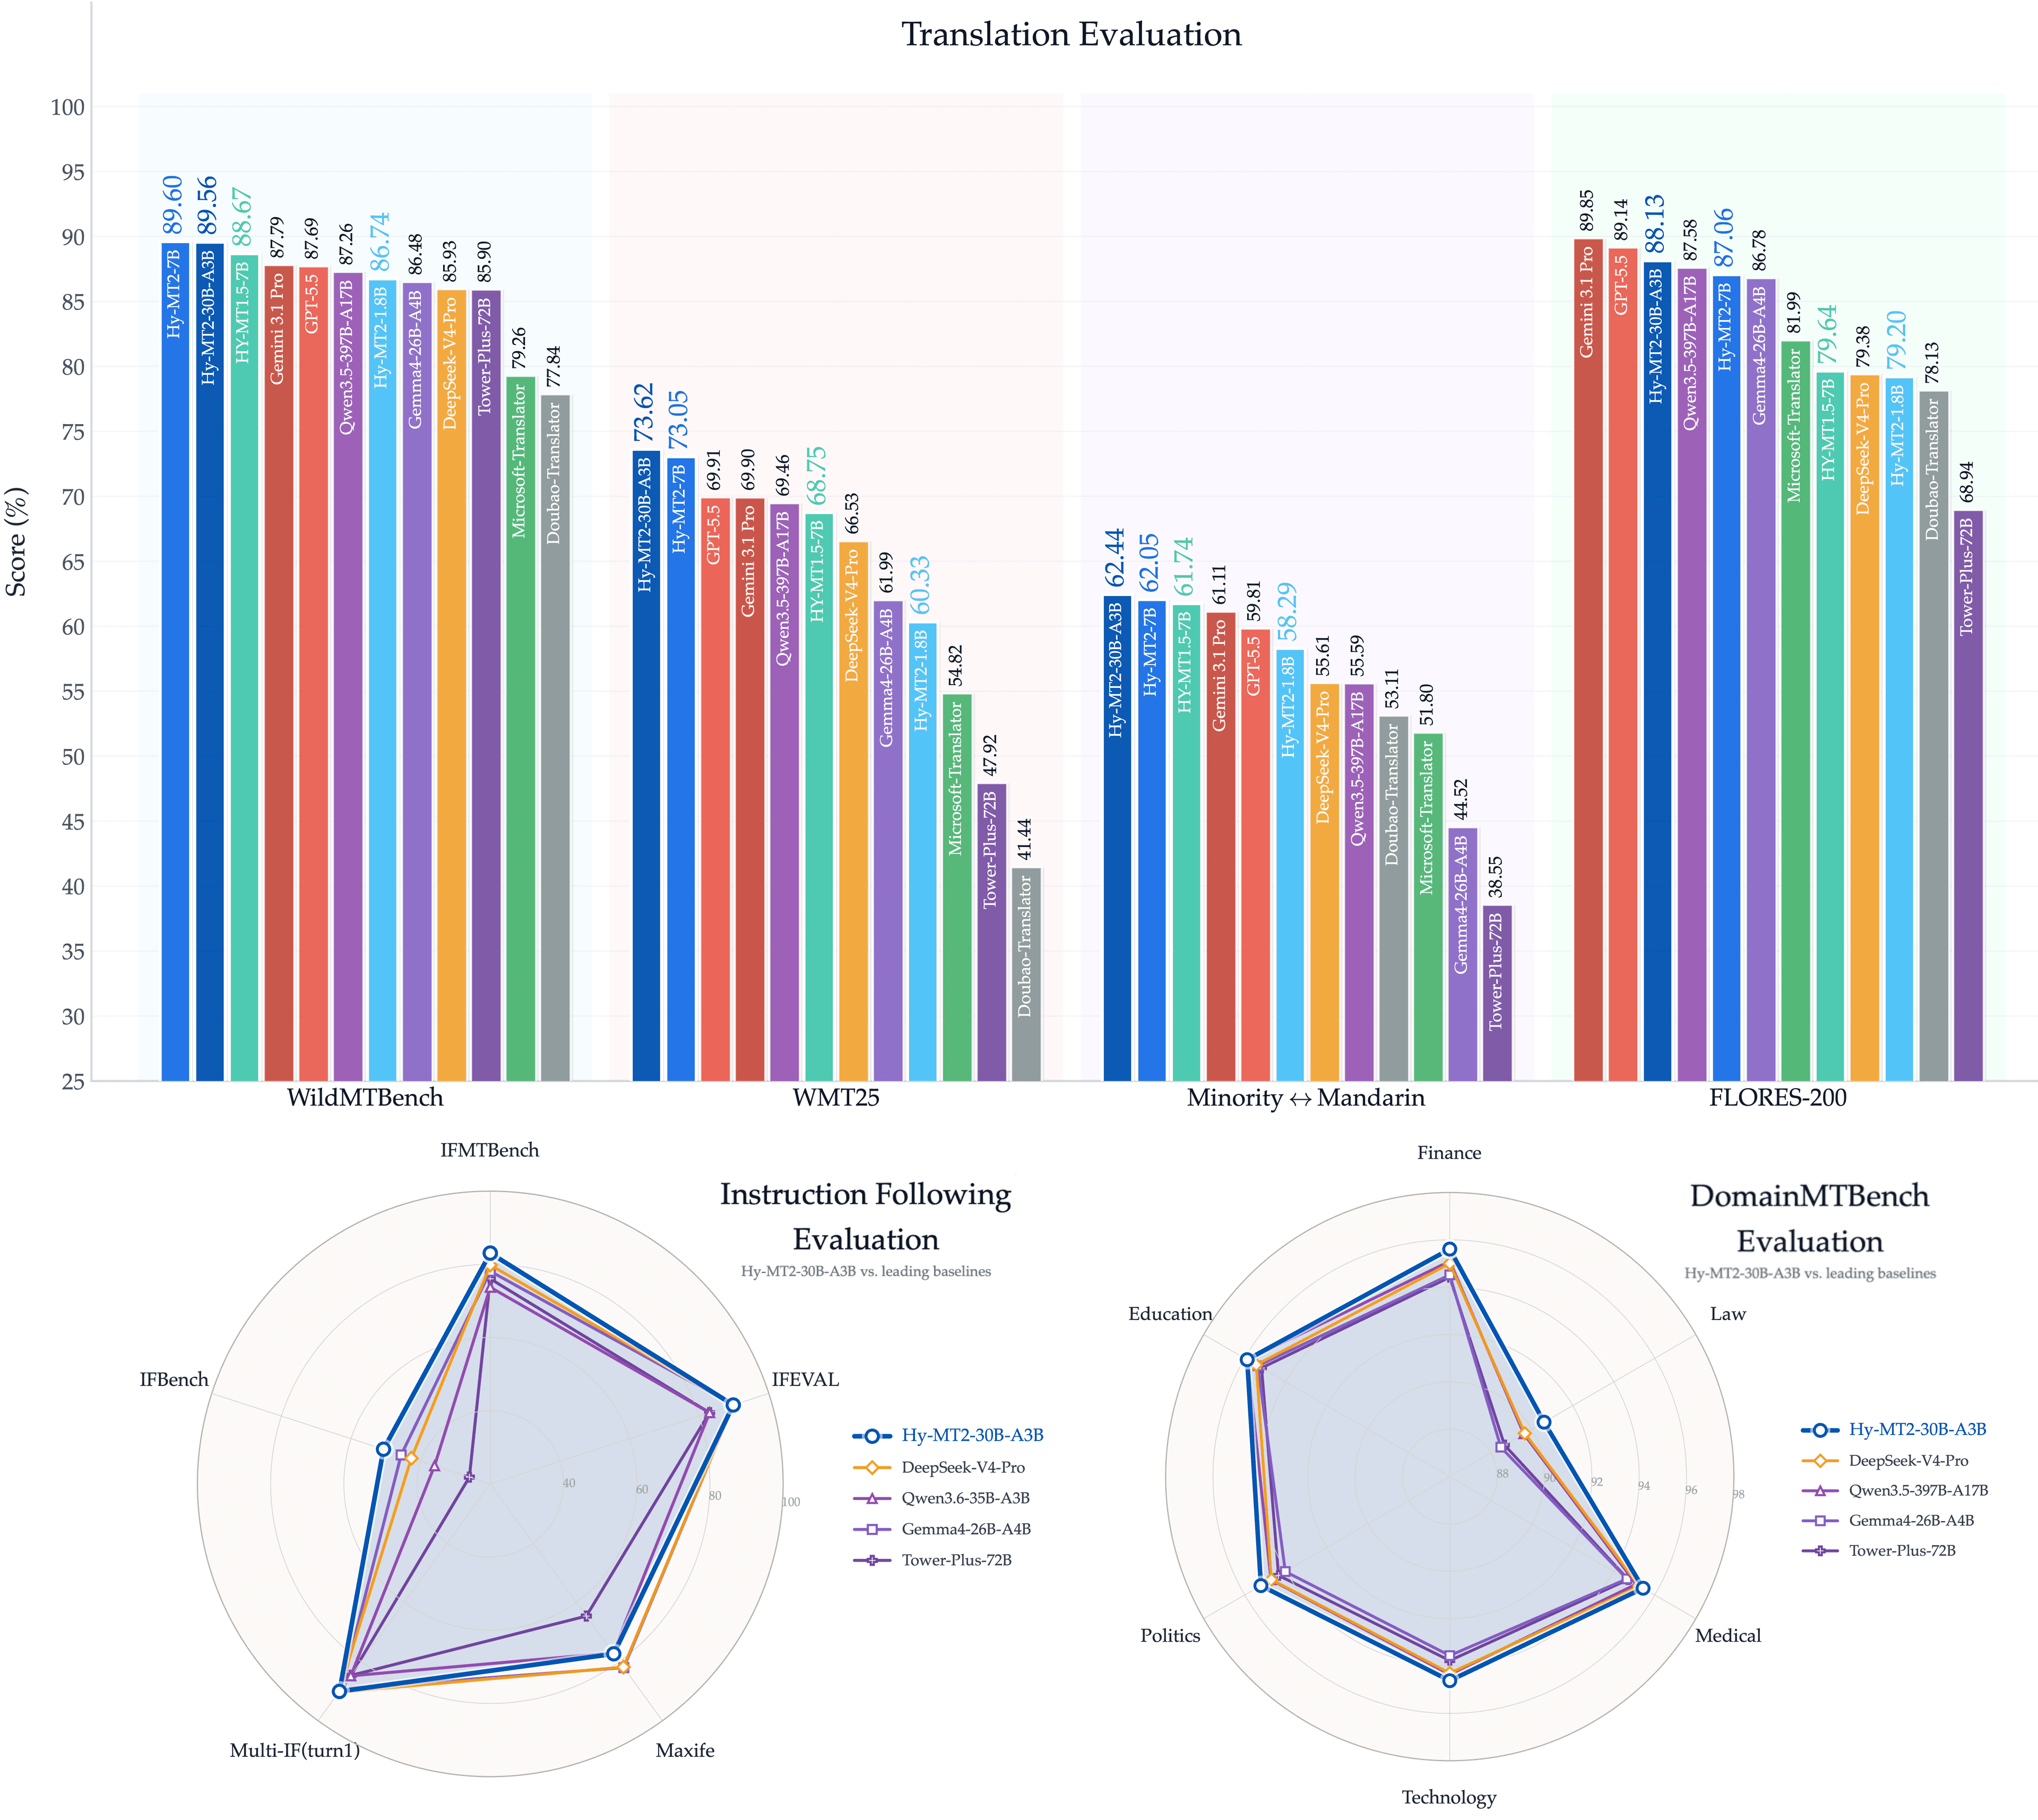
Chinese technology firm Tencent has released Hunyuan-MT2, a new 1.8 billion-parameter model specialized for machine translation. This dense model, not a Mixture-of-Experts, represents a focused effort by the company to advance multilingual AI capabilities. The model and its weights are now available on Hugging Face.
Unlike general-purpose chatbots, Hunyuan-MT2 is a purpose-built tool designed for a single, complex task: translating text between multiple languages. While the specific language pairs are not detailed, its design suggests an aim for broad coverage and high-fidelity output, making it a potentially valuable component for developers building global applications.
This release adds a significant, specialized tool to the open-weights ecosystem. It provides an alternative to relying on large, proprietary translation APIs or fine-tuning generalist models for translation tasks. However, developers should note that the model is governed by a custom "Tencent Hunyuan Model License Agreement," which carries specific restrictions and should be reviewed carefully before use.
Sources
- Visit
tencent/Hy-MT2-1.8B
Hugging Face
More from Tencent
All Tencent releases →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
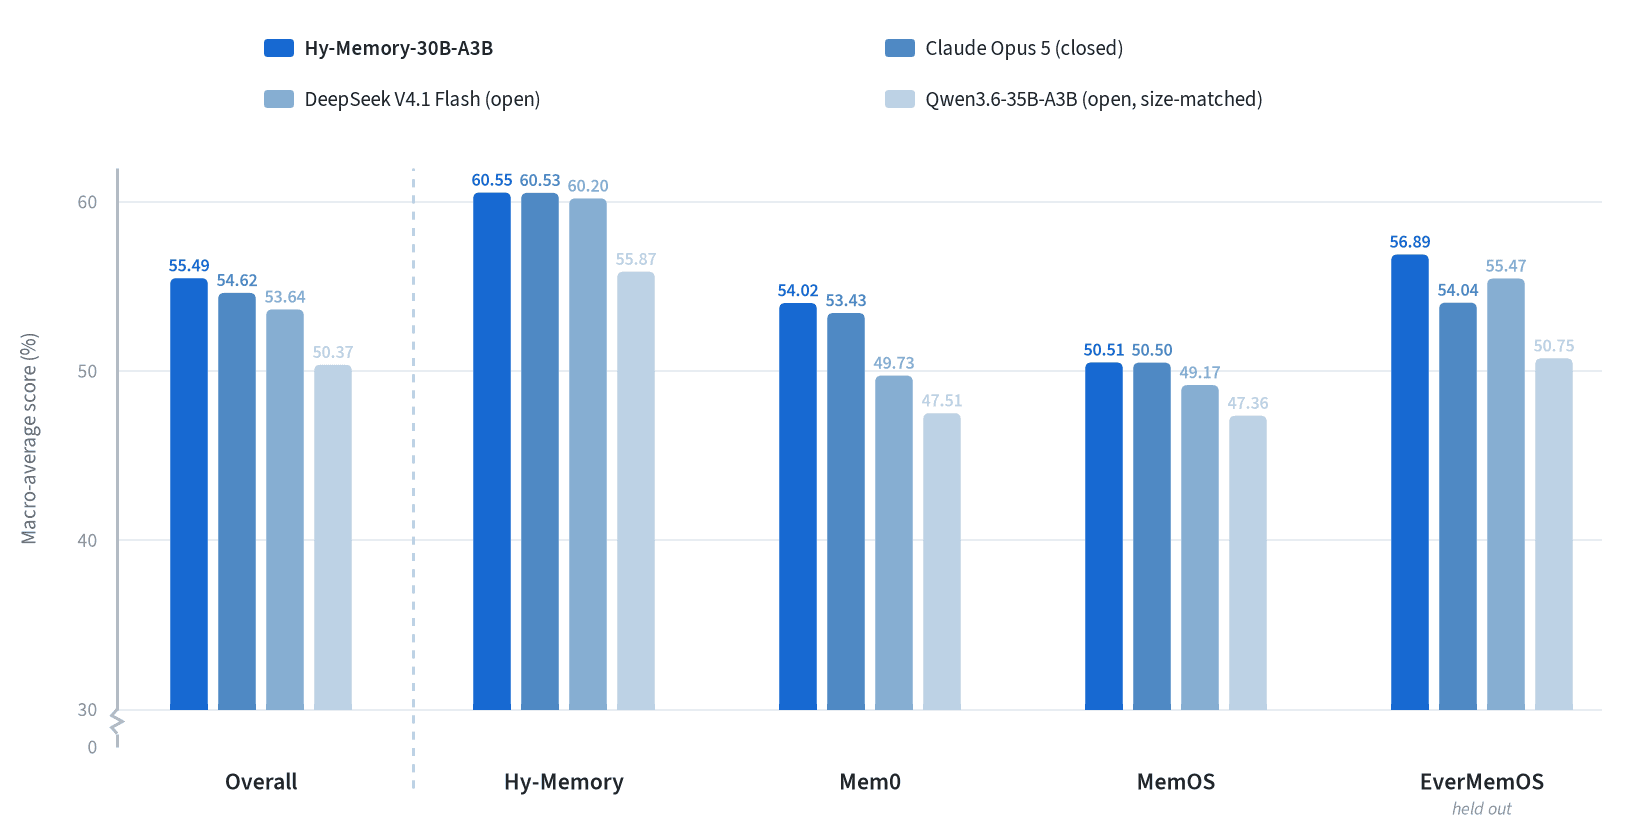
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
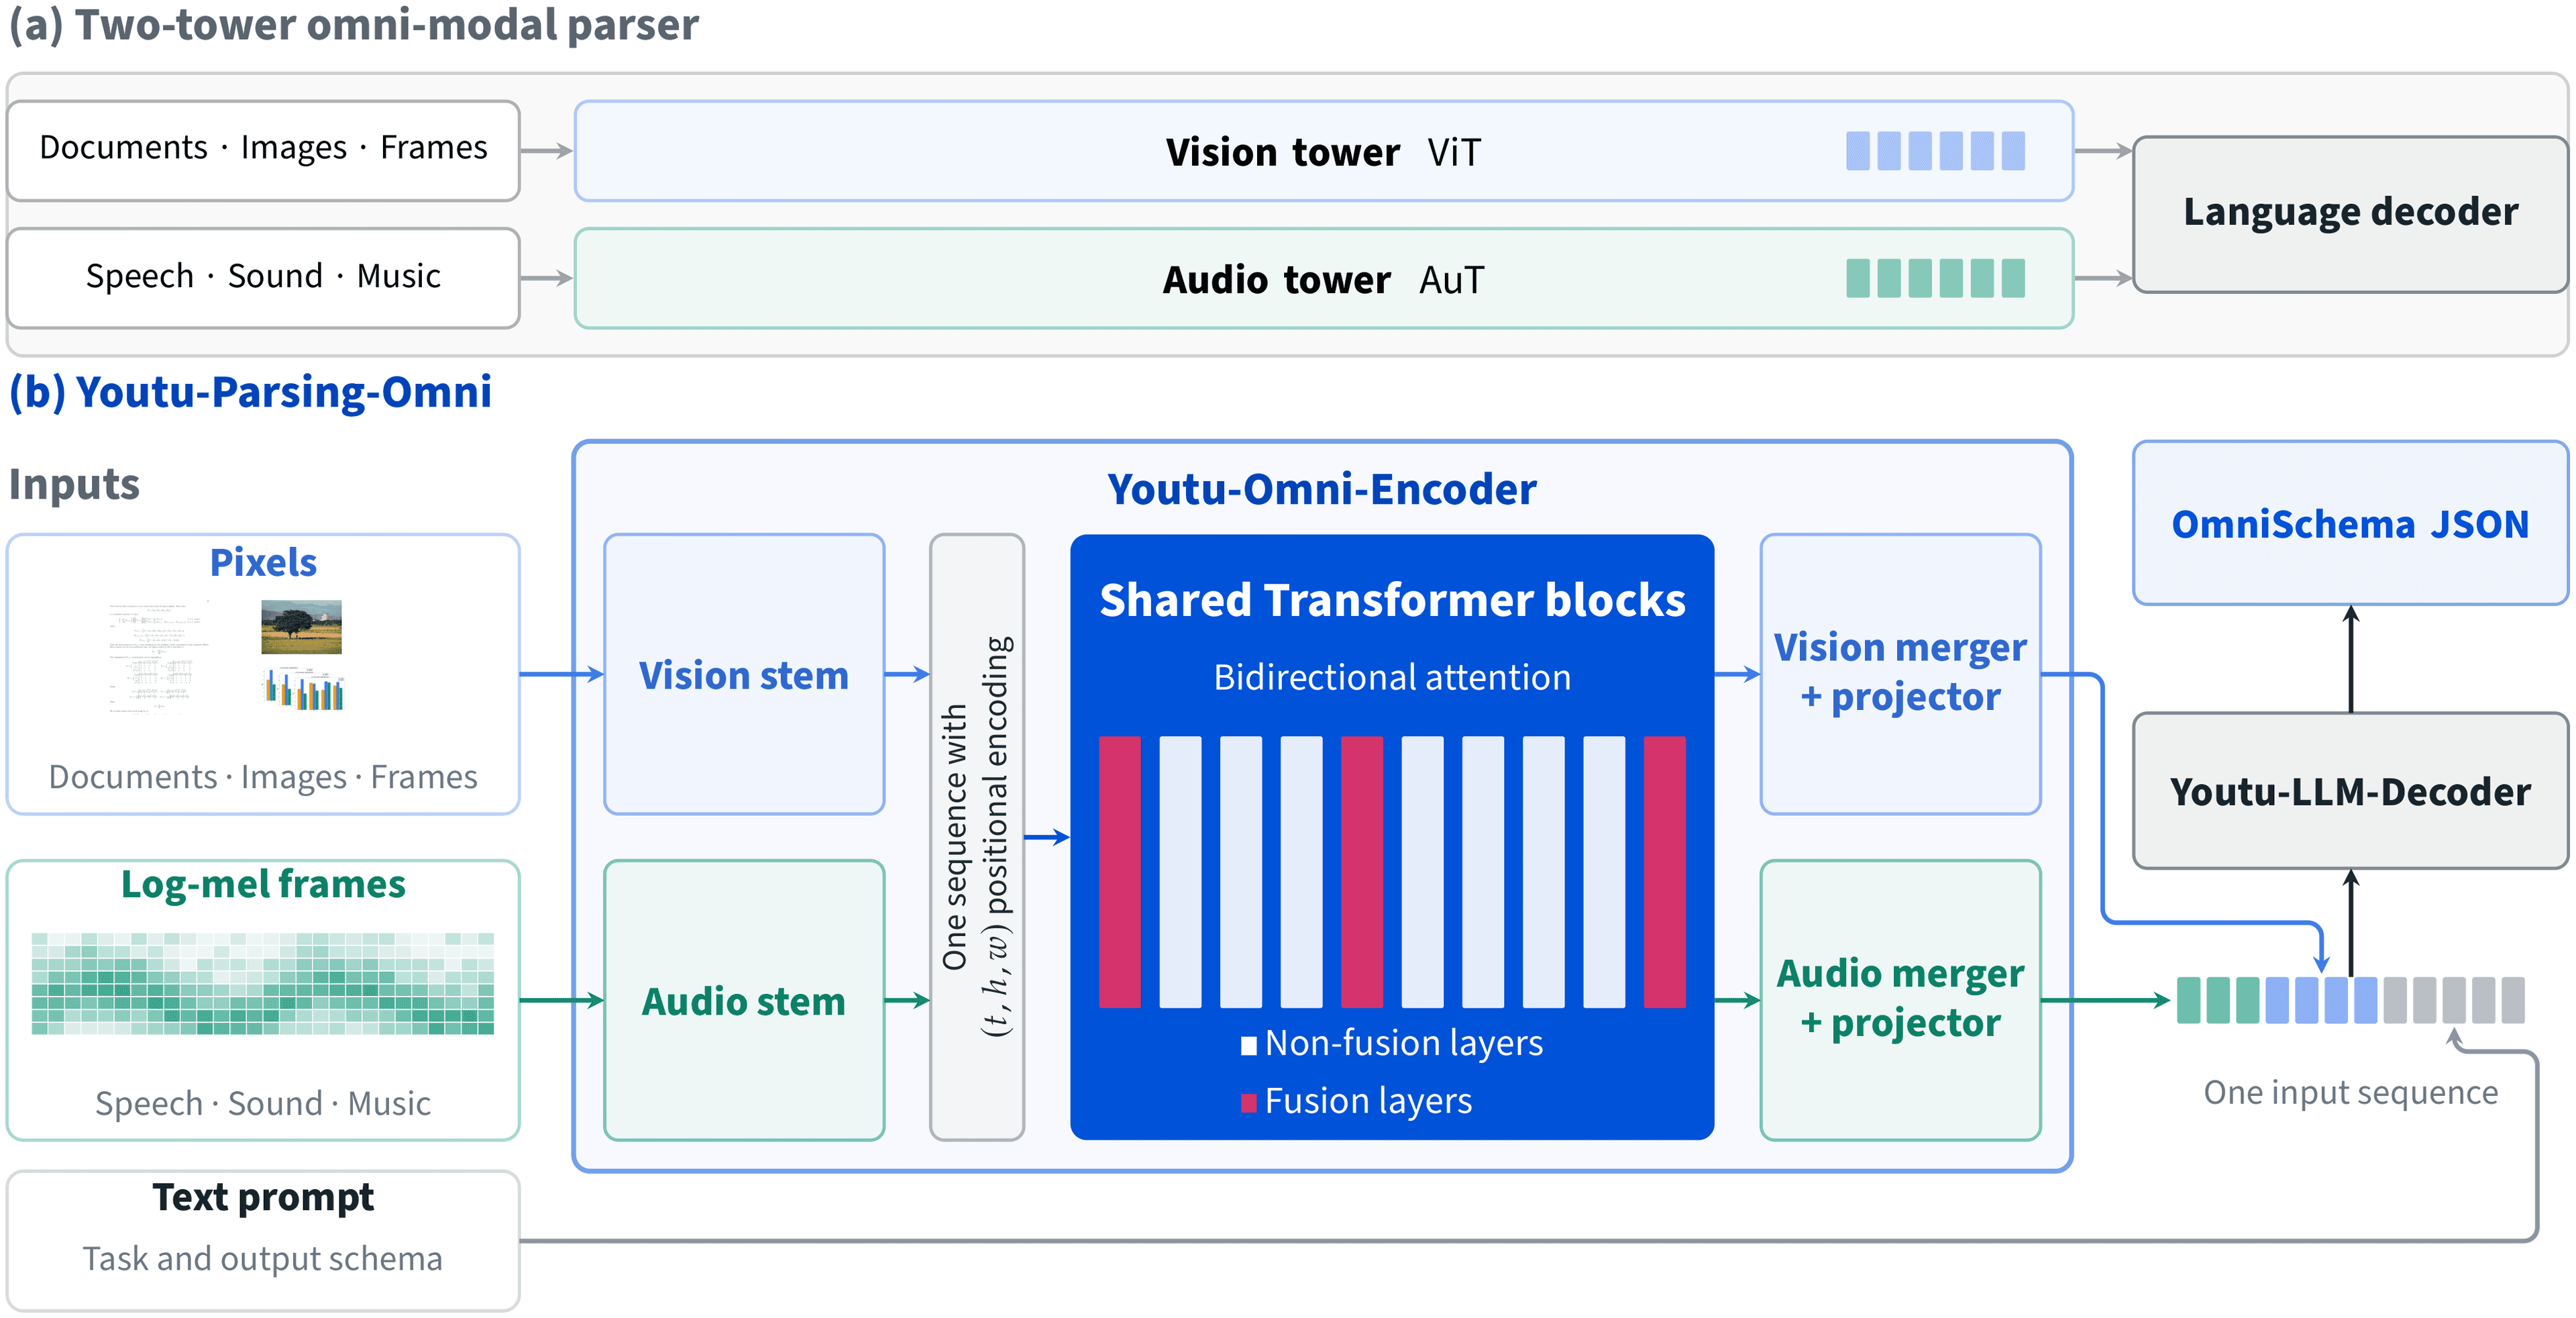
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.