IFM releases PAN2, an open world-simulation video model
The Institute of Foundation Models ships a permissively licensed diffusion-transformer system for turning text and images into video.
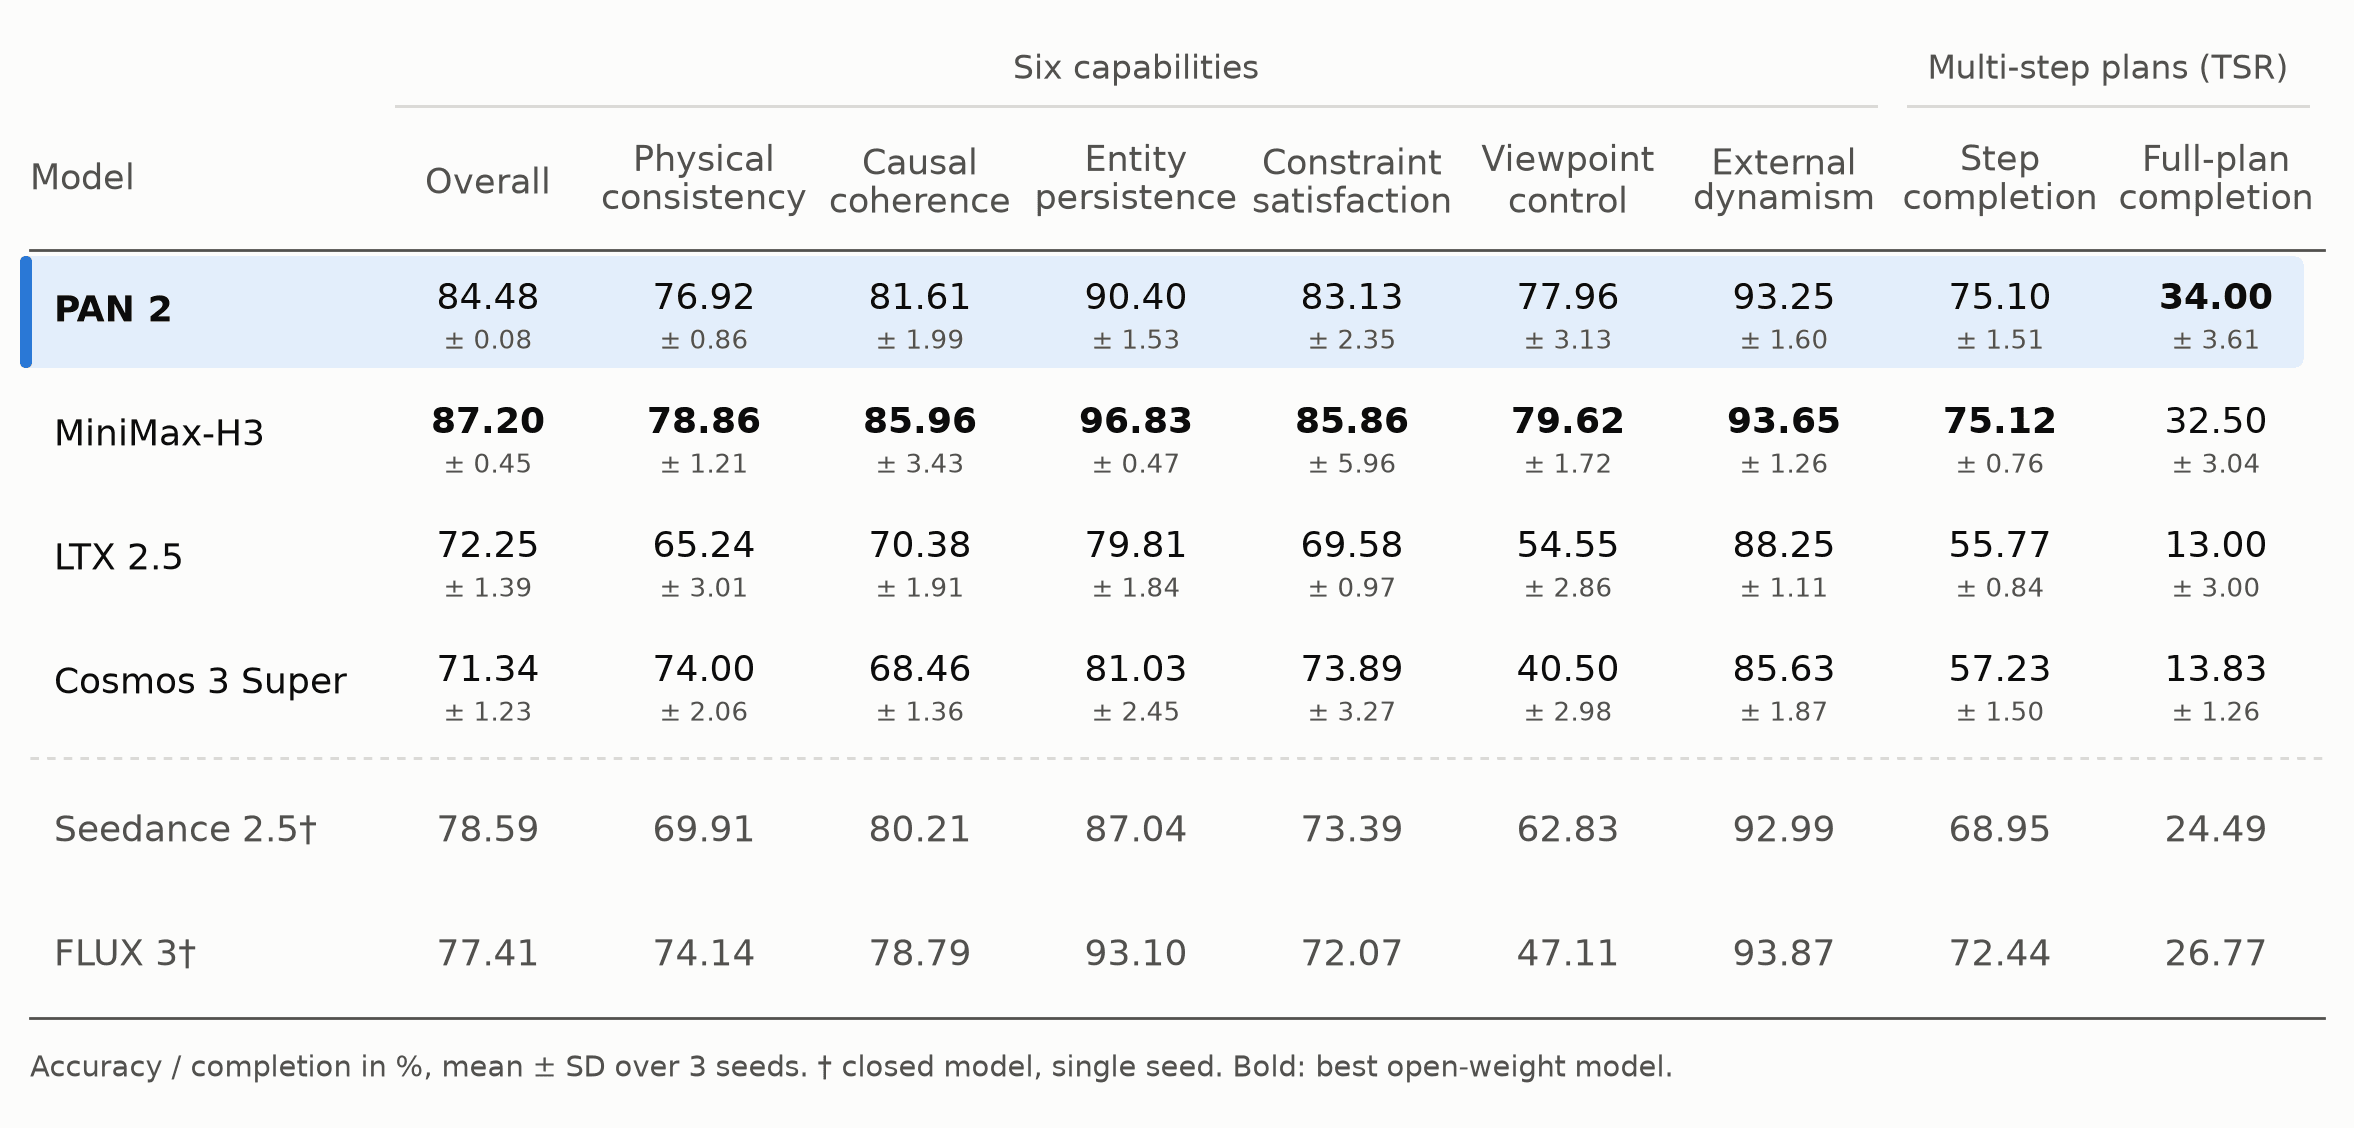
The Institute of Foundation Models has published PAN2, a diffusion-transformer model for generating video from text prompts and still images. The release is positioned as a world-simulation system, meaning it aims to model how scenes evolve over time rather than simply stitch frames together.
PAN2 supports two primary workflows: text-to-video, where a written prompt produces a clip, and image-to-video, where a single still is animated into motion. The latter is listed as the model's primary modality, suggesting IFM sees conditioning on a reference frame as the central use case.
Why it matters
The most consequential detail may be the license. PAN2 ships under Apache-2.0, one of the most permissive terms available, which allows commercial use, modification, and redistribution with minimal restrictions. That stands apart from many video models that arrive under research-only or custom non-commercial terms.
- Modalities: text-to-video and image-to-video
- Architecture: diffusion transformer
- License: Apache-2.0
- Framing: world simulation
IFM has not published parameter counts, context details, or benchmark figures alongside the release, so the practical quality and hardware requirements remain to be tested by the community. For now, the model and its details are available on the Hugging Face repository.
Sources
- Visit
IFM/PAN2
Hugging Face
More from IFM
All IFM releases →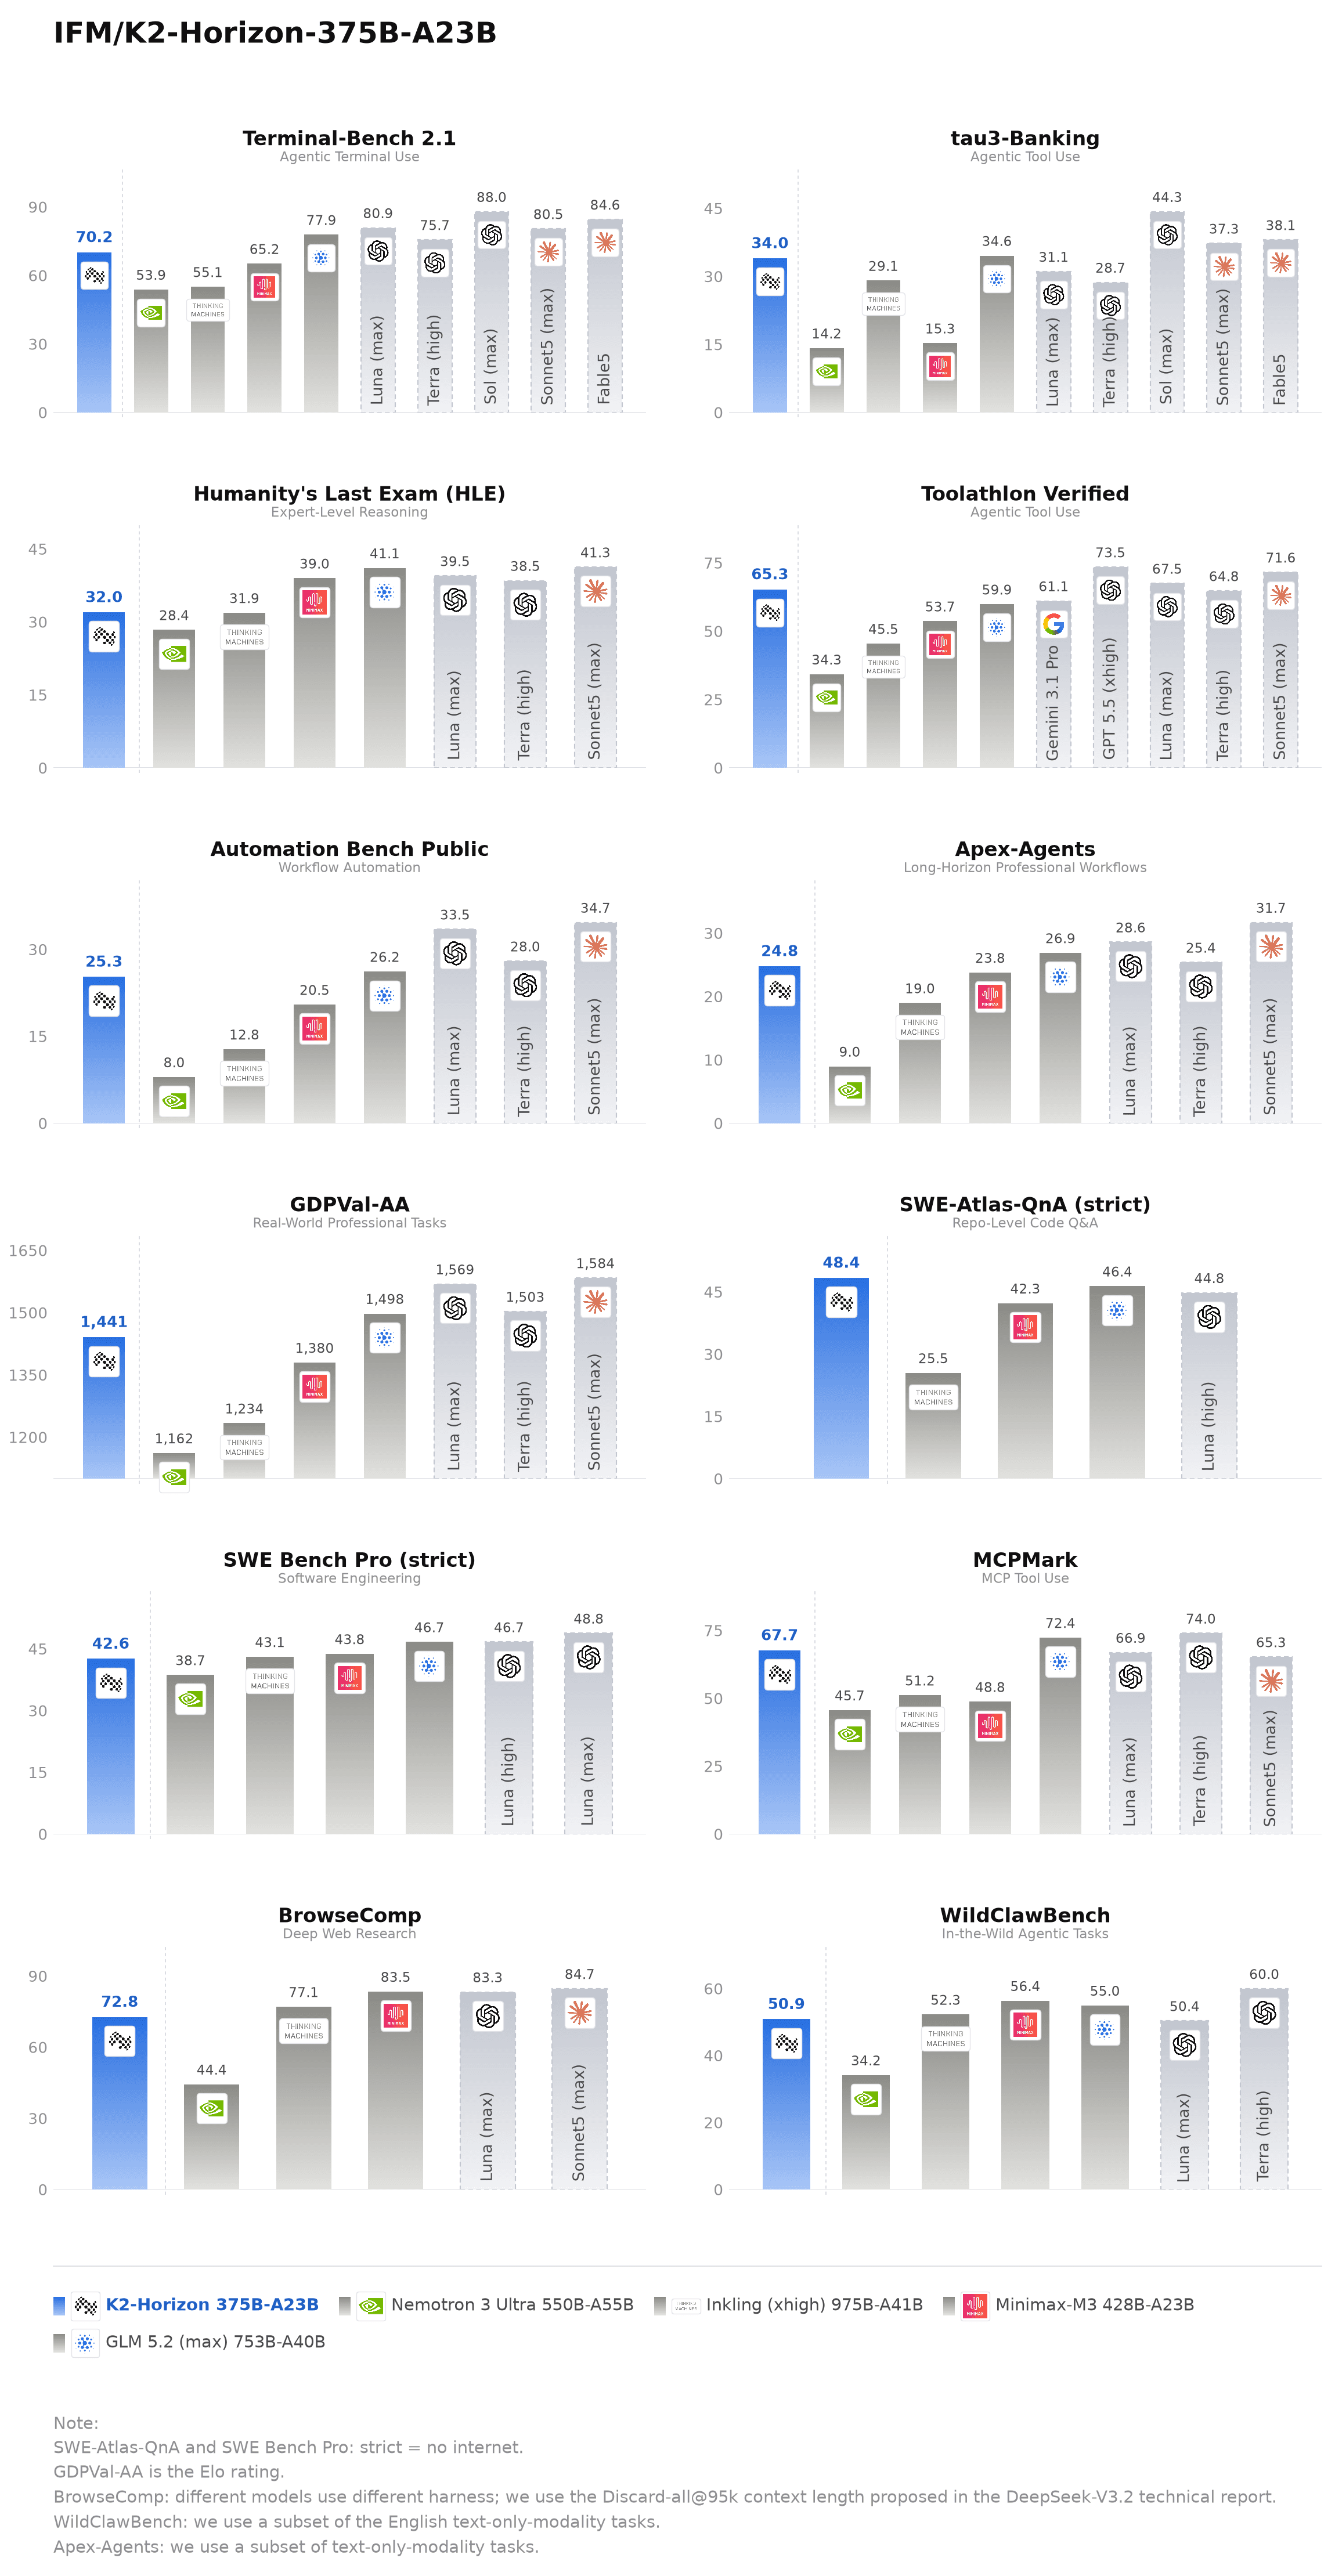
IFM releases K2-Horizon, a 375B open-weight MoE
The flagship model uses a mixture-of-experts design that activates just 23 billion parameters per token, keeping inference costs in check.
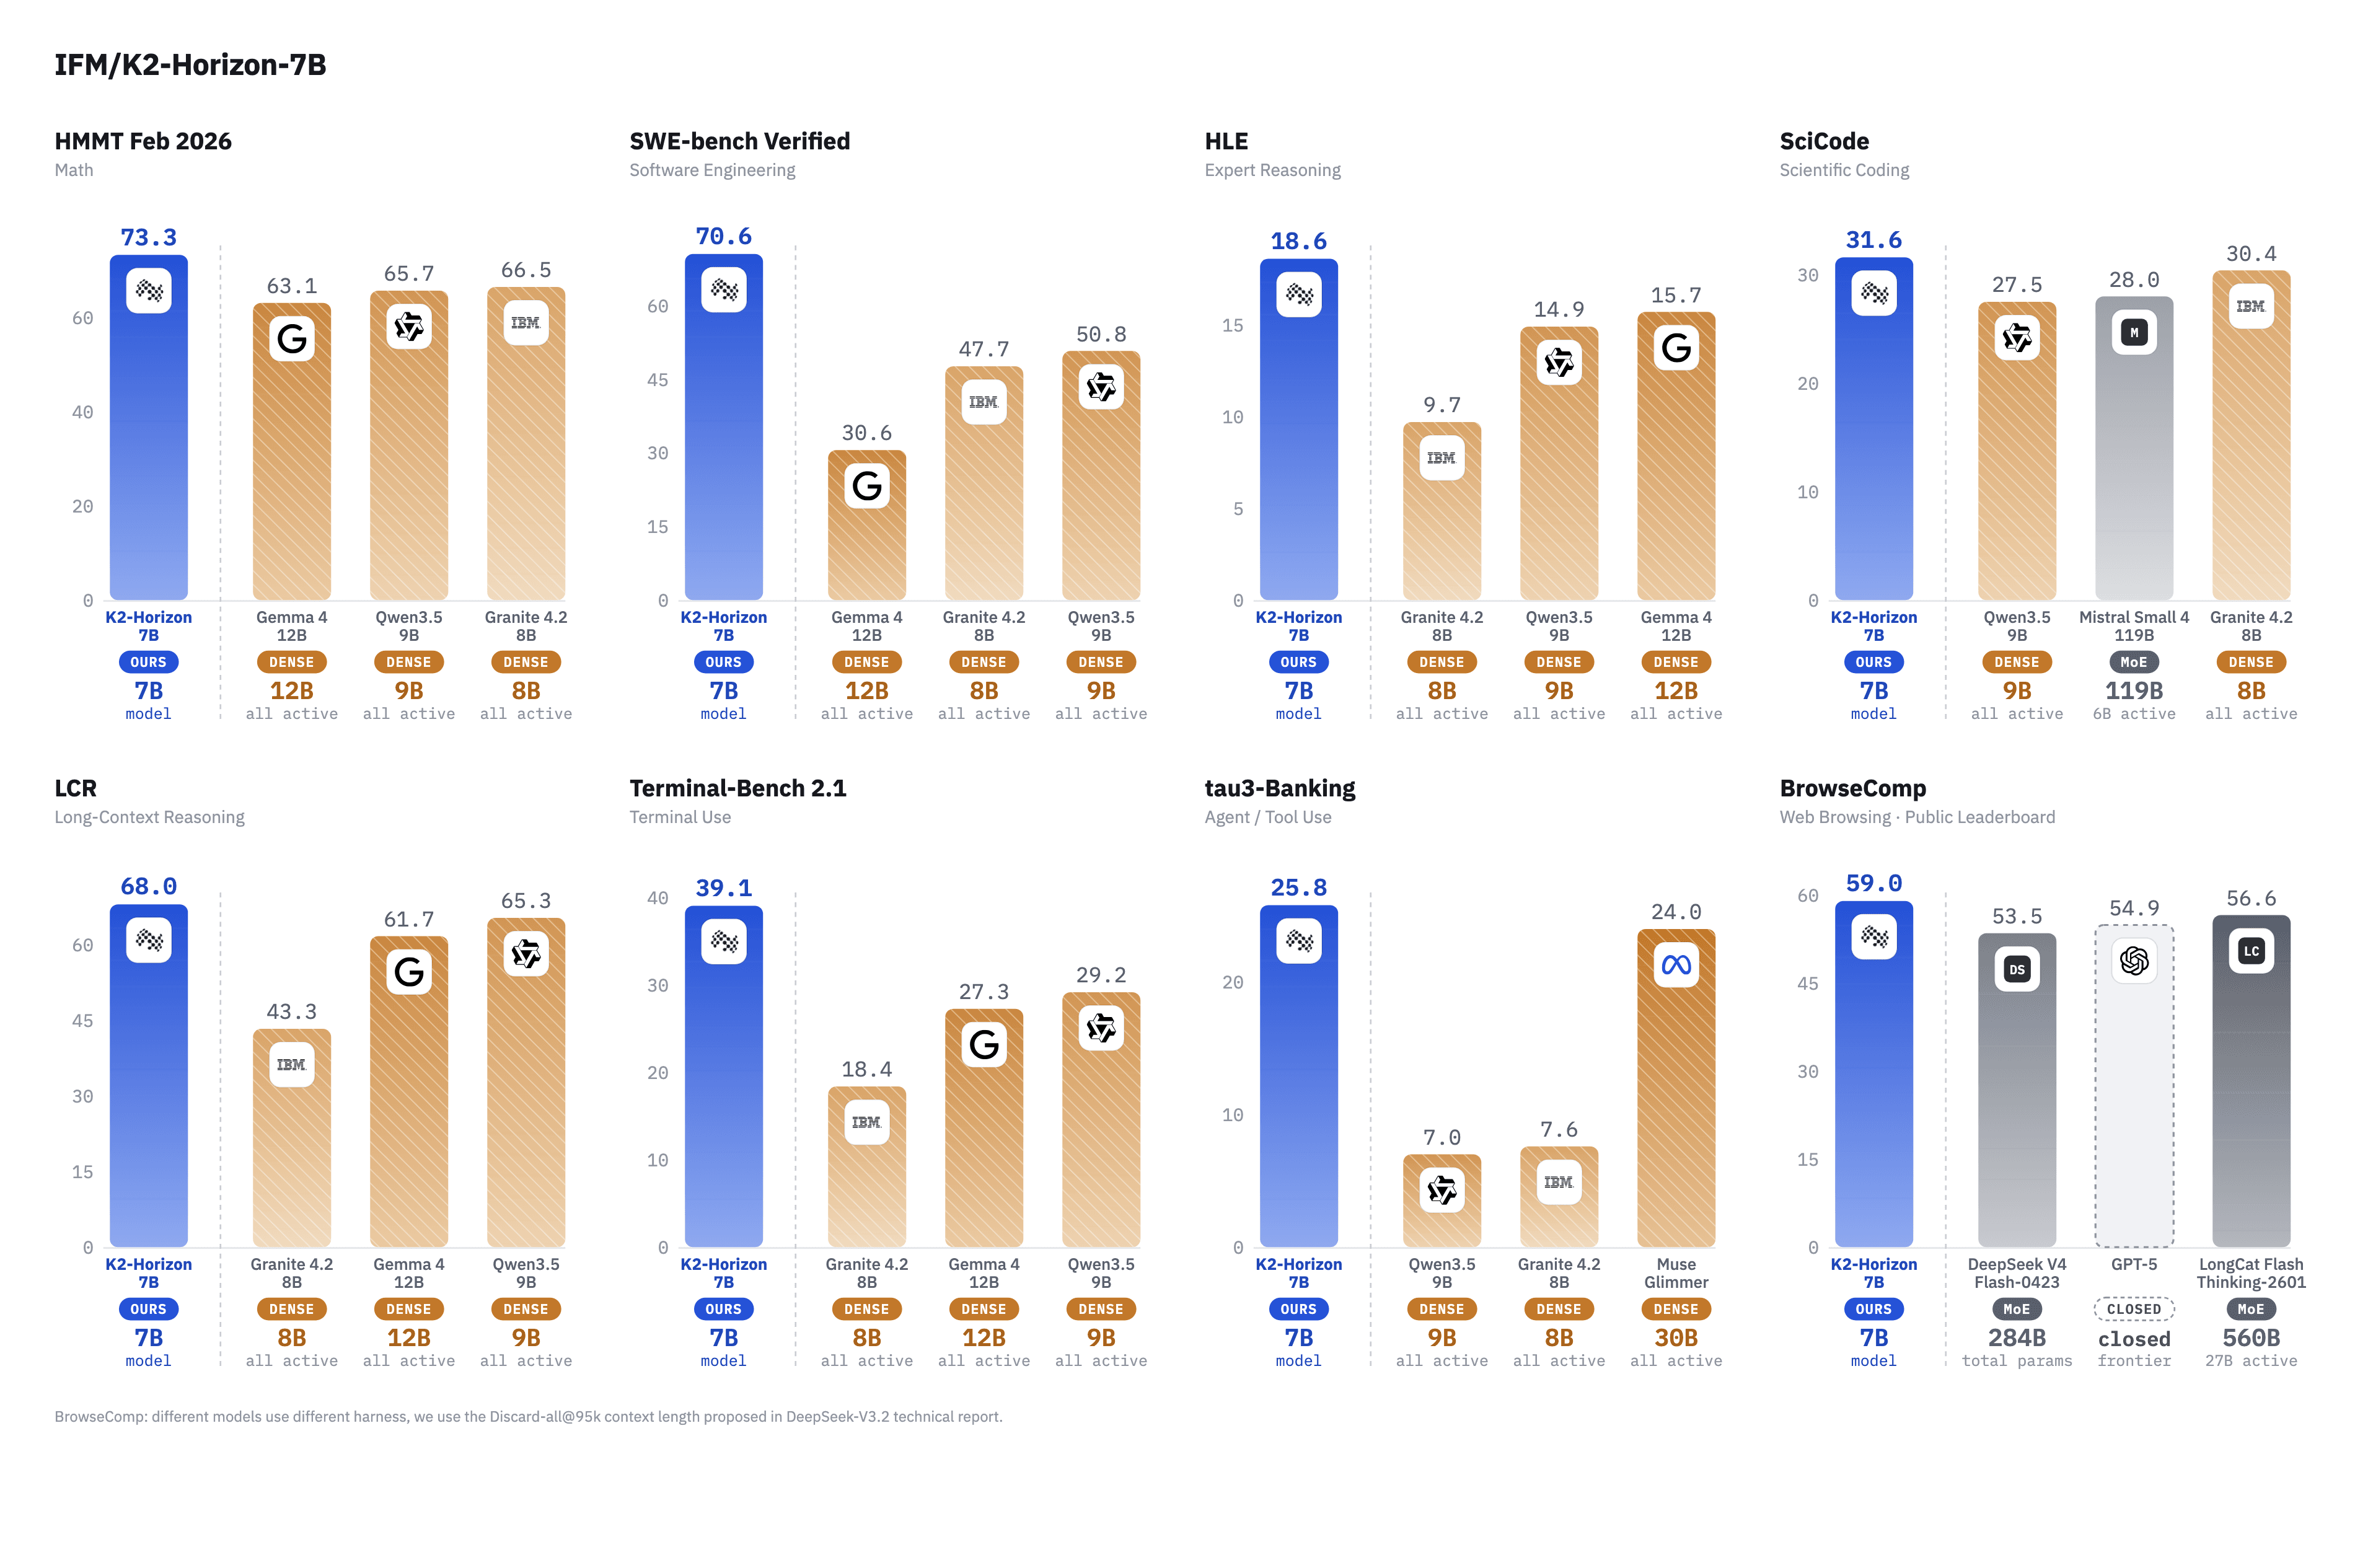
IFM releases K2-Horizon-7B with open pretraining data
The dense 7-billion-parameter model ships as open weights alongside the datasets used to train it.
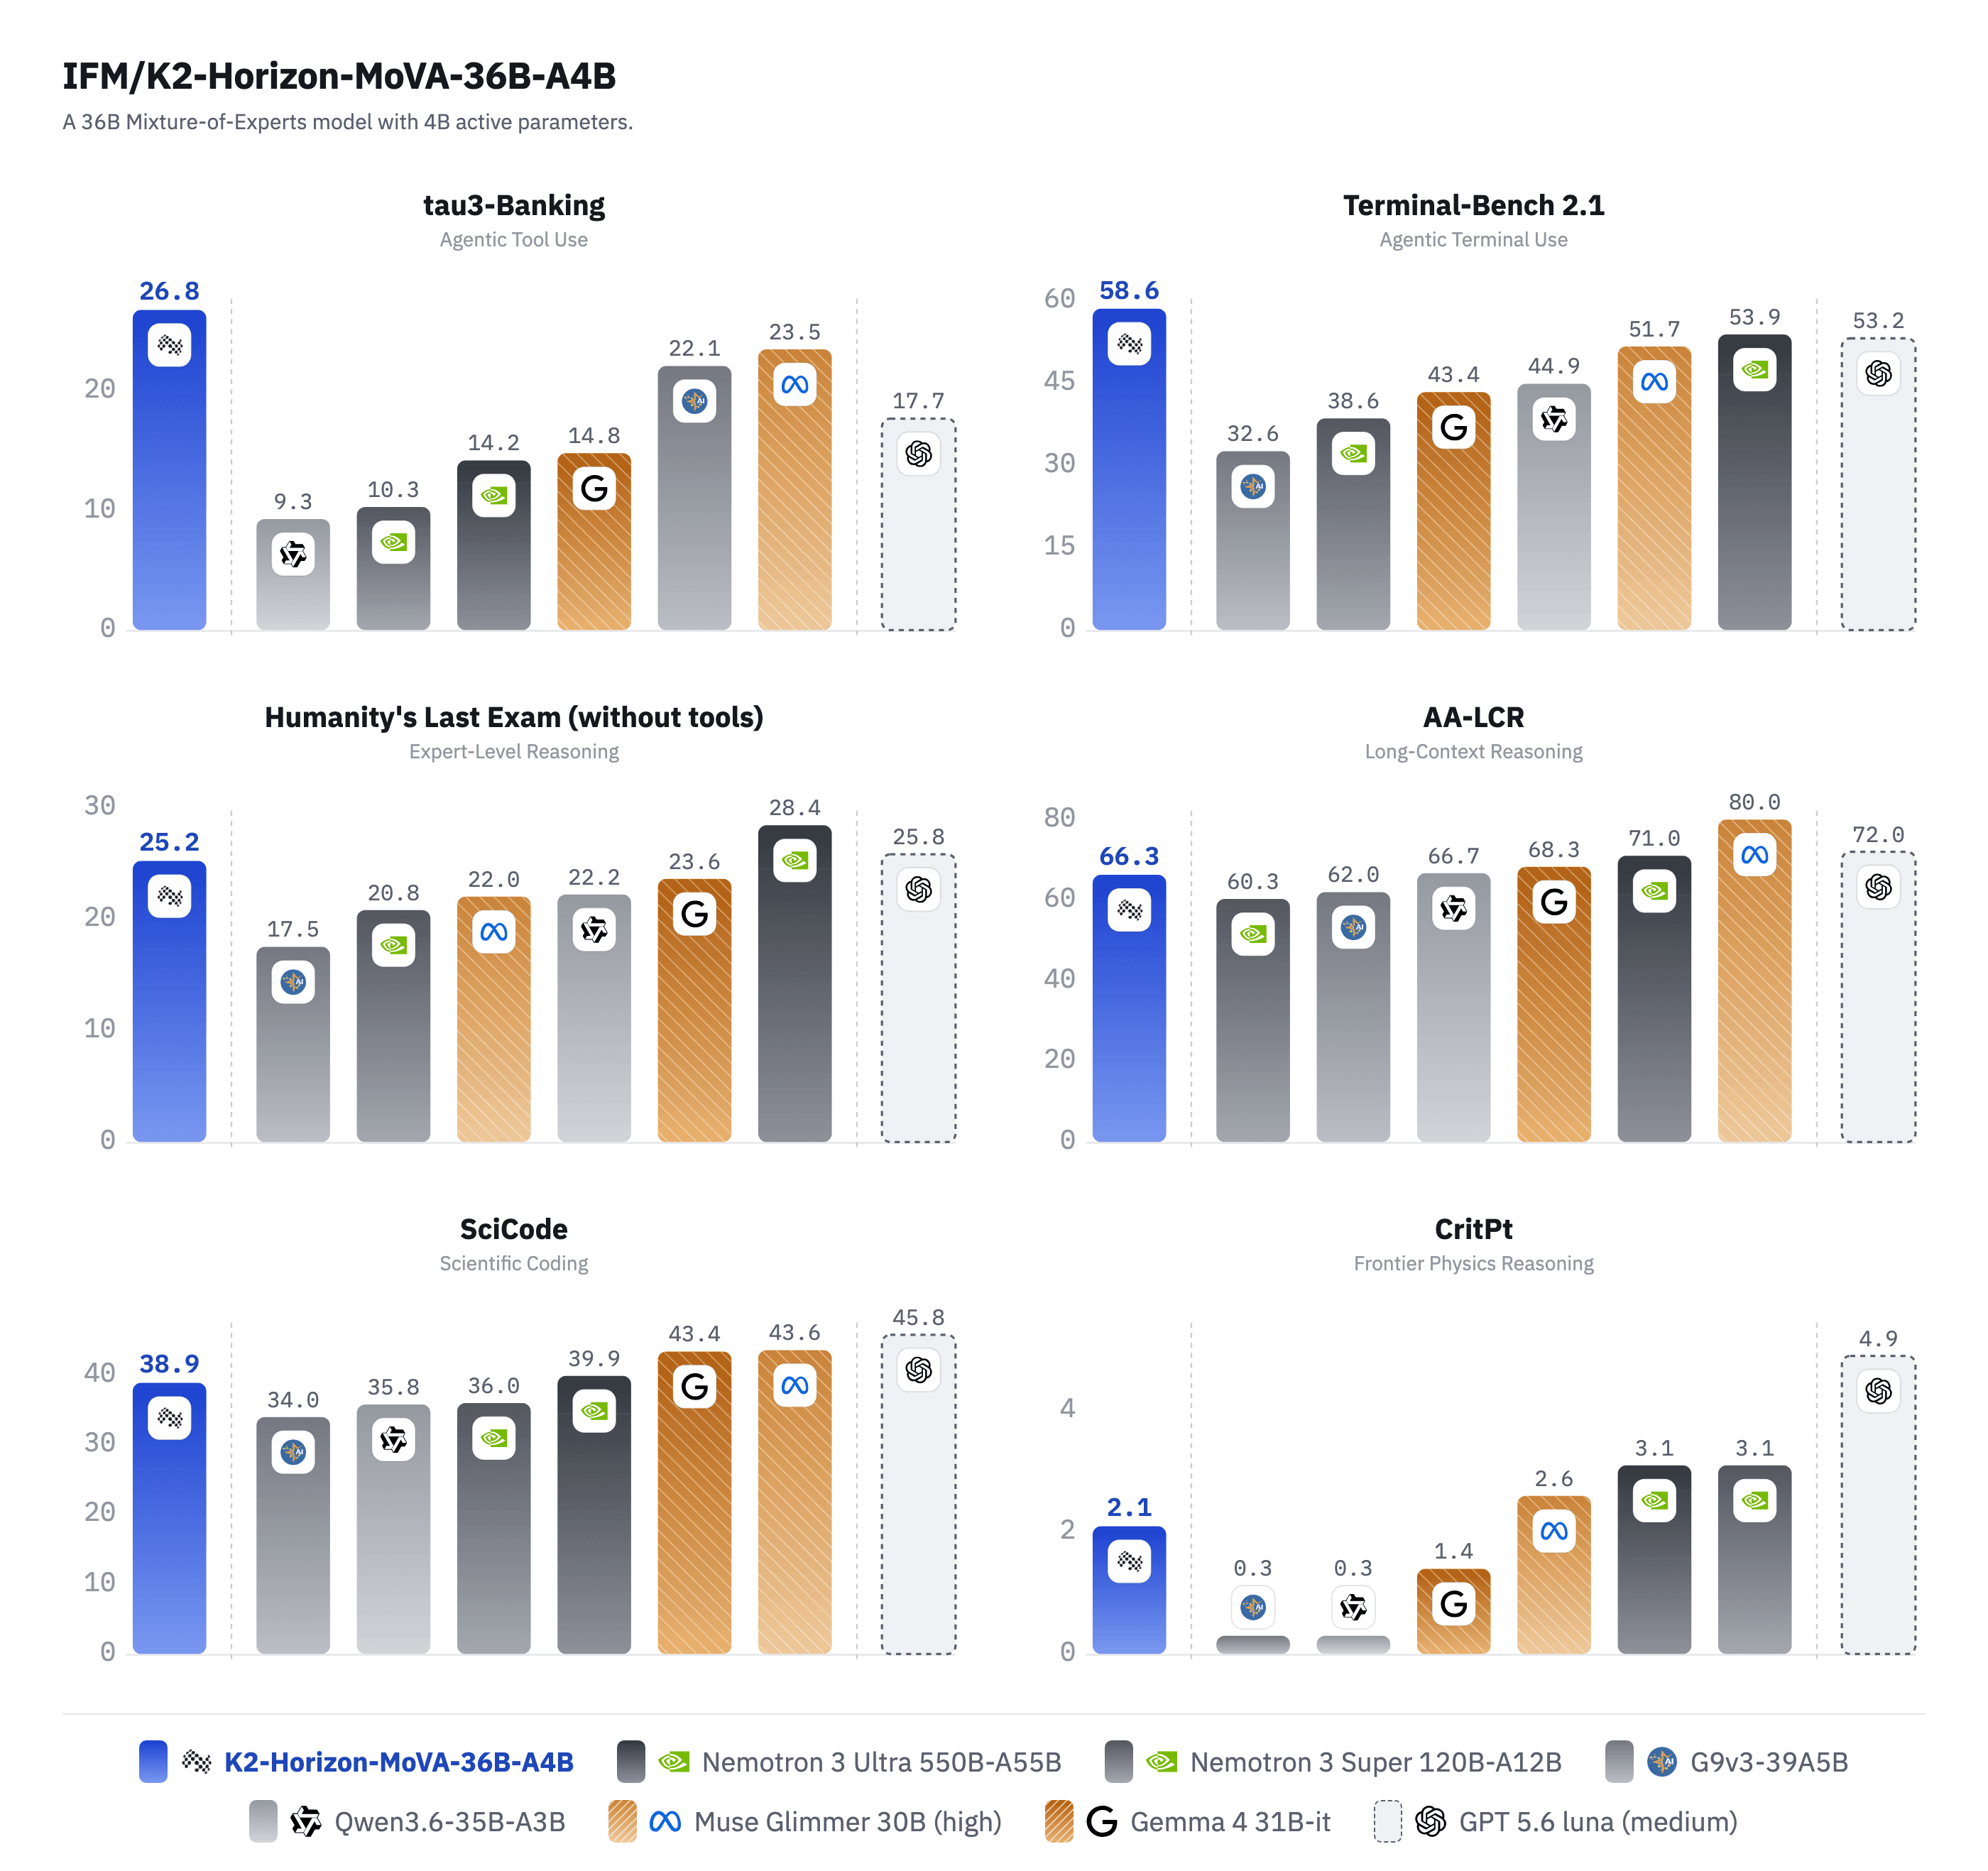
IFM's K2-Horizon MoVA Ships as a 36B MoE Model
The open-weight language model activates just 4B of its 36B parameters per token, aiming for efficiency without shedding capacity.
More in Image → Video
All Image → Video →
Meituan's LongCat Adds Audio-Driven Avatar Video
The LongCat team releases an image-to-video model that animates still portraits from audio input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
0 comments
No comments yet. Be the first to weigh in.