IFM releases K2-Horizon, a 375B open-weight MoE
The flagship model uses a mixture-of-experts design that activates just 23 billion parameters per token, keeping inference costs in check.
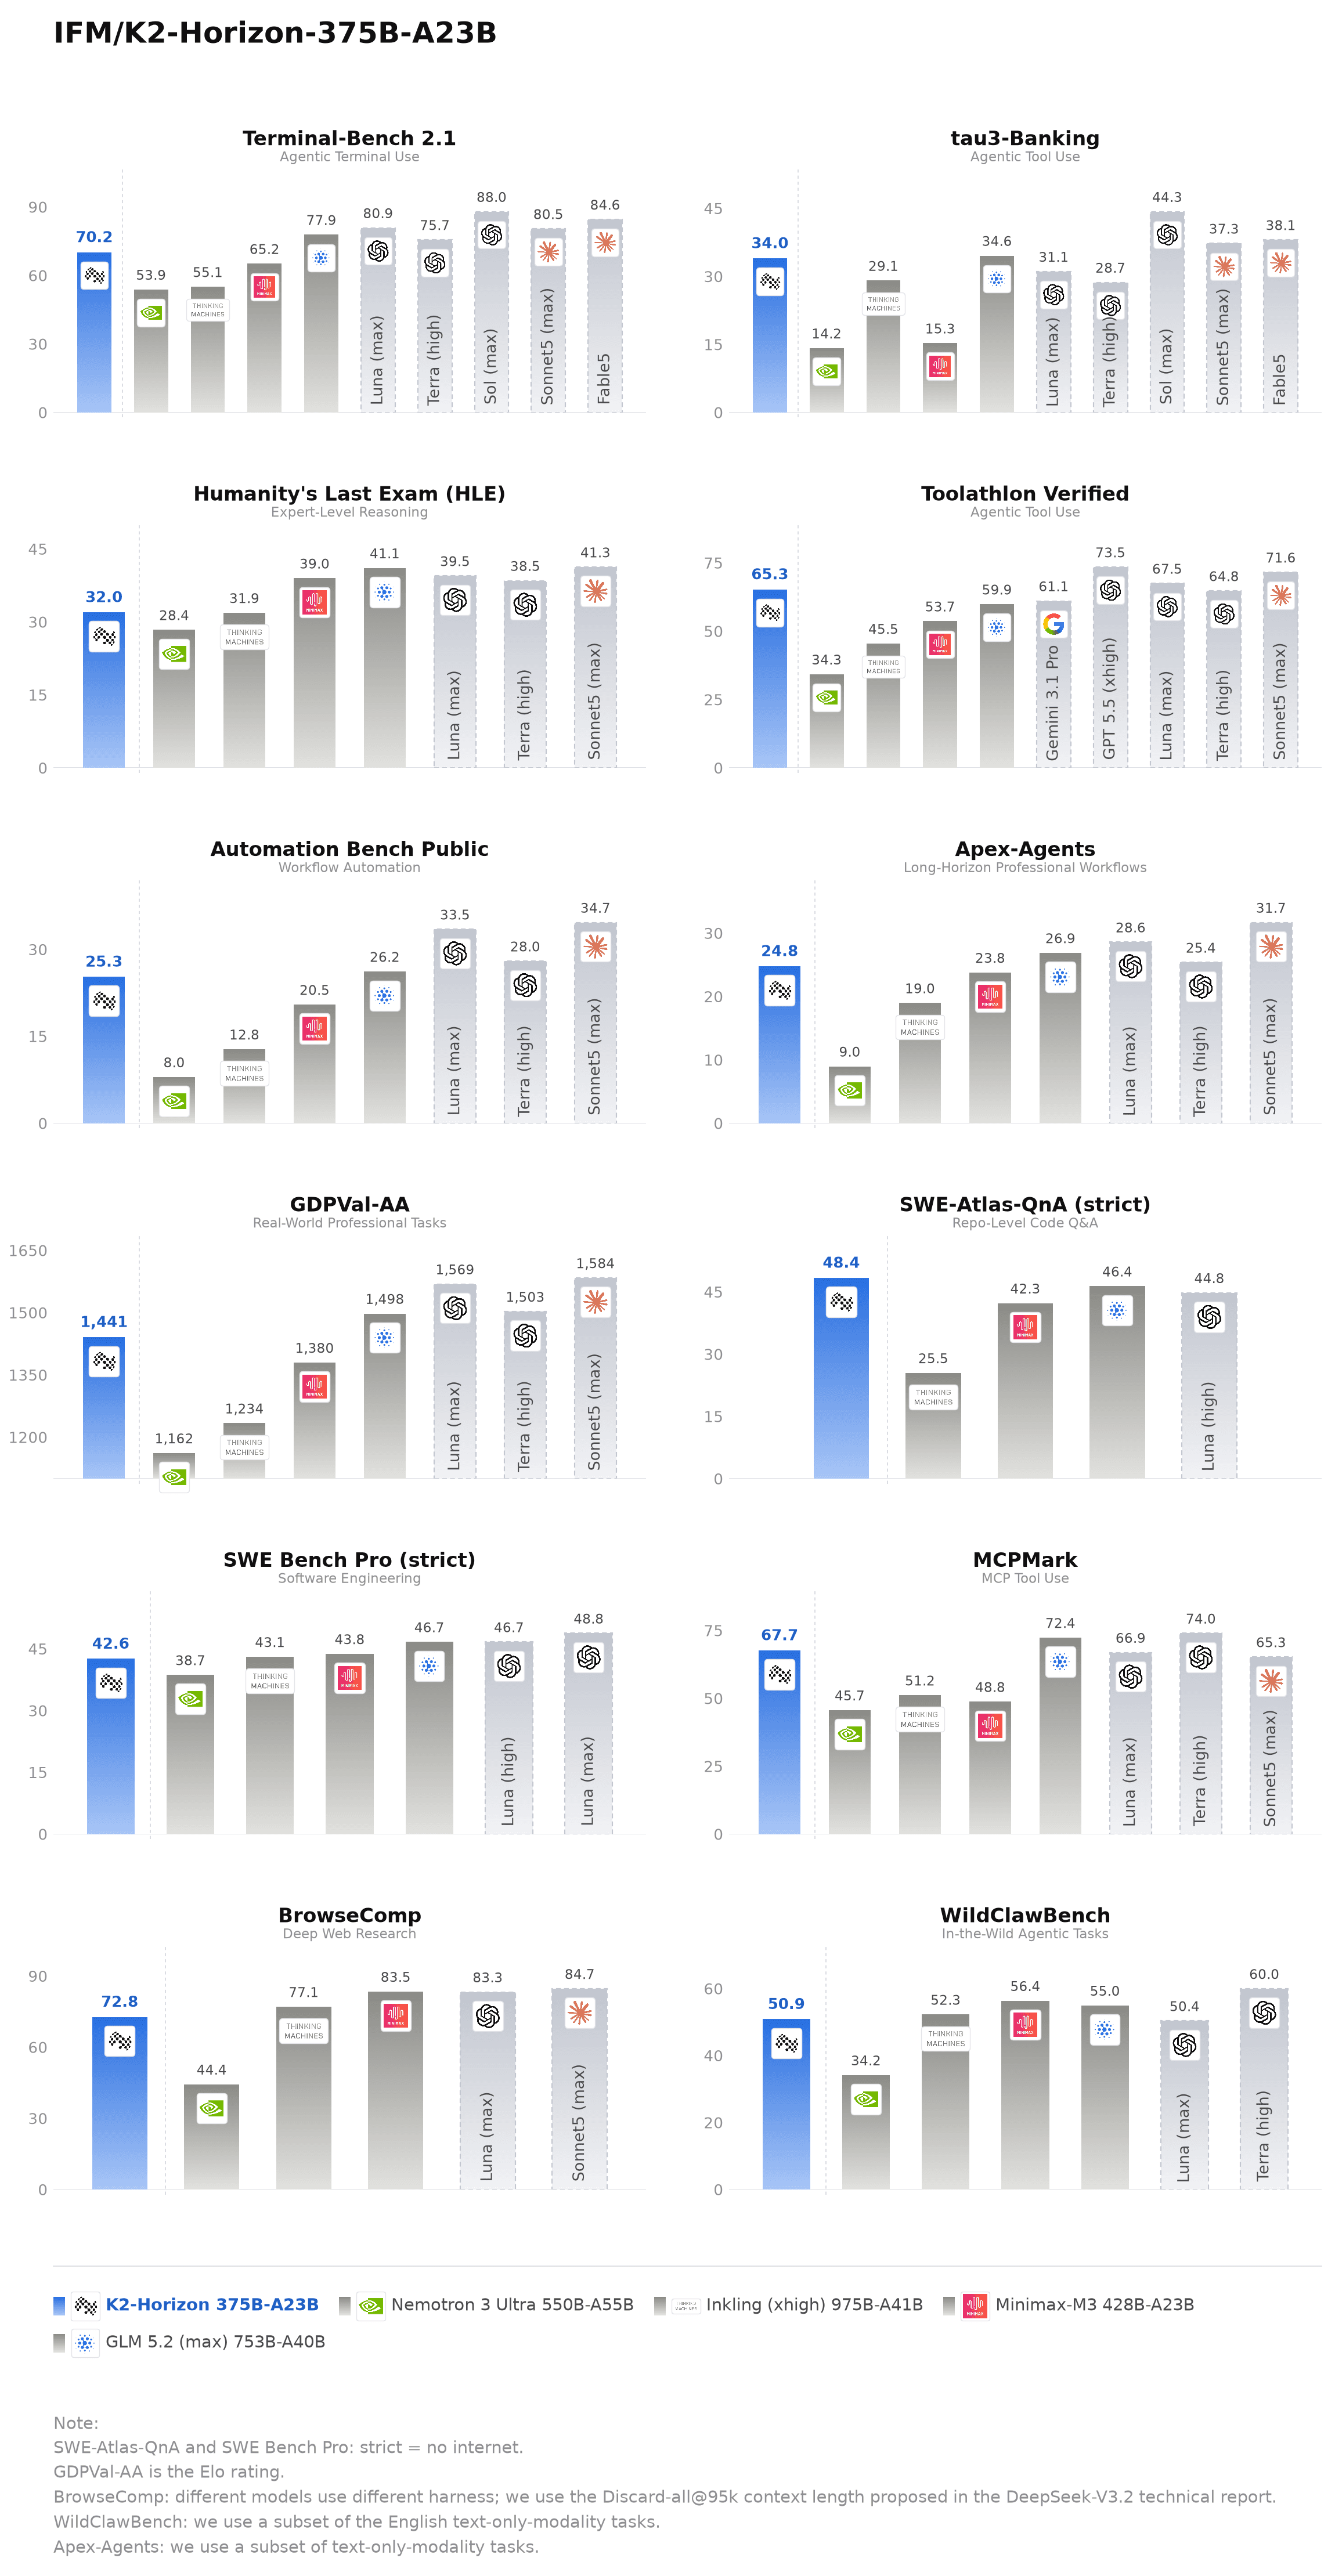
IFM has published K2-Horizon-375B-A23B, an open-weight large language model built around a mixture-of-experts (MoE) architecture. The model spans 375 billion total parameters but activates roughly 23 billion for any given token, a design meant to deliver the capacity of a very large model without paying the full compute bill on every forward pass. The weights are available on Hugging Face.
The release is positioned as a flagship, and IFM lists reasoning alongside general text generation among its intended strengths. That framing puts K2-Horizon in the same competitive lane as other large open MoE systems that have leaned on sparse activation to scale parameter counts while holding inference latency down.
Why it matters
Sparse MoE models have become the default strategy for teams that want frontier-scale capacity on a realistic serving budget. A 375B model that runs like a 23B one at inference time is far more approachable for organizations that can host it themselves, and open weights let them fine-tune and deploy without an API dependency.
A few practical notes for anyone evaluating it:
- Total vs. active parameters: 375B total, ~23B active per token.
- Architecture: mixture-of-experts, aimed at text and reasoning tasks.
- Licensing: listed as "other," so teams should review the terms on the model page before commercial use.
As with any fresh release, the real test will be independent benchmarking and community fine-tunes. For now, the model is live and downloadable, and the details on the Hugging Face repository are the authoritative reference.
Sources
- Visit
IFM/K2-Horizon-375B-A23B
Hugging Face
More from IFM
All IFM releases →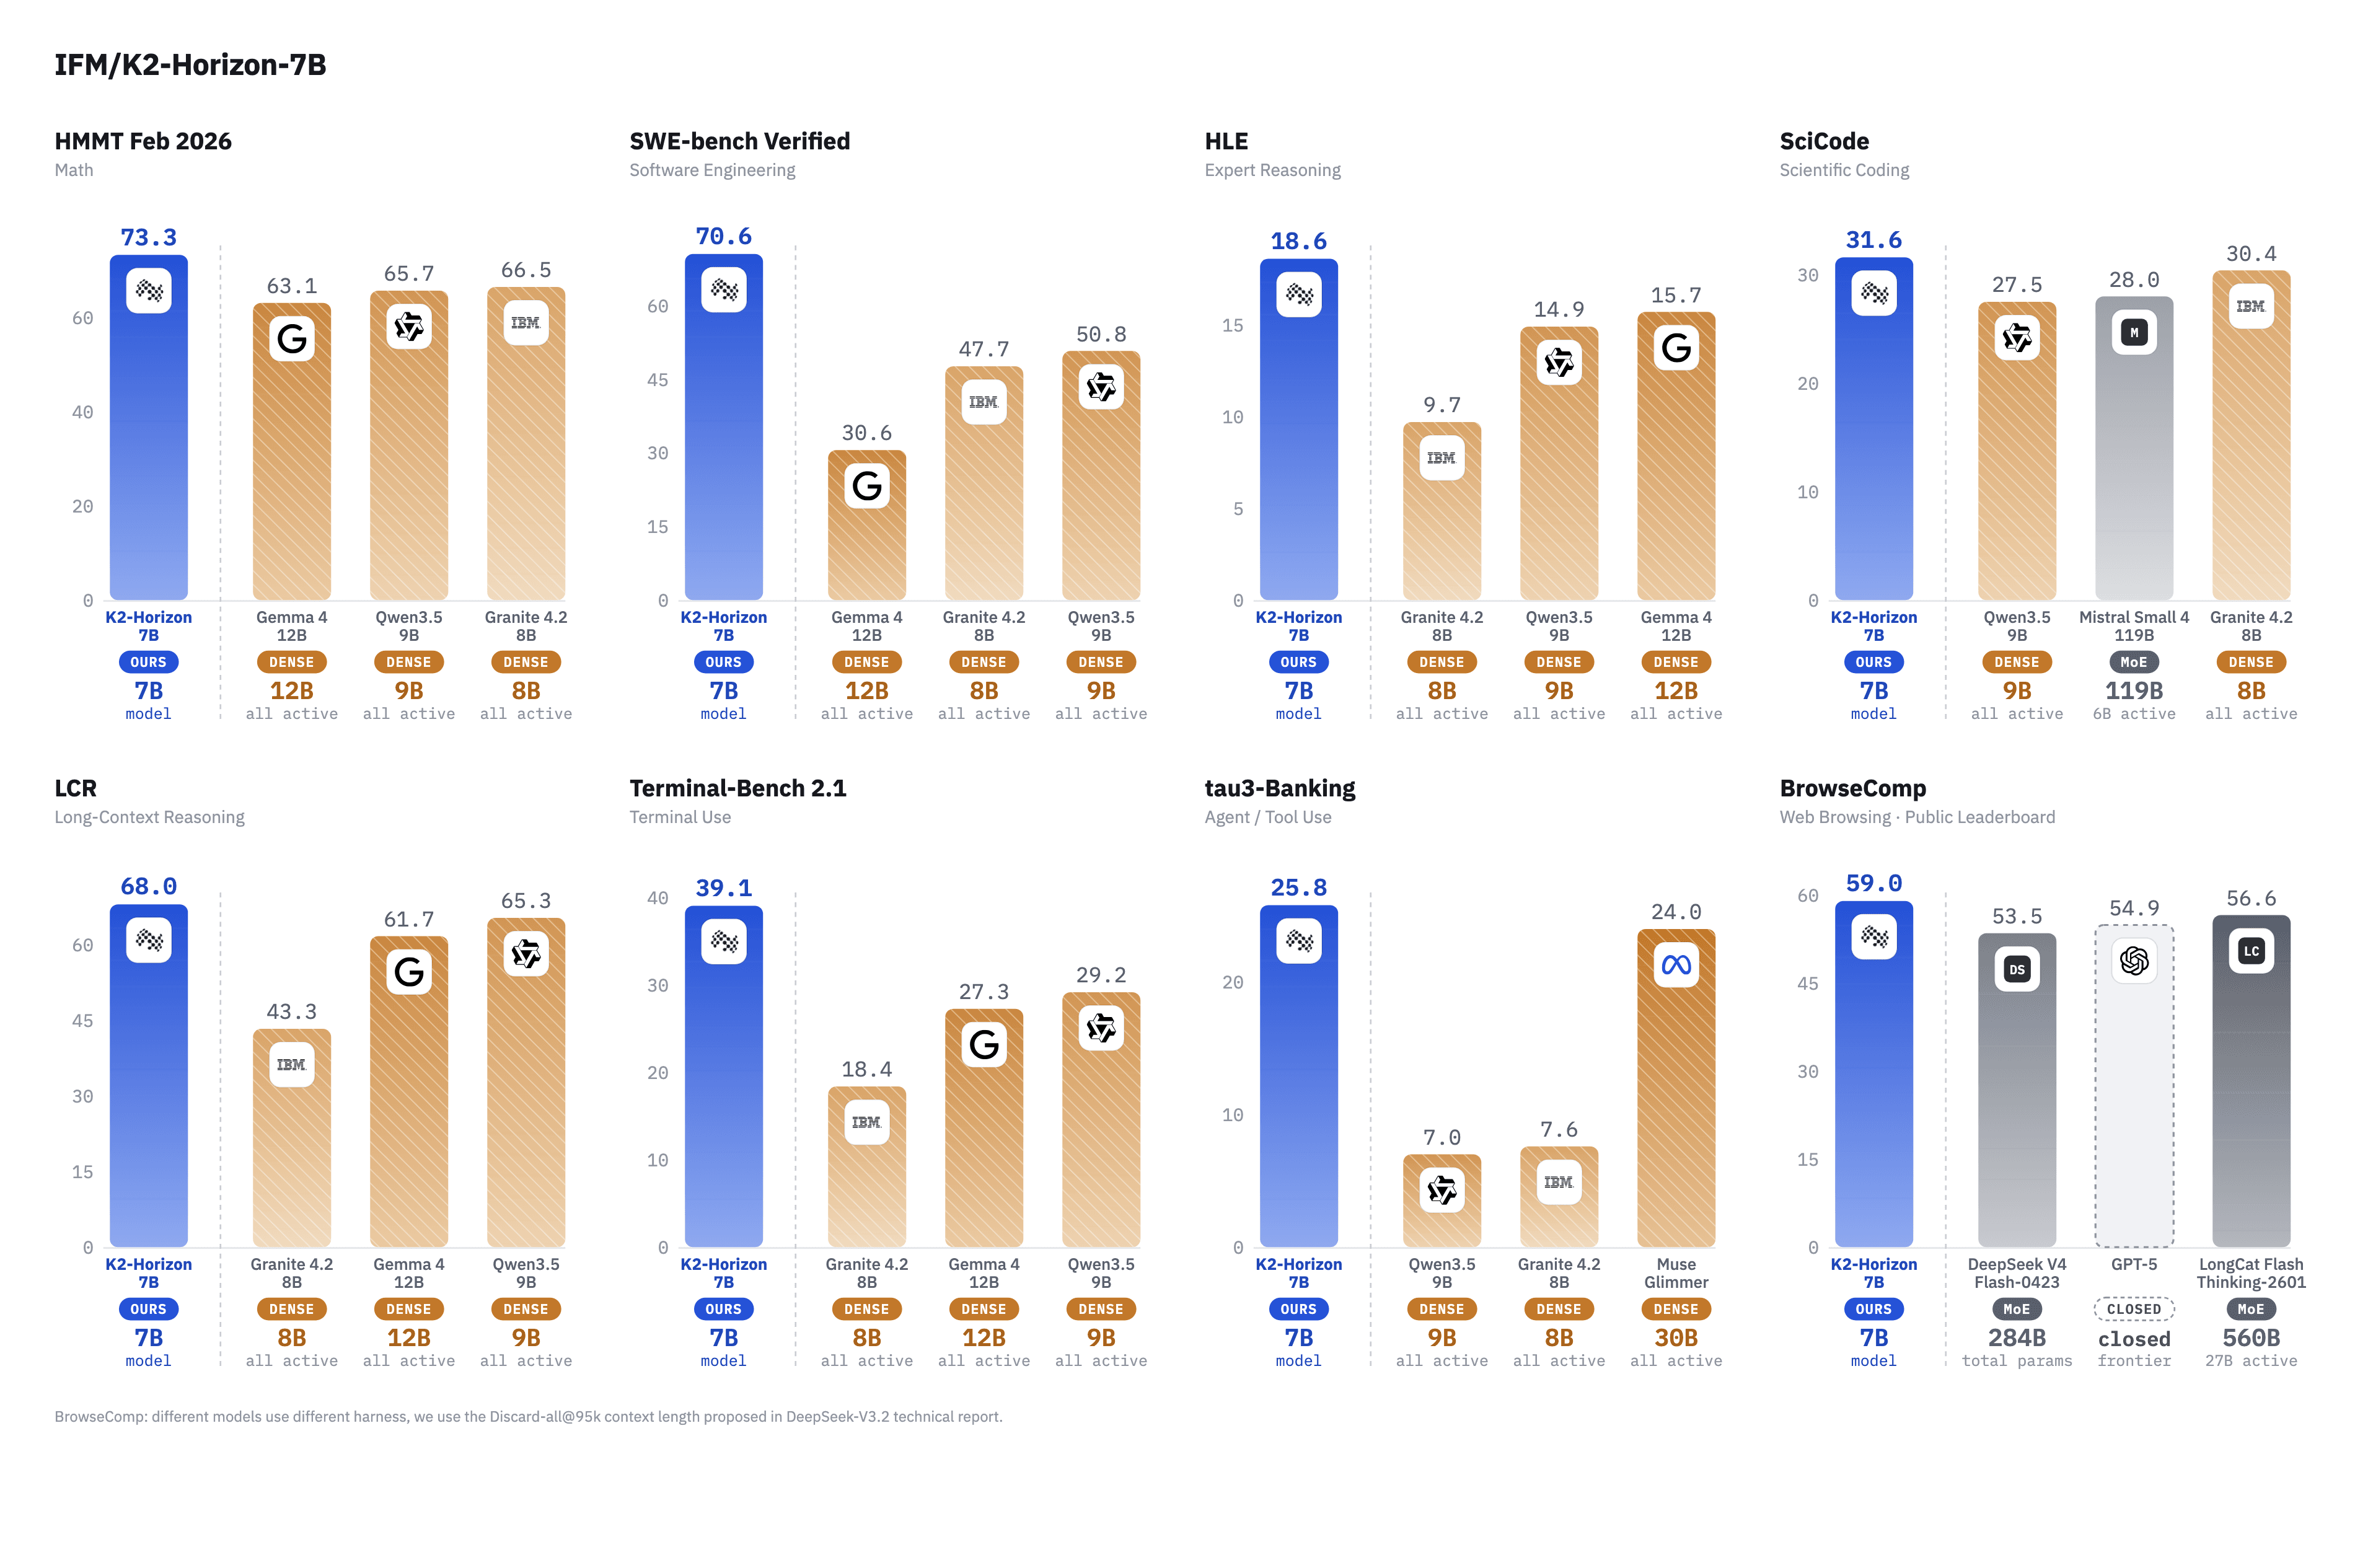
IFM releases K2-Horizon-7B with open pretraining data
The dense 7-billion-parameter model ships as open weights alongside the datasets used to train it.
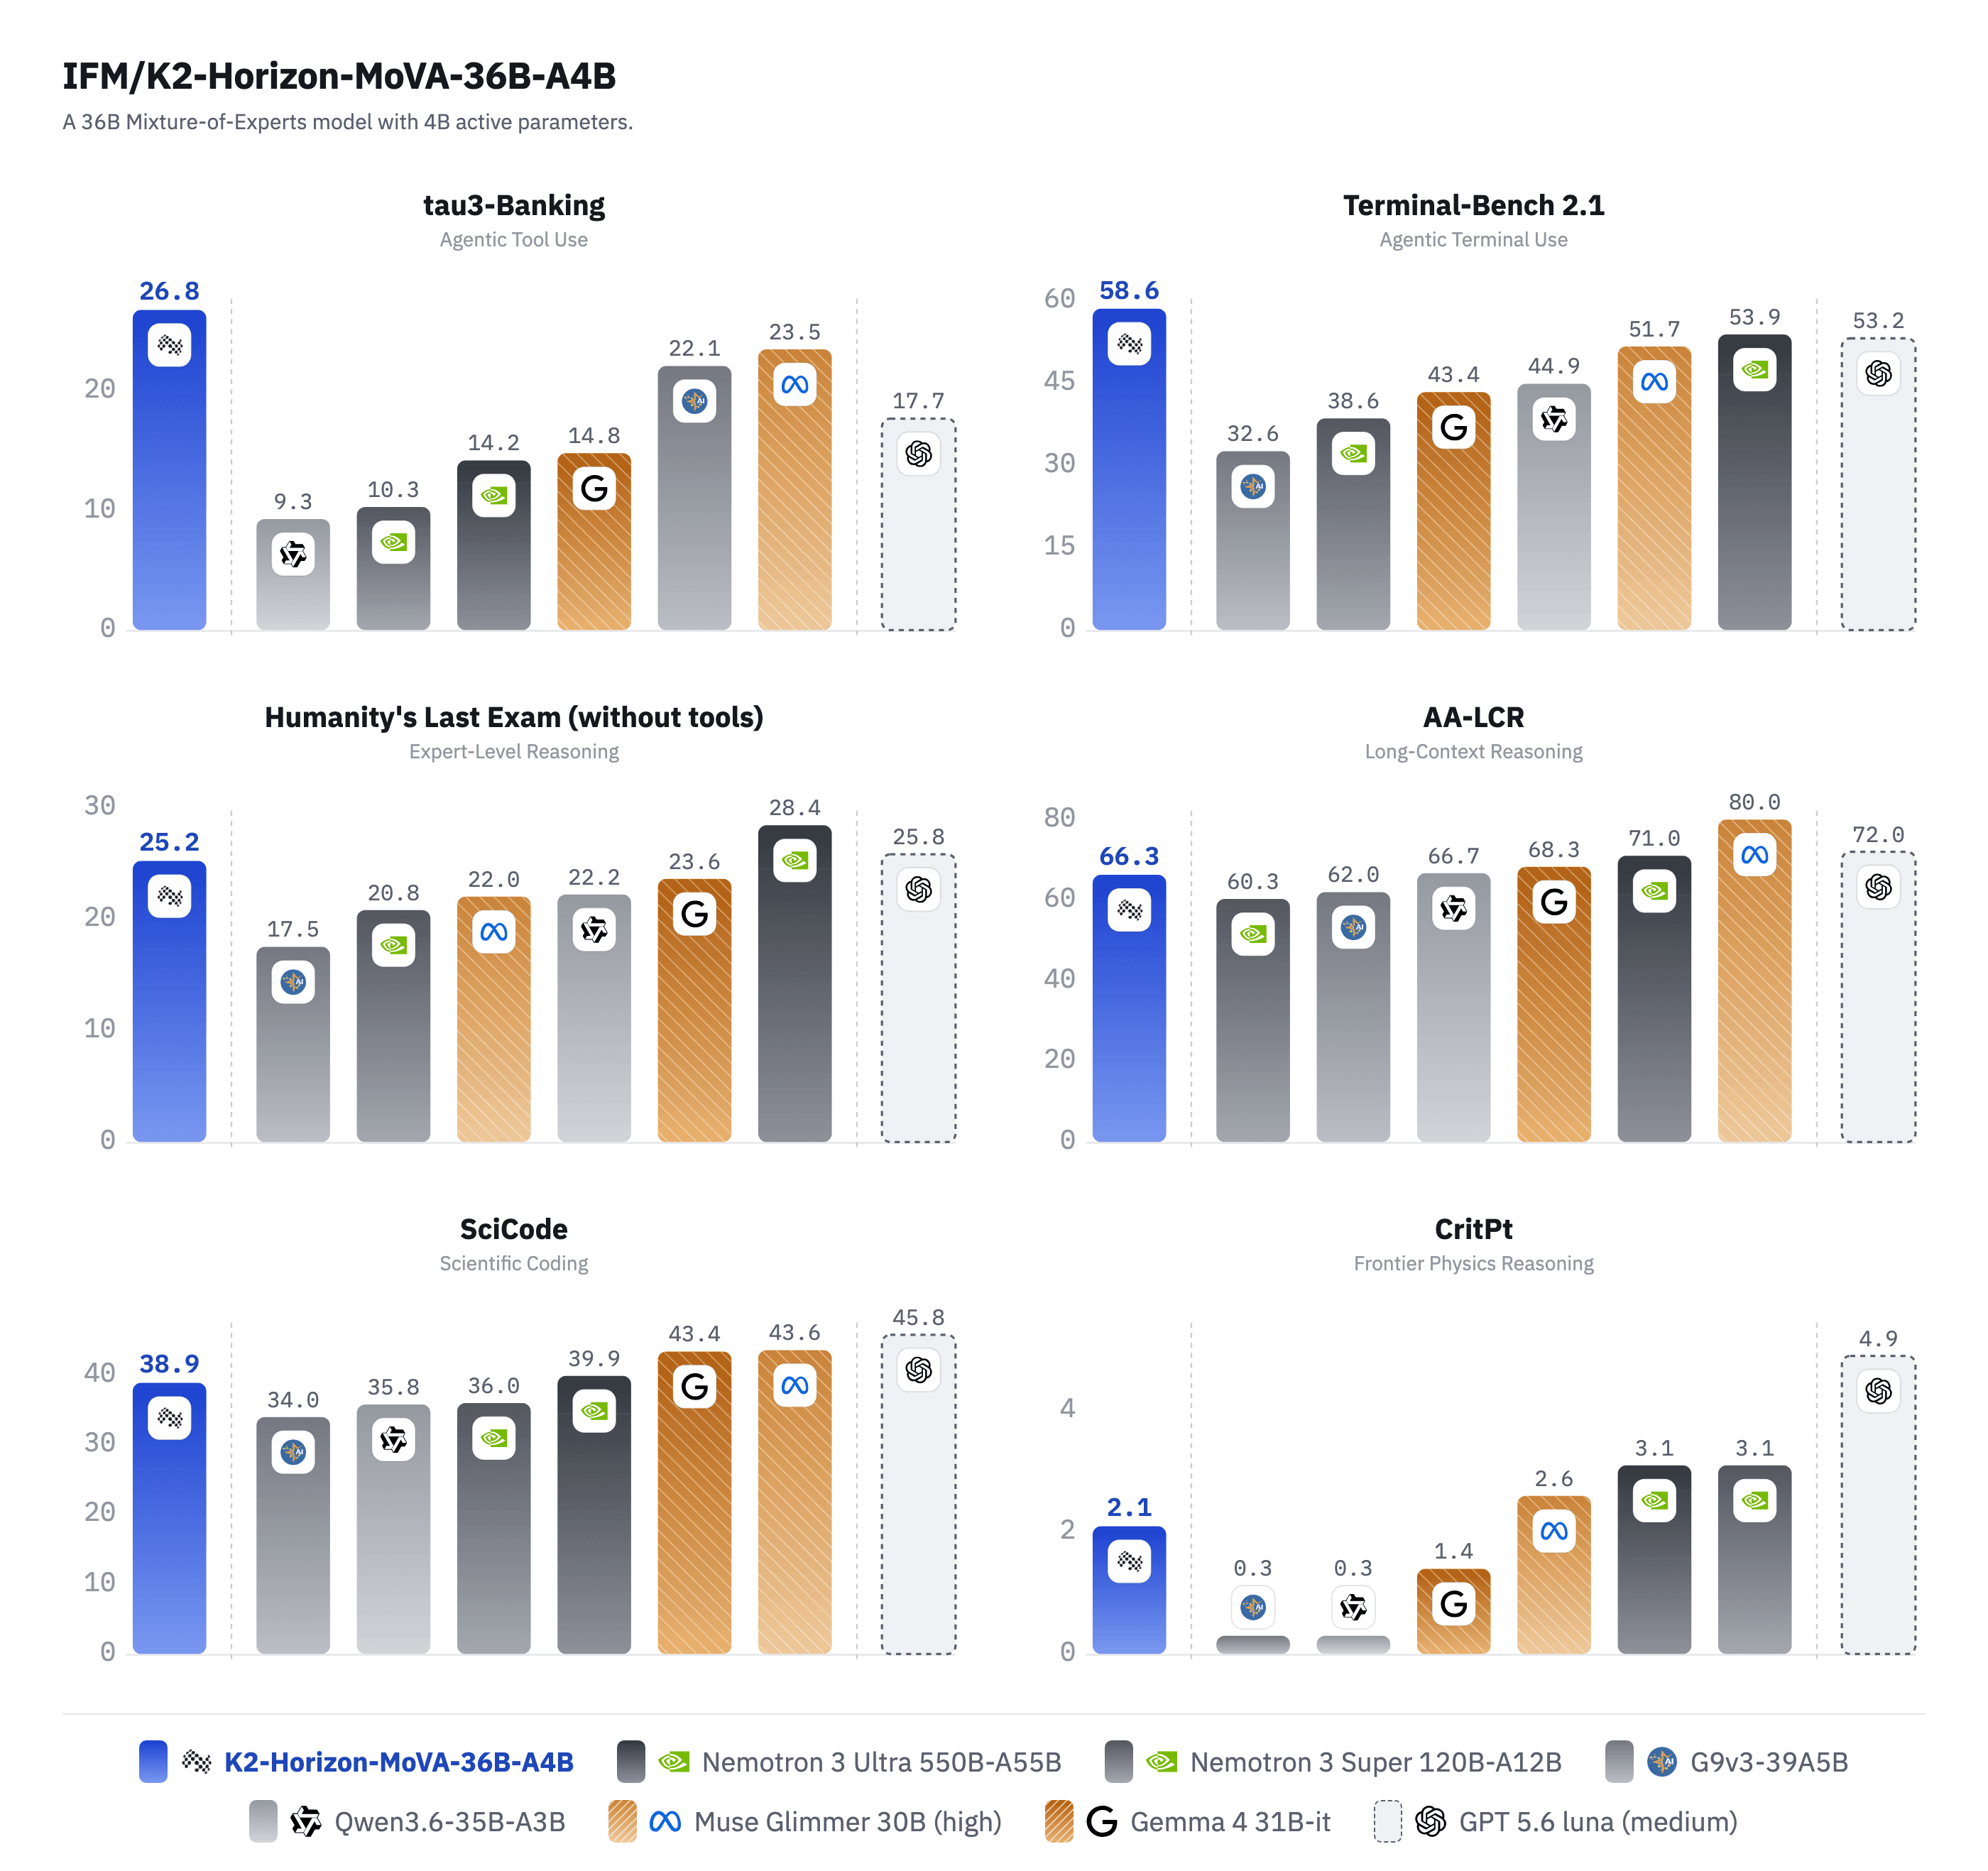
IFM's K2-Horizon MoVA Ships as a 36B MoE Model
The open-weight language model activates just 4B of its 36B parameters per token, aiming for efficiency without shedding capacity.
More in Text / LLM
All Text / LLM →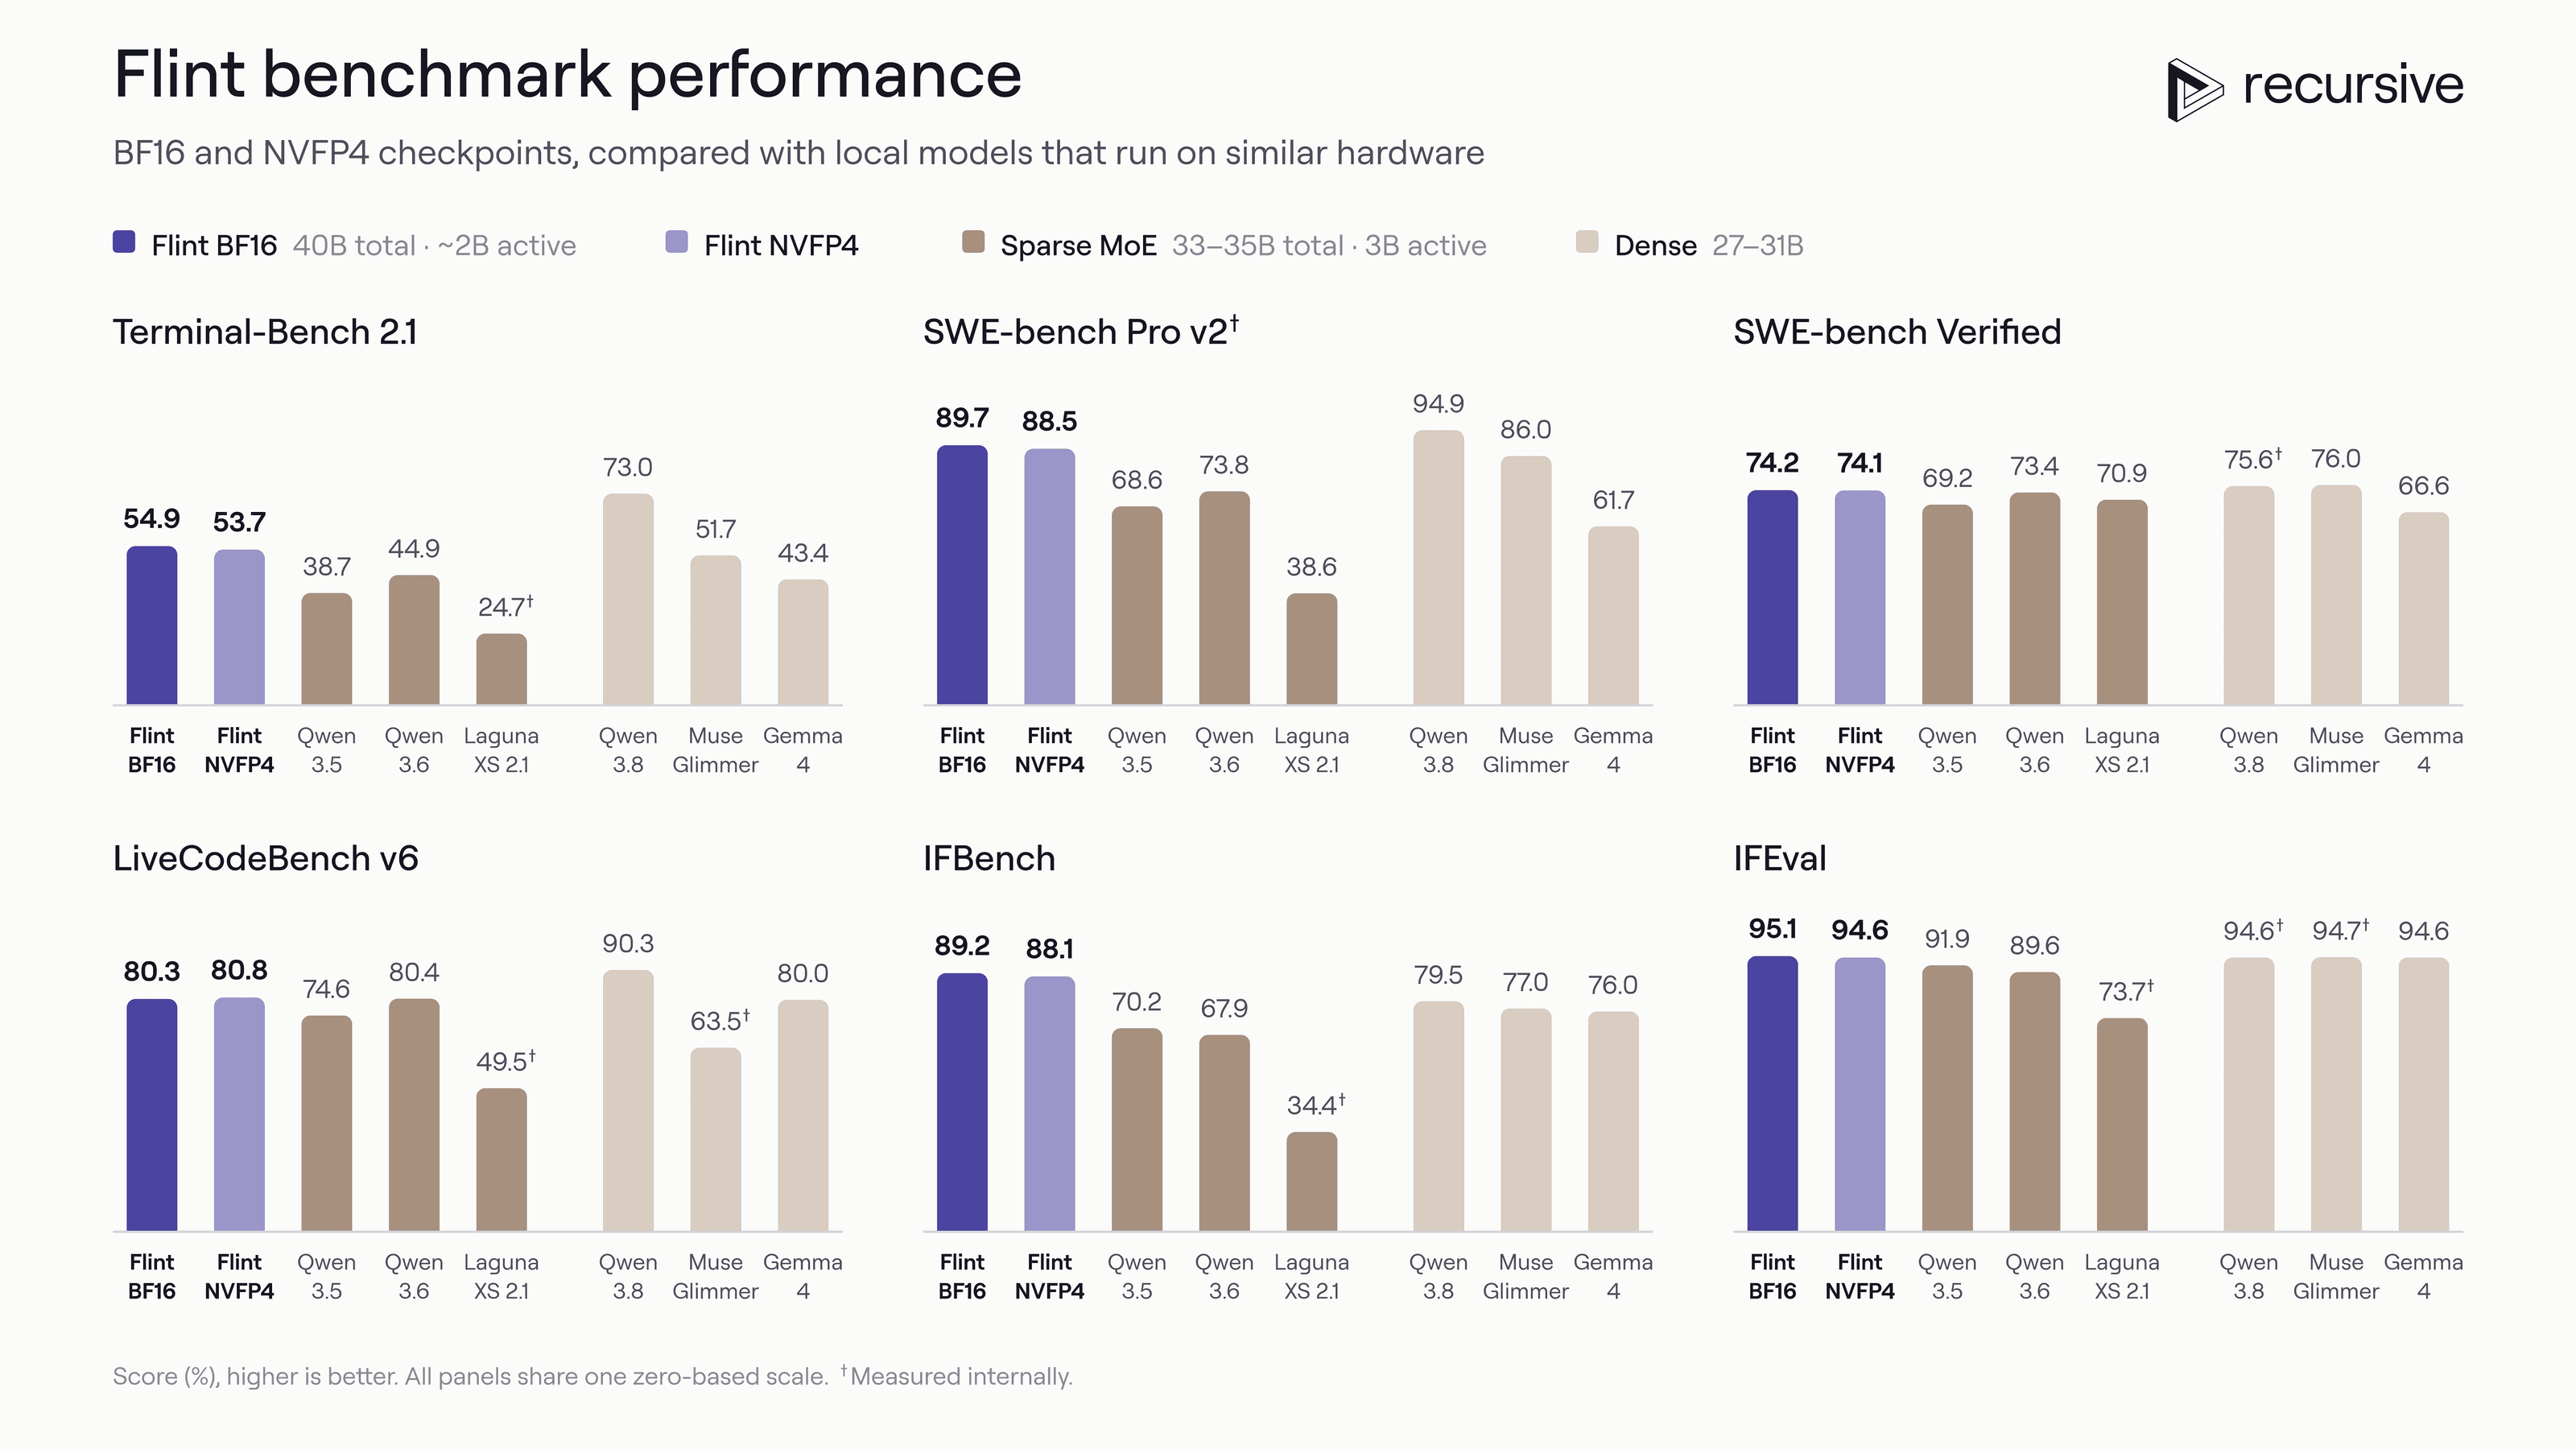
Recursive releases Flint, an Apache-2.0 chat model
The new conversational LLM ships under a permissive license with community GGUF builds already available for local use.
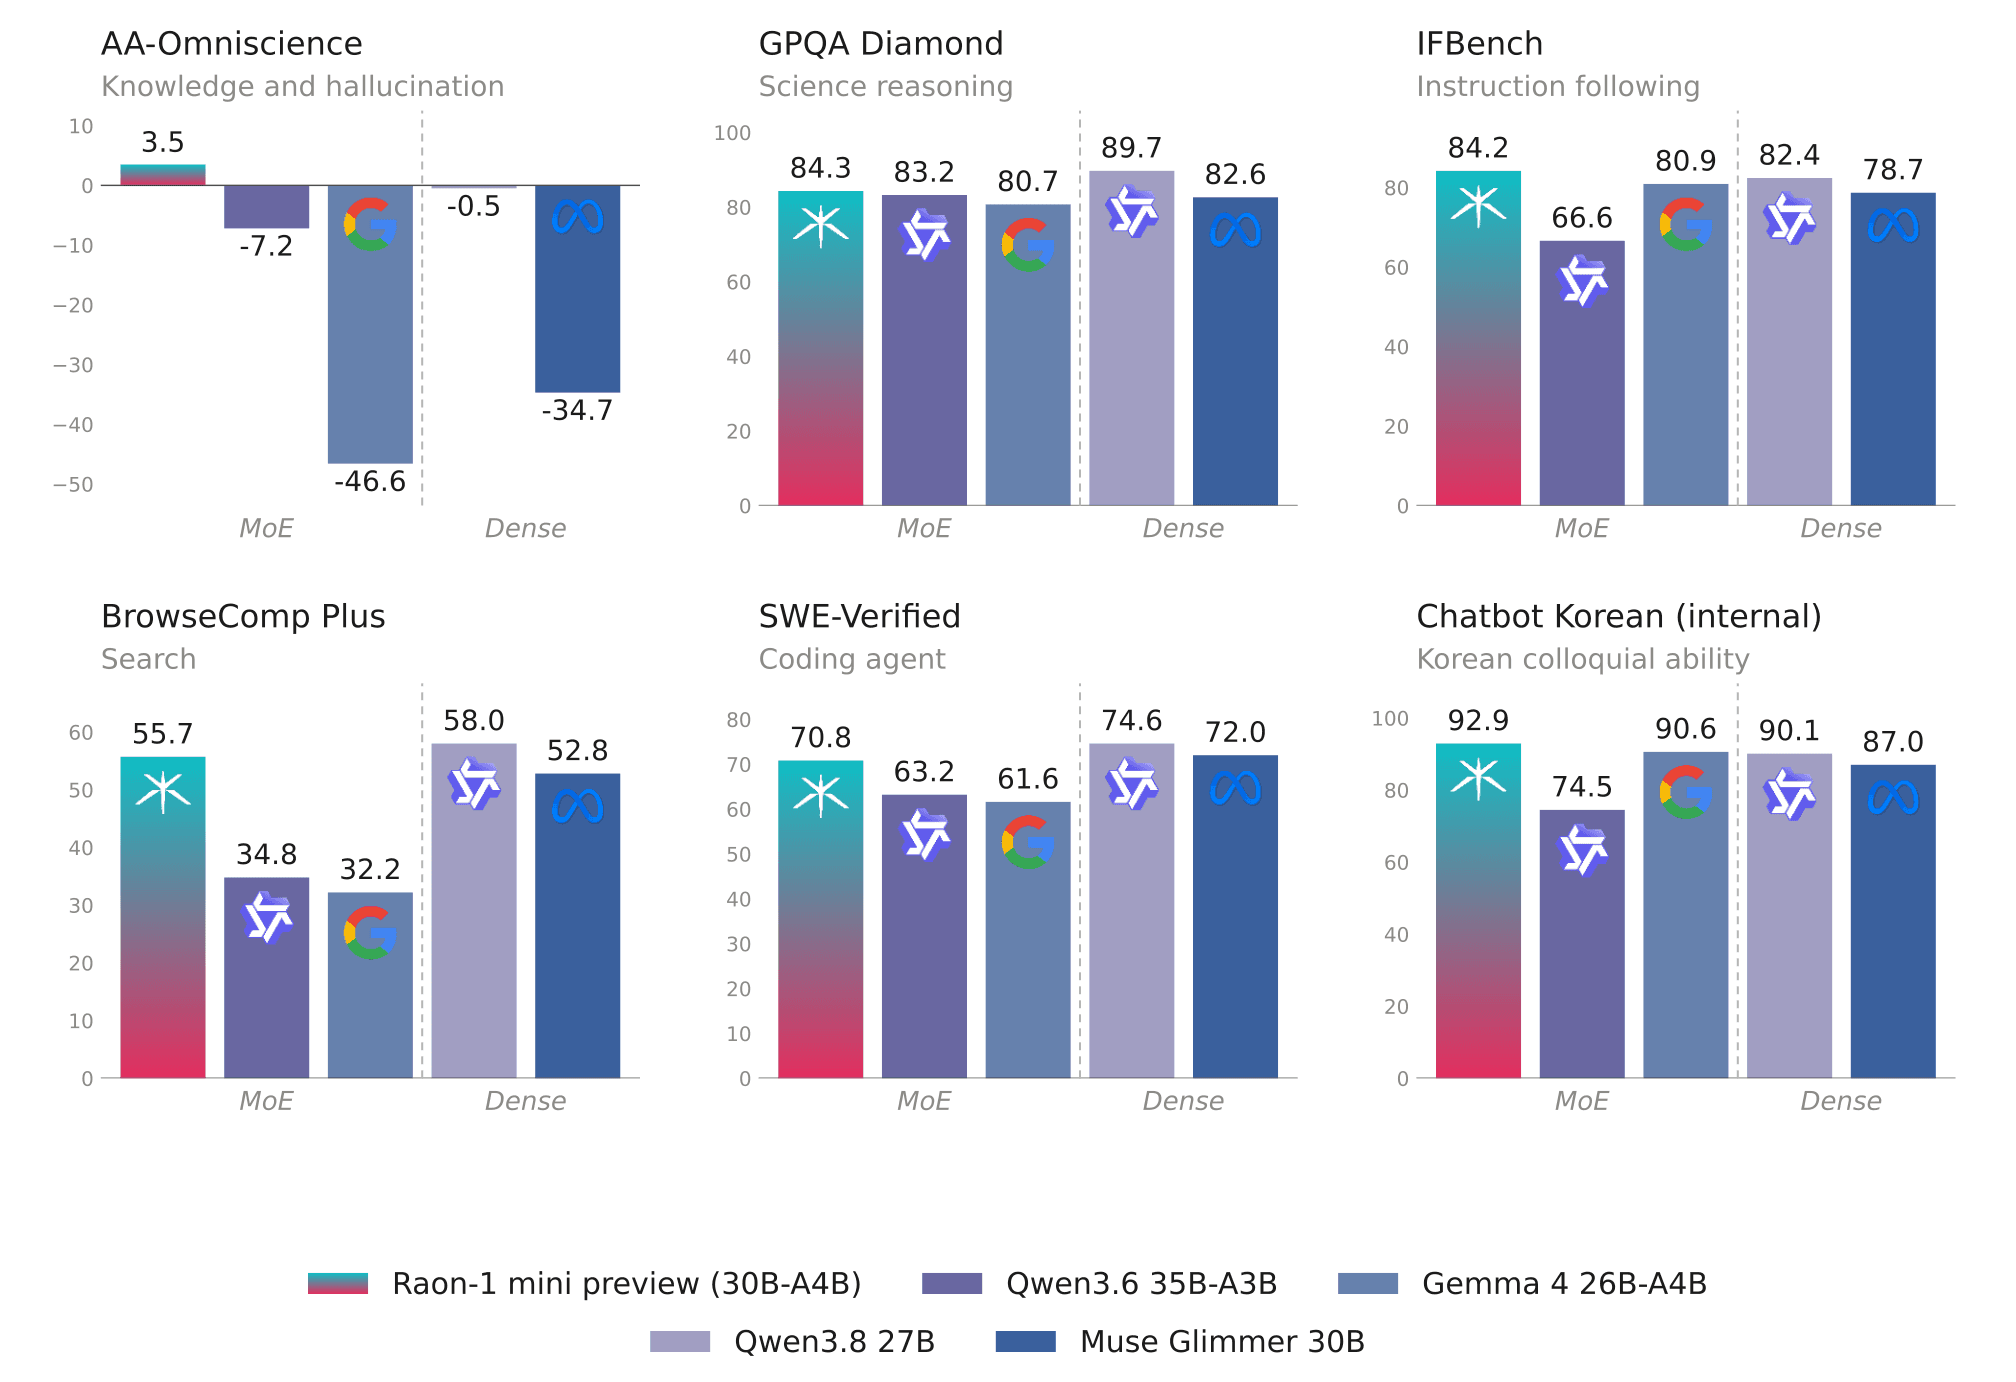
KRAFTON releases Raon-1-mini preview under Apache 2.0
The Korean game studio behind PUBG puts out a compact, permissively licensed language model as an early preview.

DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
0 comments
No comments yet. Be the first to weigh in.