IFM releases K2-Horizon-7B with open pretraining data
The dense 7-billion-parameter model ships as open weights alongside the datasets used to train it.
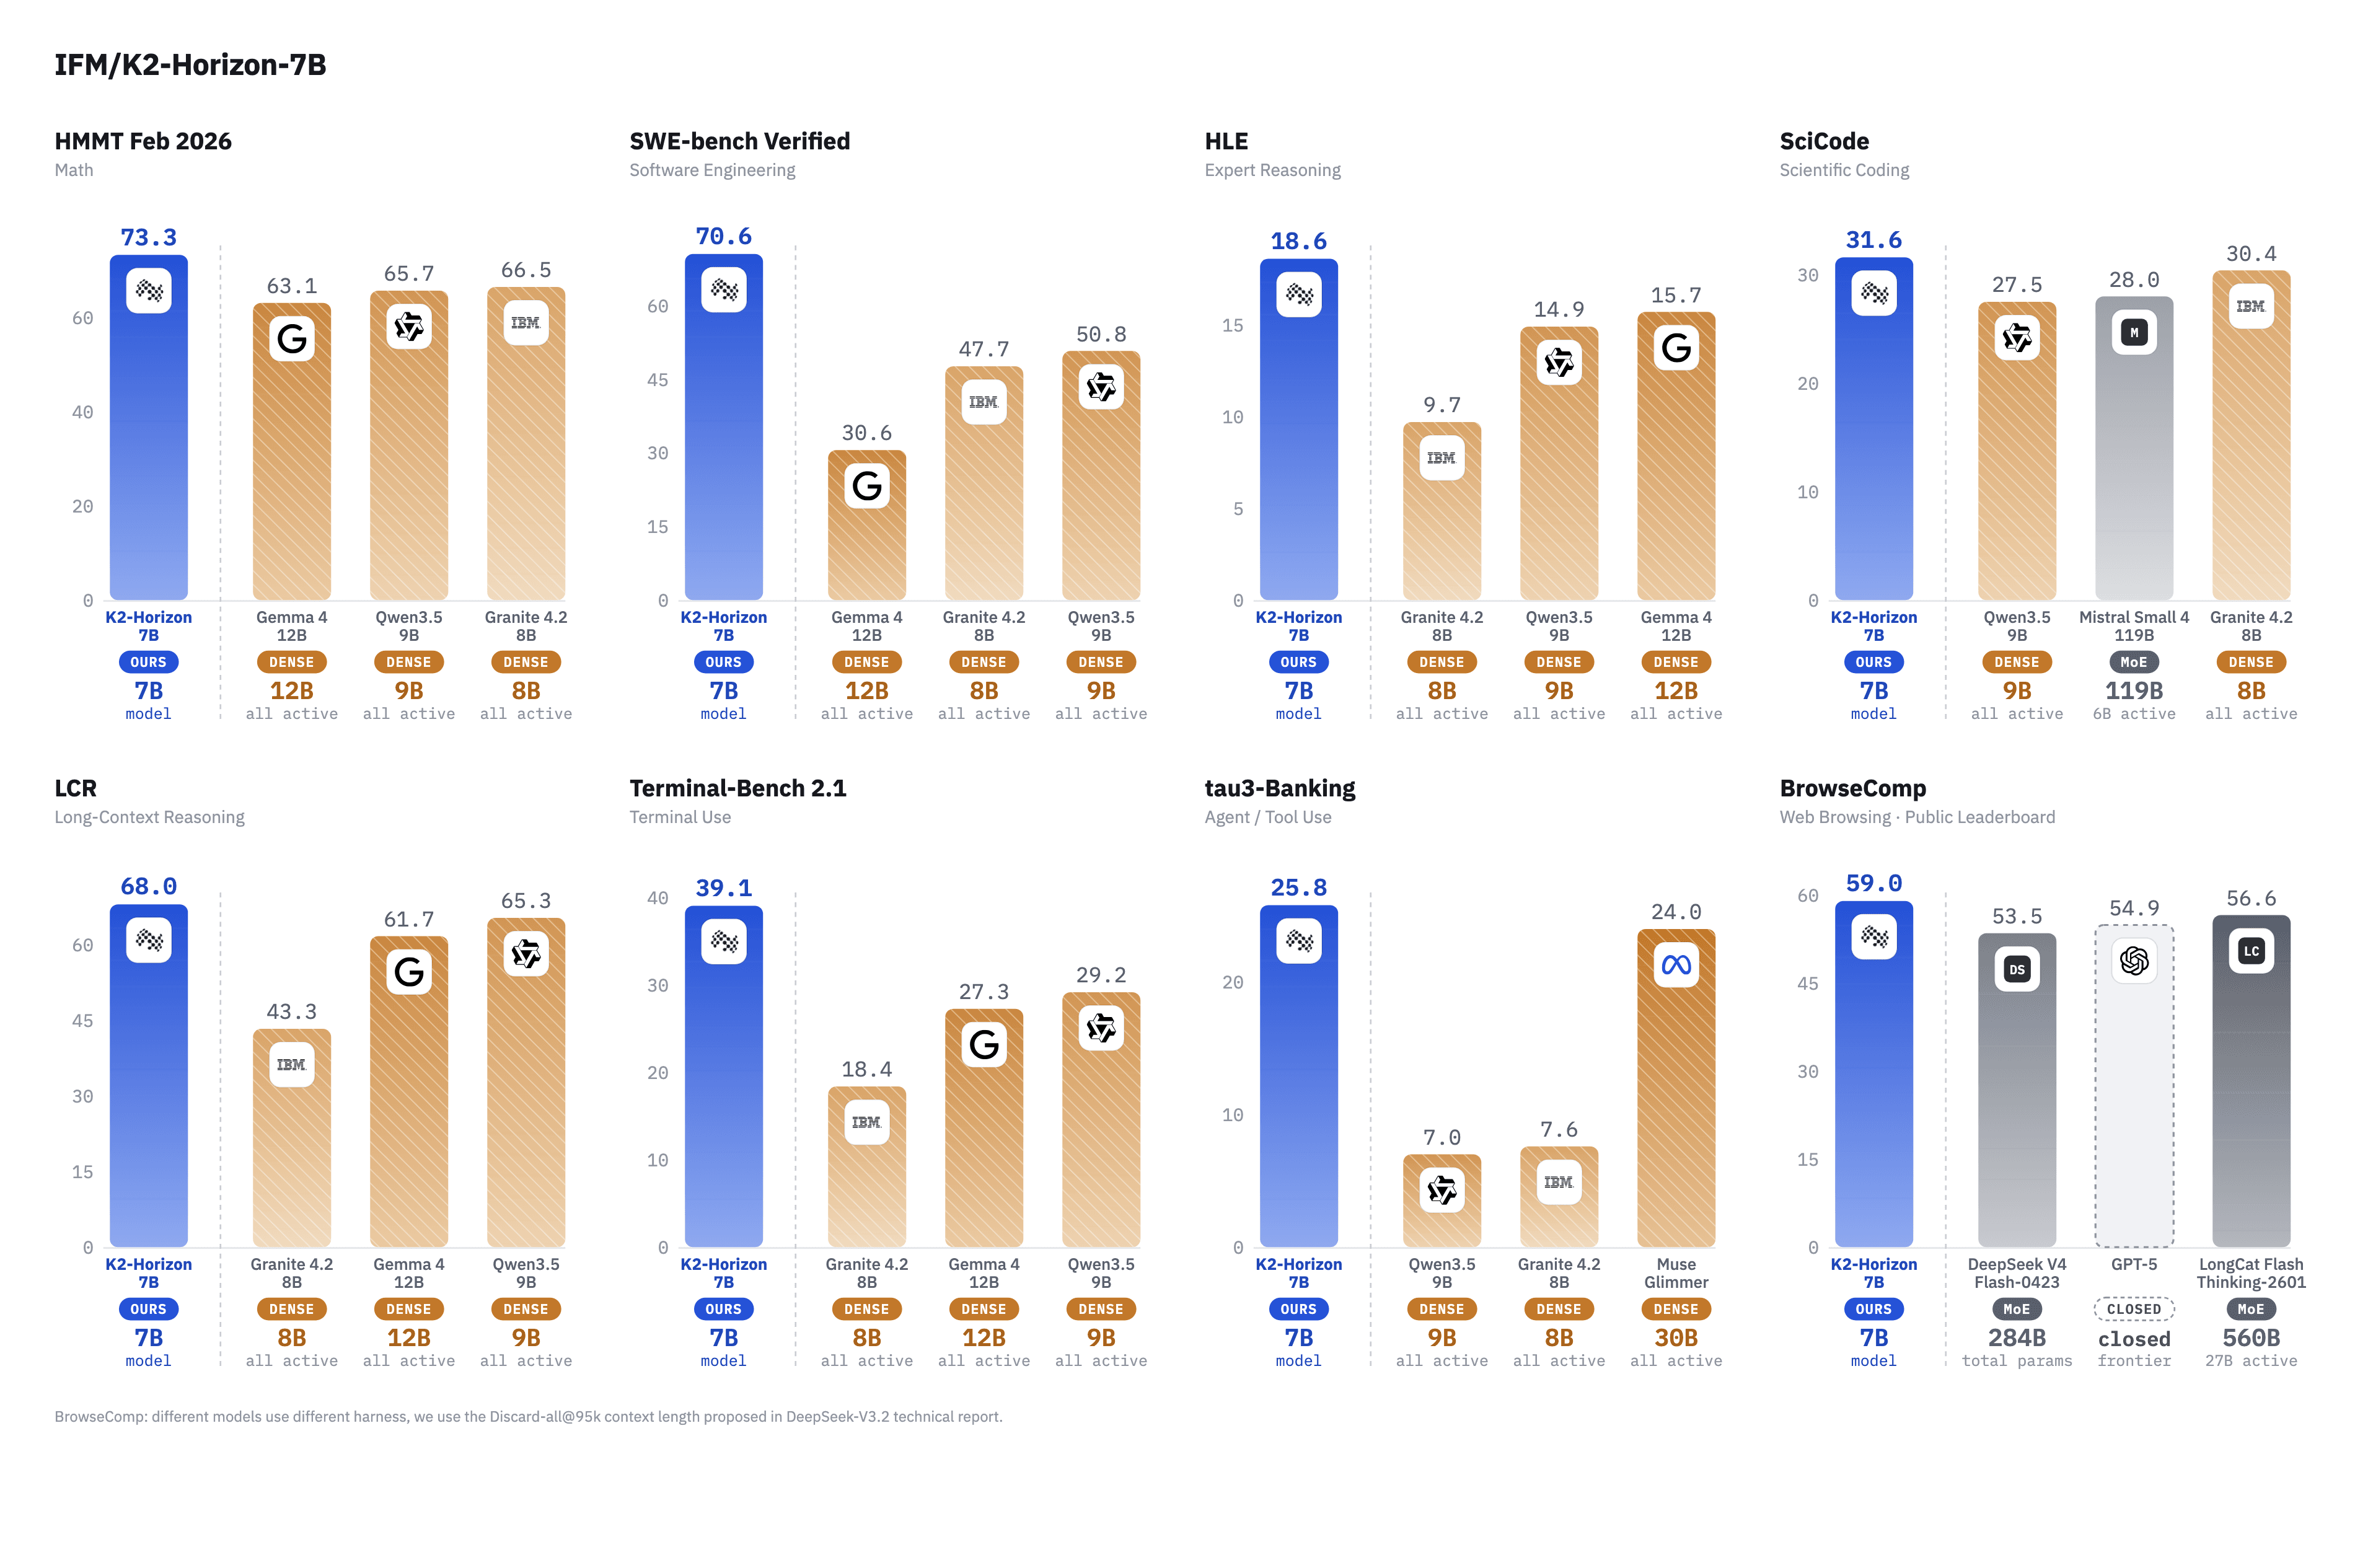
IFM has published K2-Horizon-7B, a dense 7-billion-parameter text model released as open weights on Hugging Face. It is the first entry in the K2-Horizon family, arriving in the increasingly crowded 7B tier where models are small enough to run on a single accelerator yet capable enough for practical fine-tuning.
The distinguishing detail here is not the architecture but the transparency around it. IFM says the release includes the pretraining datasets used to build the model, a step many open-weight projects skip. That matters for teams that need to audit training data, reproduce results, or continue pretraining on a documented corpus.
Why it matters
Most models described as open ship only their weights, leaving the training recipe opaque. Releasing the underlying data moves K2-Horizon closer to genuine reproducibility:
- A conventional dense design, rather than a mixture-of-experts, keeping deployment straightforward
- A 7B footprint suited to modest hardware and downstream tuning
- Published pretraining datasets that support inspection and further training
The model is offered under a custom license, so prospective users should review the terms before commercial use. IFM has not published headline benchmark numbers with this initial release, so its standing against peers like Mistral 7B or Qwen's small models remains to be tested. For now, the appeal is the combination of open weights and open data in a compact package.
Sources
- Visit
IFM/K2-Horizon-7B
Hugging Face
More from IFM
All IFM releases →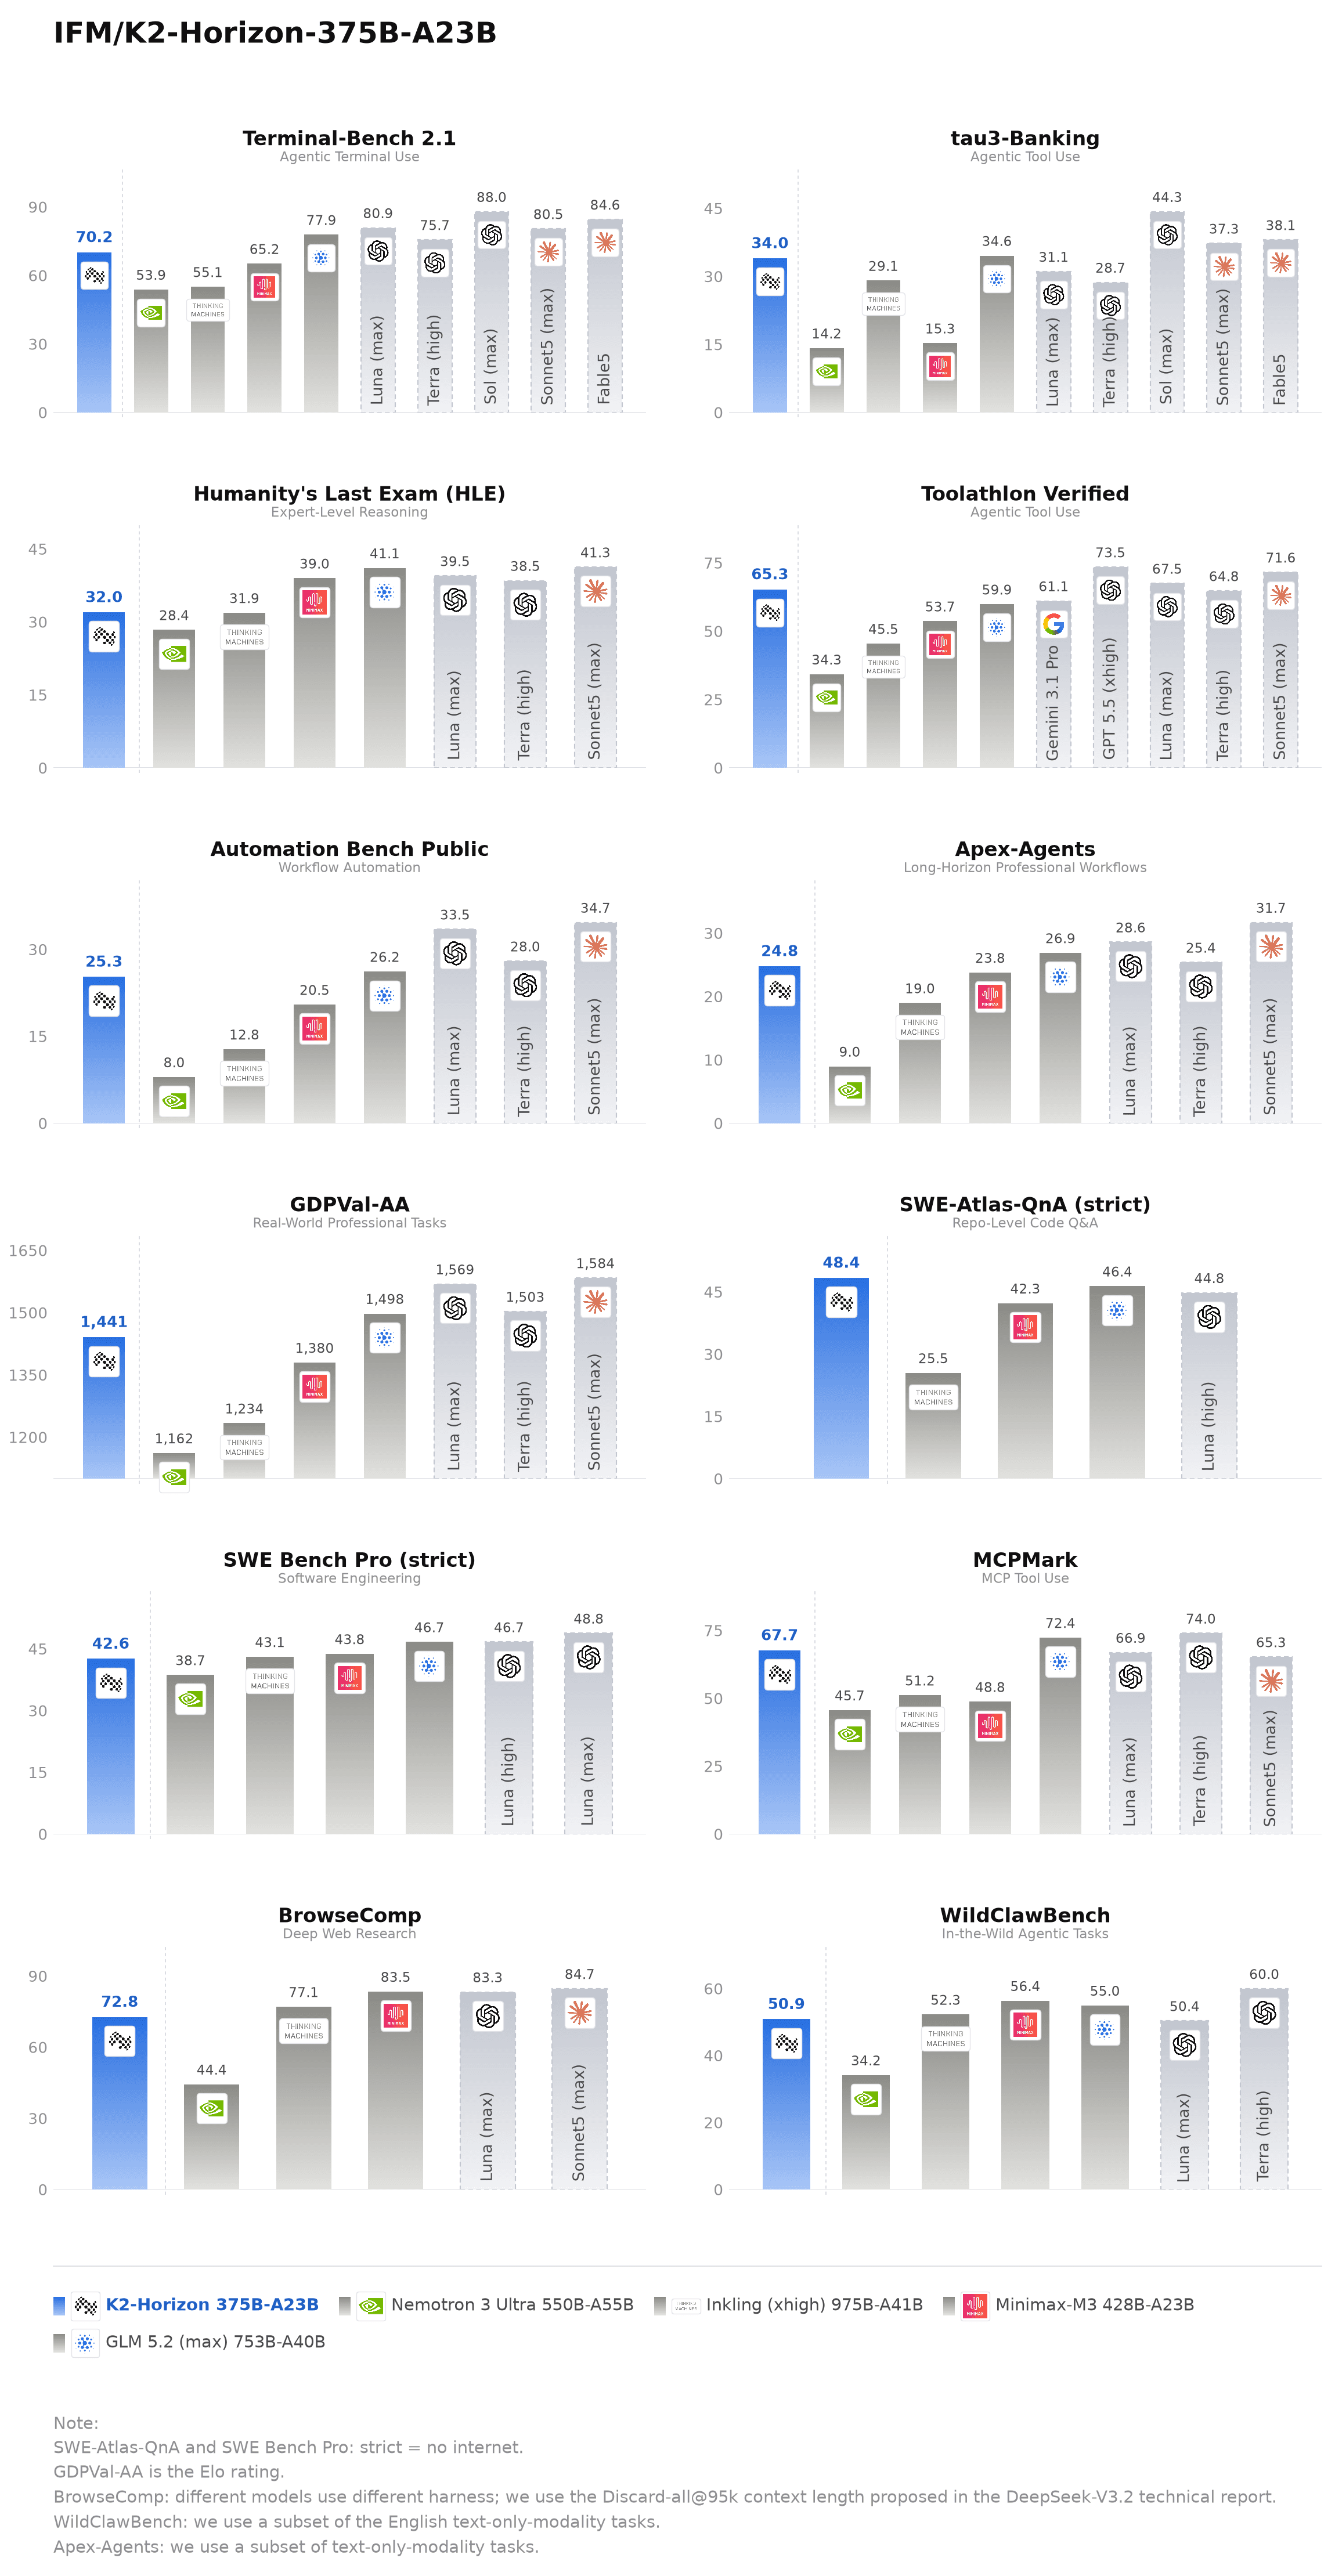
IFM releases K2-Horizon, a 375B open-weight MoE
The flagship model uses a mixture-of-experts design that activates just 23 billion parameters per token, keeping inference costs in check.
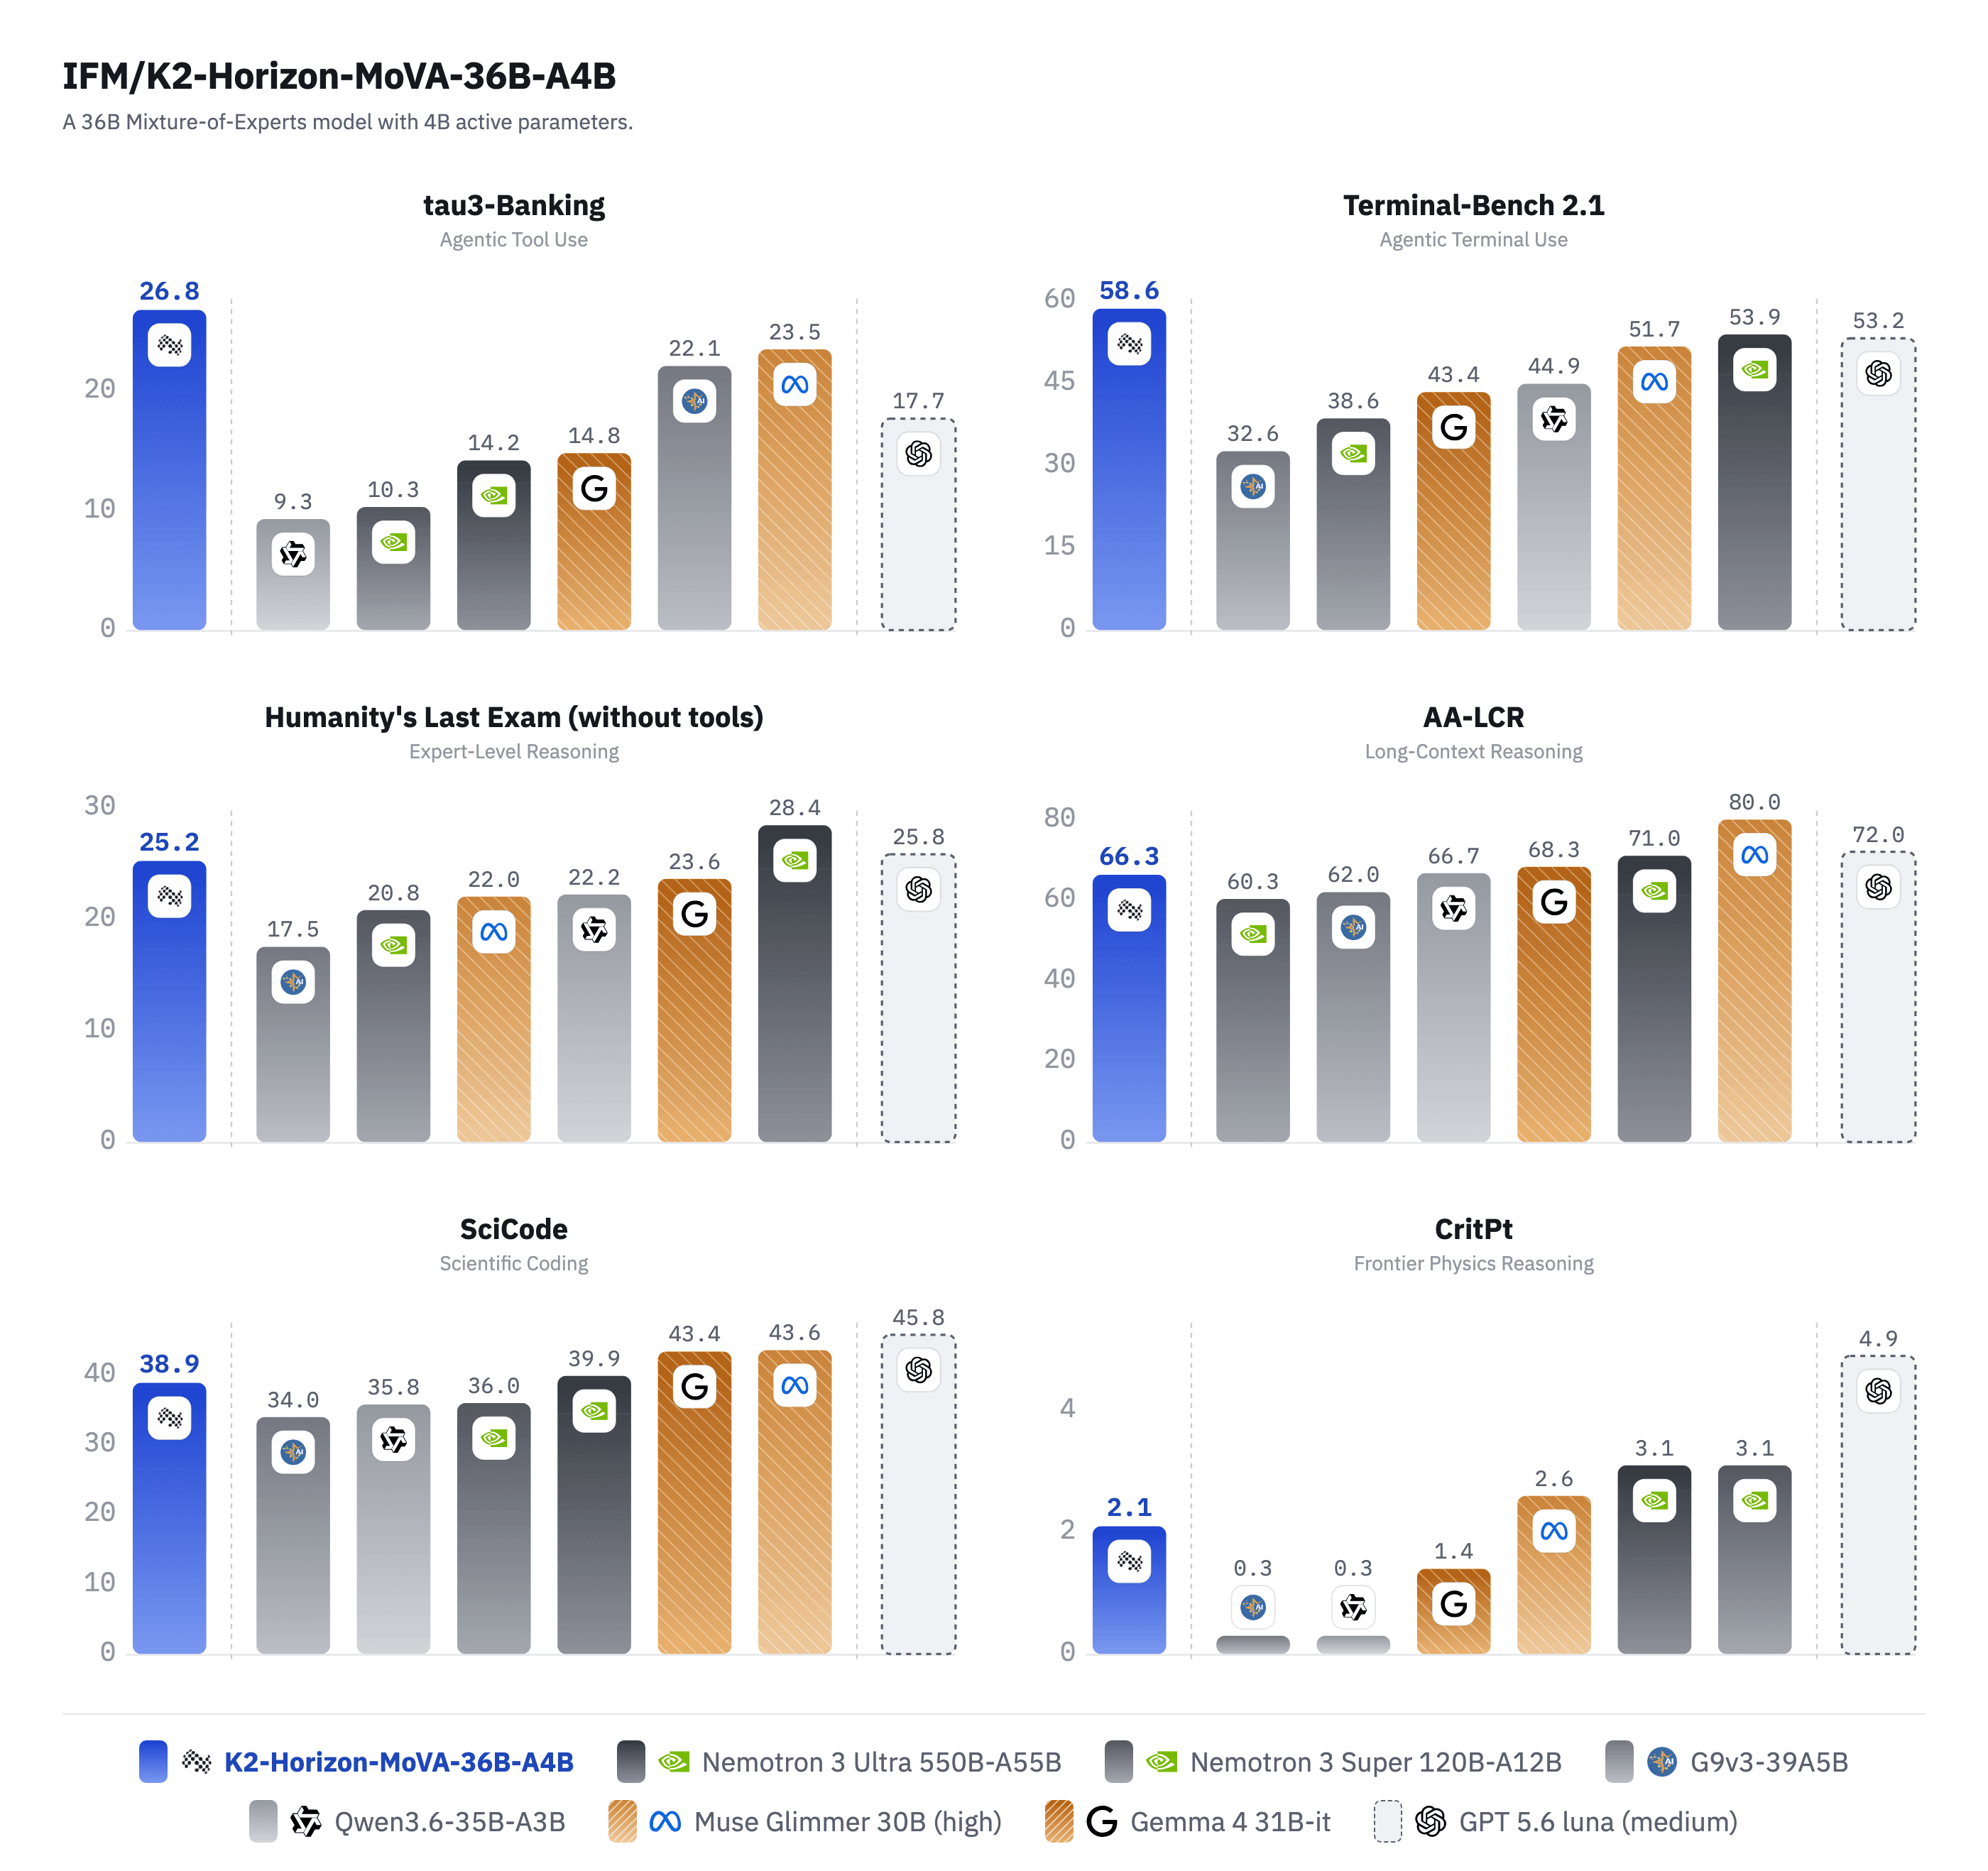
IFM's K2-Horizon MoVA Ships as a 36B MoE Model
The open-weight language model activates just 4B of its 36B parameters per token, aiming for efficiency without shedding capacity.
More in Text / LLM
All Text / LLM →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.