IFM's K2-Horizon MoVA Ships as a 36B MoE Model
The open-weight language model activates just 4B of its 36B parameters per token, aiming for efficiency without shedding capacity.
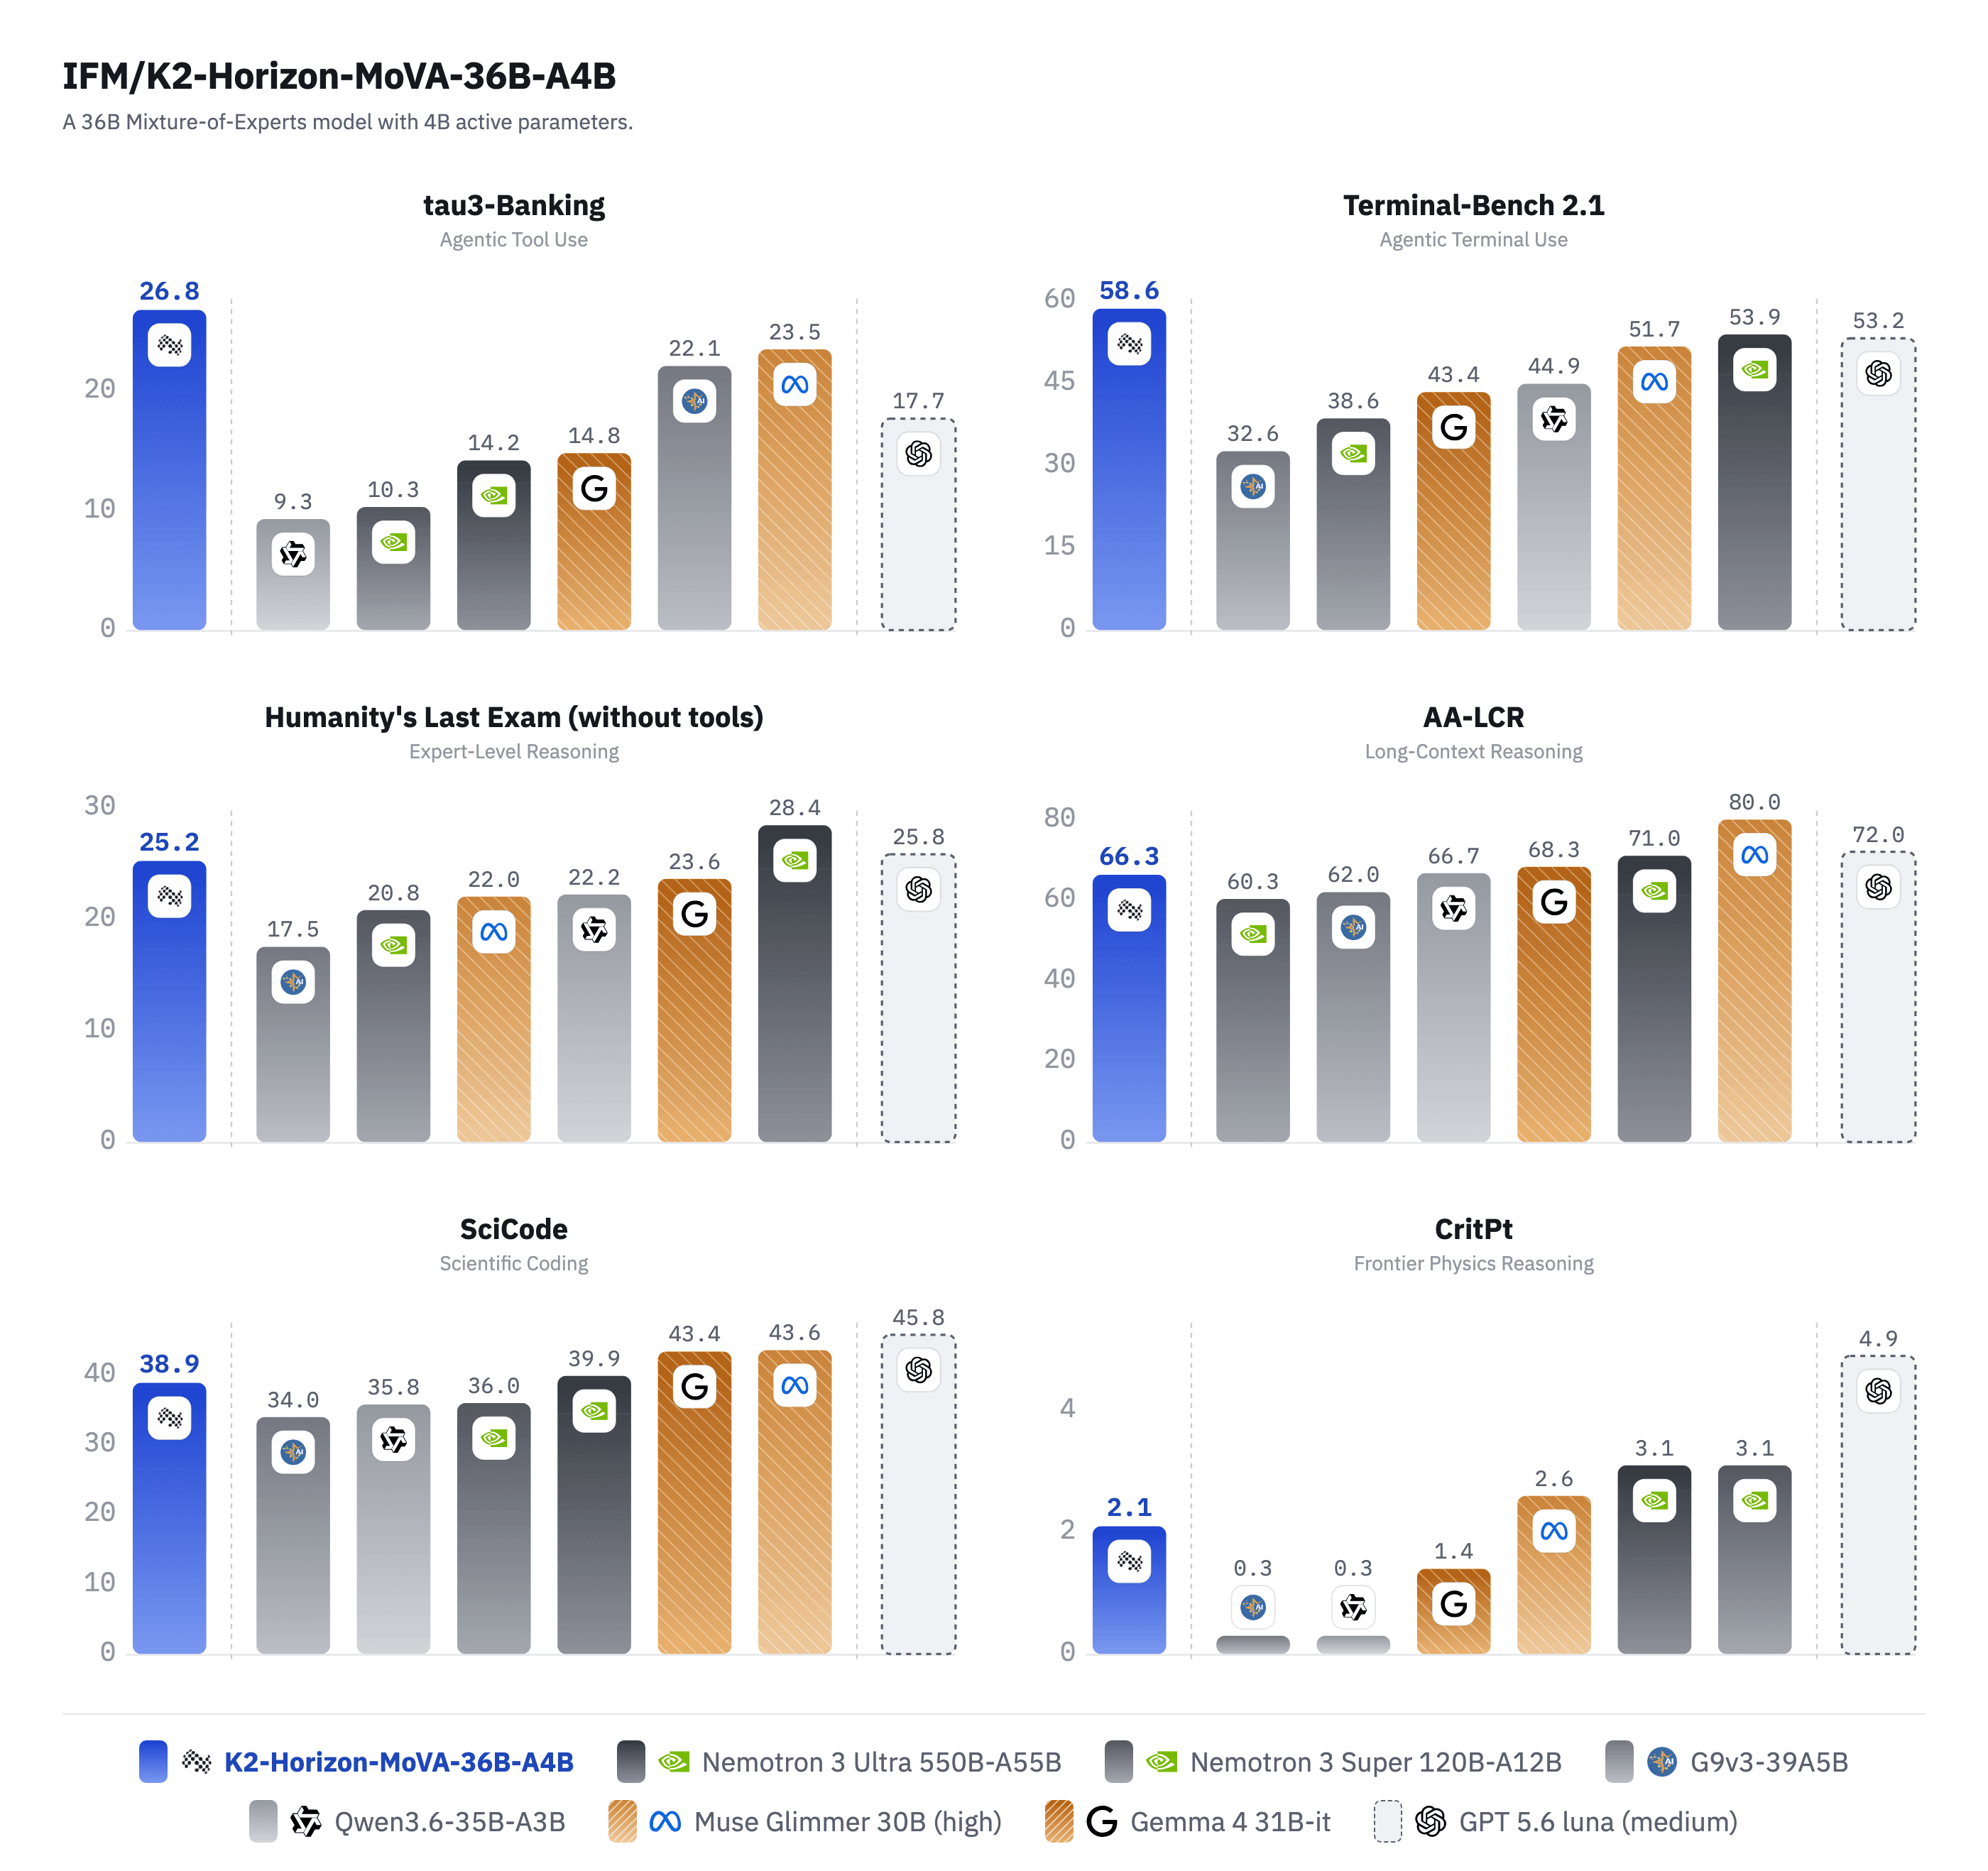
IFM has published K2-Horizon-MoVA-36B-A4B, an open-weight large language model built on a mixture-of-experts (MoE) design. The model carries 36 billion total parameters but activates only around 4 billion for any given token, according to its Hugging Face repository. It is the first entry in the K2-Horizon family and focuses on text generation.
The sparse MoE approach is the model's defining feature. Rather than firing every parameter on each forward pass, the network routes tokens to a small subset of specialized experts. That lets a model hold a large parameter budget while keeping the per-token compute cost closer to a much smaller dense model — a trade-off that has become increasingly common as teams try to balance quality against inference expense.
Why it matters
MoE architectures have moved from research curiosity to a practical deployment strategy, and a 36B/4B-active configuration lands in a range that could be attractive for teams with modest hardware.
- Total parameters: 36B, distributed across experts
- Active parameters: roughly 4B per token
- Modality: text-only language generation
- Weights: openly available under a custom license
Several details remain unstated in the initial listing, including context length and the specific license terms, which IFM marks simply as "other." As with any new open release, real-world evaluation will determine how the efficiency claims translate into usable performance. For now, the weights are available for developers to download and test directly from the model page.
Sources
- Visit
IFM/K2-Horizon-MoVA-36B-A4B
Hugging Face
More from IFM
All IFM releases →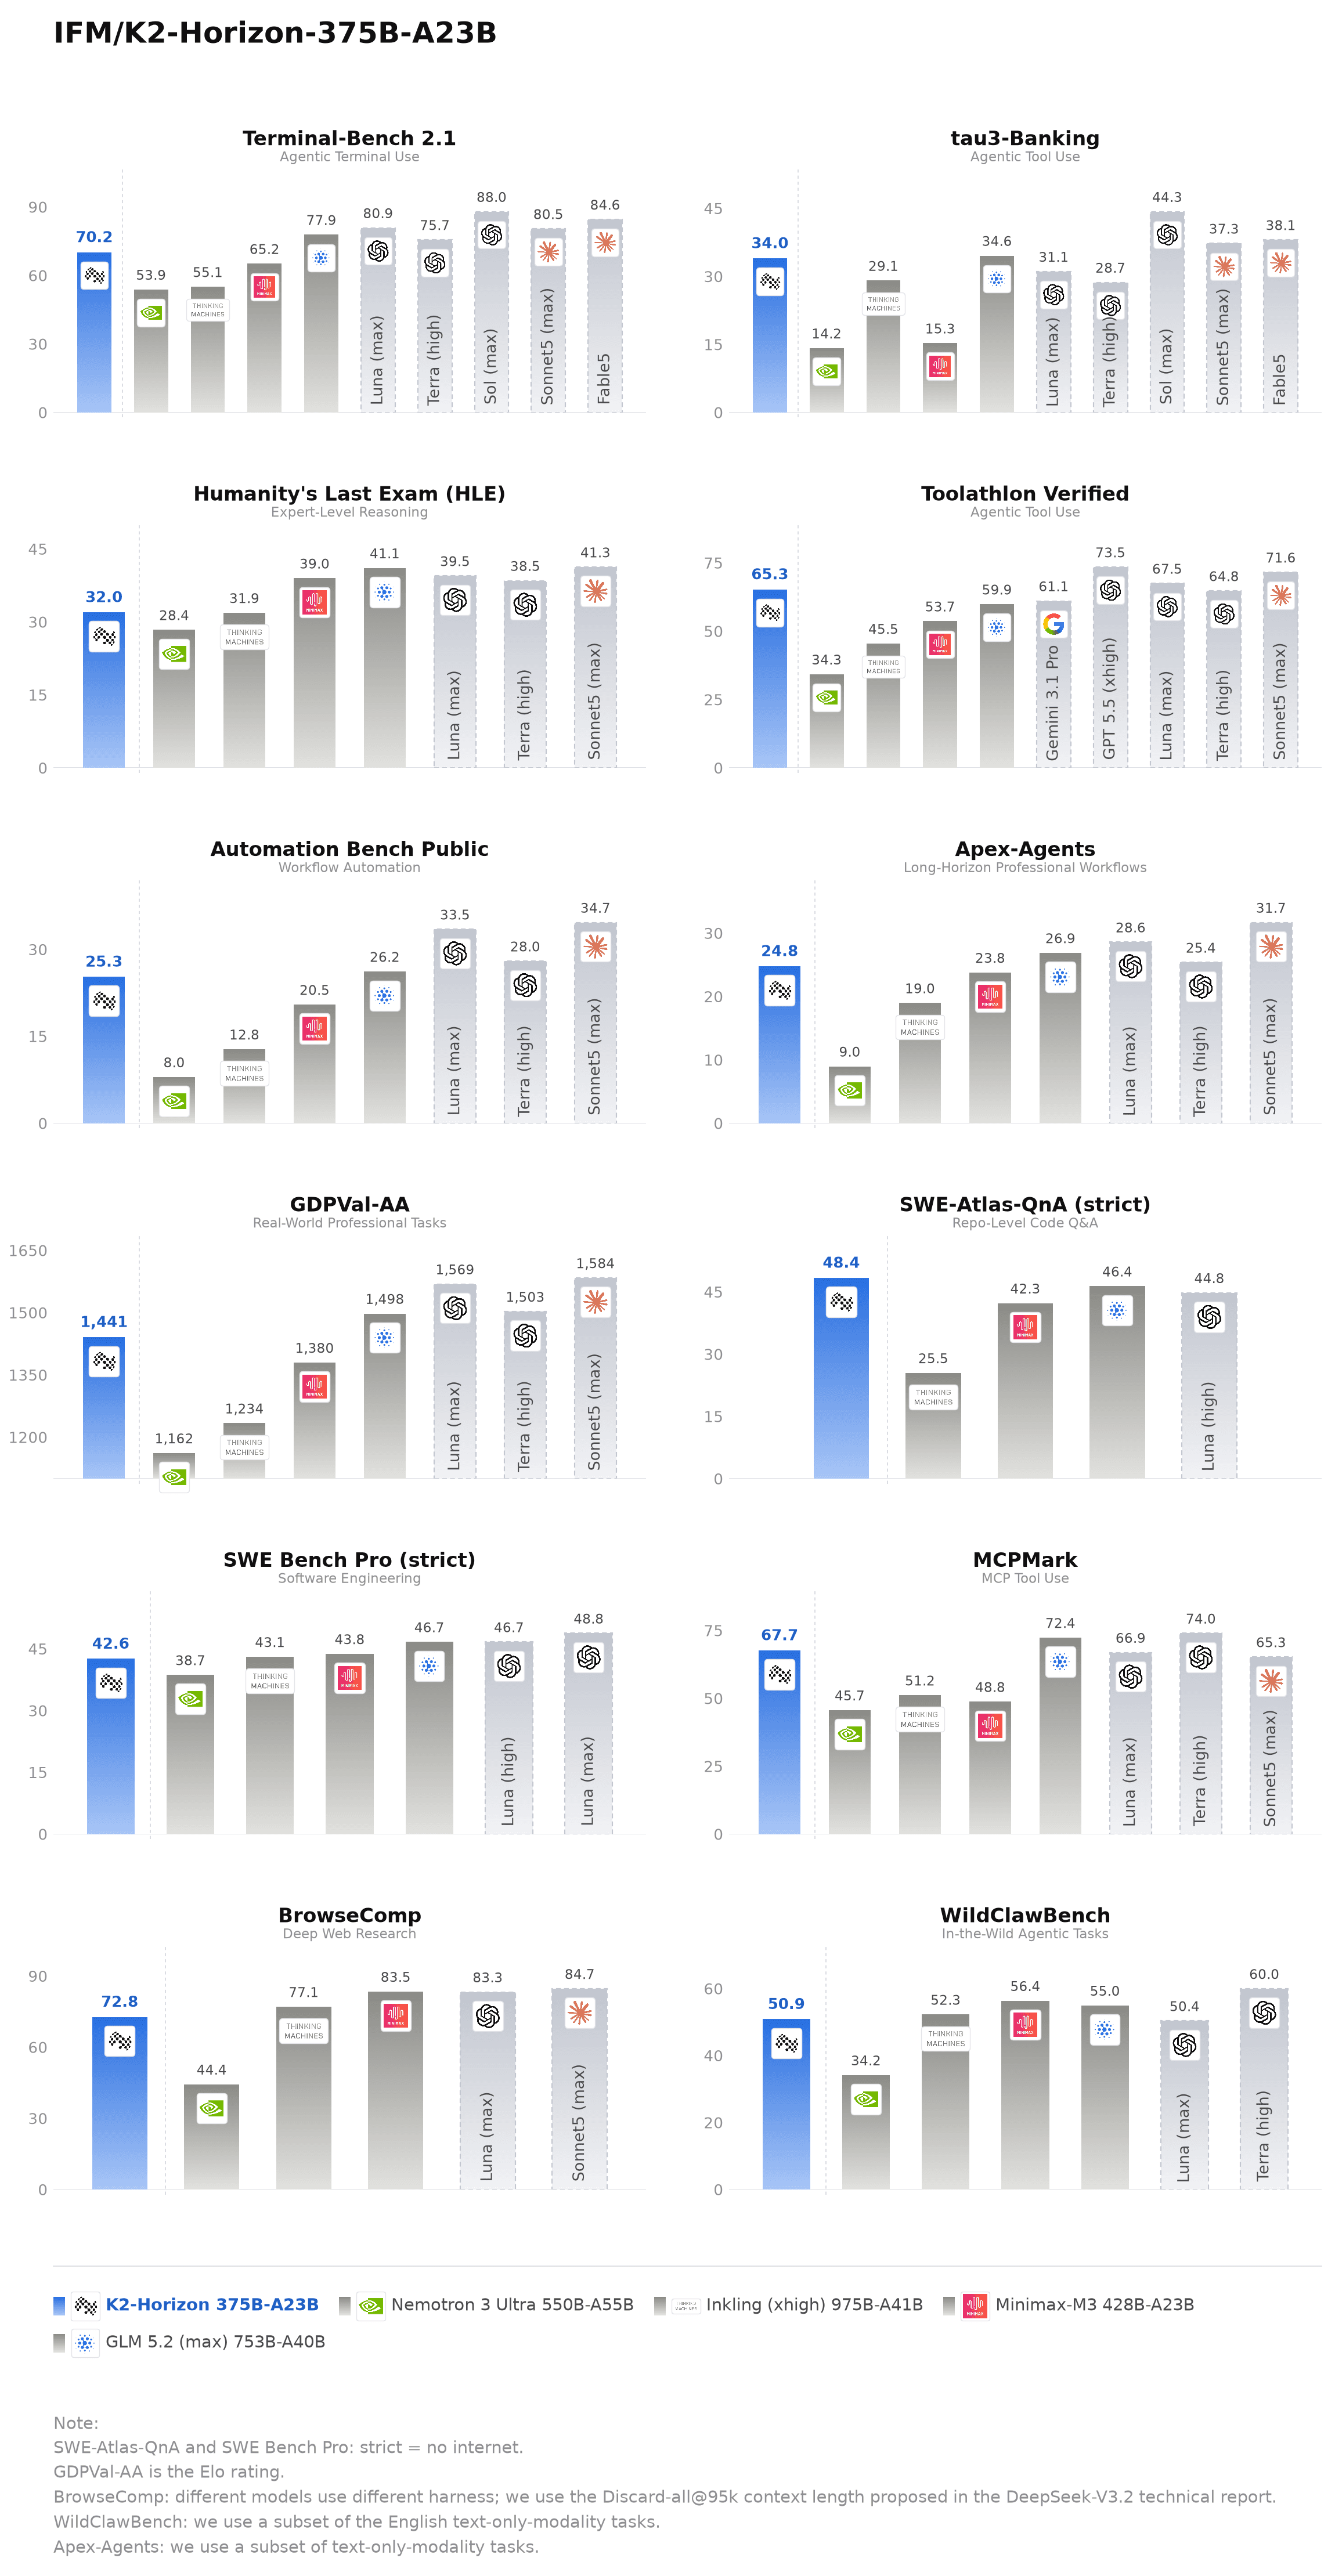
IFM releases K2-Horizon, a 375B open-weight MoE
The flagship model uses a mixture-of-experts design that activates just 23 billion parameters per token, keeping inference costs in check.
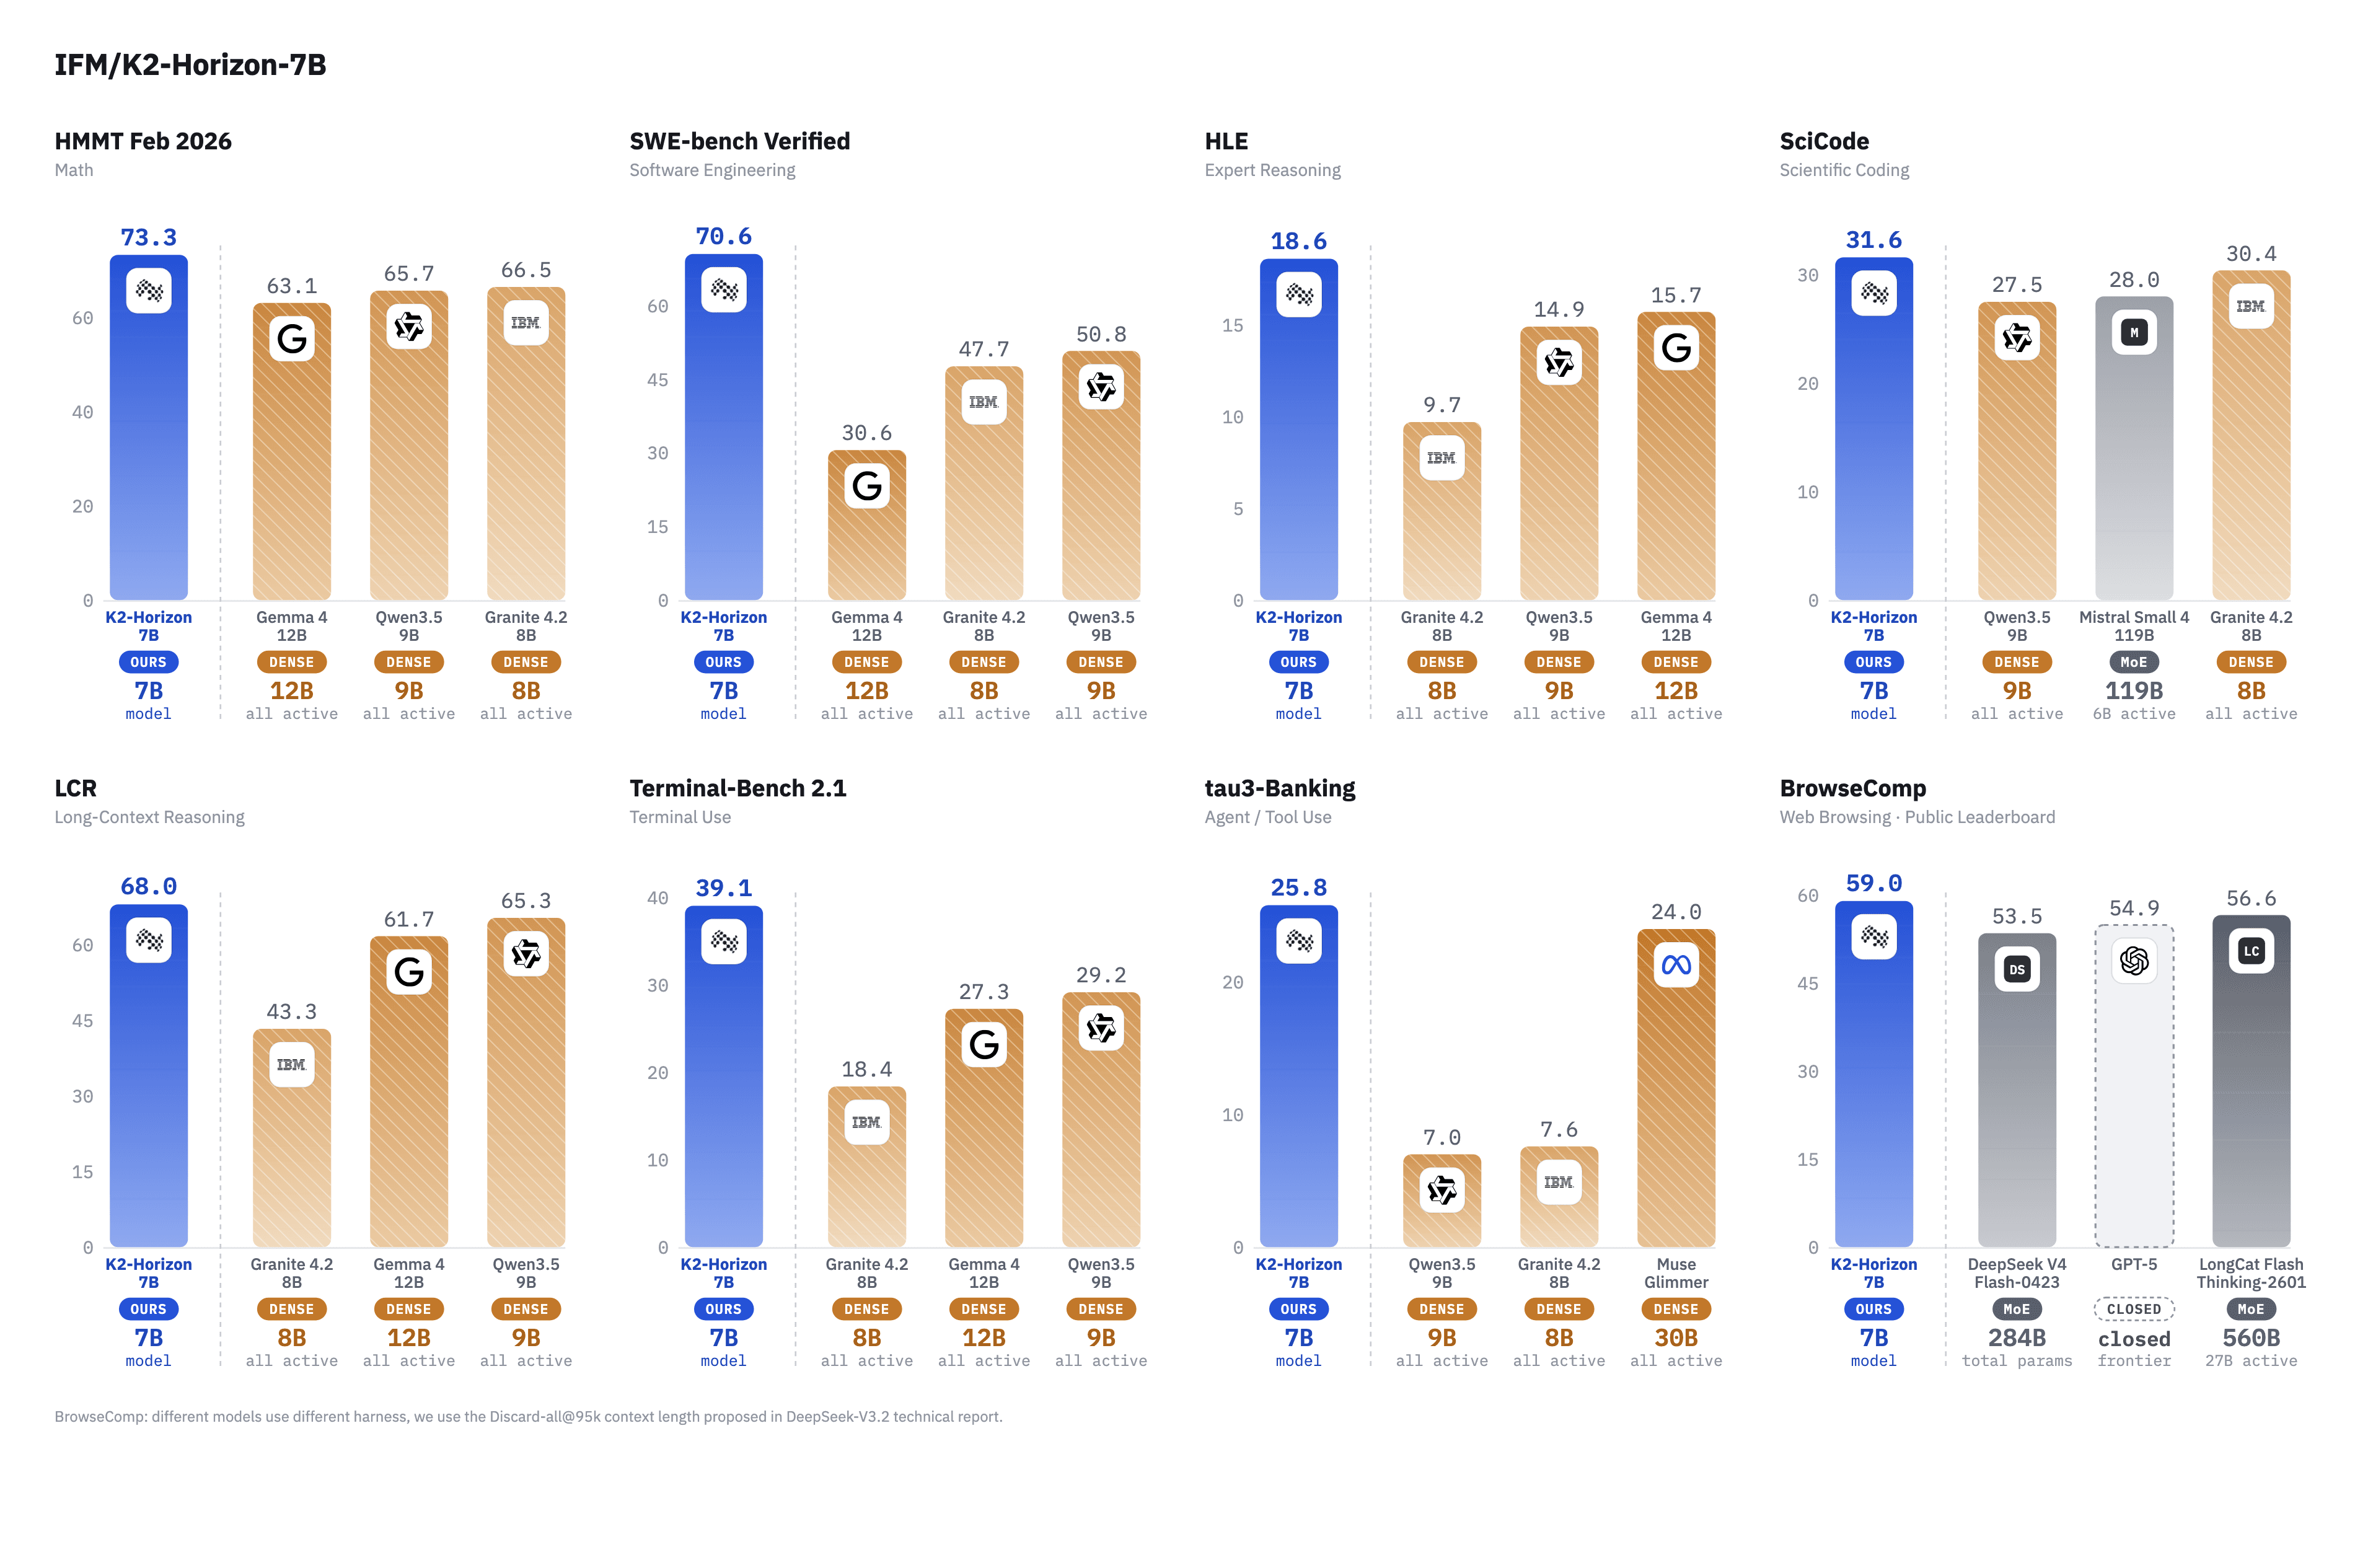
IFM releases K2-Horizon-7B with open pretraining data
The dense 7-billion-parameter model ships as open weights alongside the datasets used to train it.
More in Text / LLM
All Text / LLM →IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
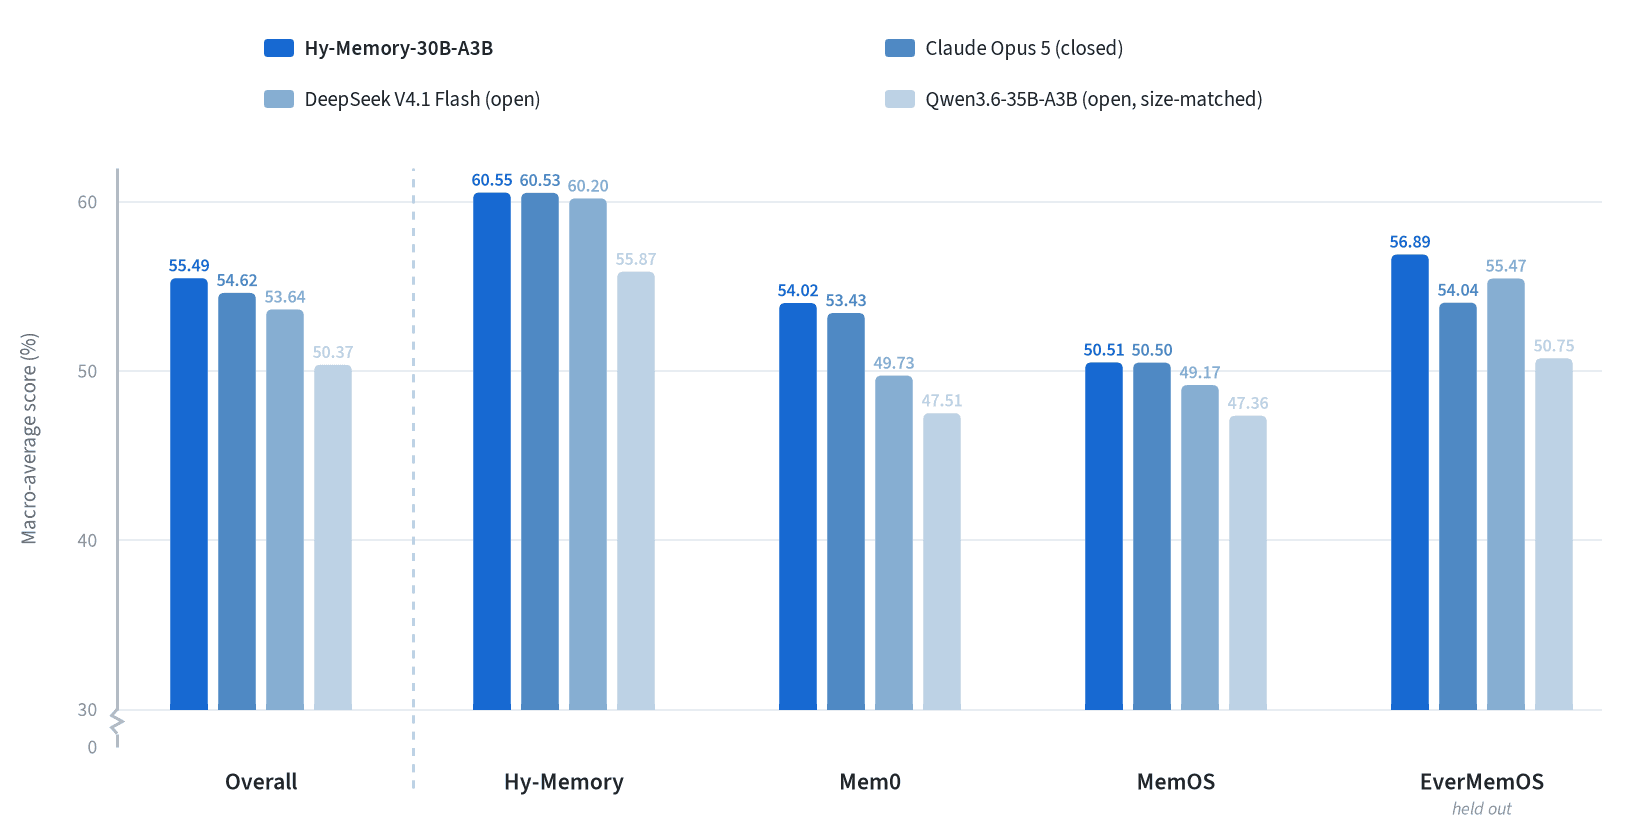
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
inclusionAI releases Ling-3.1-flash under MIT license
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
0 comments
No comments yet. Be the first to weigh in.