MiniMax Releases H3 Image, Its Open Text-to-Image Model
The Chinese AI lab enters the open image-generation space with a single model that both creates and edits pictures from text.
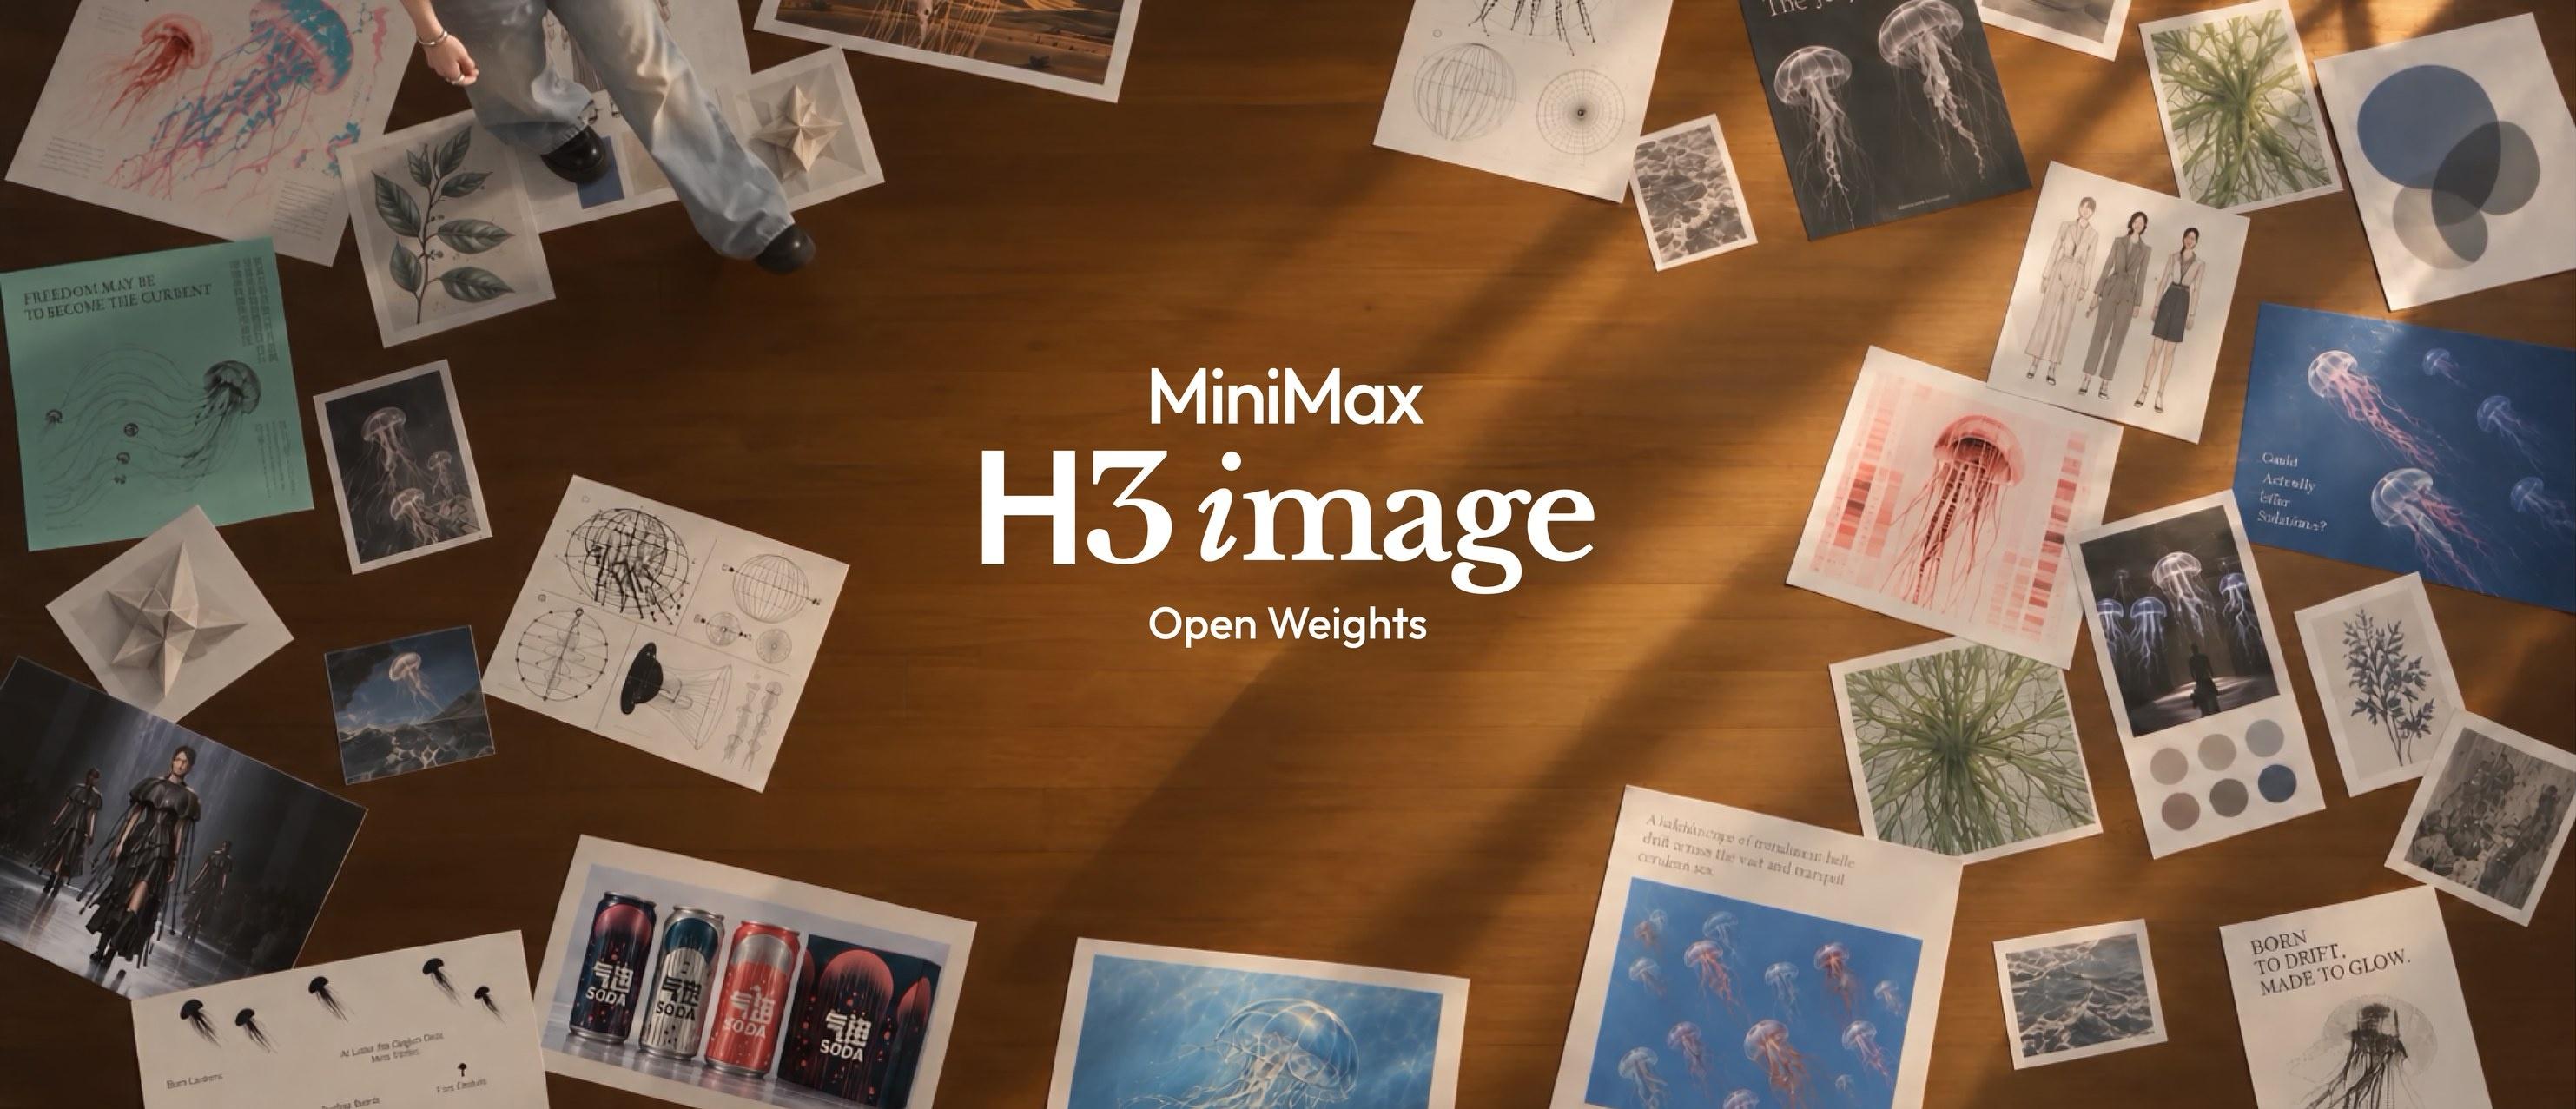
MiniMax has published H3 Image, a text-to-image model that also handles image editing, on Hugging Face. It marks the company's first entry into open image generation, extending a portfolio that has so far leaned toward large language and agentic models.
The model covers two closely related tasks: generating pictures from text prompts and editing existing images based on instructions. Bundling both capabilities into one release is increasingly common, letting developers use a single system for creation and iterative refinement rather than stitching together separate tools.
Why it matters
MiniMax is among the more prominent Chinese labs releasing model weights, and its move into images adds another option for developers building generative visual tools outside the walled gardens of proprietary APIs. A few things stand out:
- H3 Image is distributed under a custom license rather than a standard permissive one, so teams should read the terms before commercial use.
- MiniMax has not published parameter counts or detailed benchmarks alongside the release.
As always with a fresh image model, the real test will be how its outputs hold up against established open alternatives once the community starts running it. The weights and documentation are available now on Hugging Face.
Sources
- Visit
MiniMaxAI/MiniMax-H3-Image
Hugging Face
More from MiniMax
All MiniMax releases →
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

MiniMax Opens Its Music3 Text-to-Music Model
The Chinese AI lab brings its music generation system to Hugging Face, expanding the roster of open audio models.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.