Meituan Releases LongCat-Next 'Any-to-Any' AI Model
The Chinese tech company has released the weights for a unified model that can process and generate combinations of text, images, audio, and video.
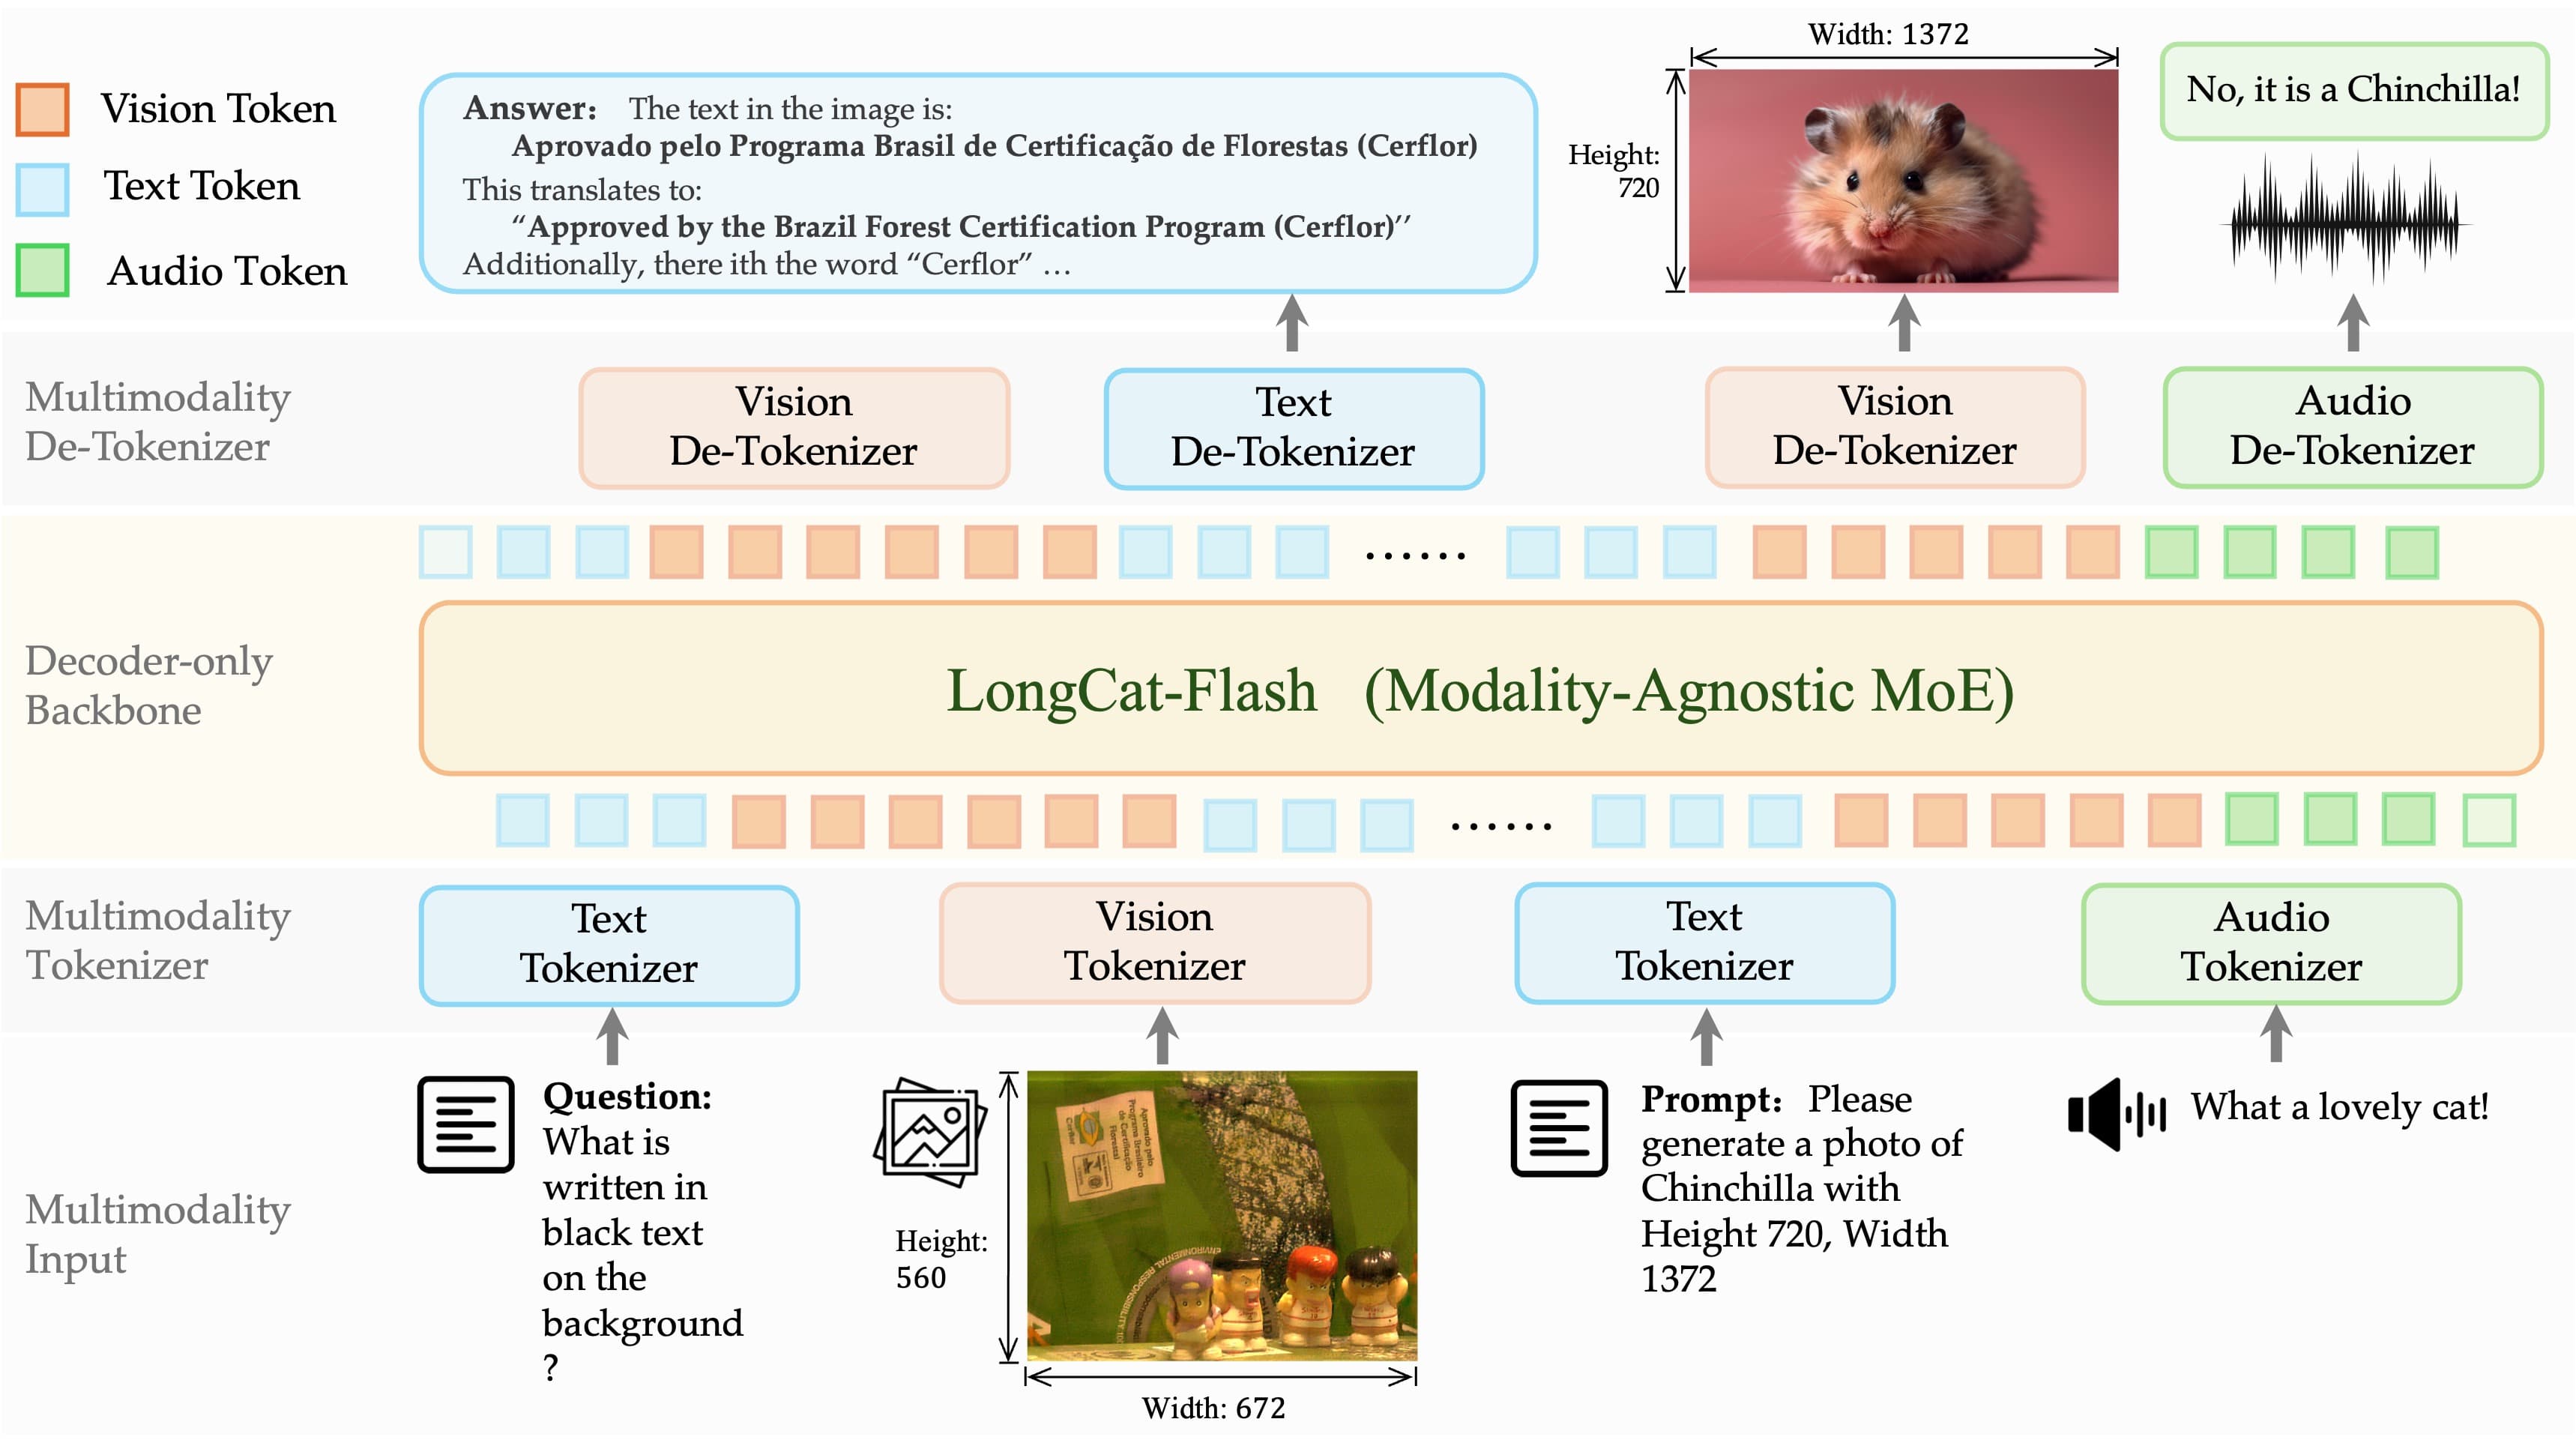
Chinese technology company Meituan has released the weights for LongCat-Next, an ambitious 'any-to-any' multimodal model. Published under a permissive MIT license, the model marks a significant step towards more flexible and generalized AI systems that can operate across a wide spectrum of data types.
Unlike most multimodal models that handle specific input-output pairs, such as text-to-image or image-to-text, LongCat-Next is designed for true combinatorial flexibility. It can accept any mix of text, images, audio, and video as input and generate any combination of those modalities as output. For example, it could take an image and an audio clip as prompts and produce a descriptive paragraph and a short video in response.
A Unified Architecture
The model achieves this versatility through a unified framework. Instead of stitching together separate, specialized encoders and decoders for each data type, LongCat-Next uses a single, end-to-end trained network. This architecture relies on a shared vocabulary to represent and process information from different sources, enabling it to generate coherent, multimodal content from complex prompts.
The release of LongCat-Next on the Hugging Face Hub provides researchers and developers with a powerful tool for exploring the frontiers of multimodal AI. Its open-ended capabilities and permissive license encourage experimentation in creative content generation, data synthesis, and complex reasoning tasks that span multiple domains.
Sources
- Visit
meituan-longcat/LongCat-Next
Hugging Face
More from Meituan
All Meituan releases →
Meituan Ships a Lighter, Sparser LongCat-Flash
The food-delivery giant's newest open model trims its mixture-of-experts design for more efficient inference under an MIT license.
Meituan releases LongCat-2.0 language model
The Chinese delivery giant continues its push into open AI with a new text model on Hugging Face.
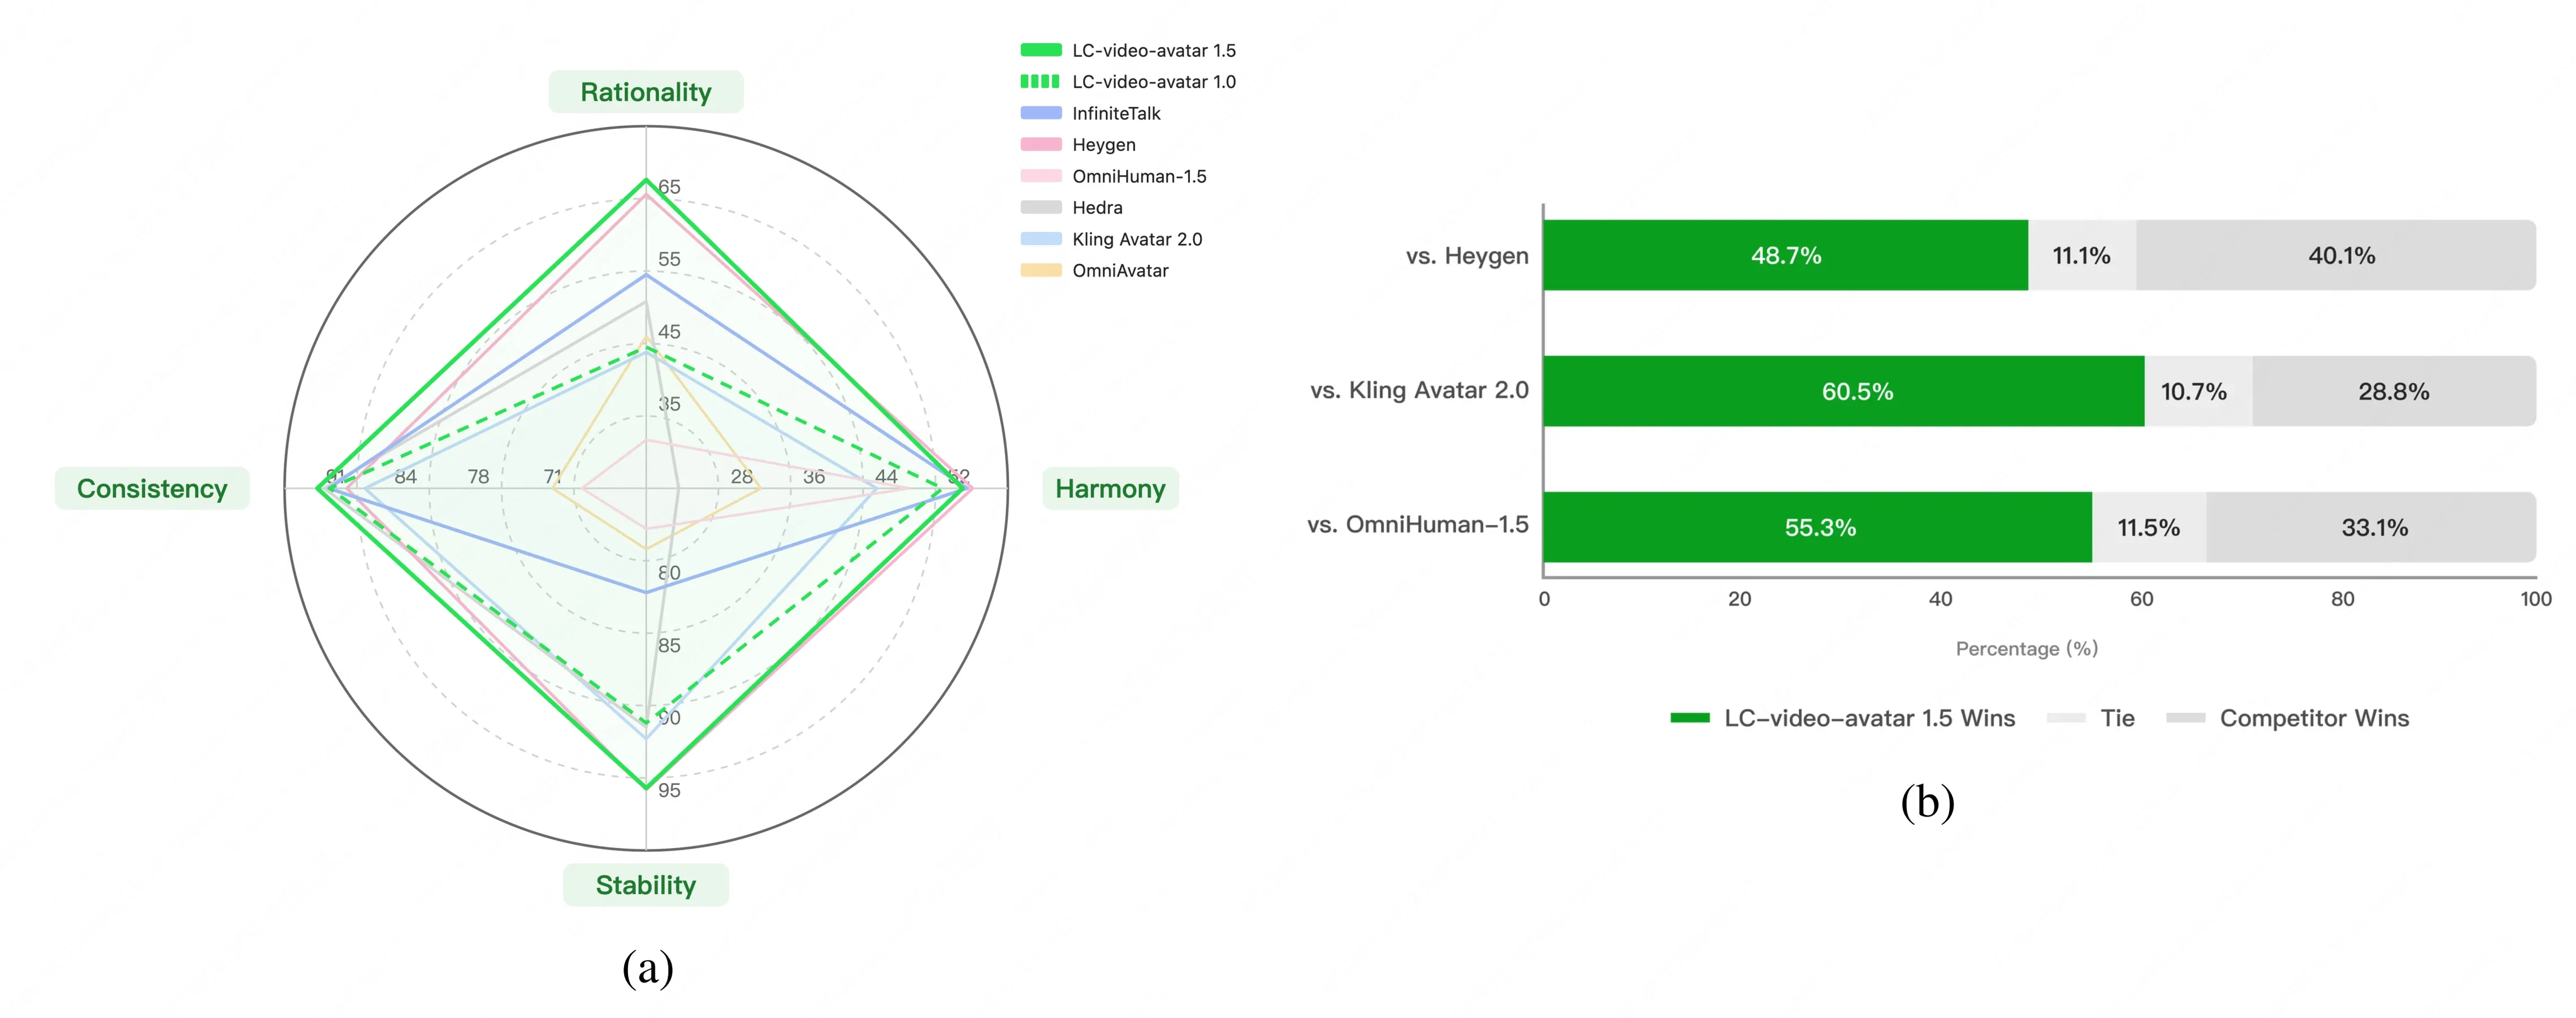
Meituan releases LongCat-Video-Avatar 1.5
An audio-driven avatar model that animates still images into talking video, with support for continuation of longer clips.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.