Qwen Releases Compact ASR Model for Streaming Audio
The new Fun-ASR-Nano model from Alibaba's team packs real-time multilingual transcription, speaker diarization, and hotword detection into an efficient package.
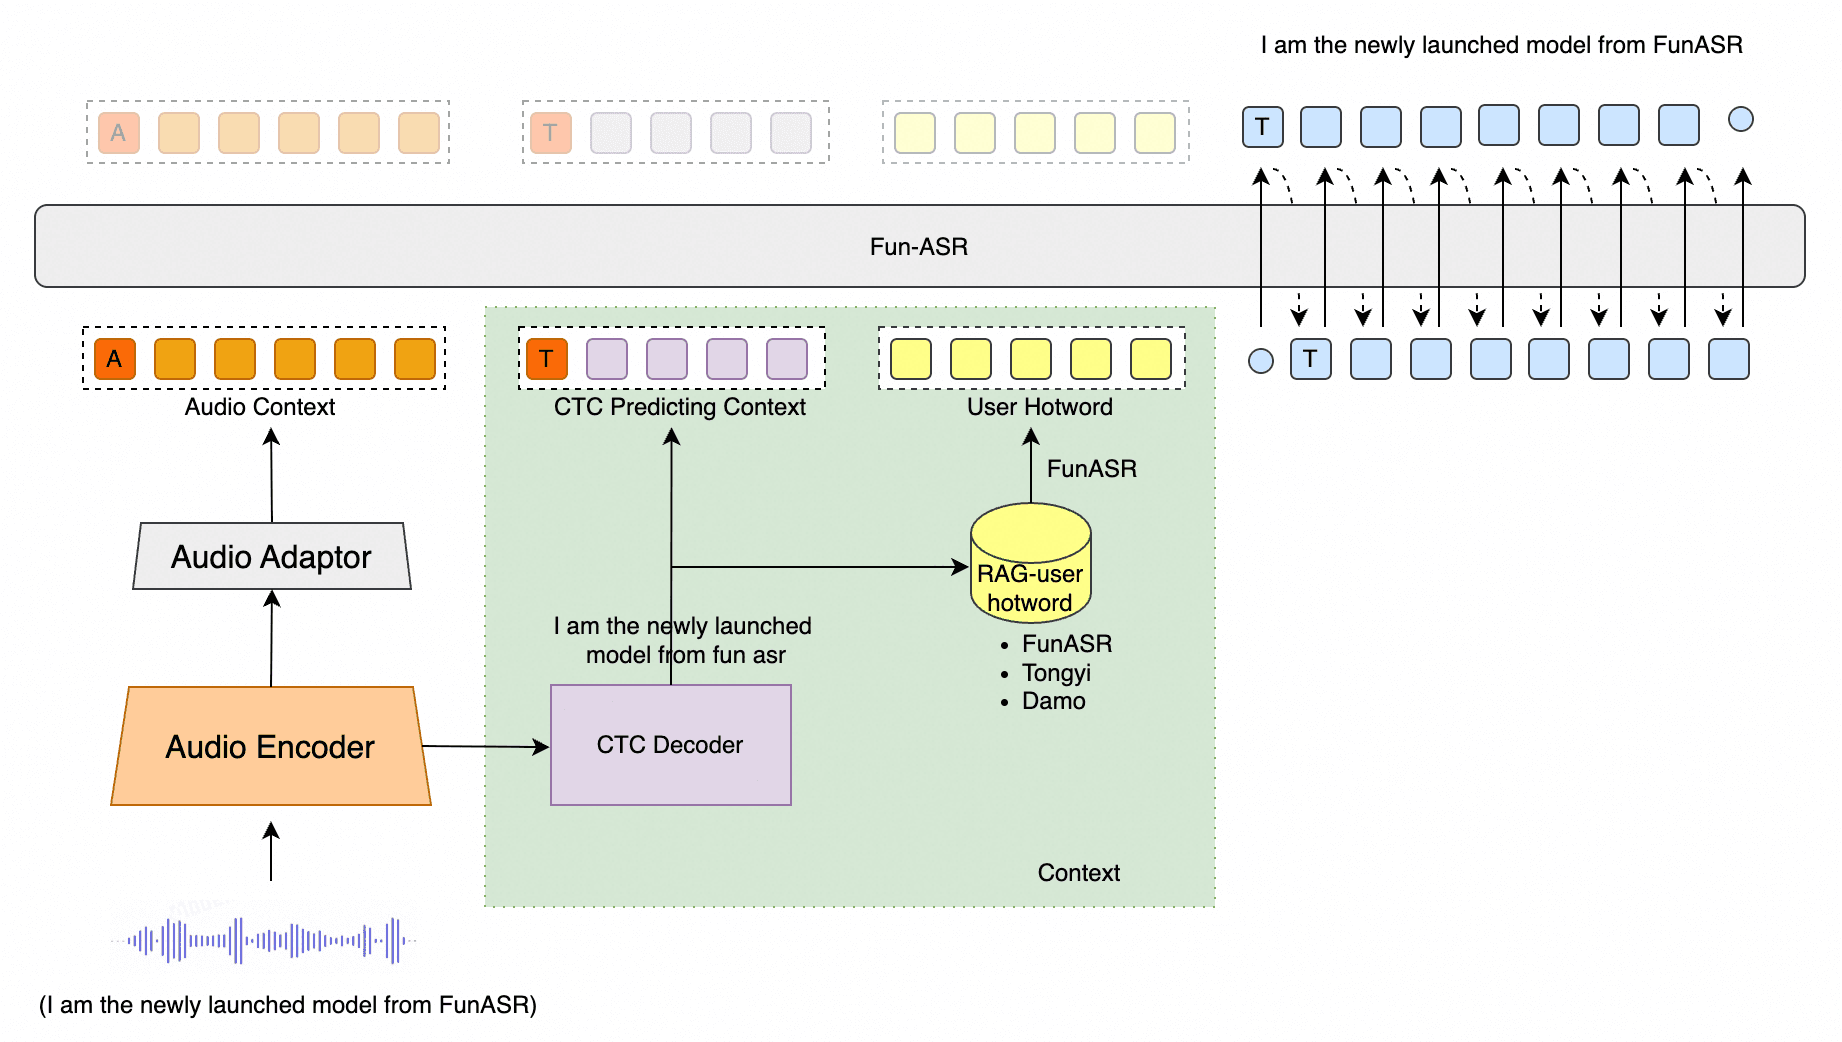
Alibaba's Qwen team has released Fun-ASR-Nano-2512, a new automatic speech recognition (ASR) model designed for efficiency and real-time performance. As its "Nano" designation suggests, the model is compact, making it a candidate for applications where computational resources are constrained.
Fun-ASR-Nano moves beyond simple transcription by integrating several advanced features often found in much larger systems. Its architecture is built for streaming audio, allowing it to process speech with low latency as it's spoken, rather than waiting for an entire audio file to be complete.
Structured Audio Output
This combination of features makes the model particularly useful for building sophisticated conversational AI and analysis tools. Key capabilities detailed in the official release include:
- Speaker diarization: Identifying who is speaking and when.
- Word-level timestamps: Aligning transcribed text with its precise timing in the source audio.
- Hotword detection: Customizing the model to reliably recognize specific keywords.
- Multilingual support: Processing speech from multiple languages.
By packaging these tools into a lightweight model, the Qwen team provides a powerful component for developers creating on-device or edge applications, such as smart meeting assistants or embedded voice-controlled interfaces. The model is available under the custom Model-Scope Open-Source License.
Sources
- Visit
FunAudioLLM/Fun-ASR-Nano-2512
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
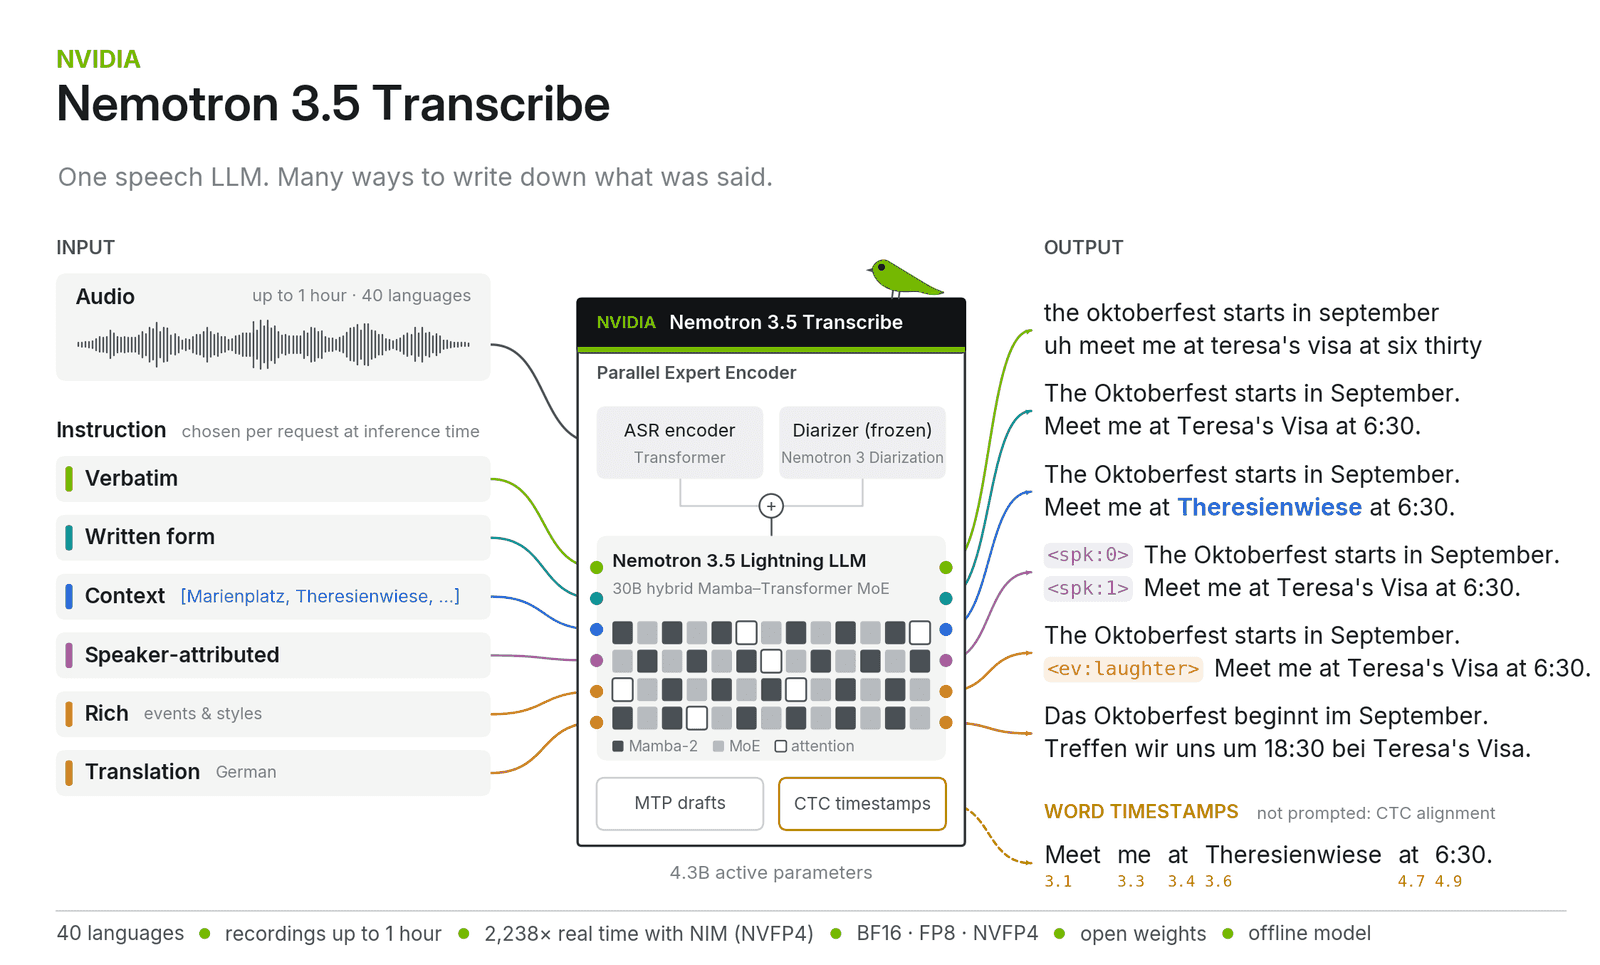
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
TII extends the Falcon family into speech recognition
The Abu Dhabi lab behind the Falcon language models releases Falcon ASR, an open speech-to-text system.
0 comments
No comments yet. Be the first to weigh in.