PersonaLive Model Animates Portraits in Real Time
The new open-source model from OpenBMB uses a diffusion-based architecture to generate expressive video from a single still image.
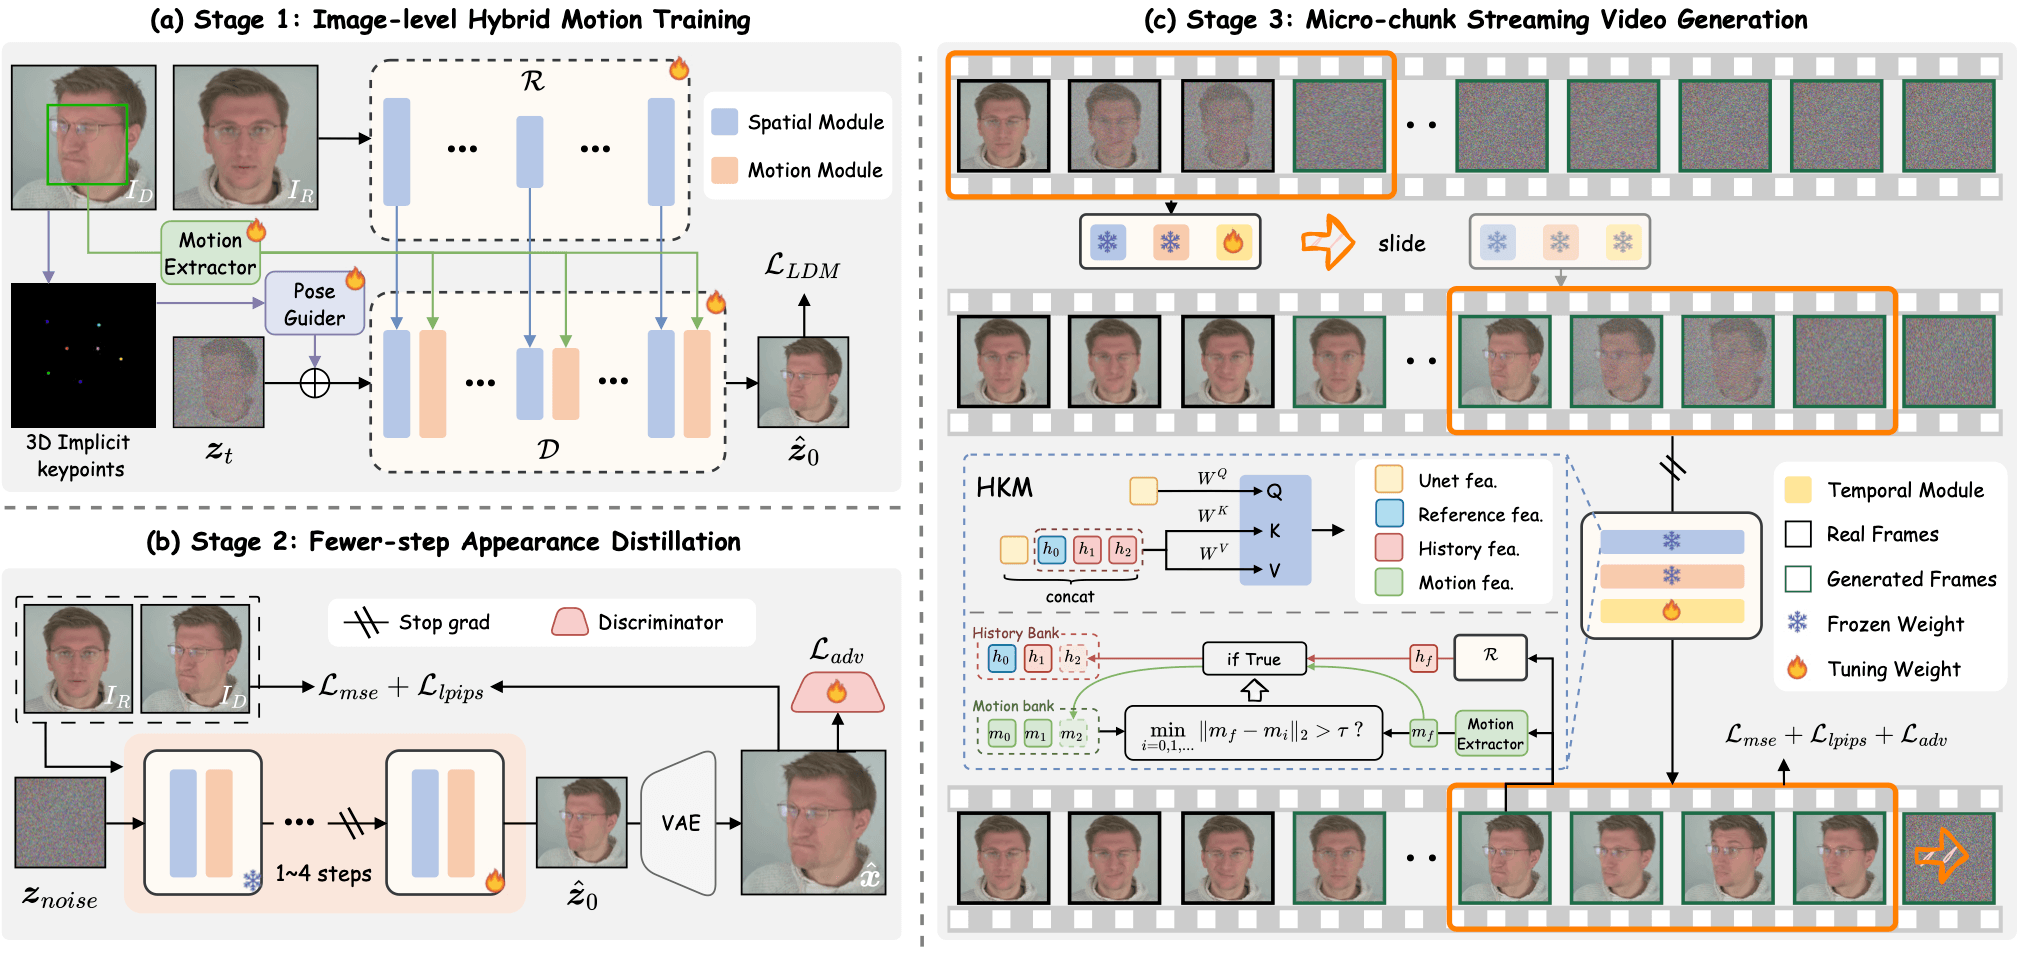
Researchers at OpenBMB have released PersonaLive, an open-source model that brings a single still photograph to life with real-time animation. The project tackles the challenge of creating expressive, live digital avatars by generating video directly from a reference portrait, a significant step forward for interactive AI applications.
Unlike many video generation models that require lengthy processing, PersonaLive is designed for low-latency performance. It employs a diffusion-based architecture, a powerful technique typically associated with high-quality but slower image synthesis. The model's ability to adapt this for live interaction marks a notable engineering achievement in generative AI.
Under the Hood
The efficiency of PersonaLive comes from a carefully optimized architecture. According to the project's technical details, its core components are engineered to be lightweight:
- A streamlined reference encoder captures the subject's core identity from the source image.
- An efficient UNet-based noise predictor generates the animation frames.
- A fast diffusion process enables the model to synthesize video output in real time.
Published on Hugging Face under a permissive Apache 2.0 license, PersonaLive provides a foundational tool for developers. Its release could power a new wave of applications in video conferencing, virtual live-streaming, and interactive entertainment, offering an open alternative to the proprietary avatar systems built by major tech platforms.
Sources
- Visit
huaichang/PersonaLive
Hugging Face
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
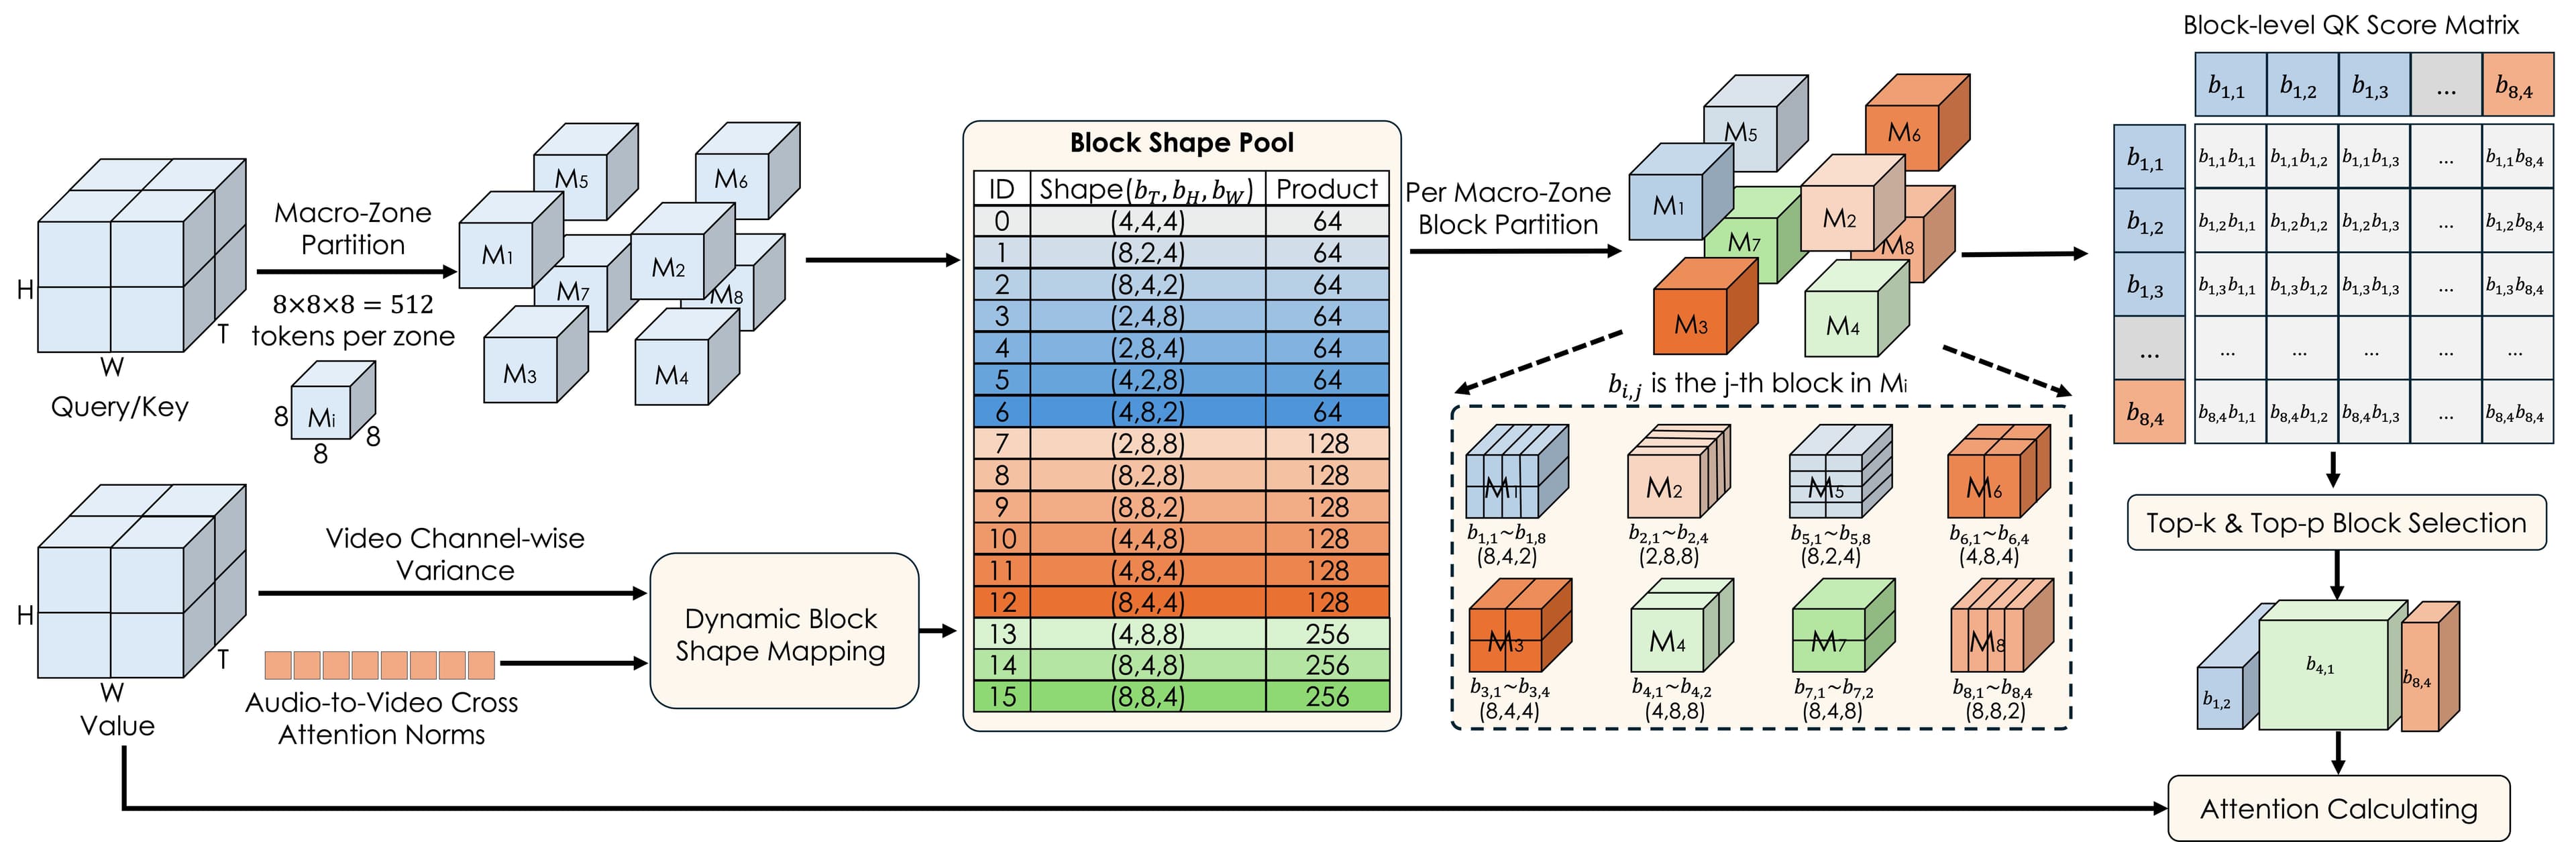
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.