Google Releases MedASR for Medical Transcription
The new speech recognition model from DeepMind is trained specifically on medical dictation, aiming for higher accuracy in clinical notes.
Google DeepMind has released MedASR, a new automatic speech recognition (ASR) model designed to accurately transcribe medical dictation. The model targets the specific vocabulary, jargon, and syntax used by clinicians, a domain where general-purpose transcription tools often fall short.
MedASR is specialized for English-language medical speech, with a particular focus on the demanding field of radiology. This narrow training allows it to better handle complex terminology and the rapid dictation style common in clinical settings, aiming to produce cleaner and more reliable electronic health records from spoken notes.
The potential impact of high-accuracy medical ASR is significant. By reducing the time physicians spend manually correcting transcripts, specialized models can help alleviate administrative burdens and allow clinicians to focus more on patient care. Accurate documentation is also critical for billing, insurance, and maintaining a reliable patient history.
While the model is available for exploration, its license carries an important restriction. The weights for MedASR are provided for non-commercial use only, which limits its direct integration into commercial healthcare products. This positions the release primarily as a resource for researchers and developers to build upon for future healthcare applications.
Sources
- Visit
google/medasr
Hugging Face
More from Google DeepMind
All Google DeepMind releases →
EmbeddingGemma 2 Expands to Any Modality
Google DeepMind's compact embedding model now spans text, vision, audio, and video in a single vector space.
Google DeepMind's Gemma 4 Goes Multimodal and MoE
The new open-weights family adds a mixture-of-experts design, encoder-free multimodal inputs, and an optional thinking mode.
Google DeepMind Releases TabFM for Tabular Data
A new foundation model brings zero-shot, in-context learning to classification and regression on structured tables.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
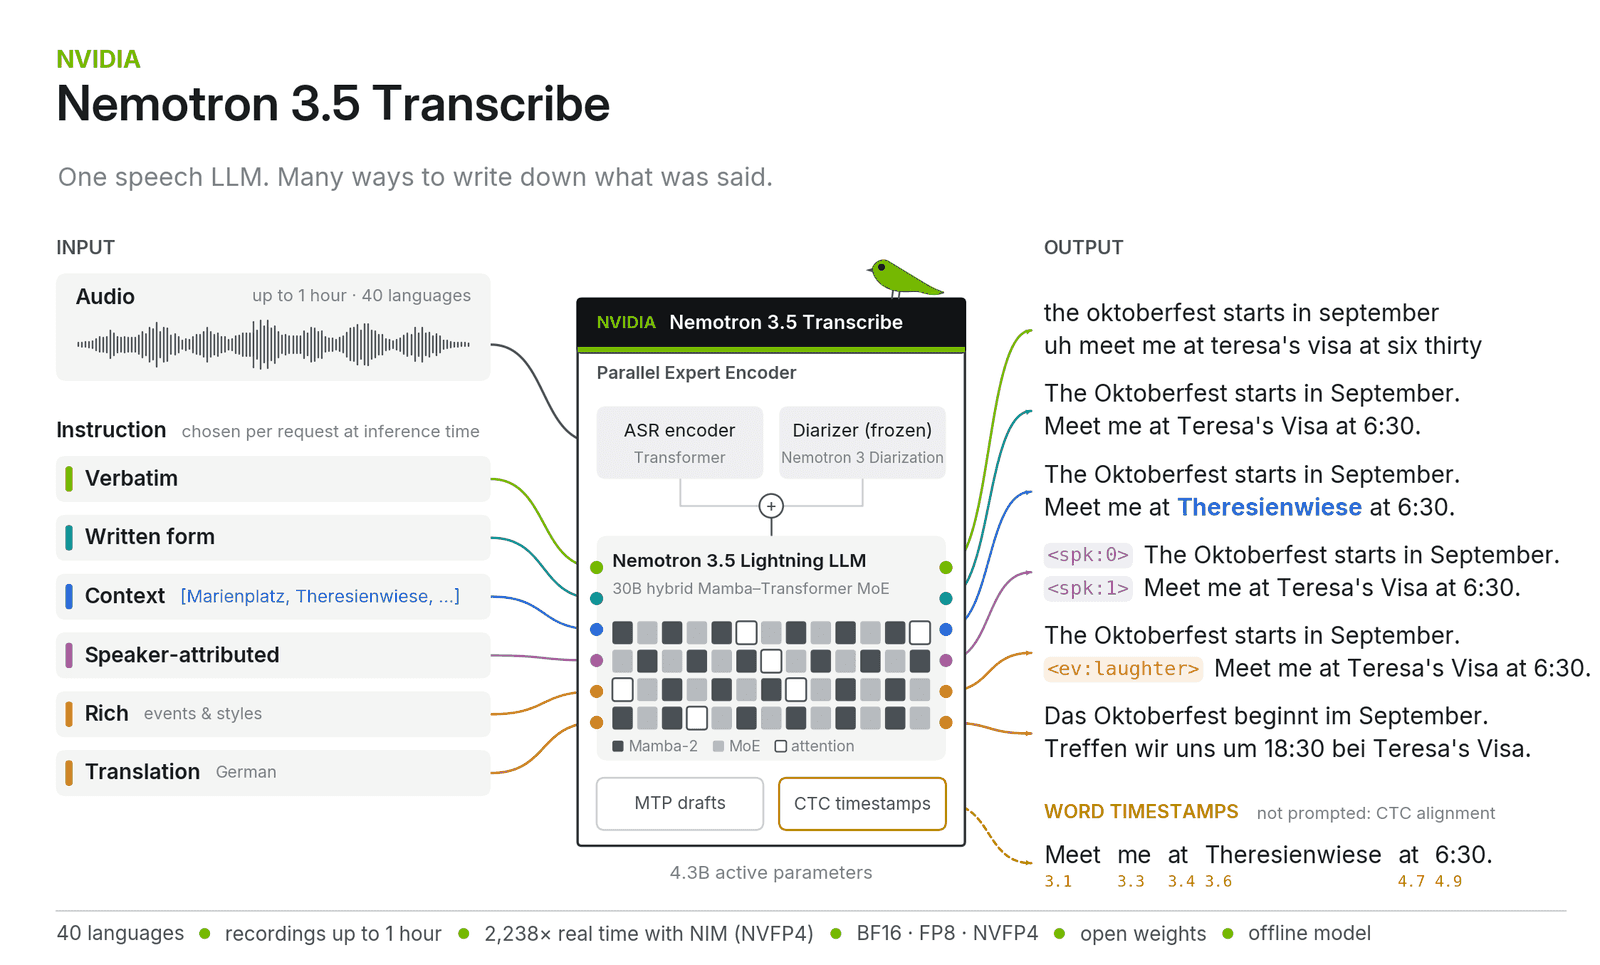
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.