Qwen3 Family Expands into Speech Recognition
Alibaba's Qwen team has released a new 1.7-billion-parameter model designed specifically for automatic speech recognition.

The Qwen team at Alibaba has released Qwen3-ASR-1.7B, extending its new generation of models into the domain of audio processing. This 1.7-billion-parameter model is designed for automatic speech recognition (ASR), also known as speech-to-text, and is now available on the Hugging Face Hub.
Unlike general-purpose language models, Qwen3-ASR is a specialized tool focused on a single task: accurately transcribing spoken language into written text. This makes it a foundational component for a wide range of applications, from creating meeting transcripts and video subtitles to enabling voice-activated user interfaces and accessibility tools.
The release provides another strong open-source option in a field largely defined by models like OpenAI's Whisper. With its Apache 2.0 license, Qwen3-ASR-1.7B offers a permissively licensed alternative for developers and businesses to build upon without restrictive terms. Its relatively moderate size suggests a balance between performance and computational efficiency, making it potentially suitable for a variety of hardware environments.
Sources
- Visit
Qwen/Qwen3-ASR-1.7B
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
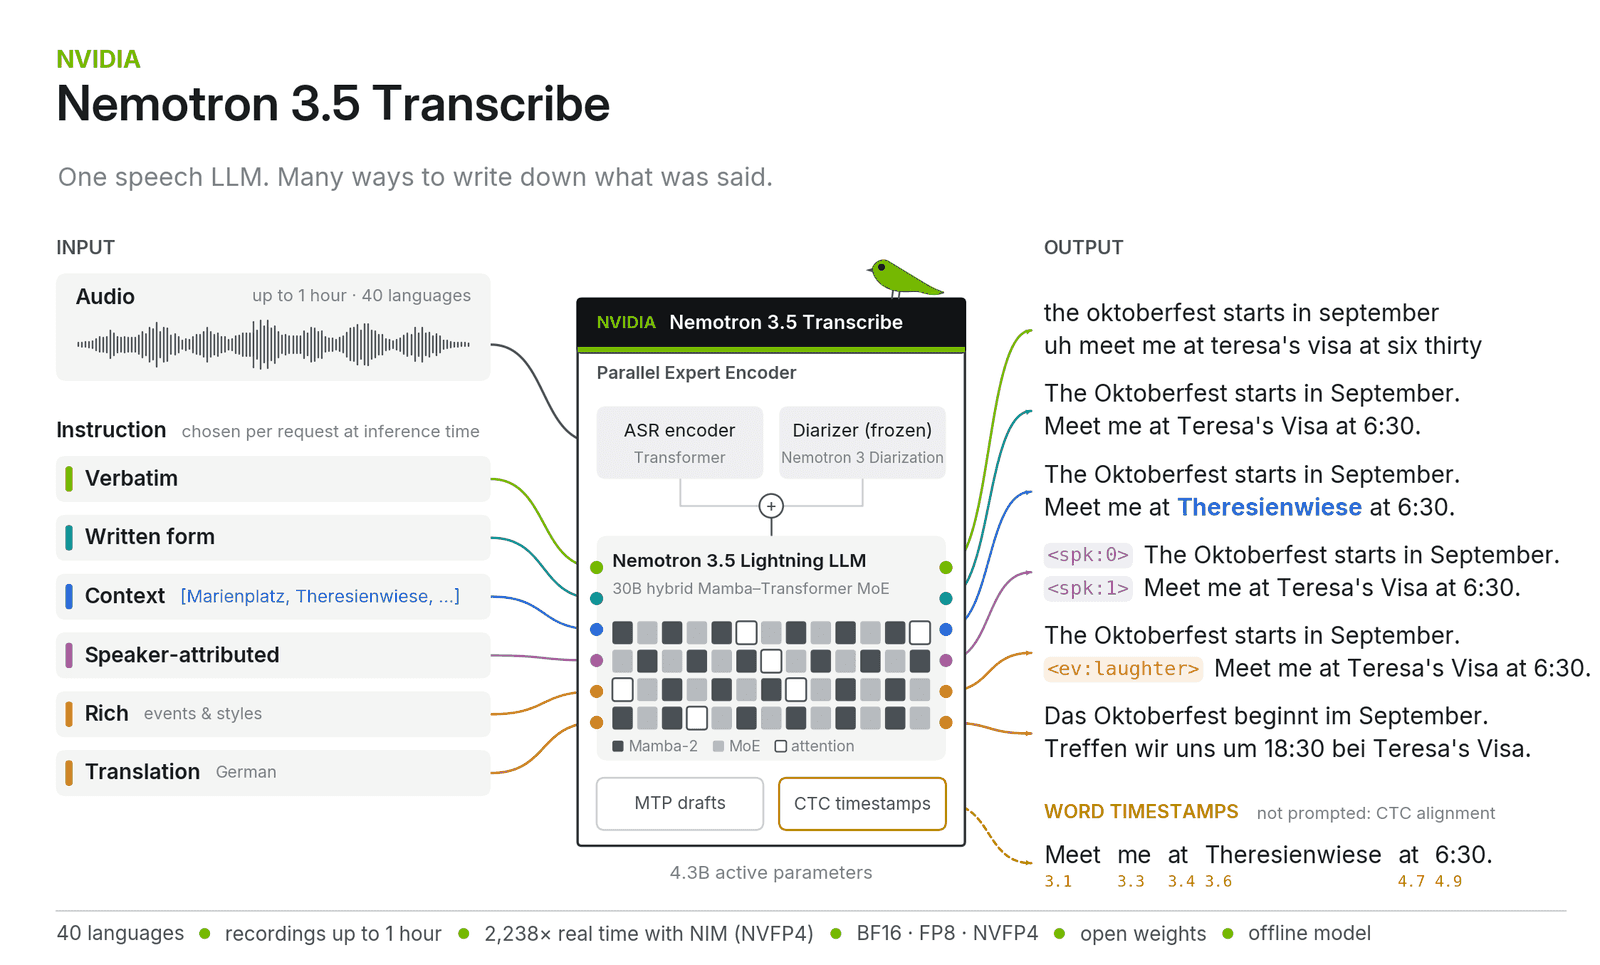
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
TII extends the Falcon family into speech recognition
The Abu Dhabi lab behind the Falcon language models releases Falcon ASR, an open speech-to-text system.
0 comments
No comments yet. Be the first to weigh in.