Mega-ASR Improves on Qwen for Speech Recognition
Researcher Zhifei Xie has released a 1.7B-parameter model that refines Alibaba's Qwen3-ASR, showing improved performance on English and Chinese transcription benchmarks.
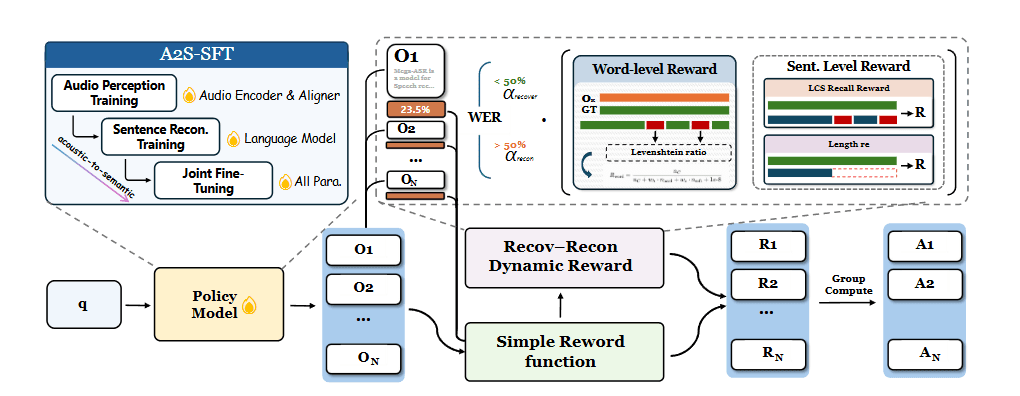
A new speech recognition model called Mega-ASR has been released by researcher Zhifei Xie, offering a strong open-source option for English and Chinese transcription. The 1.7 billion-parameter model is a fine-tuned version of Alibaba's recently released Qwen3-ASR-1.7B, demonstrating how community efforts can quickly build upon and specialize foundational models.
This release highlights the collaborative nature of open-source AI. By taking a capable base model and training it further on a curated mix of public and private datasets, the developer was able to enhance its performance for specific use cases. The model's permissive Apache 2.0 license allows it to be freely used and modified, even for commercial applications, encouraging further adoption and innovation.
Fine-Tuning for Robustness
According to performance metrics shared by the developer, Mega-ASR achieves a lower word and character error rate than both its base model and OpenAI's Whisper-large-v3 across several key benchmarks. The improvements are particularly notable on Chinese language datasets like AISHELL-1 and Wenetspeech, suggesting the additional training successfully targeted areas for improvement.
For developers and researchers working with English or Chinese audio, Mega-ASR represents a powerful and accessible tool for automatic speech recognition. The model is available for download and use from its Hugging Face repository, where the author has also provided details on its training process and evaluation results.
Sources
- Visit
zhifeixie/Mega-ASR
Hugging Face
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
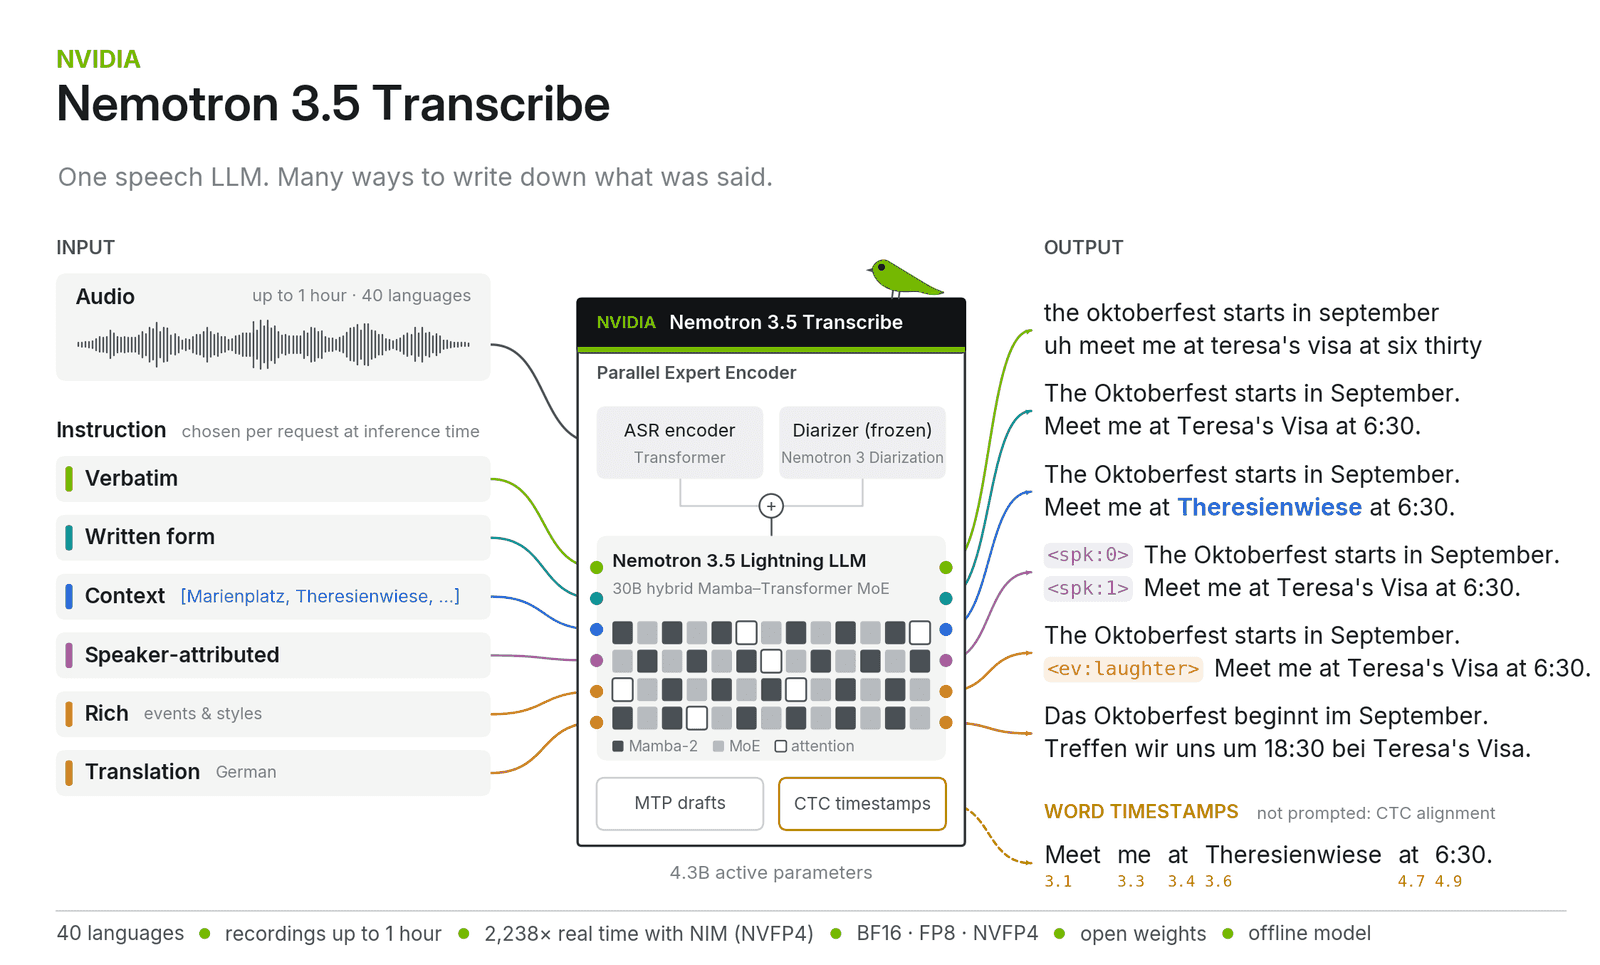
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.