Mistral Enters Speech AI with Voxtral Mini Model
The company, known for its powerful text models, has released its first open-source speech recognition system designed for real-time, multilingual transcription.
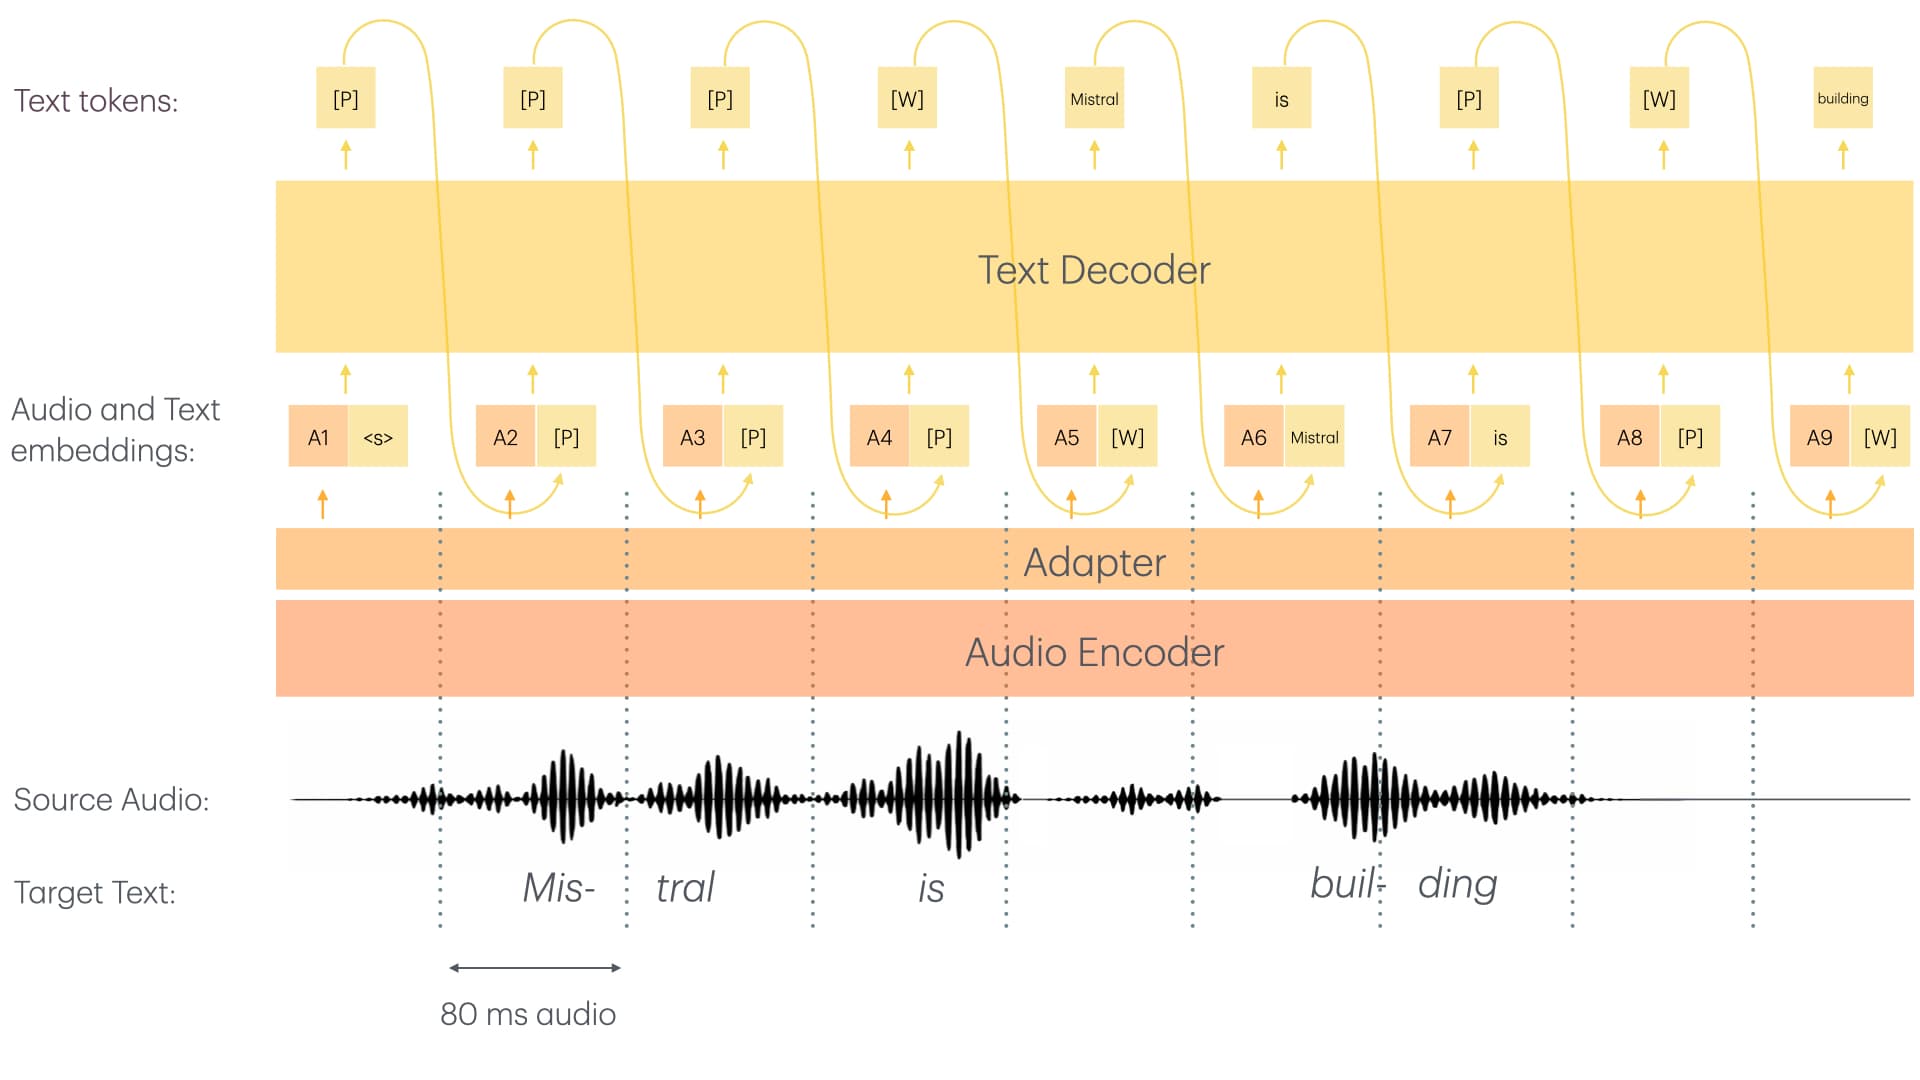
Mistral AI, a company that has rapidly built a reputation for its powerful open-source text models, has released Voxtral Mini 4B Realtime, its first publicly available model for automatic speech recognition (ASR).
This new 4-billion-parameter system is designed specifically for real-time, multilingual speech-to-text applications. Its focus on low-latency performance makes it a candidate for tasks like live captioning, meeting transcription, and voice-activated assistants where immediate feedback is critical.
A New Modality for Mistral
The release signals a significant expansion for the Paris-based AI lab. While previously focused exclusively on text generation with models like Mistral 7B and Mixtral, the company is now entering the competitive audio AI space. This move positions Voxtral as an open-source alternative to established ASR systems, including OpenAI's popular Whisper model.
By releasing Voxtral Mini under a permissive Apache 2.0 license, Mistral continues its strategy of providing foundational tools for developers. The model is now available for download and experimentation on the Hugging Face Hub, allowing the community to build upon and integrate it into new voice-powered applications.
Sources
- Visit
mistralai/Voxtral-Mini-4B-Realtime-2602
Hugging Face
More from Mistral AI
All Mistral AI releases →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
Mistral's Timestral brings forecasting to open weights
The French lab releases a compact 209M-parameter foundation model aimed squarely at time-series prediction.
Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
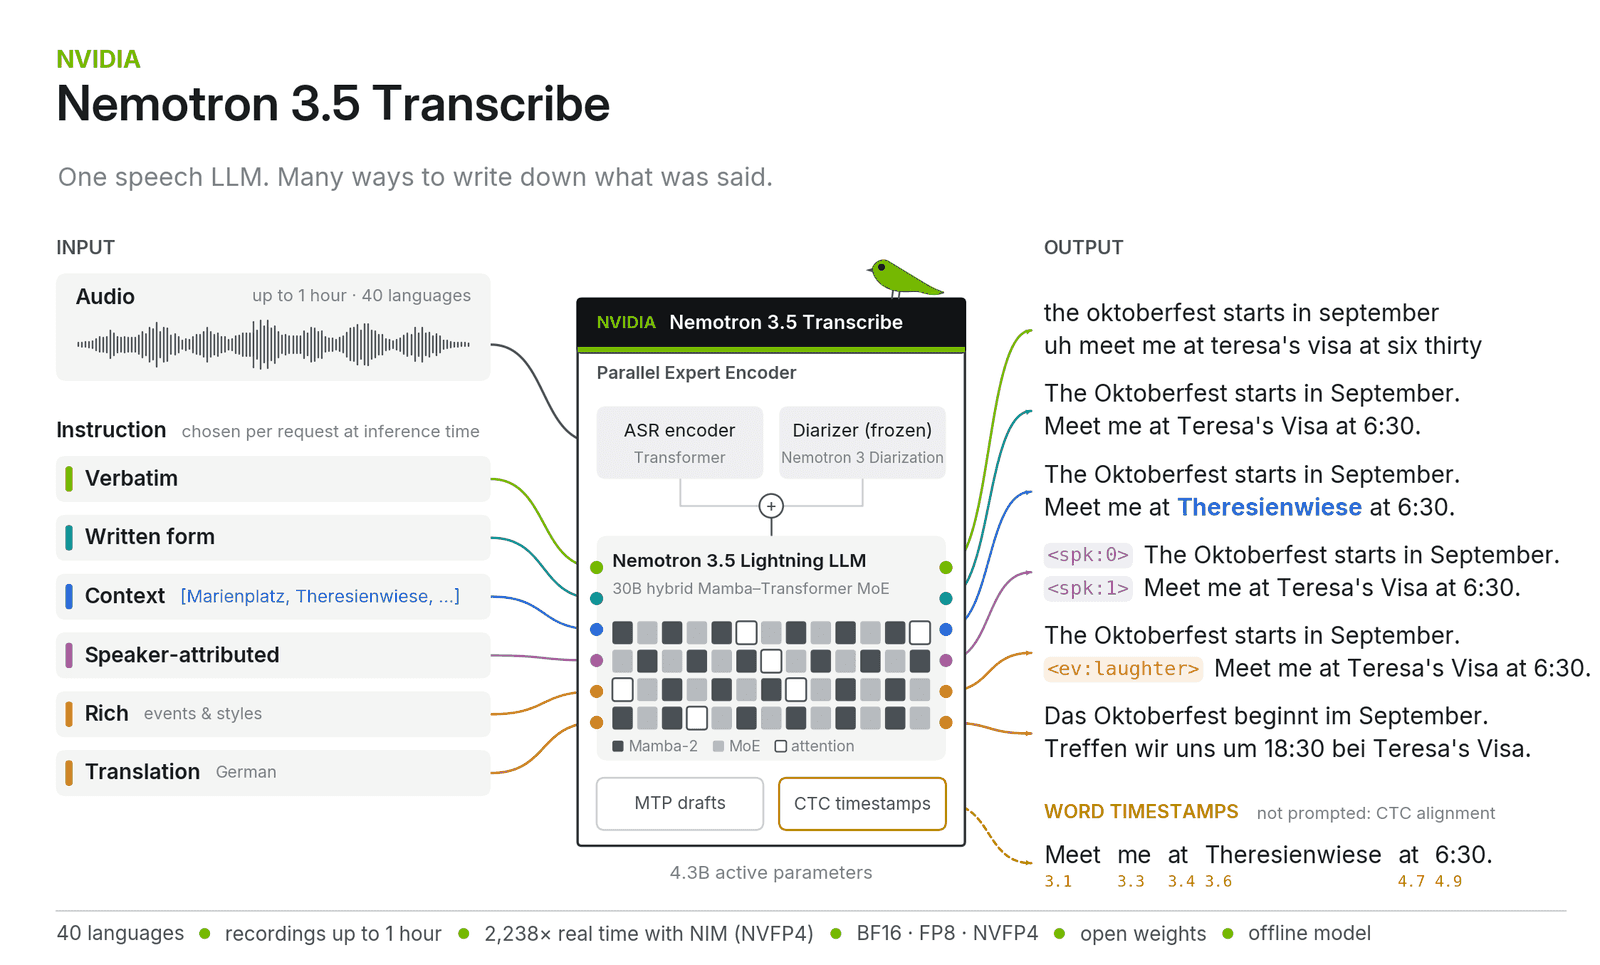
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.