Moonshine: Open STT Models Aim to Beat Whisper
Resemble AI releases MIT-licensed speech-to-text models that claim higher accuracy than OpenAI's Whisper Large v3.
Resemble AI has released Moonshine, a family of open-weight speech-to-text models that the company claims achieve higher accuracy than OpenAI's Whisper Large v3. The models are published under the permissive MIT license, making them straightforward to adopt in commercial as well as research projects, and are available on GitHub.
Moonshine arrives in the under-1B parameter range, positioning it as a comparatively lightweight option in a space where Whisper has become the default reference point for open transcription. The compact size matters: smaller automatic speech recognition models are easier to run on edge devices and consumer hardware, and they reduce the cost and latency of real-time transcription.
Why it matters
Whisper has dominated open speech recognition since its release, so any credible challenger draws attention. A permissively licensed alternative that claims to edge out Whisper Large v3 on accuracy could give developers a meaningful choice, particularly for applications where model footprint and licensing terms are deciding factors.
- MIT license, suitable for commercial use
- Open weights in the sub-1B parameter class
- Positioned as a direct accuracy competitor to Whisper Large v3
As always, vendor accuracy claims warrant independent verification across languages, accents, and noisy conditions before teams commit to a swap. But the combination of open weights, a permissive license, and a small footprint makes Moonshine worth a look for anyone building transcription into their stack.
Sources
- Visit
Show HN: Moonshine Open-Weights STT models – higher accuracy than WhisperLargev3
Hacker News
More from Resemble AI
All Resemble AI releases →
Resemble AI Releases Dramabox Voice Cloning TTS Model
The new text-to-speech model uses a diffusion-transformer architecture for high-quality, expressive audio and one-shot voice cloning.
Resemble AI Releases Chatterbox Turbo for Open TTS
The new text-to-speech model focuses on performance and offers voice cloning capabilities for English under a permissive MIT license.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
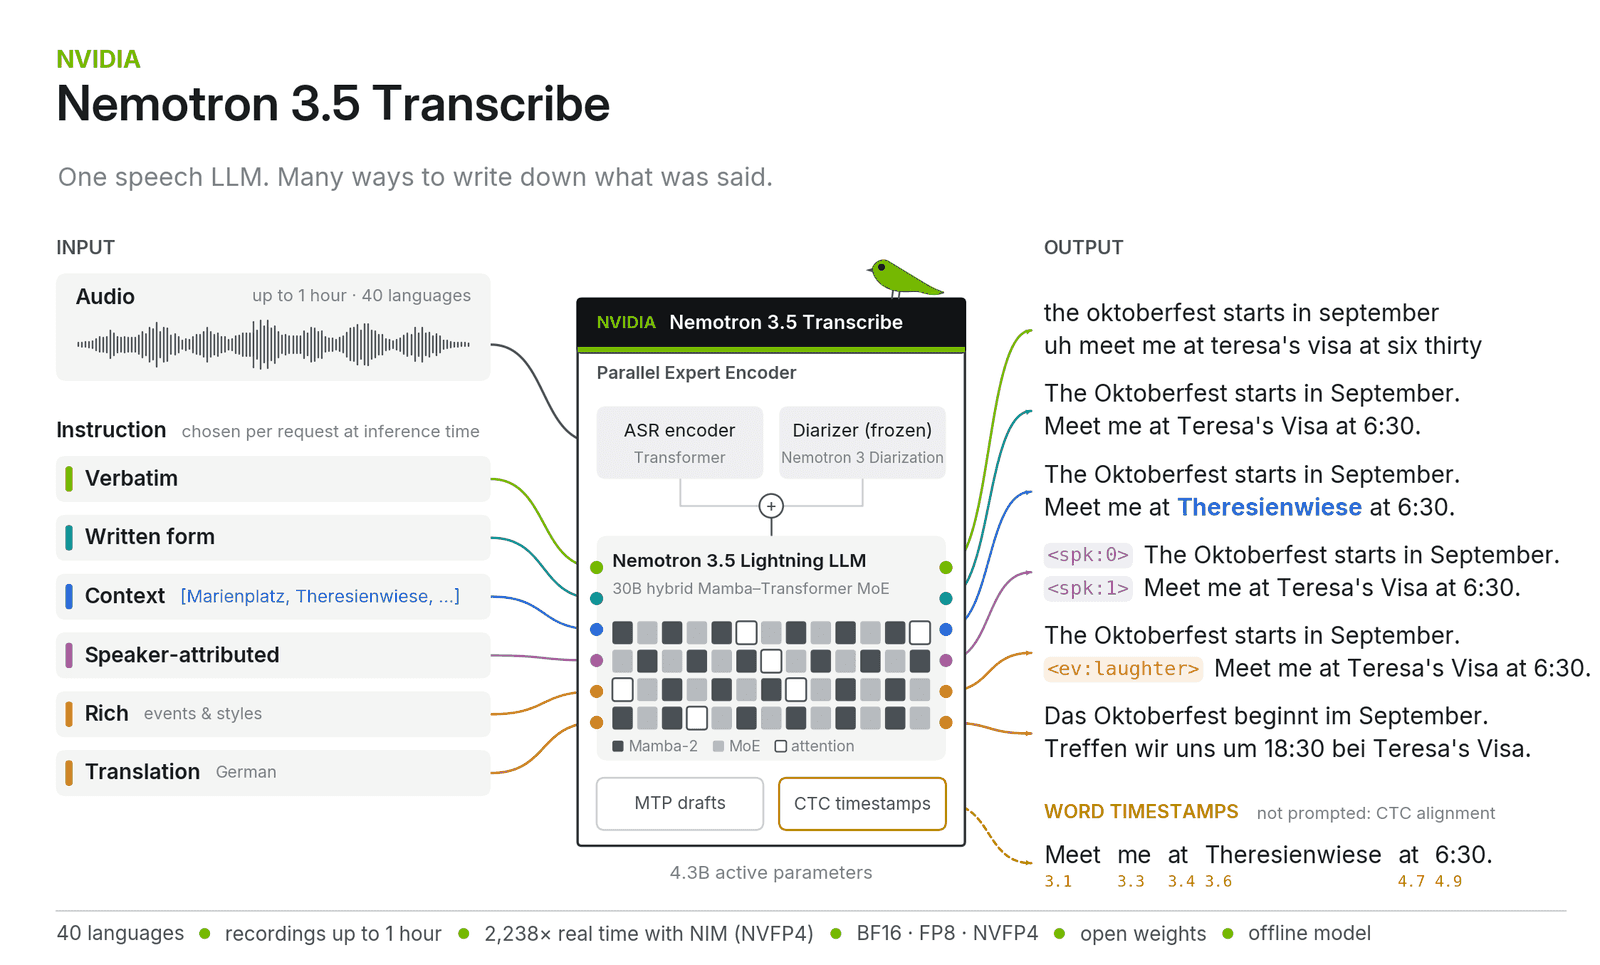
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.