SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
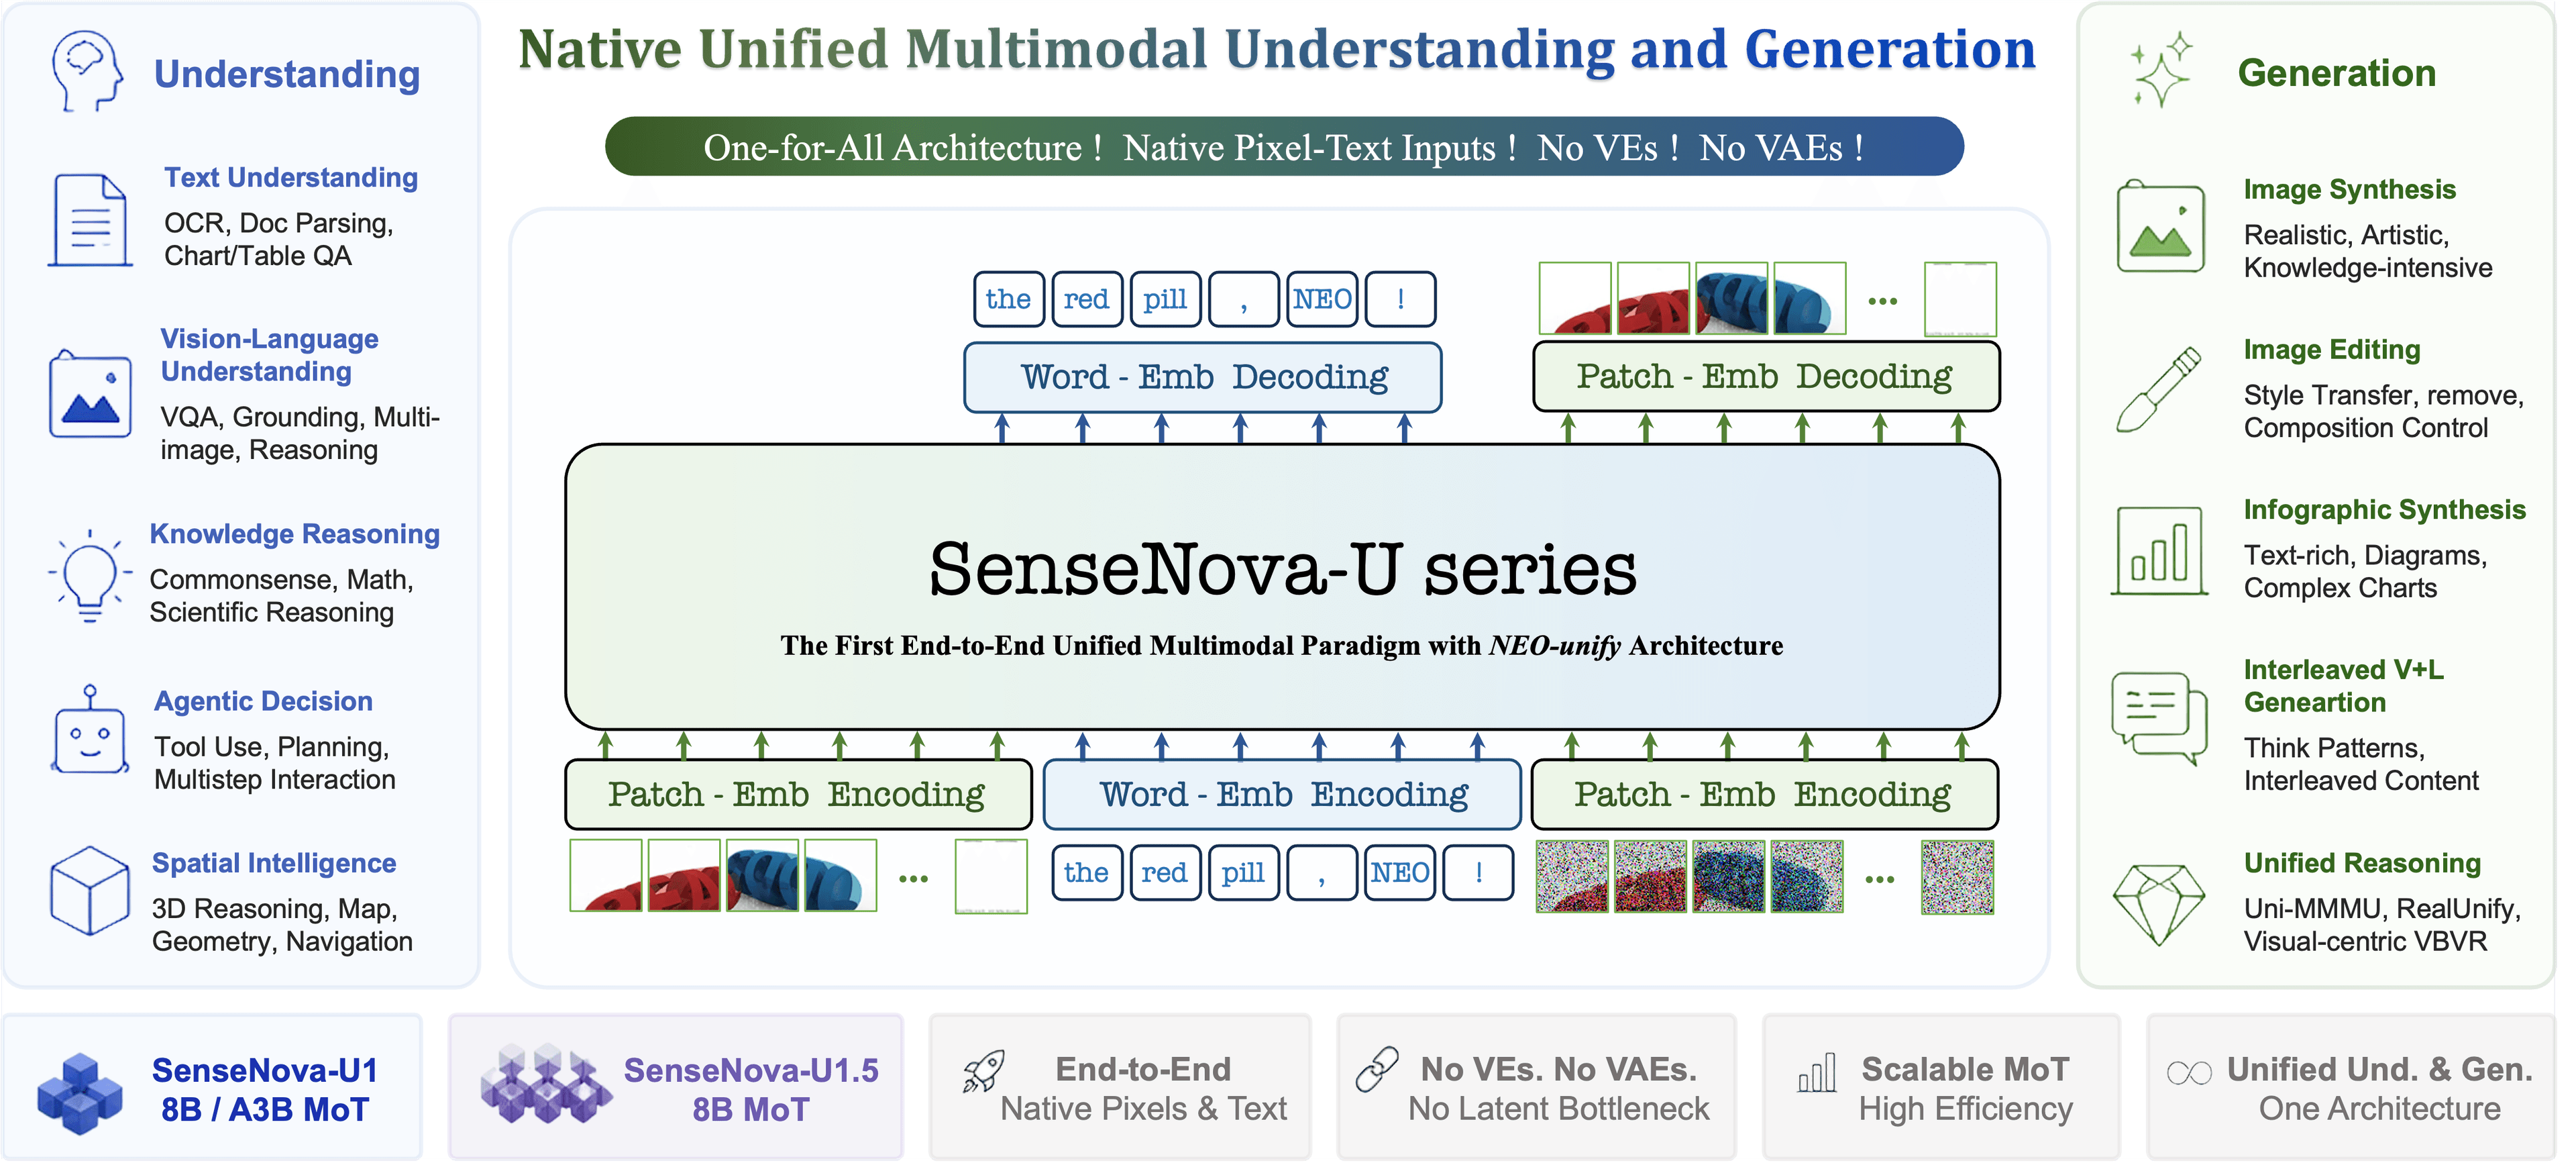
SenseTime has published SenseNova-U1.5-8B-MoT, an 8-billion-parameter multimodal model that treats different media as first-class citizens rather than bolting a vision encoder onto a text backbone. The release is available now on Hugging Face.
The headline feature is its any-to-any design. Where many open models specialize in reading images or writing text, U1.5 is built to move fluidly across modalities, including native image generation and image editing alongside its language capabilities.
Why it matters
Unified multimodal models have become a competitive frontier, with the appeal being a single set of weights that can understand and produce across formats without stitching together separate systems. Doing that at an 8B scale is notable, since it keeps the model within reach of researchers and developers who cannot run the largest frontier systems.
- Native any-to-any handling across text and images
- Built-in image generation and editing
- 8B parameters, a practical size for local and small-cluster use
A few important details are not spelled out in the release record, including context length and the exact licensing terms, which are listed simply as "other." Anyone planning production use should check the model card for usage restrictions before building on it. For now, U1.5 marks SenseTime's entry into the growing field of compact, genuinely multimodal open models.
Sources
- Visit
sensenova/SenseNova-U1.5-8B-MoT
Hugging Face
More from SenseTime
All SenseTime releases →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.
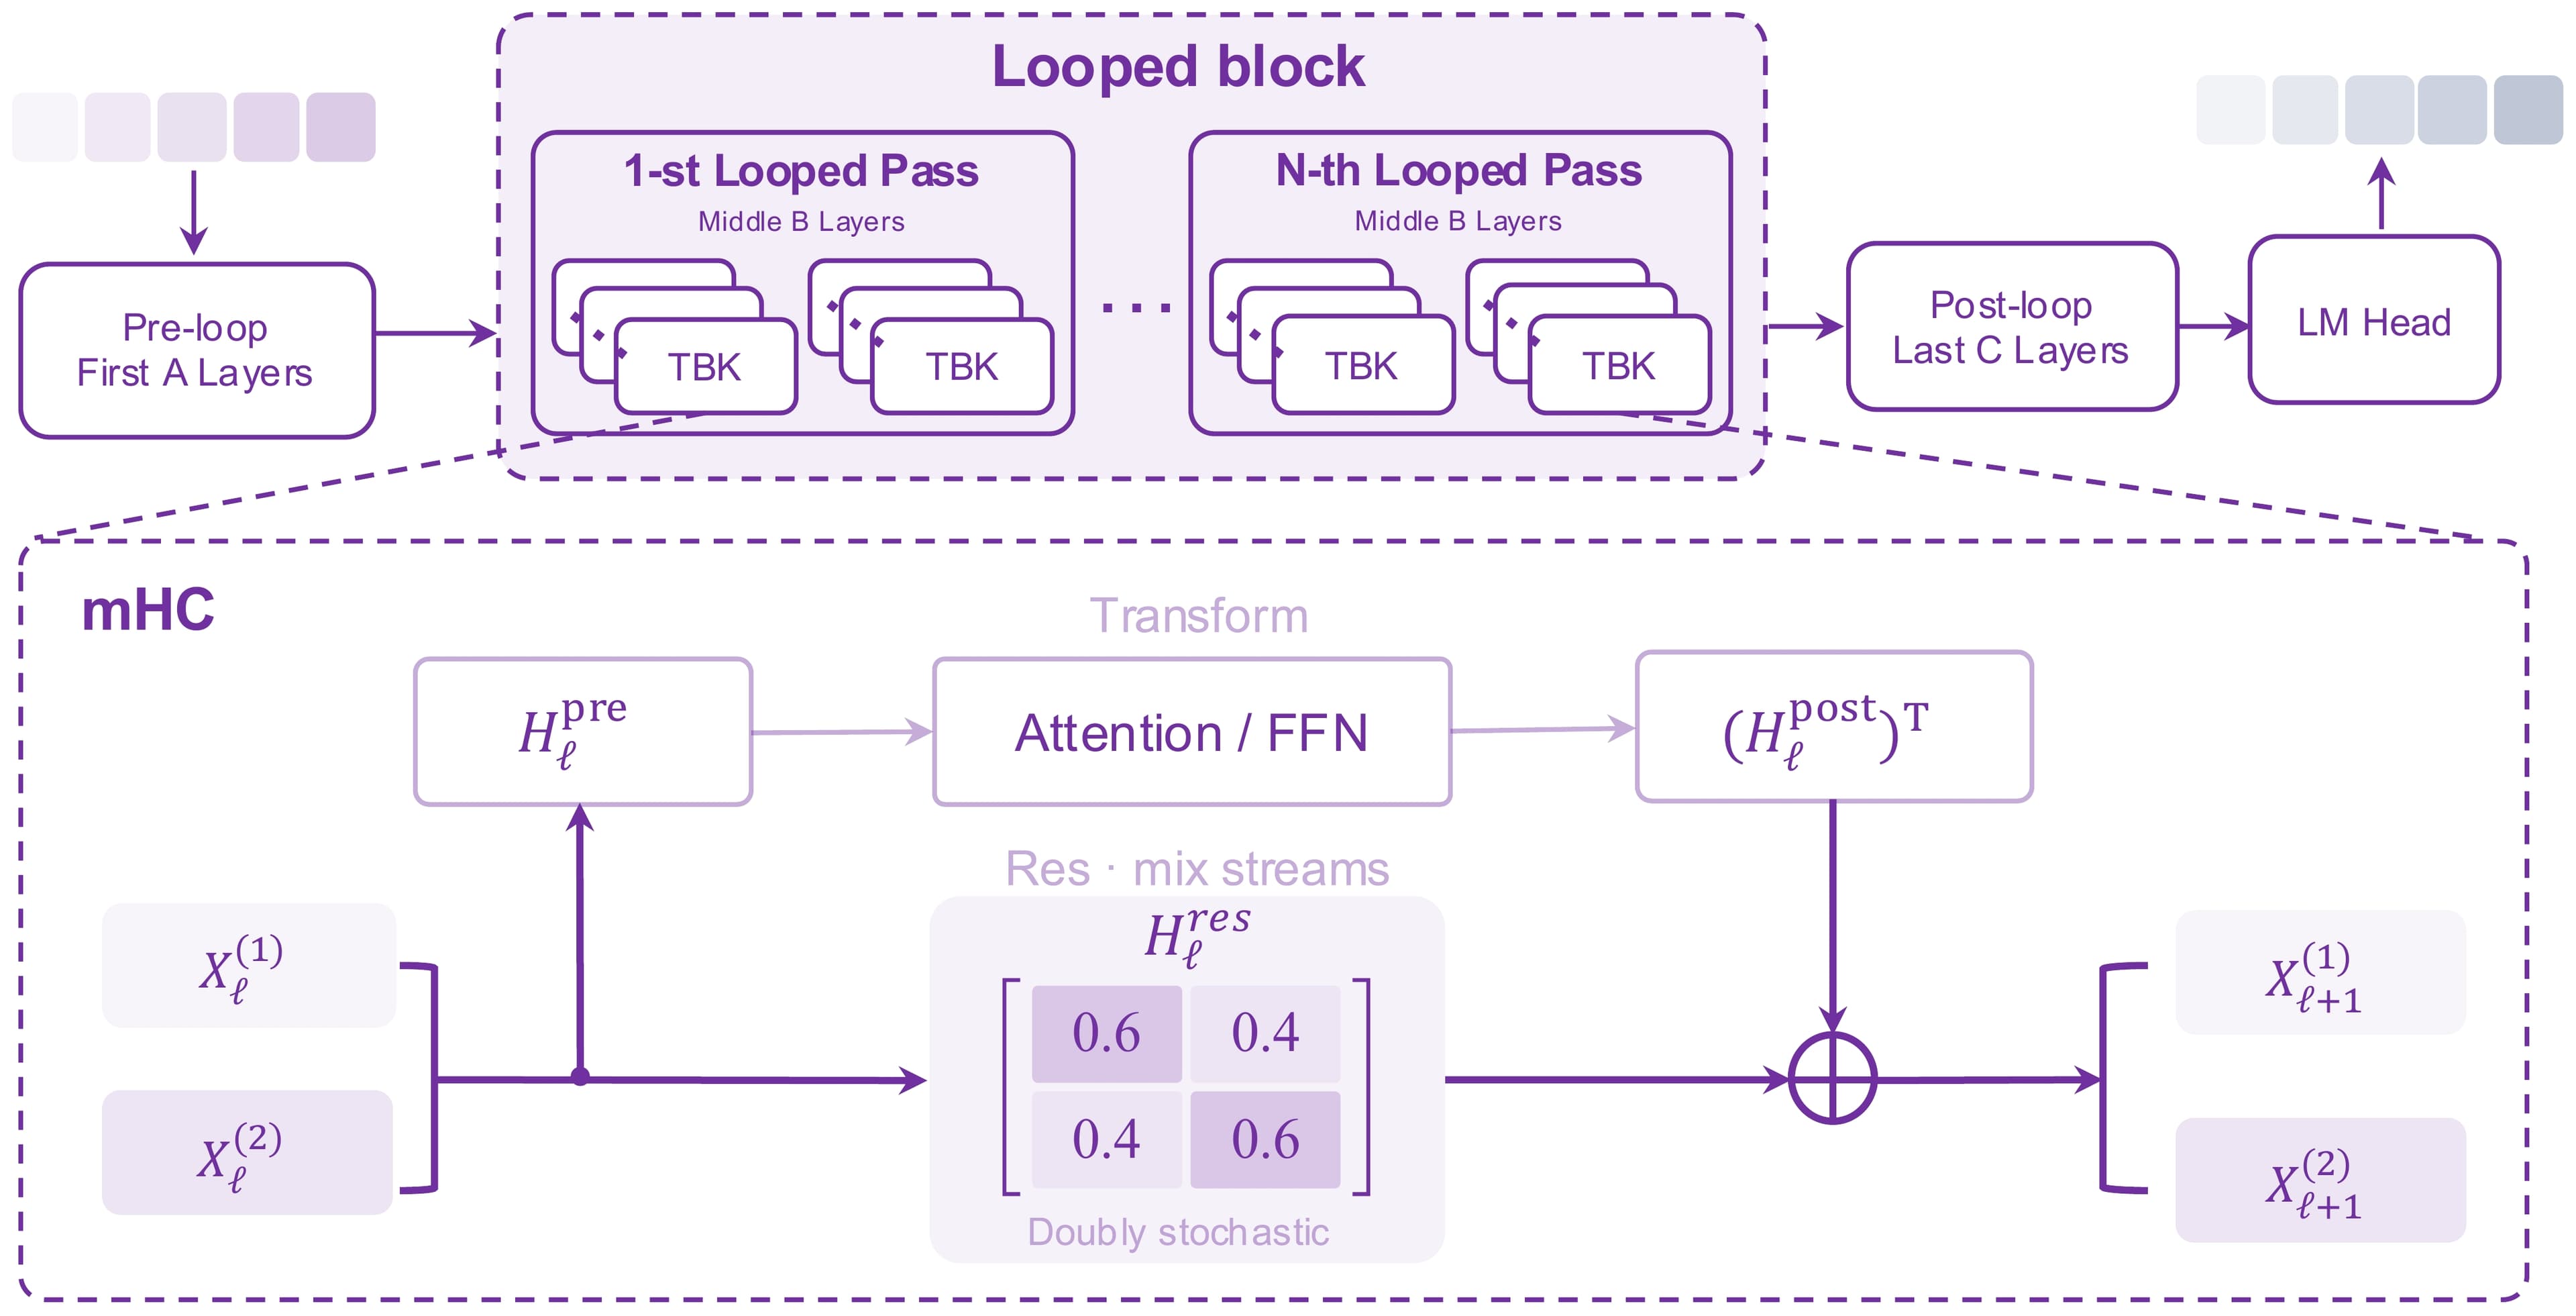
SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.
SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
More in Any-to-Any
All Any-to-Any →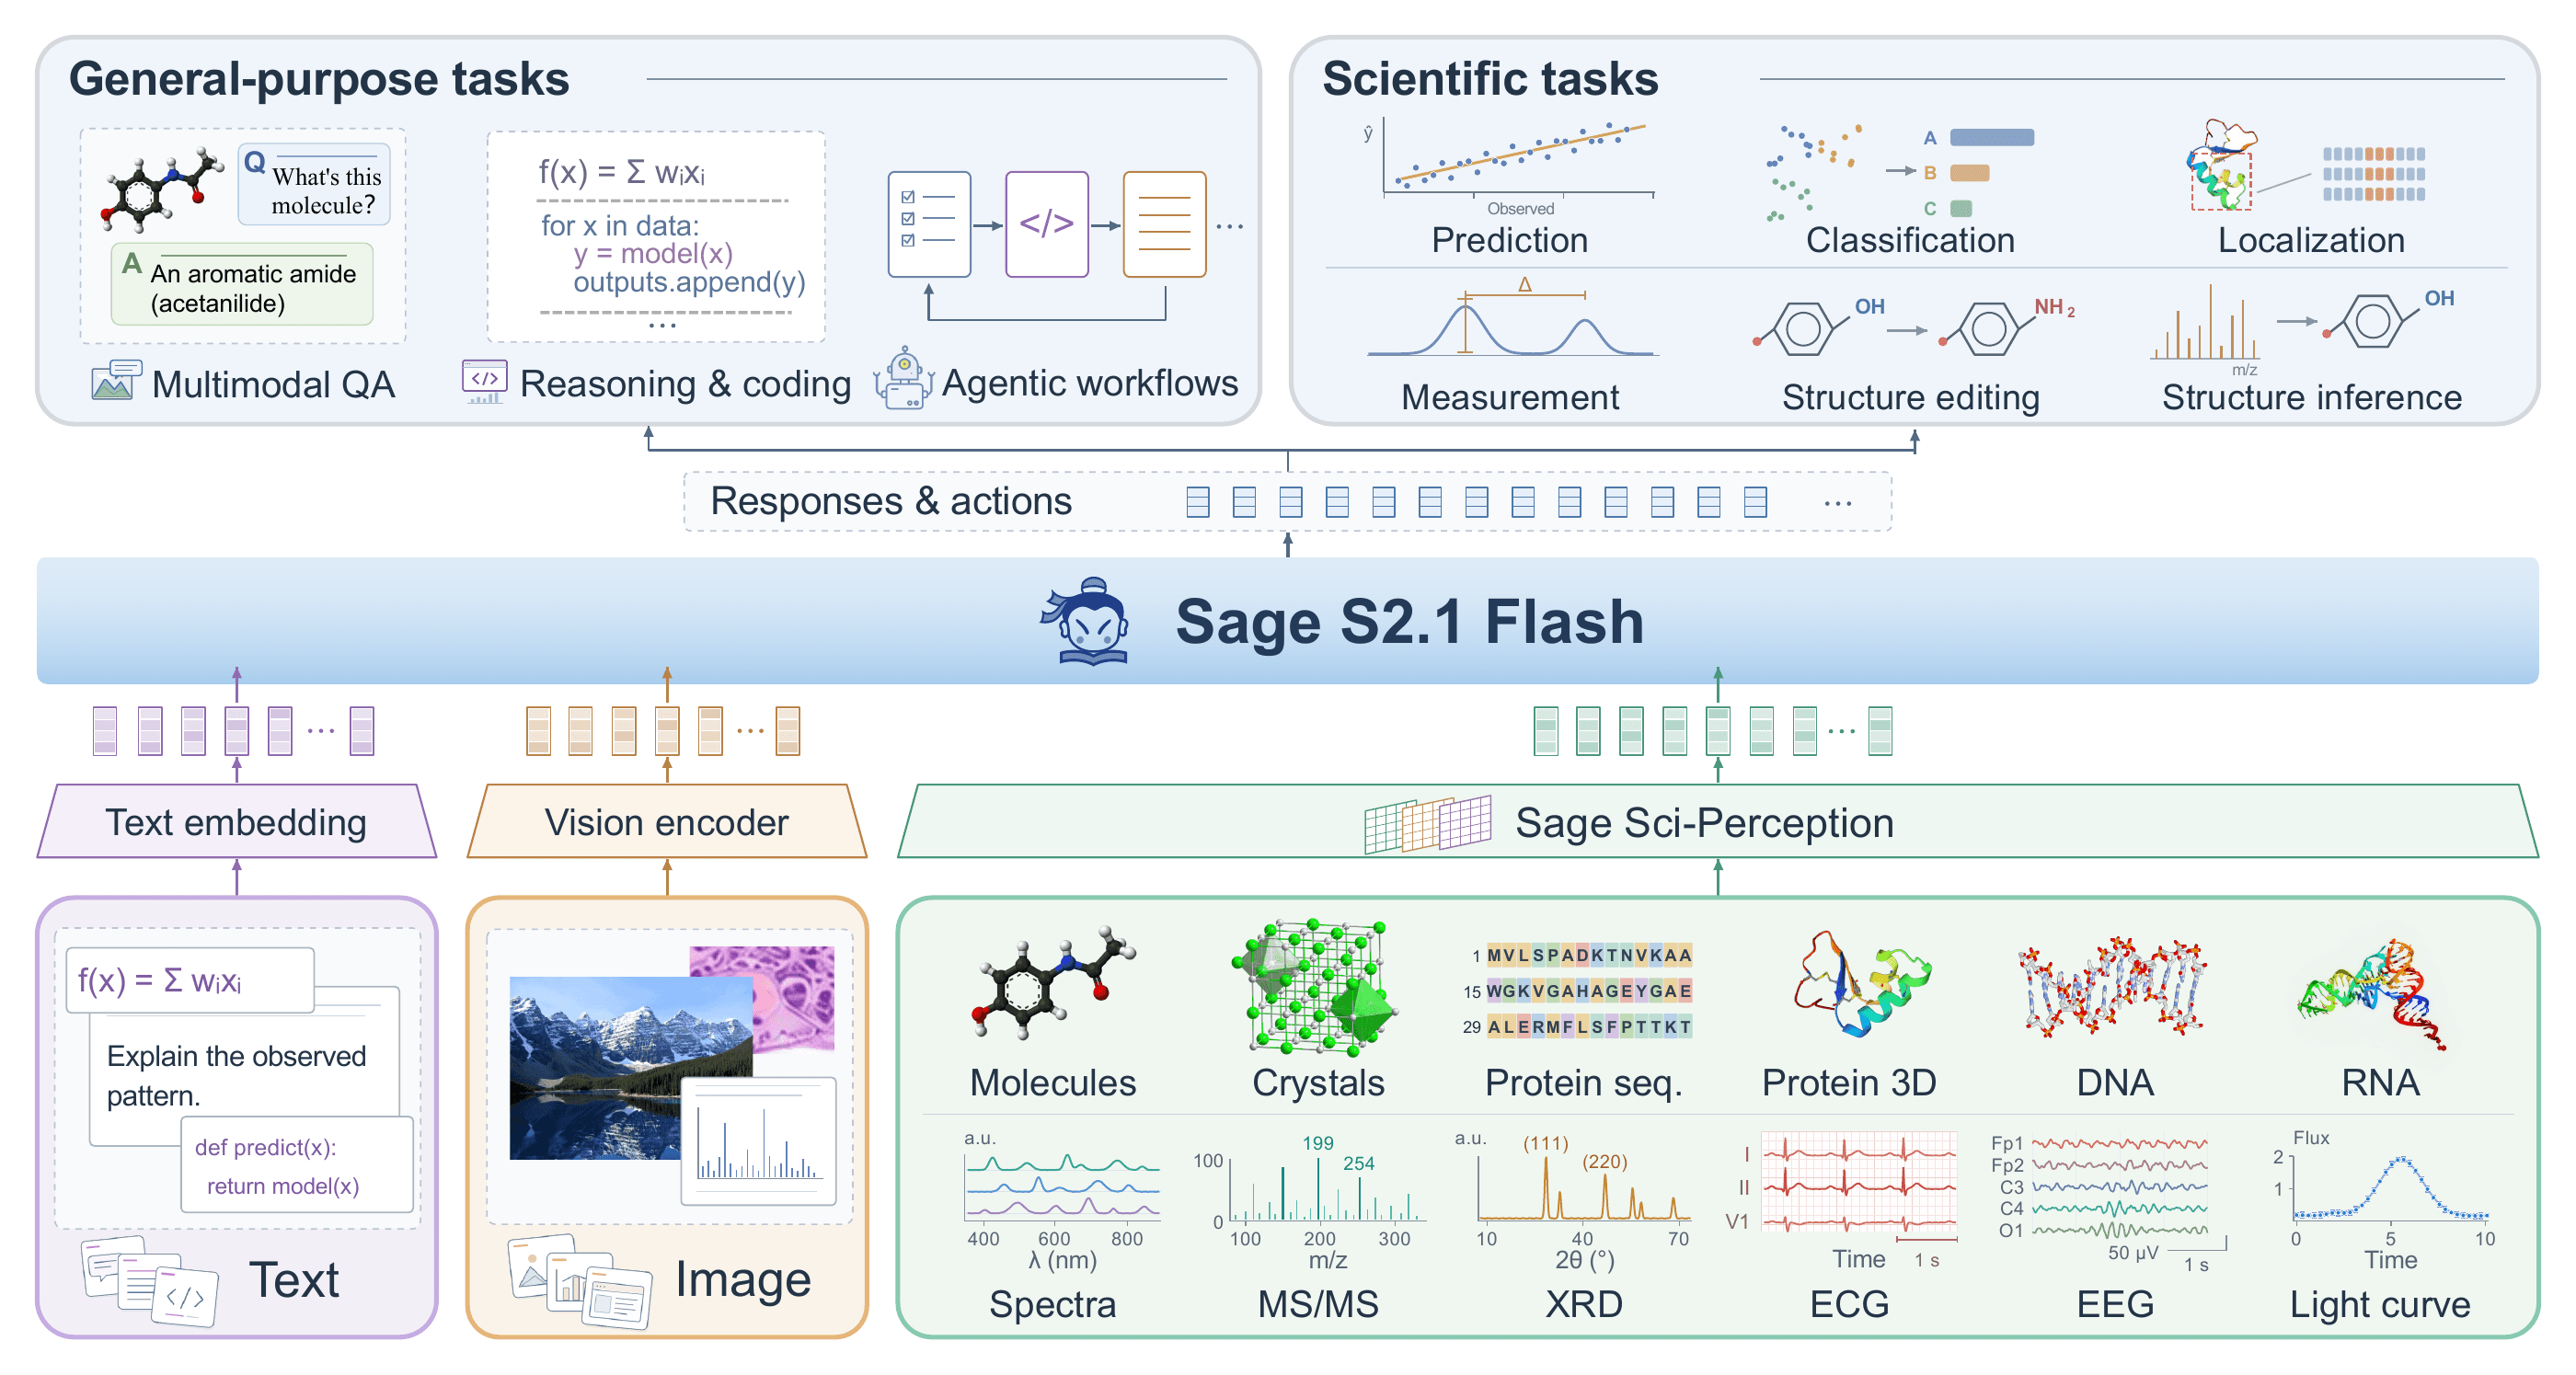
InternLM's Sage S2.1 Flash targets scientific reasoning
The 320B mixture-of-experts model is built to reason over scientific evidence and act inside interactive environments.

Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.
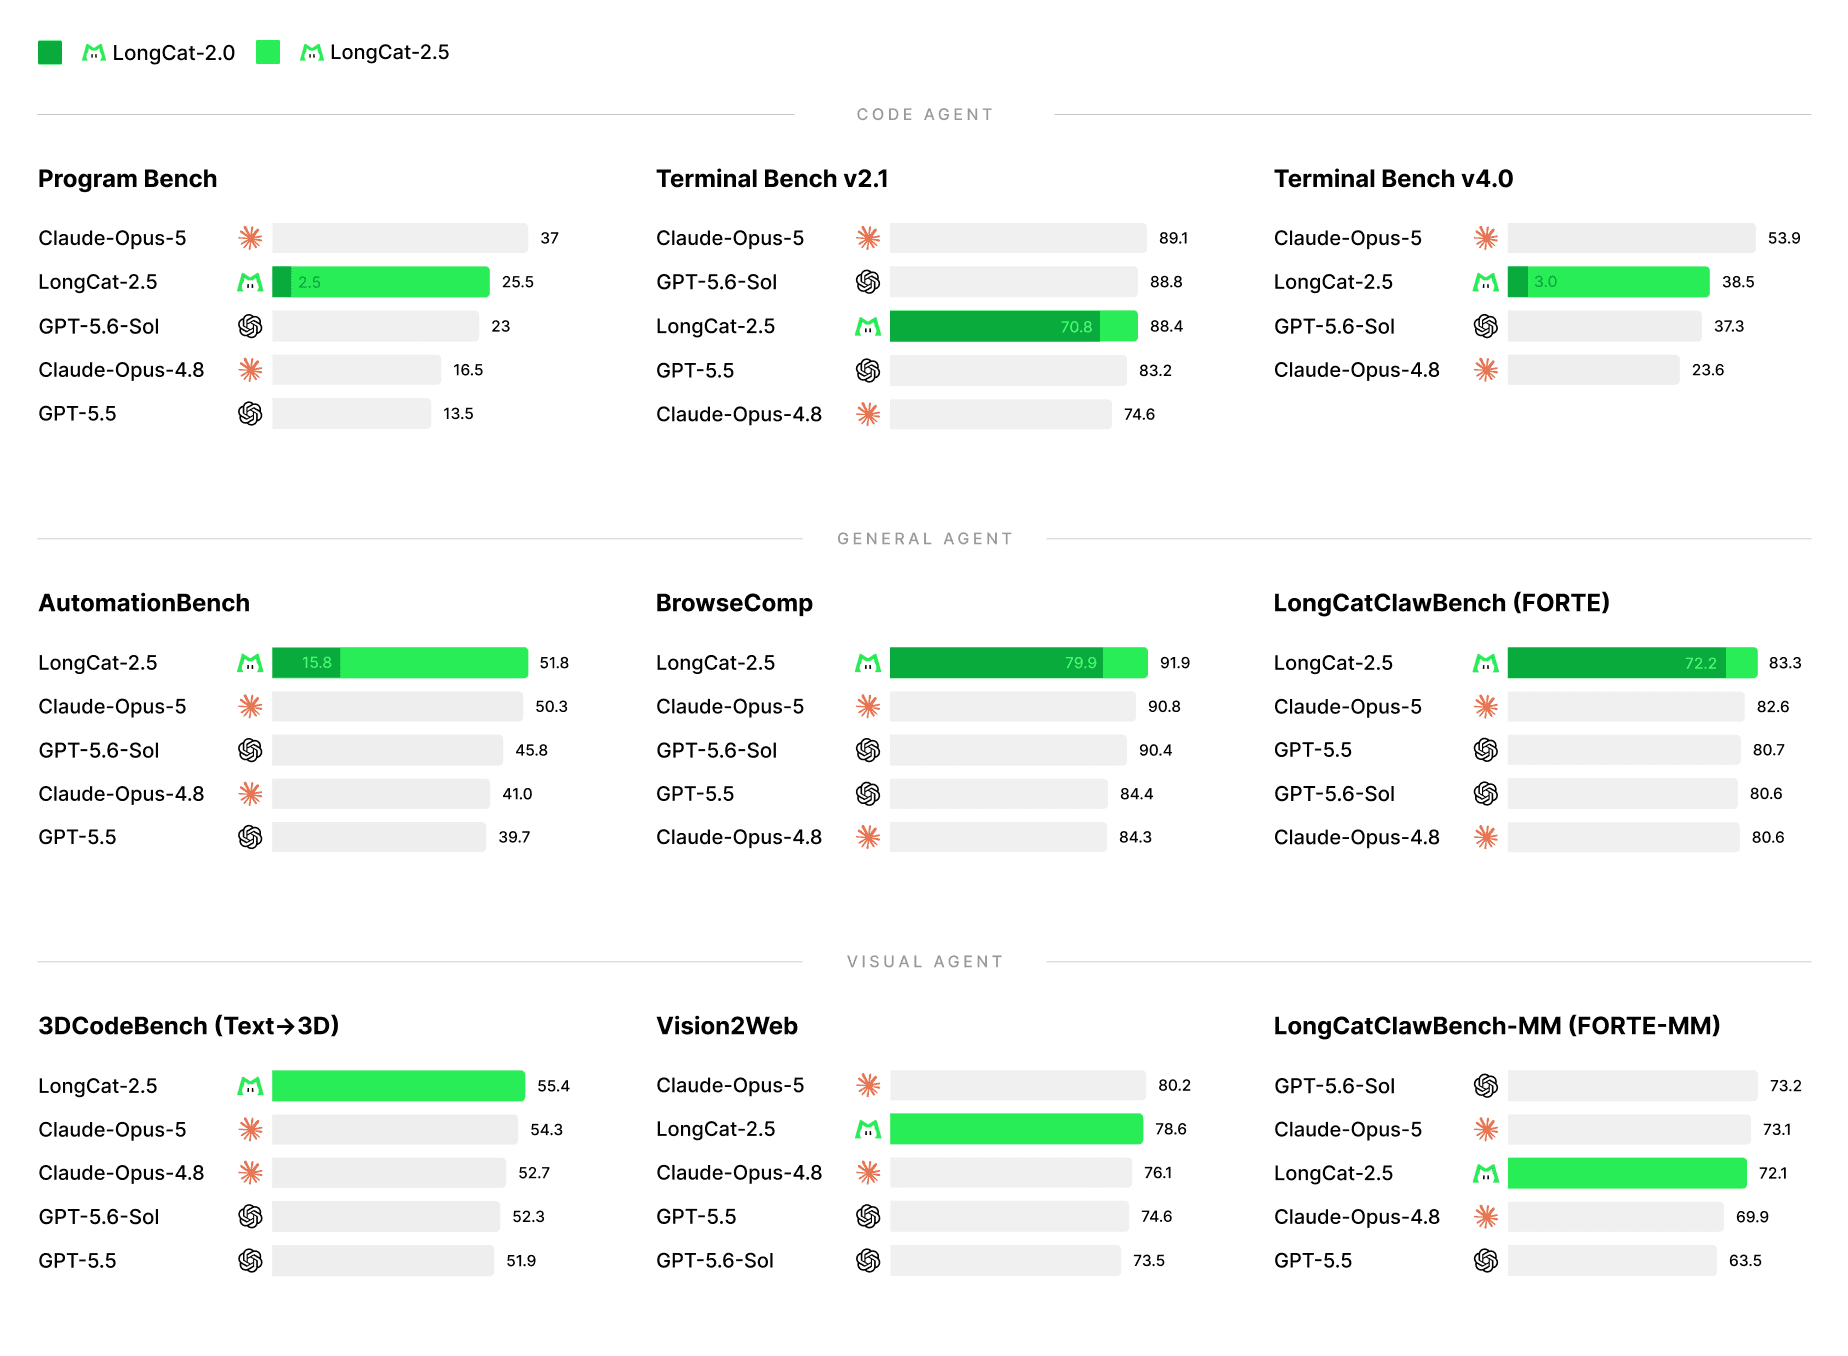
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.
0 comments
No comments yet. Be the first to weigh in.