SenseTime/Any-to-Any
SenseTime's SenseNova-U1.5 Unifies Vision Tasks
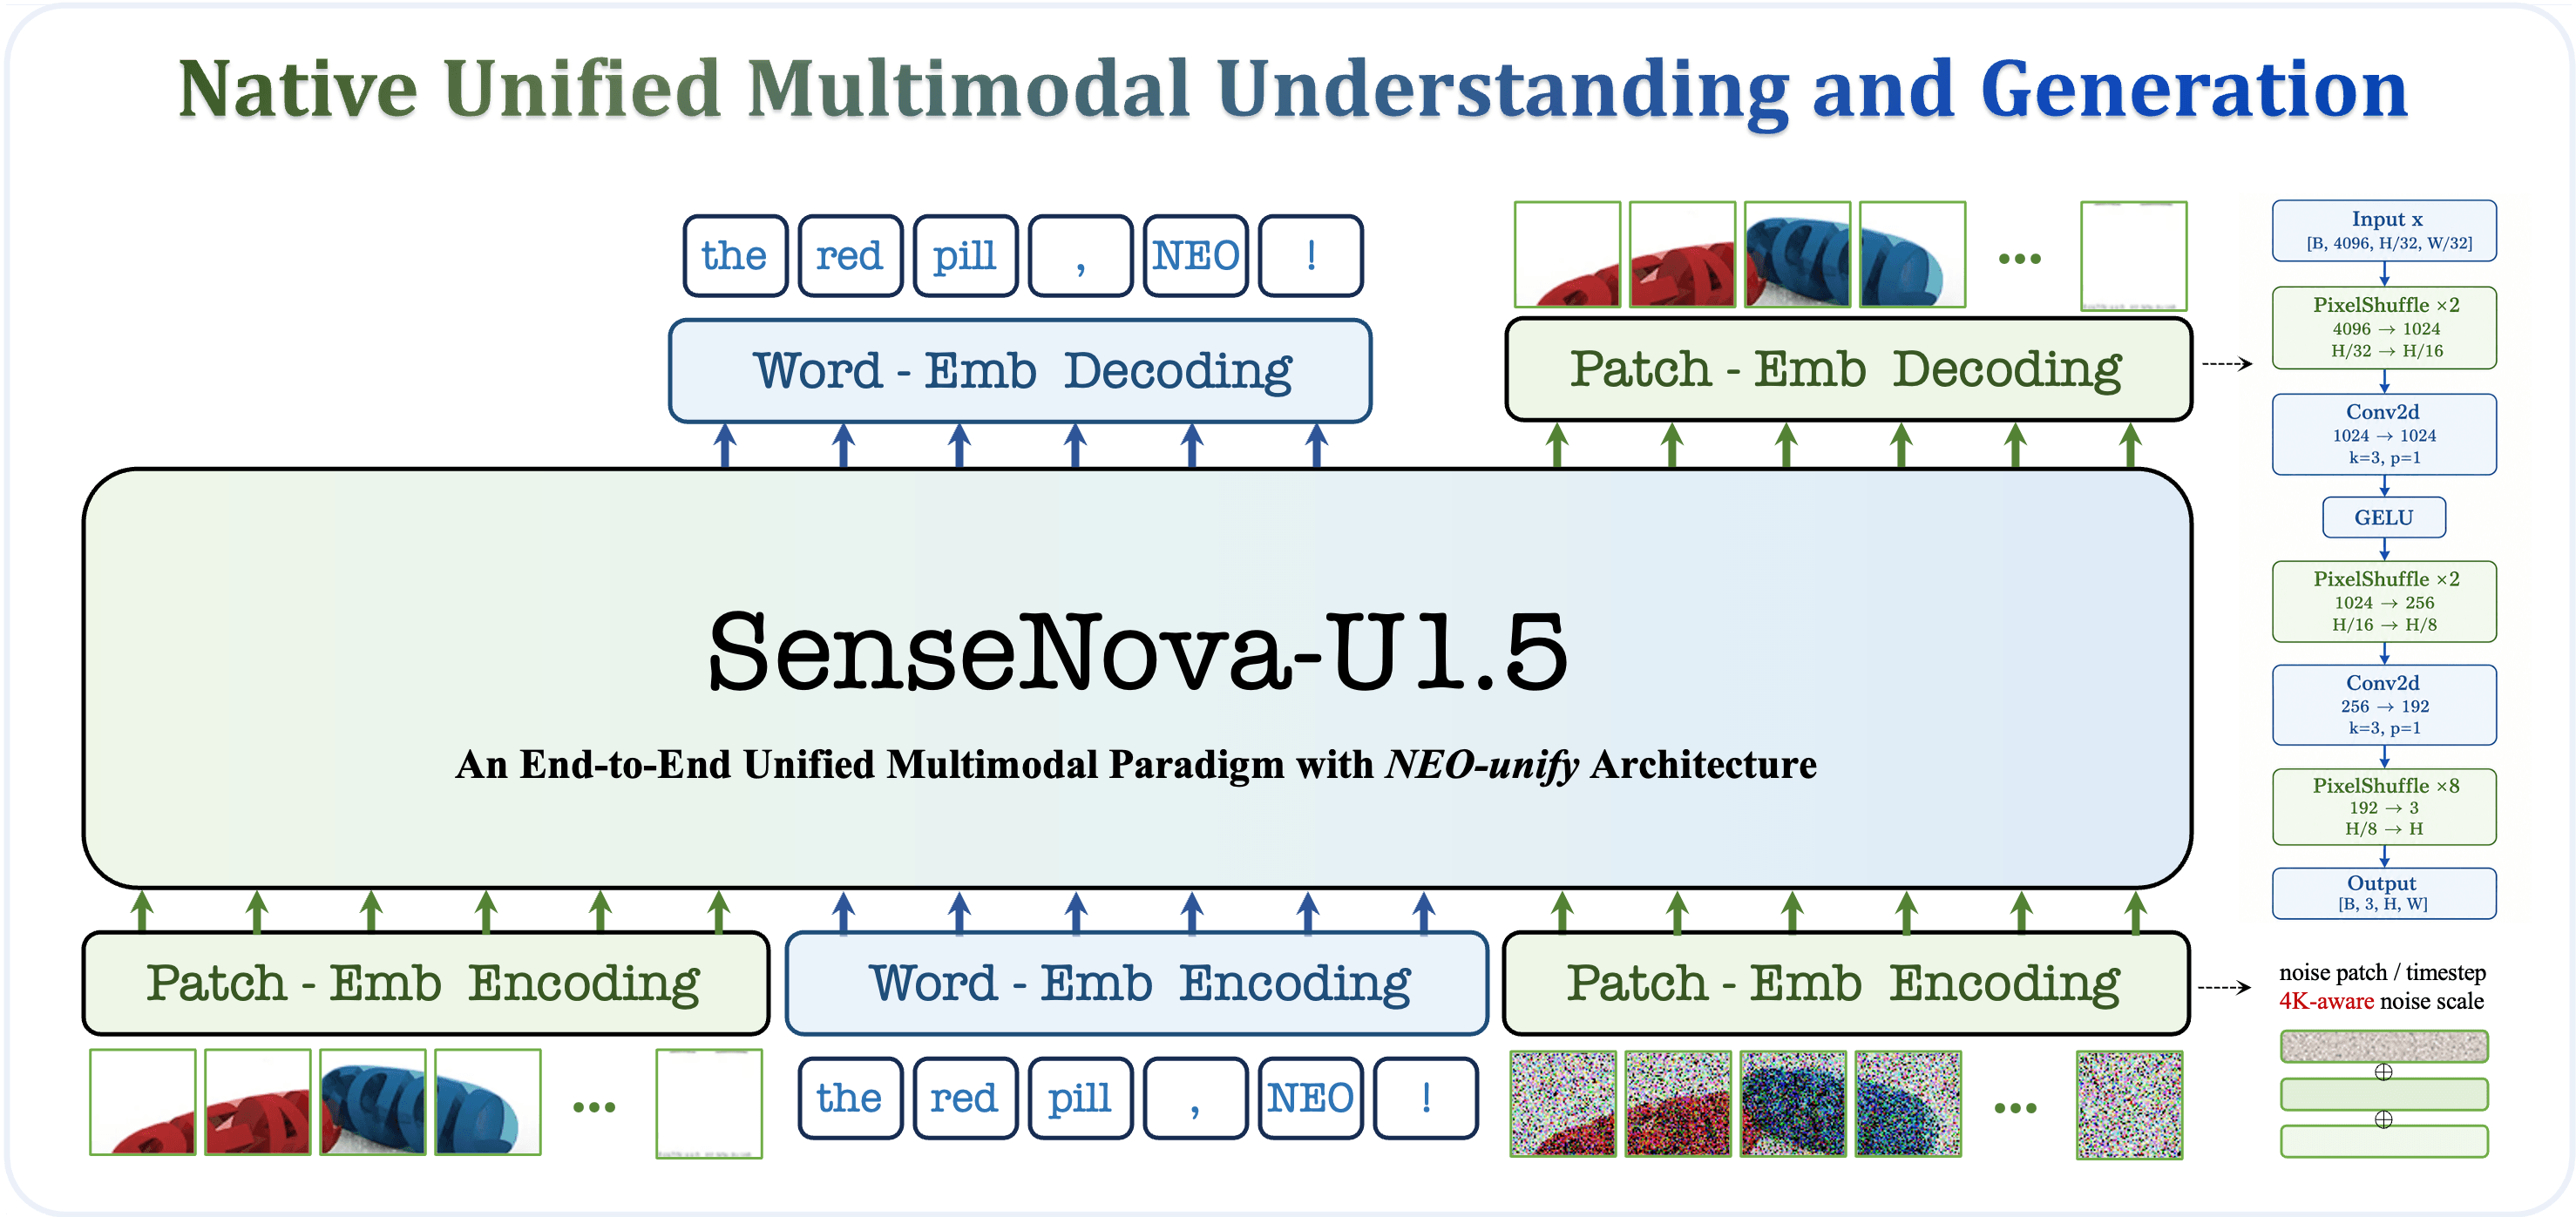
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
Company
Releases
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
An 8B any-to-any model that reads, generates, and edits images at up to 4K resolution, released as an early preview.
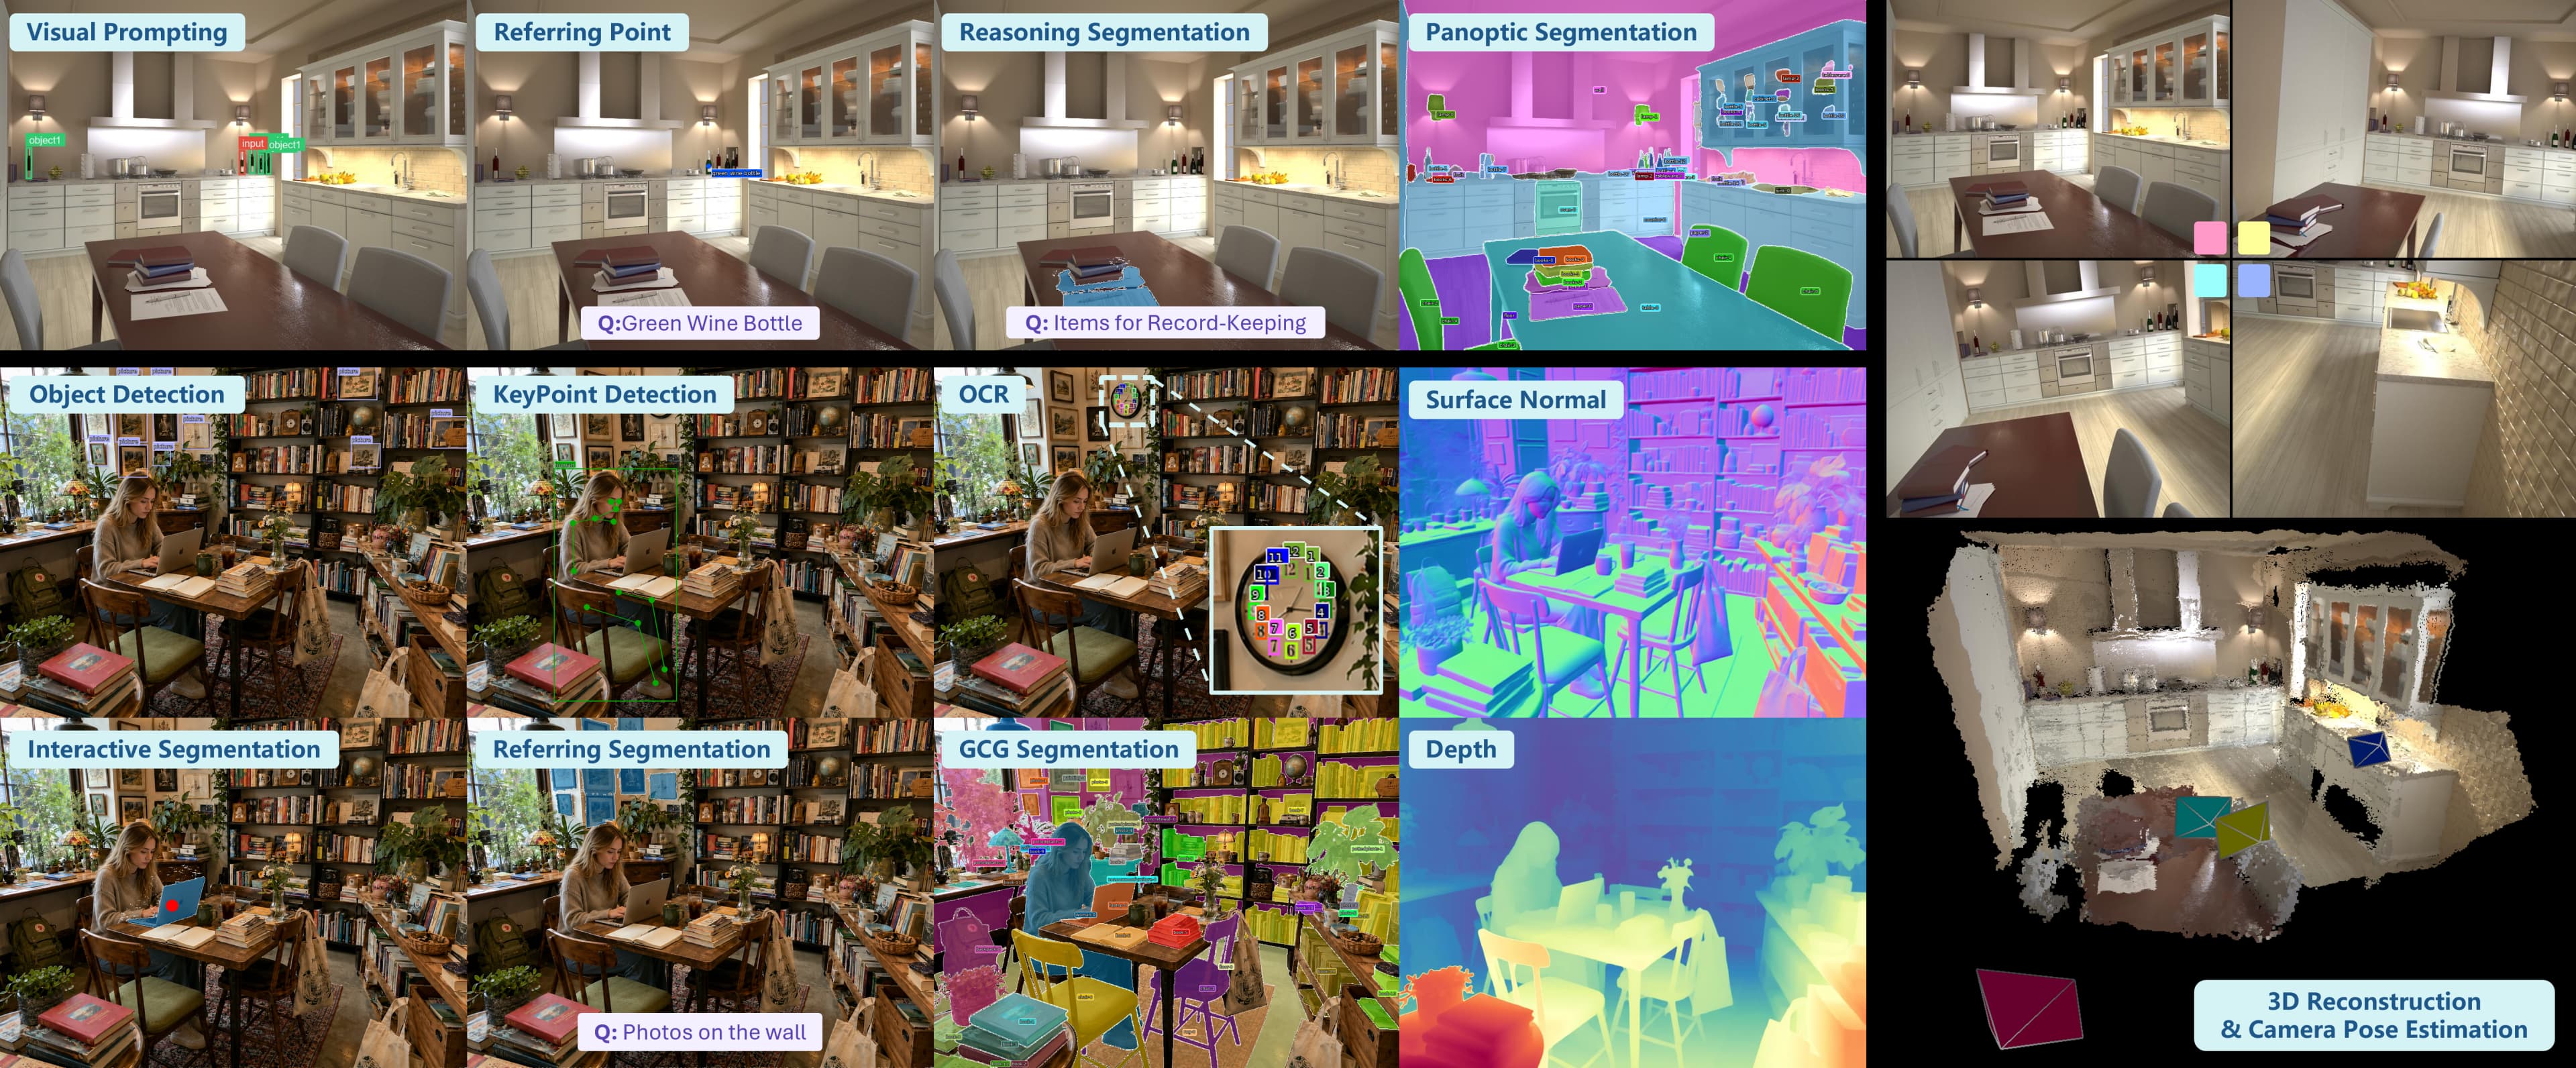
A single 7B model from SenseTime folds vision-language understanding, image generation, editing, and perception into one system.
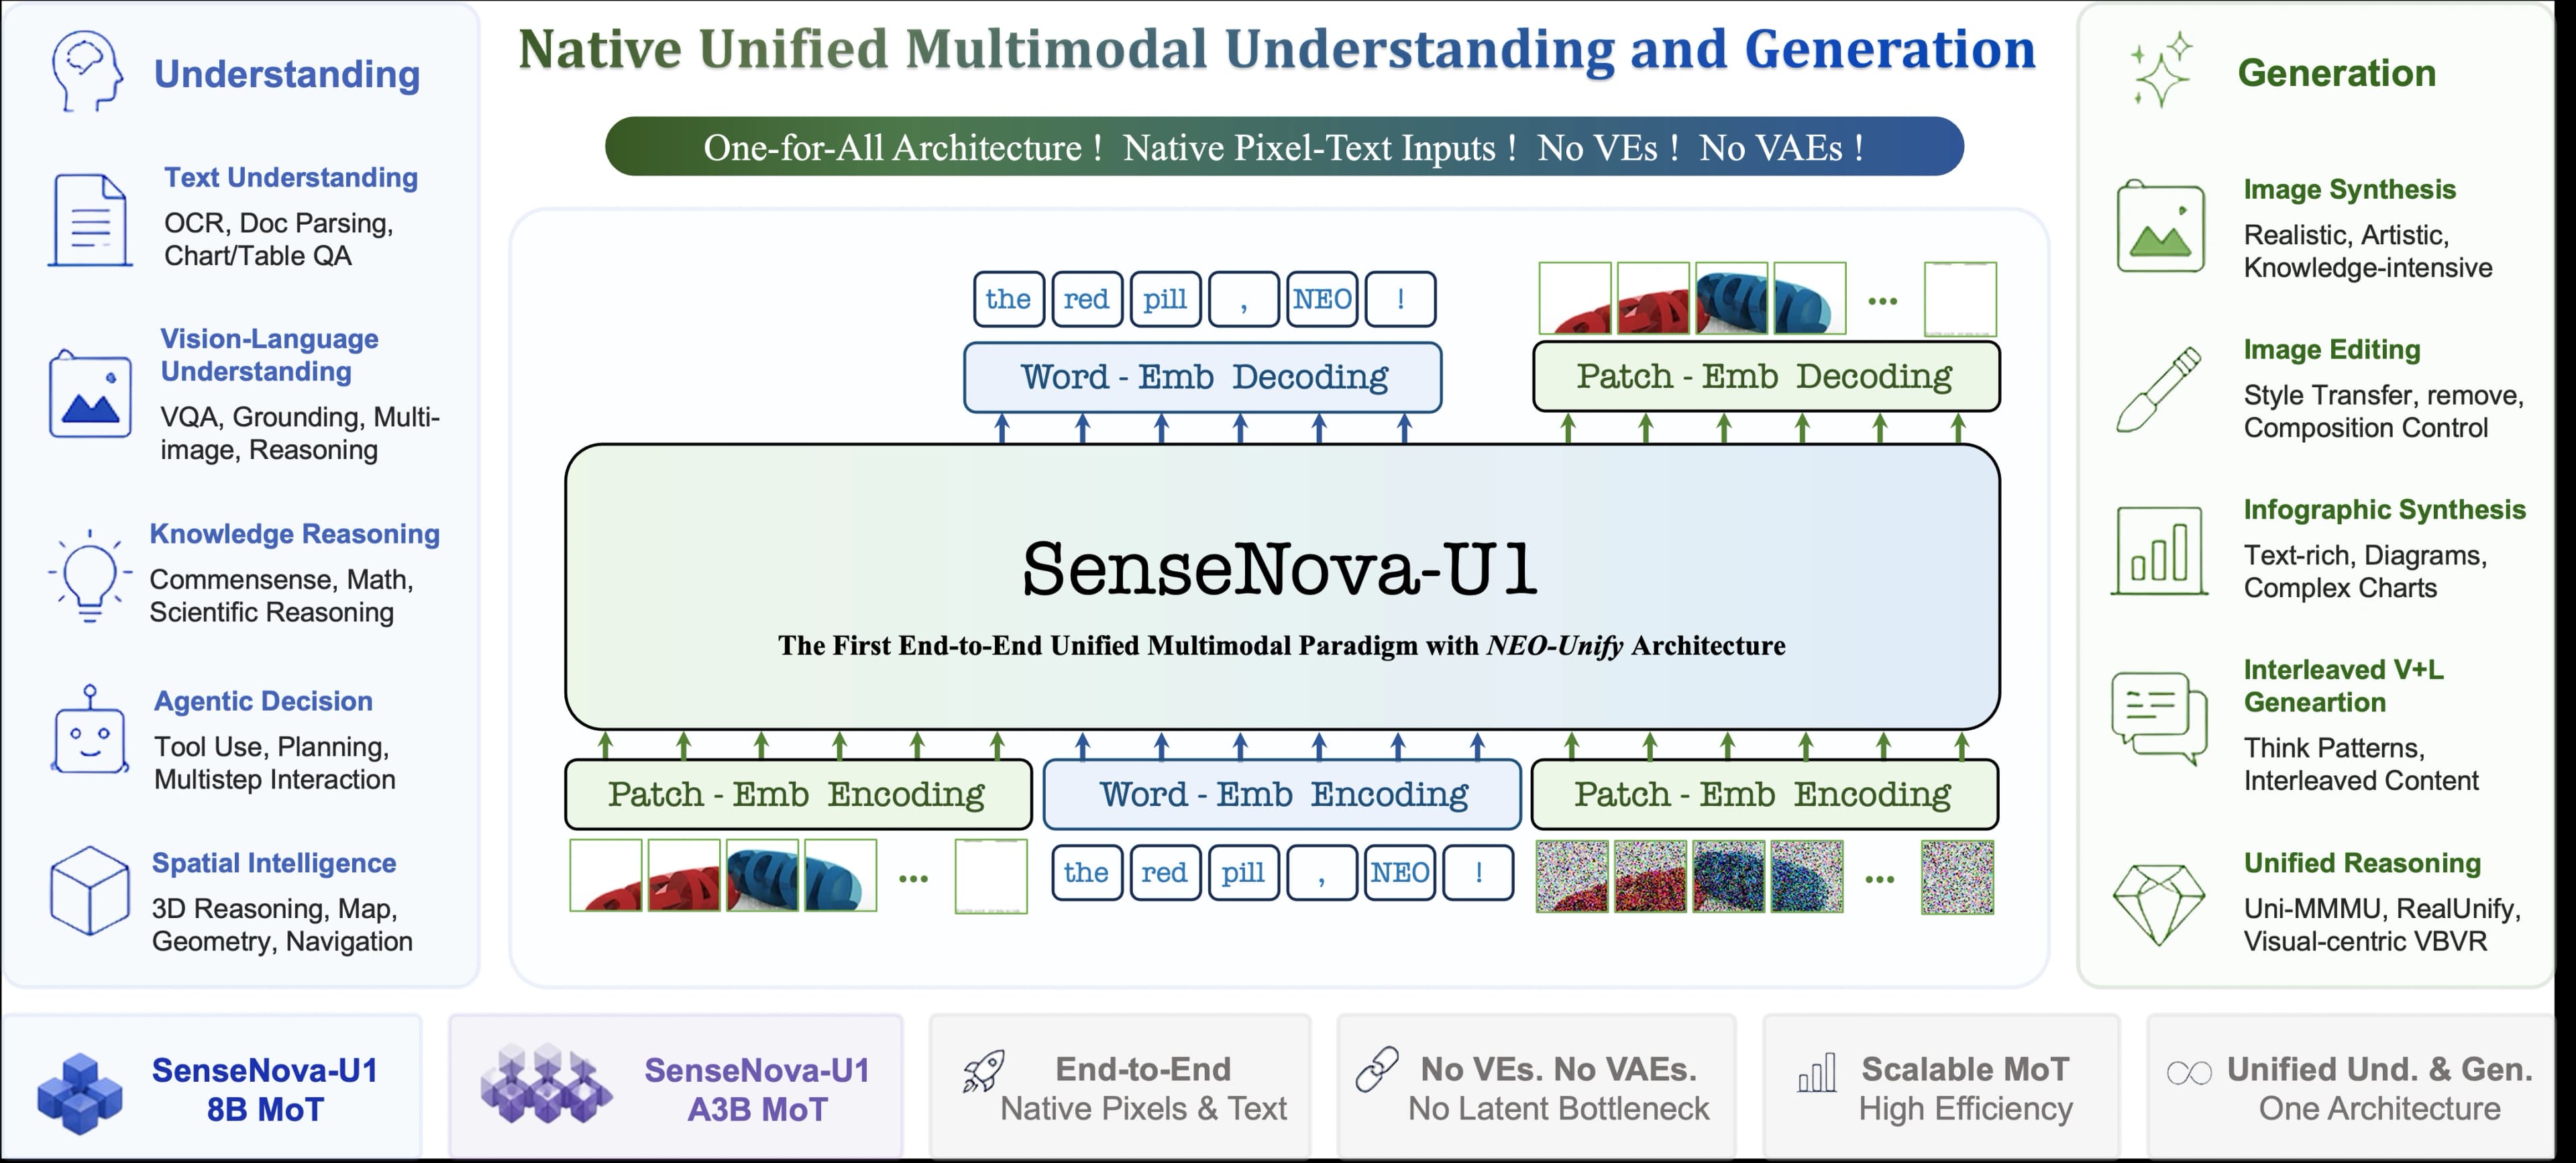
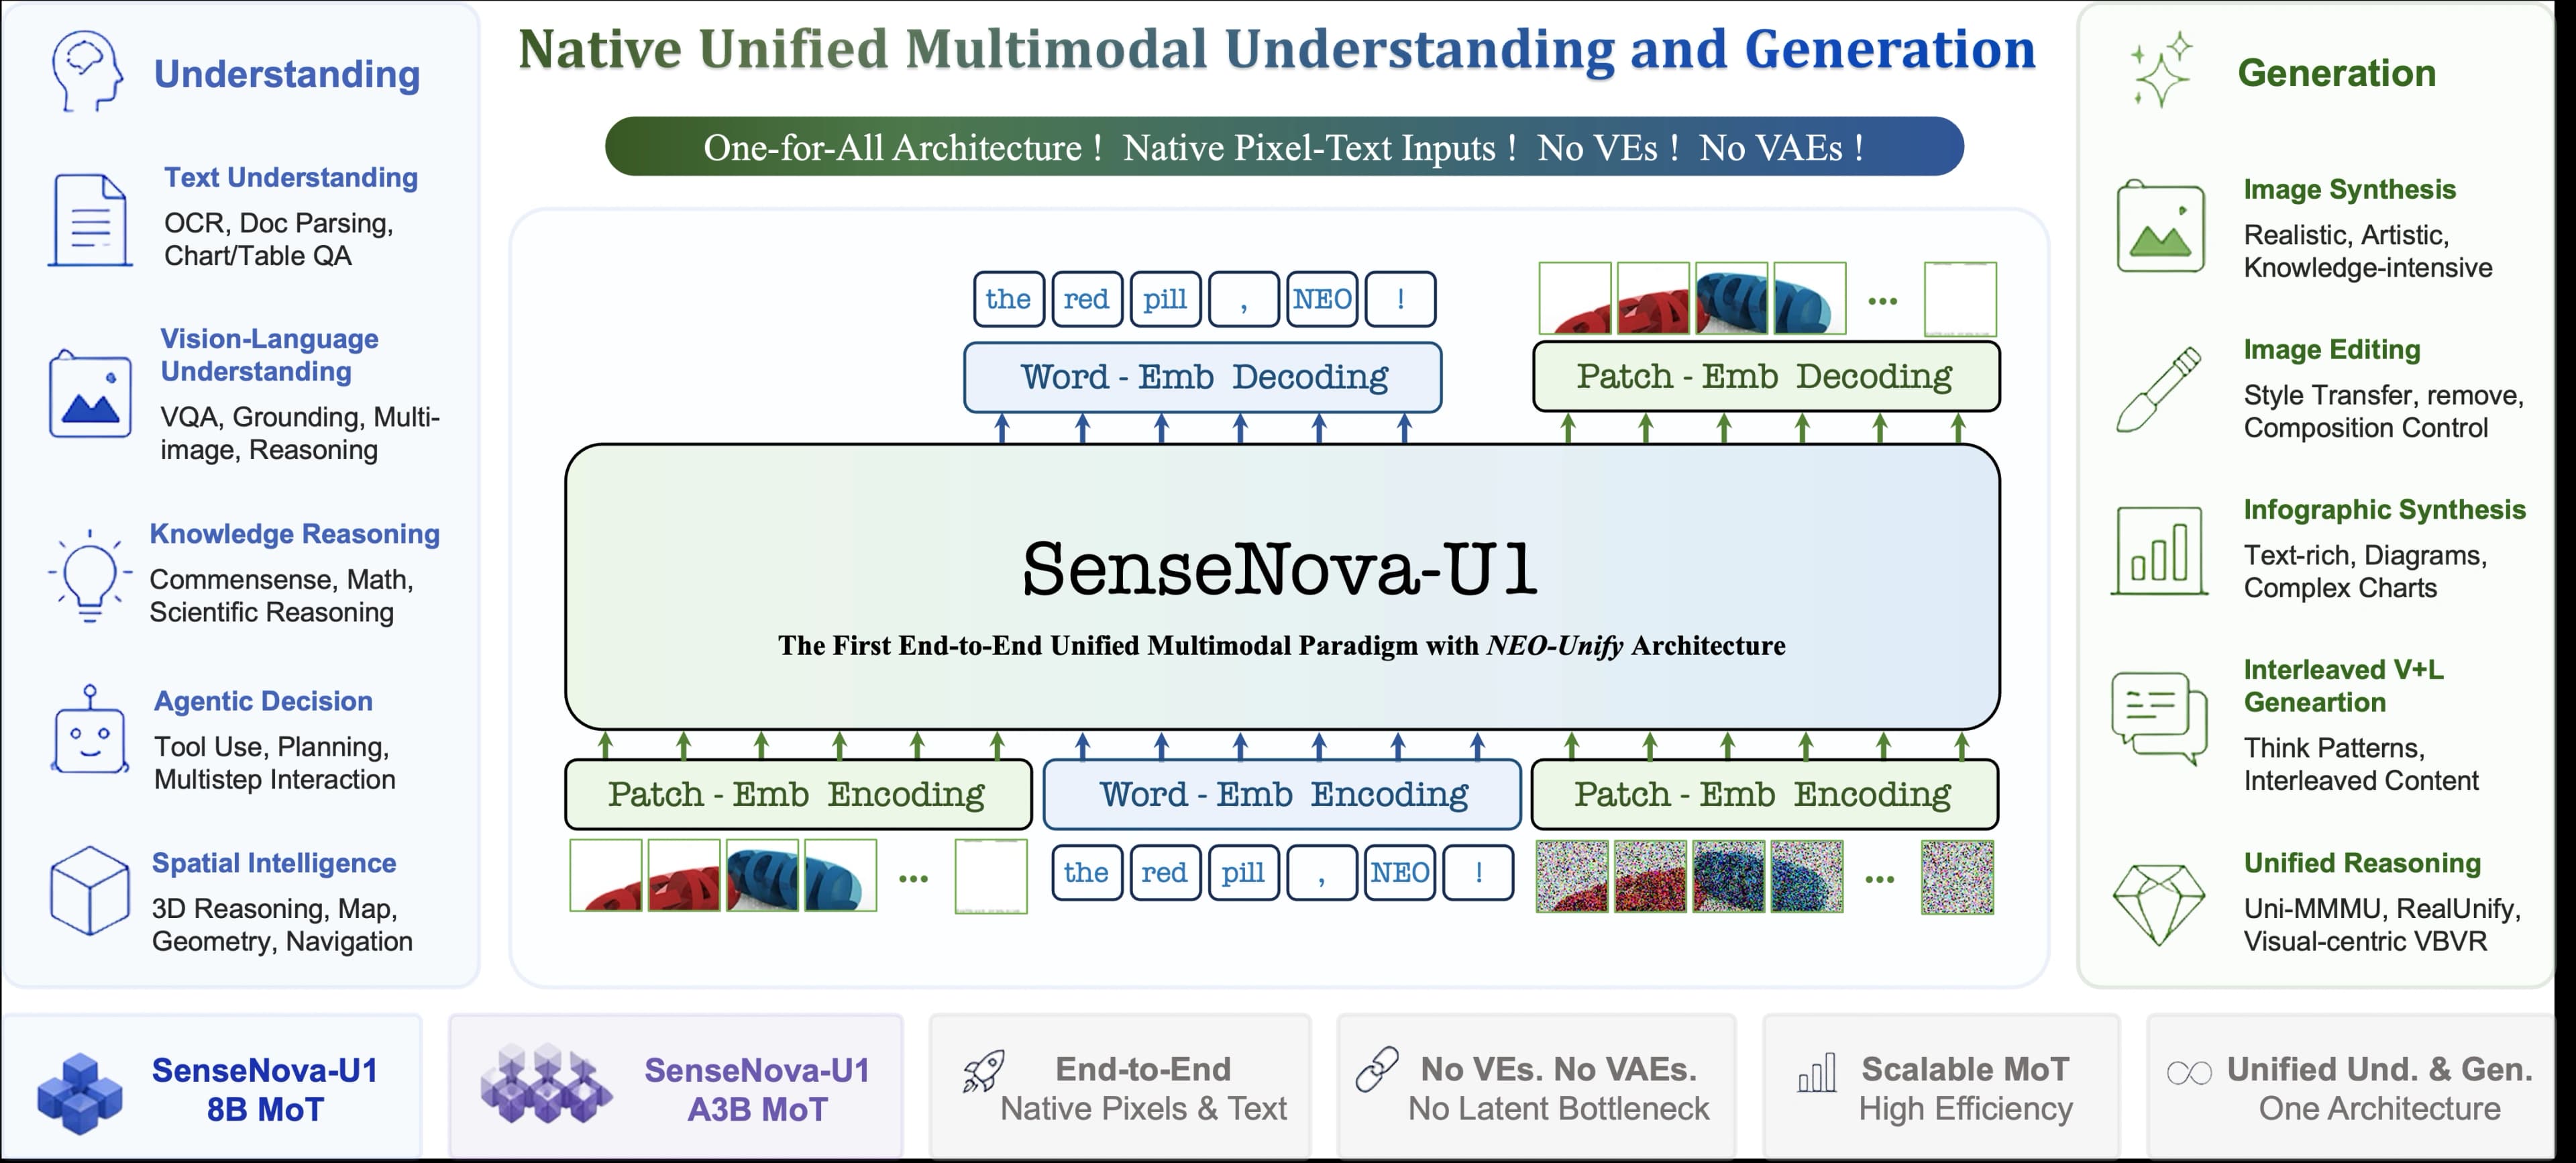
The new 8B-parameter SenseNova U1 model from SenseTime is designed for complex multimodal tasks, including the in-conversation generation and editing of infographics.
The new SenseNova-U1 model unifies image understanding, generation, and editing within a single 8-billion-parameter framework.