SenseTime Releases 8B Any-to-Any Multimodal Model
The new SenseNova-U1 model unifies image understanding, generation, and editing within a single 8-billion-parameter framework.
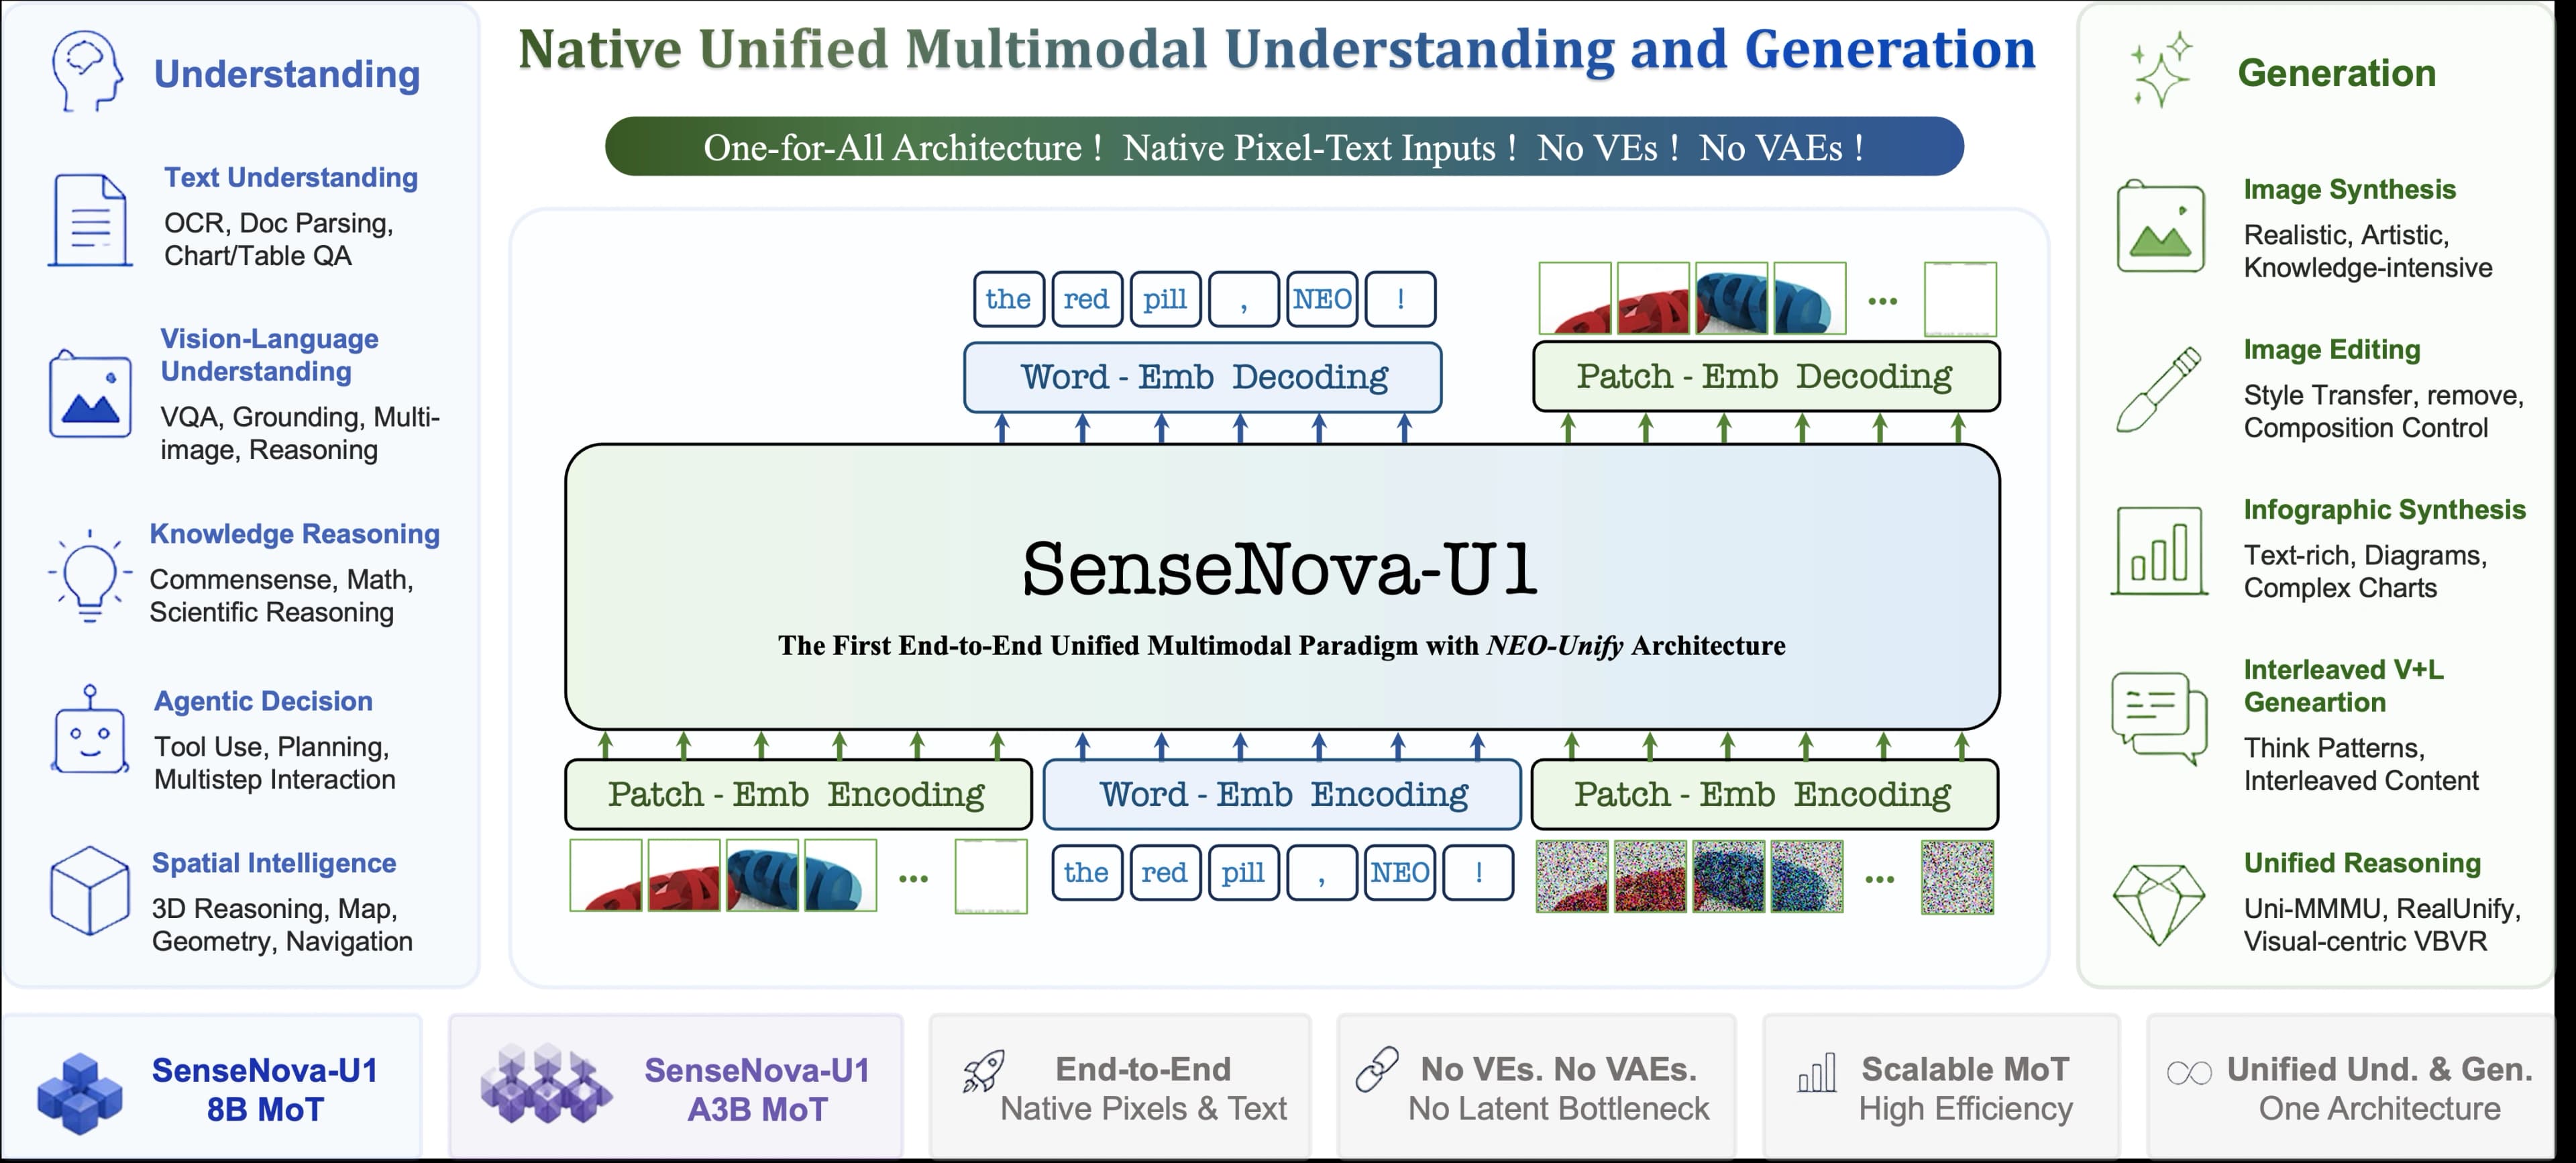
Chinese AI company SenseTime has released SenseNova-U1-8B-MoT, an 8-billion-parameter model that pushes towards a more unified approach to multimodal AI. Billed as an "any-to-any" system, it's designed to handle a diverse range of tasks involving both text and images within a single framework. The model weights and details are available on Hugging Face.
Unlike specialized models that focus on a single function like text-to-image generation, SenseNova-U1 aims to be a generalist. Its architecture allows it to understand images, generate new ones from text prompts, perform edits on existing images, and produce outputs that interleave text and visuals together.
A Unified Architecture
The model is built on an established foundation, combining a large language model with a vision transformer (ViT). According to the project's documentation, a trainable projector module acts as the bridge between these two components, enabling communication between the text and vision domains. Its core capabilities include:
- Image understanding and question answering
- Text-to-image generation
- Image editing based on text instructions
- Interleaved text and image output
SenseNova-U1 represents a growing trend towards creating more versatile, all-in-one AI systems. By integrating multiple modalities and tasks into one model, developers can simplify complex creative and analytical workflows. However, potential users should note its custom "SenseNova License," which currently restricts use to academic research and non-commercial applications.
Sources
- Visit
sensenova/SenseNova-U1-8B-MoT
Hugging Face
More from SenseTime
All SenseTime releases →SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
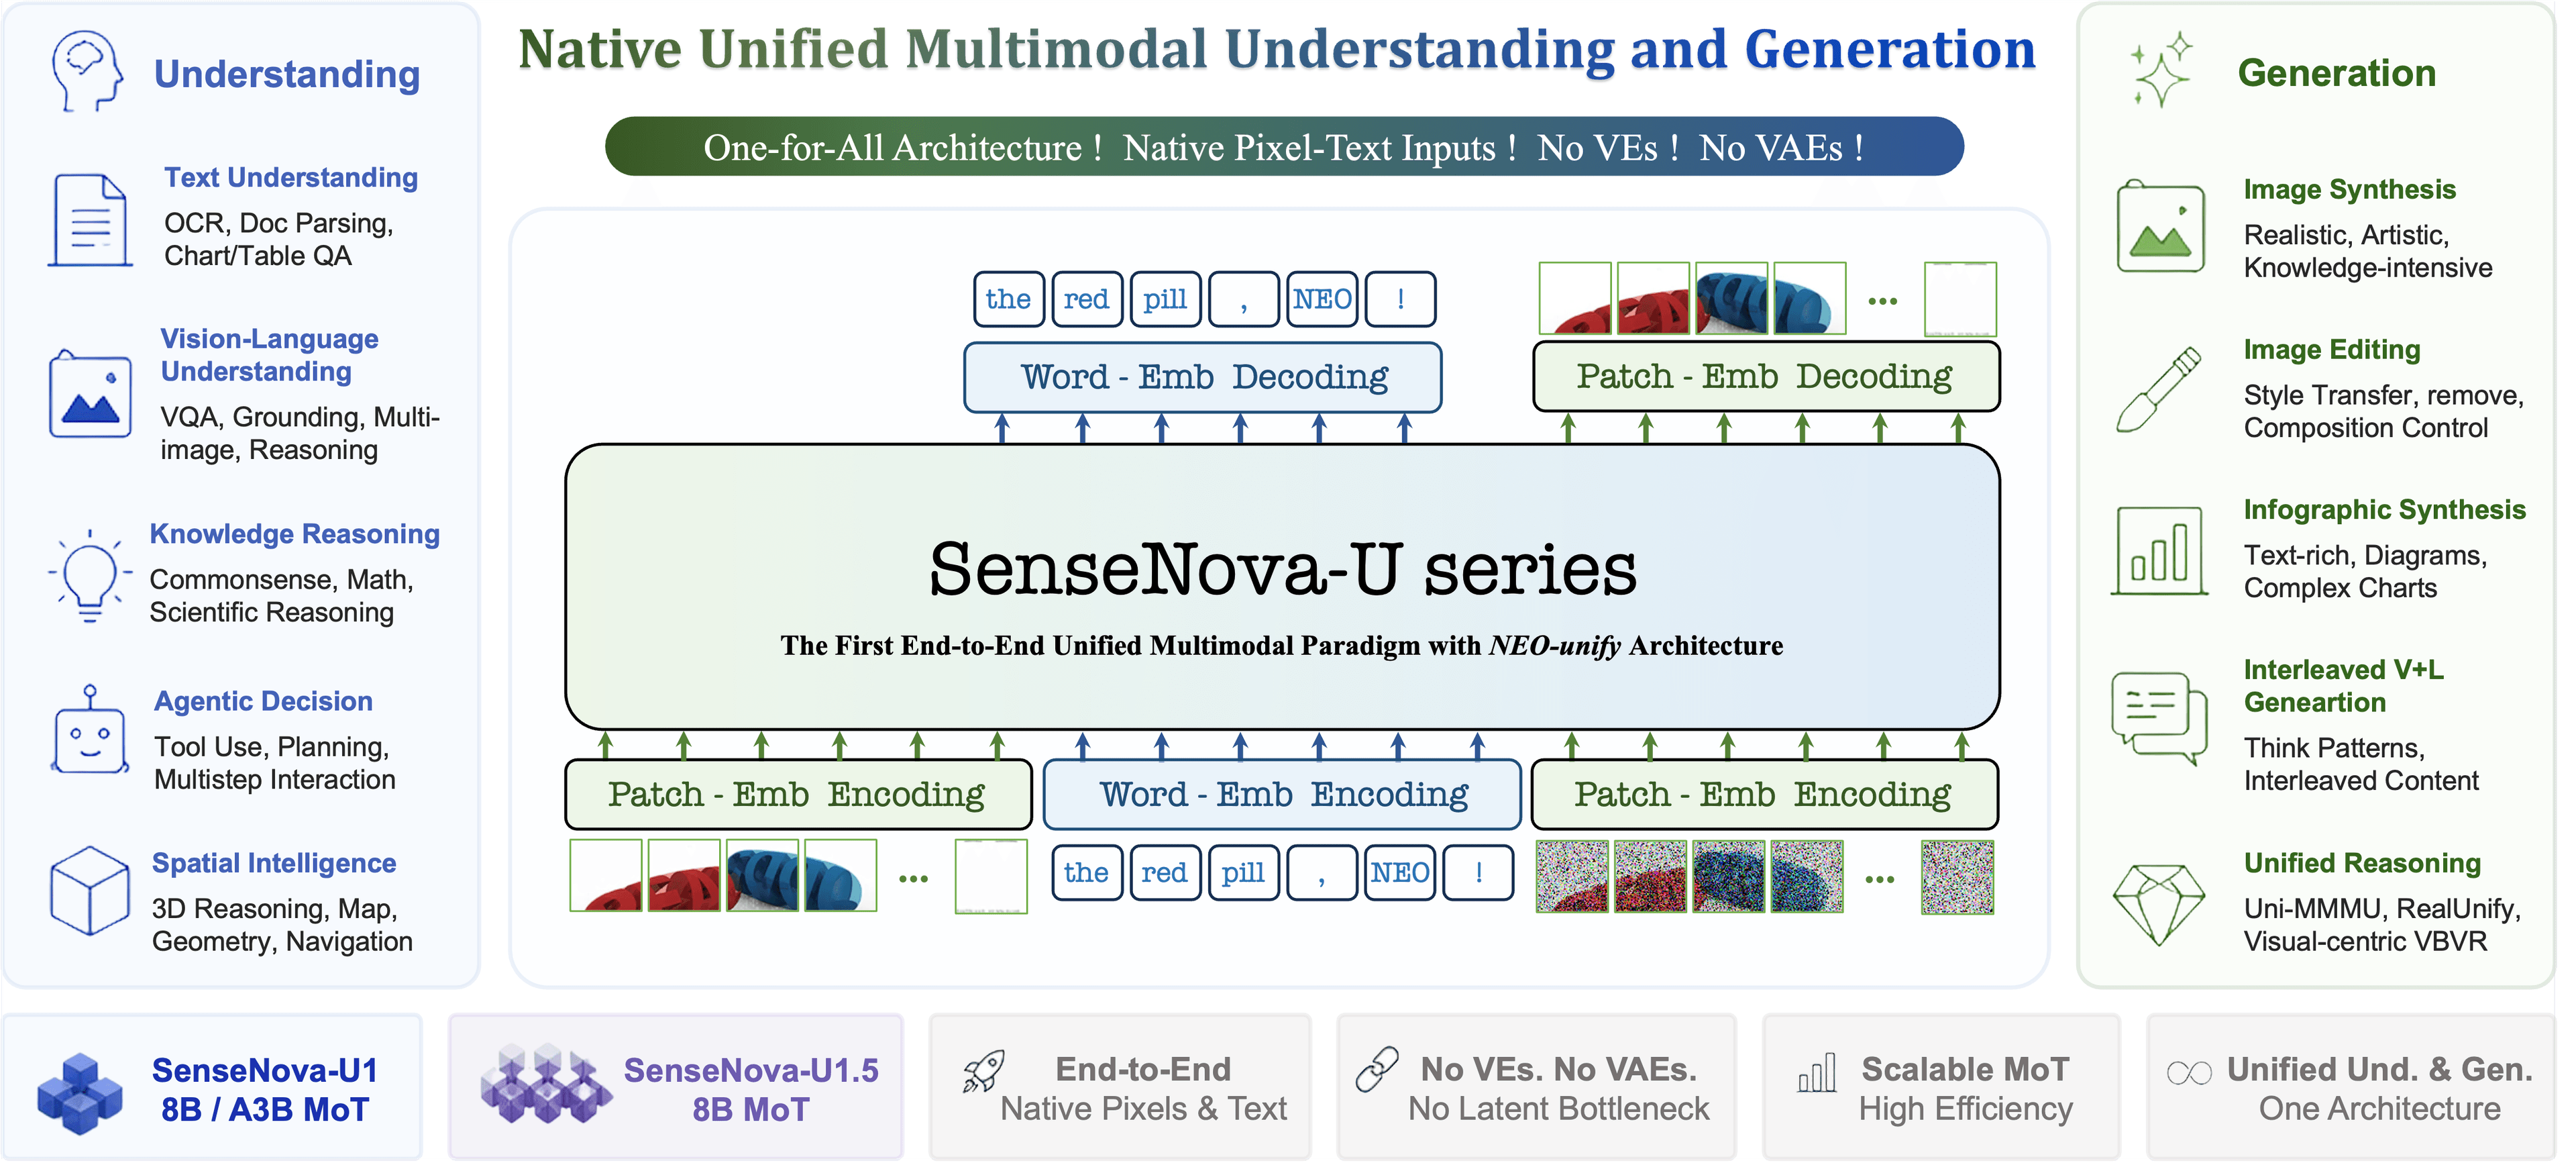
SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
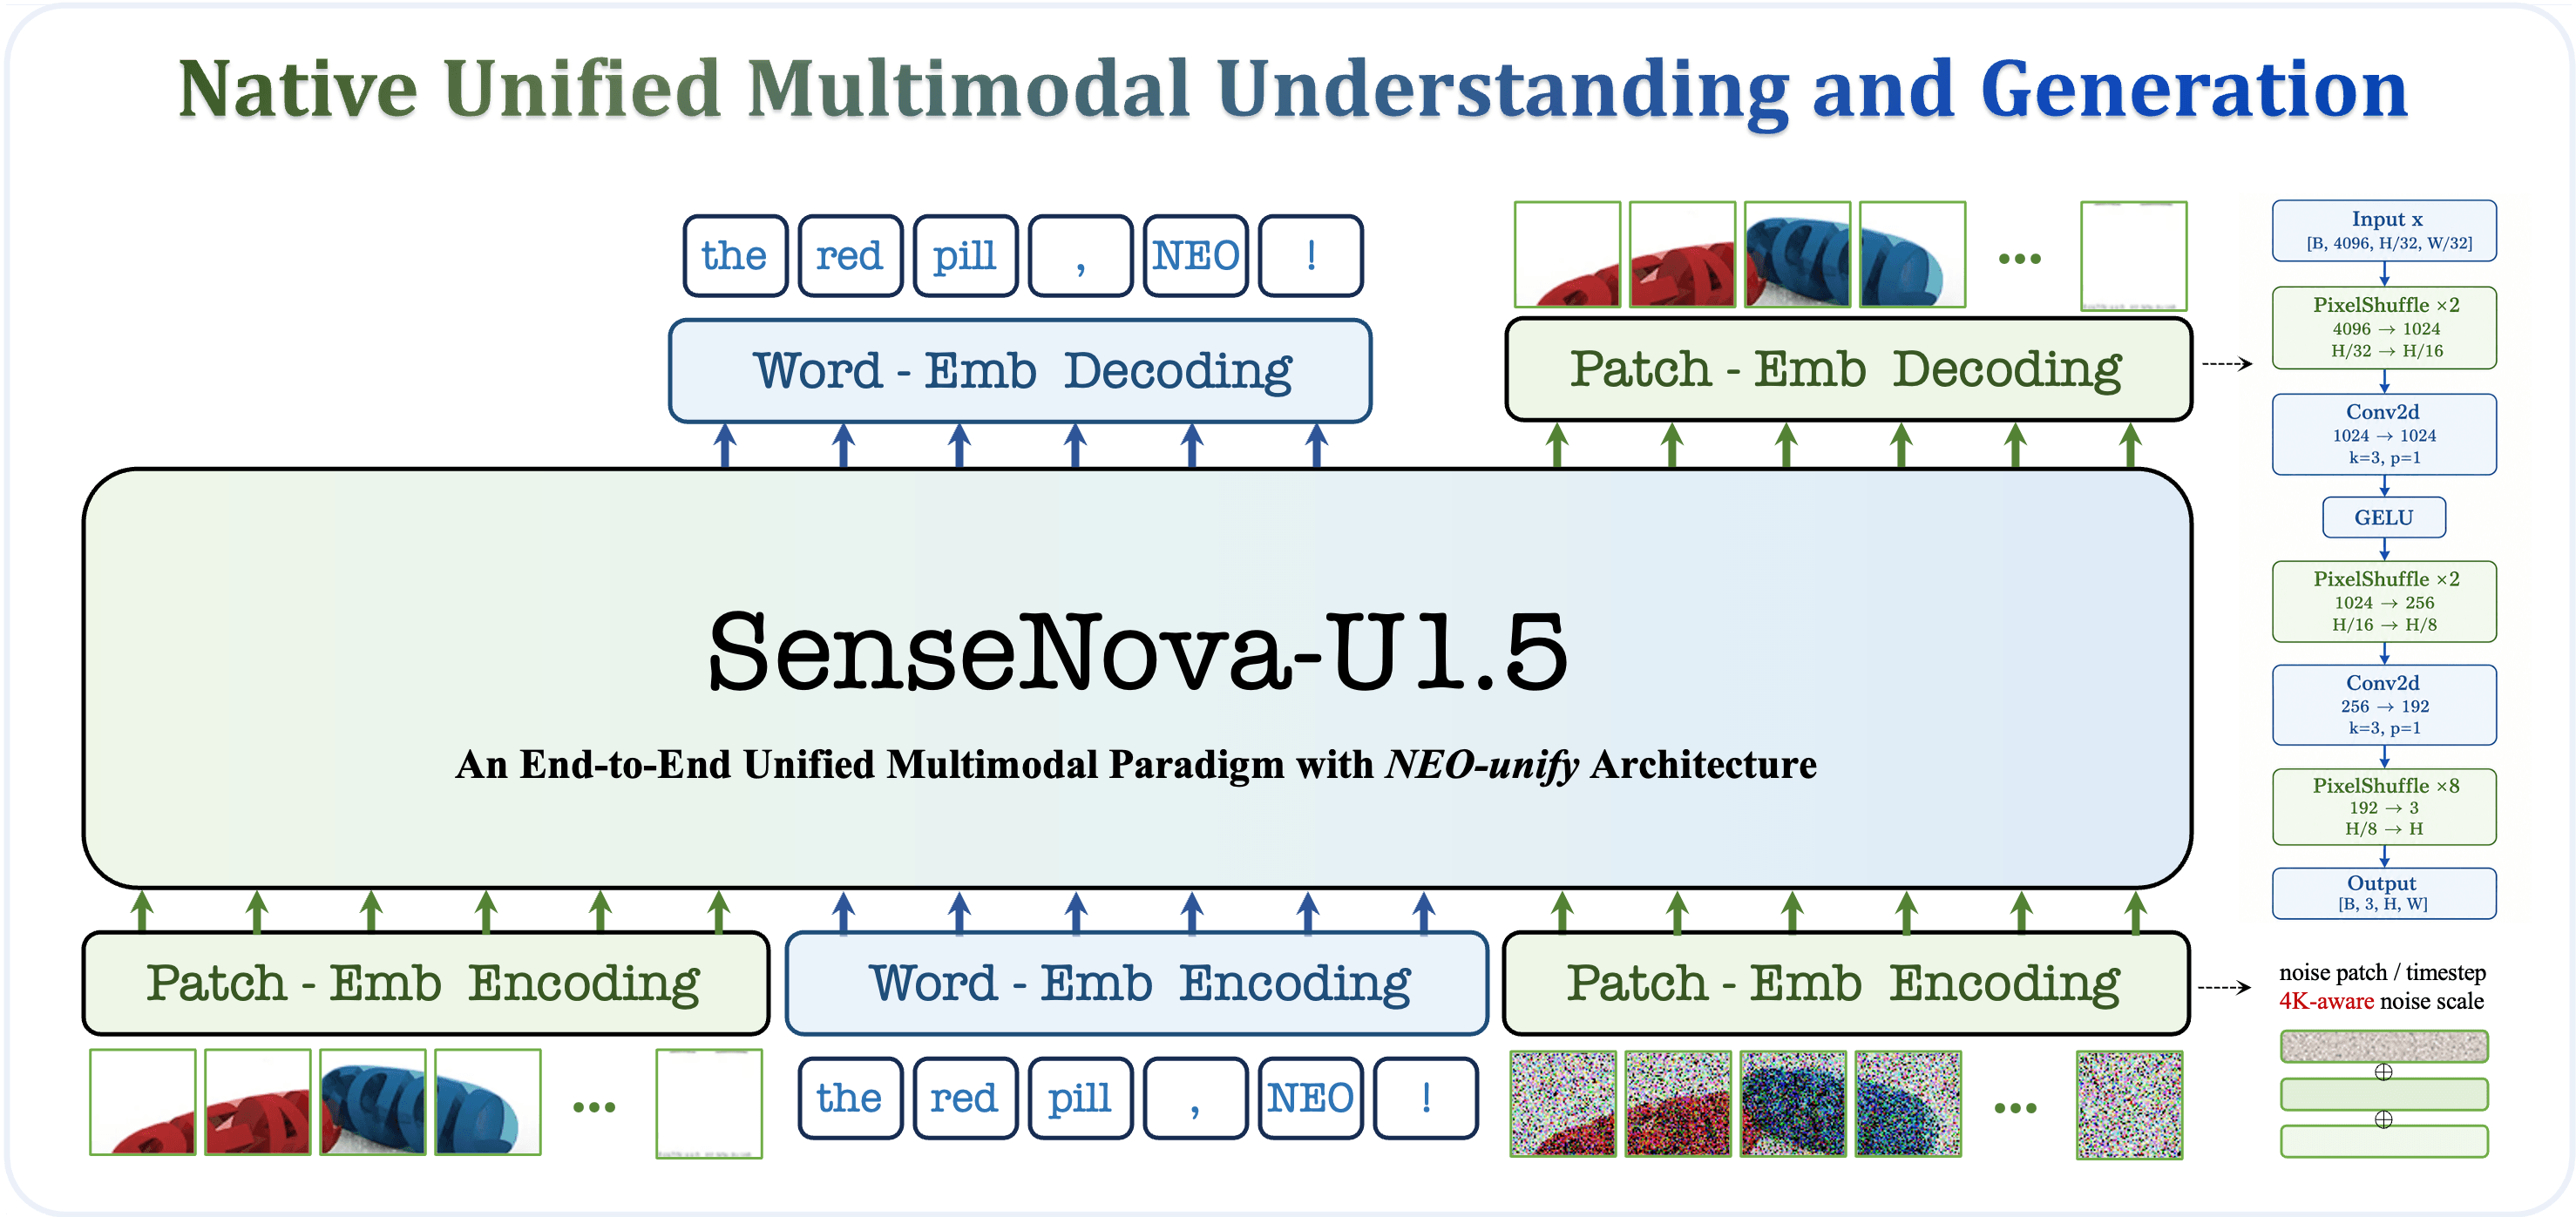
SenseTime Debuts SenseNova U1.5 8B Multimodal Preview
An 8B any-to-any model that reads, generates, and edits images at up to 4K resolution, released as an early preview.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.