SenseTime Releases 8B 'Any-to-Any' Infographic Model
The new 8B-parameter SenseNova U1 model from SenseTime is designed for complex multimodal tasks, including the in-conversation generation and editing of infographics.
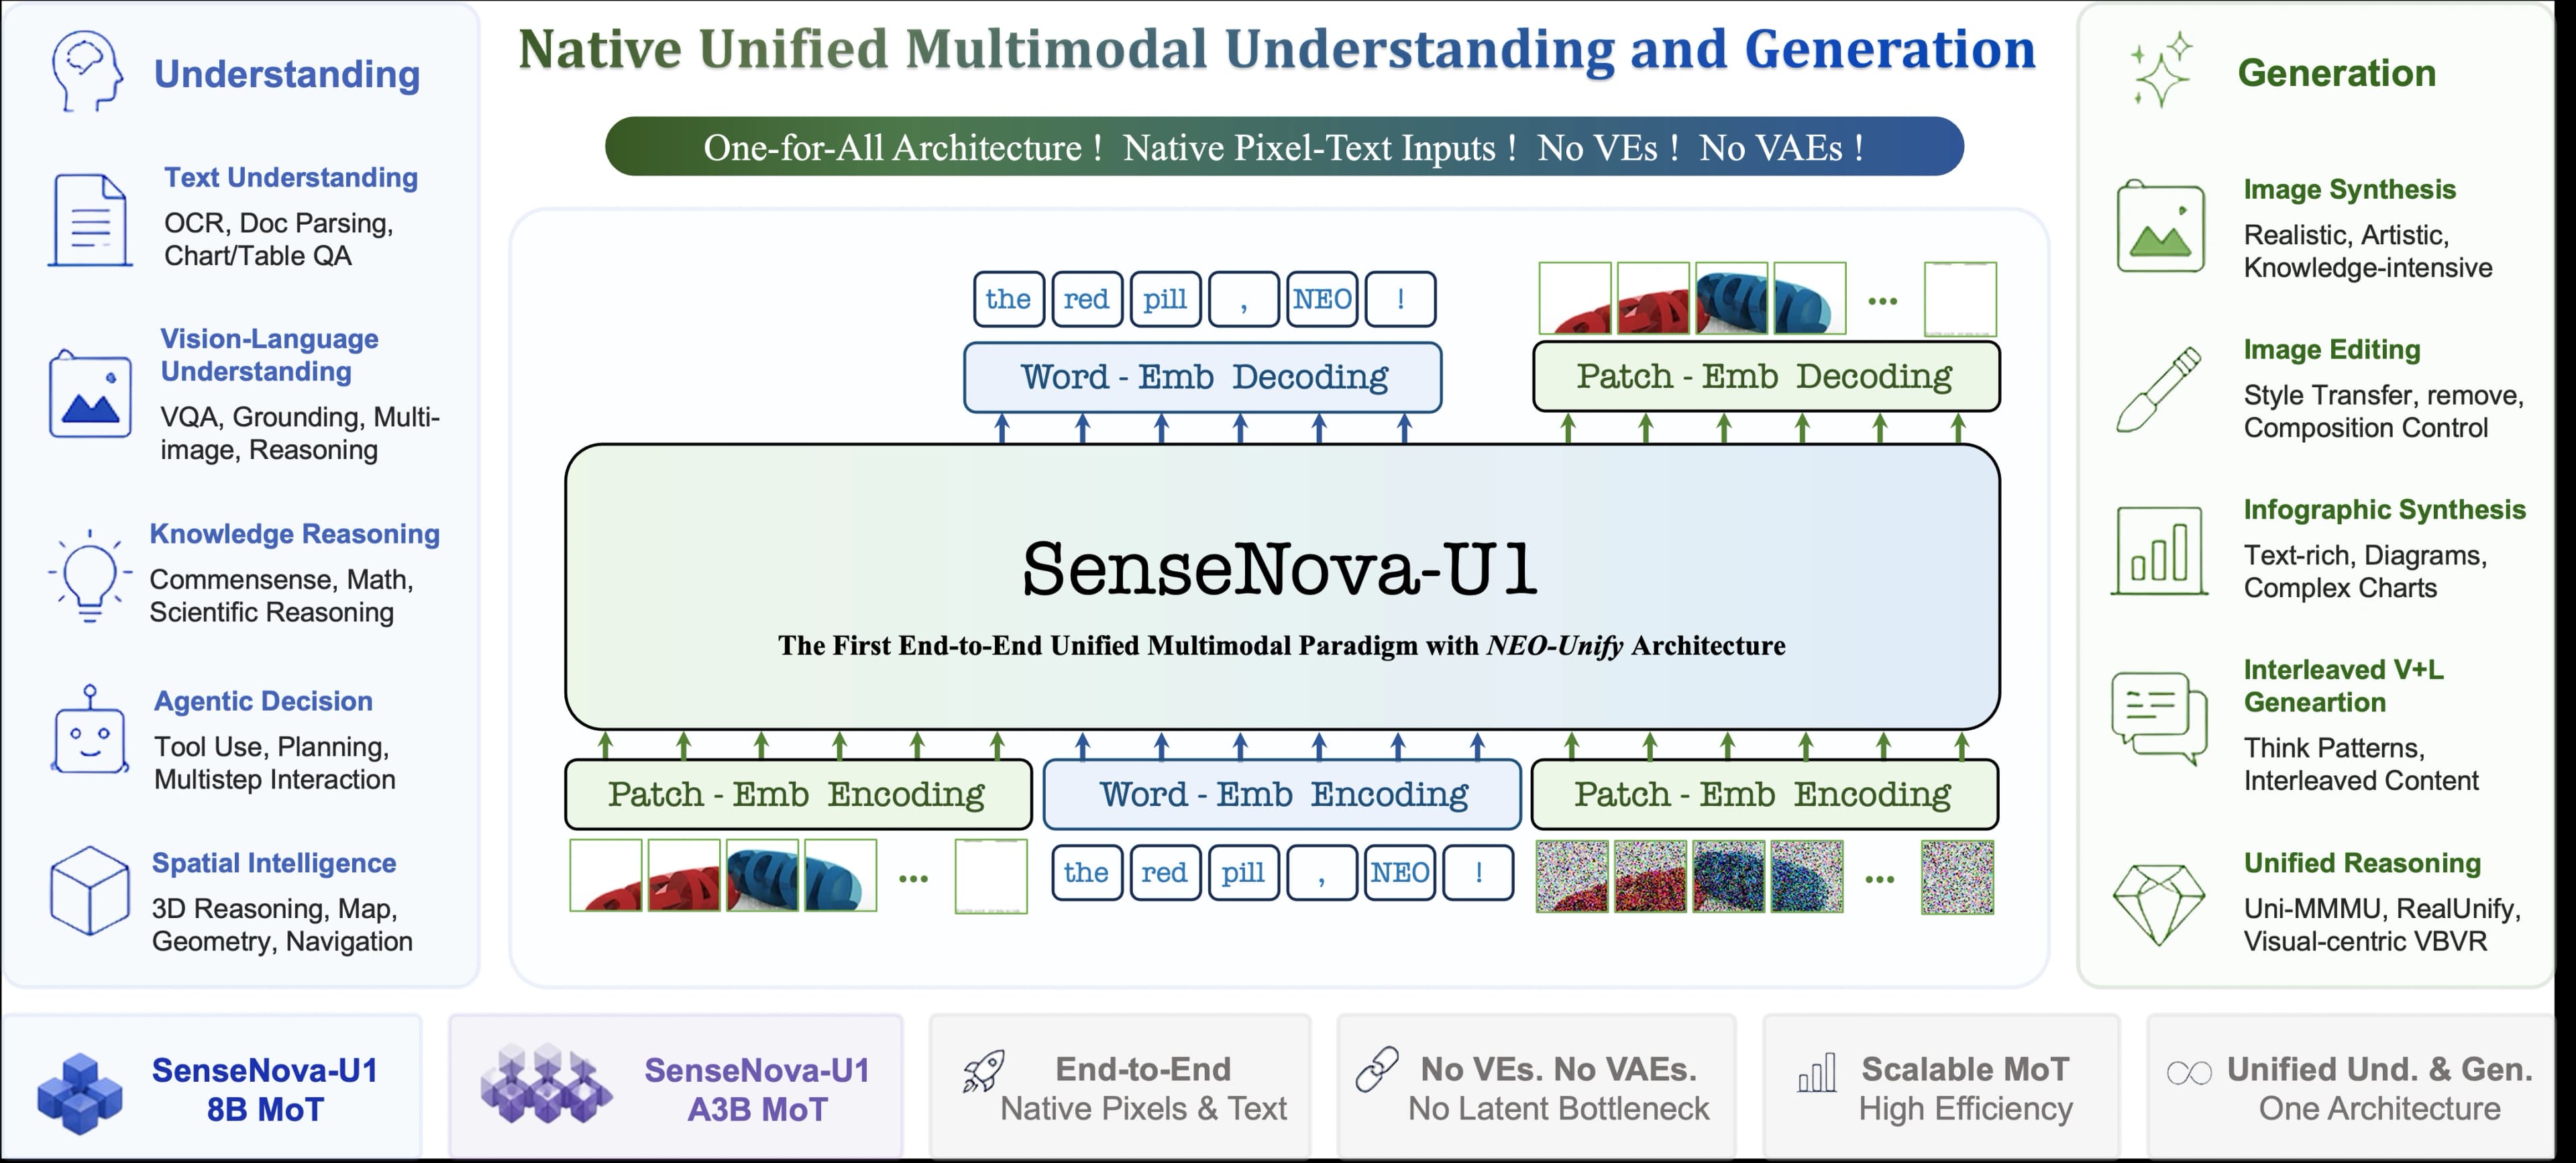
SenseTime has released SenseNova U1 8B MoT Infographic, an 8-billion-parameter model with a unique focus on creating and editing complex visual documents. The model represents a step forward in conversational AI, moving beyond simple prompts to handle 'any-to-any' interactions with interleaved text and images.
What sets SenseNova U1 apart is its 'Mixture of Talents' (MoT) architecture, which combines a large language model with a diffusion model. This allows it to not only generate images from text but also to understand and execute follow-up commands to edit those images within the same conversation. This is particularly useful for iterative design tasks, like building an infographic piece by piece.
According to the model card on Hugging Face, the system is designed to seamlessly switch between understanding user intent, generating visual elements, and continuing a natural-language dialogue.
Key Capabilities
- Any-to-Any Interaction: Can process and generate mixed sequences of text and images.
- In-Context Generation: Creates new images mid-conversation based on the preceding dialogue.
- Infographic Focus: Specialized skills for generating and editing charts, diagrams, and other infographic elements.
The model's weights are available for research and non-commercial use. While not a fully open-source release for commercial applications, it provides researchers with a powerful tool for exploring the frontier of generative multimodal AI.
Sources
- Visit
sensenova/SenseNova-U1-8B-MoT-Infographic
Hugging Face
More in Any-to-Any
StepFun's StepAudio 3 Realtime targets live voice AI
The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.
SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.

SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
0 comments
No comments yet. Be the first to weigh in.