SenseTime's SenseNova-Vision-7B-MoT Goes Any-to-Any
A single 7B model from SenseTime folds vision-language understanding, image generation, editing, and perception into one system.
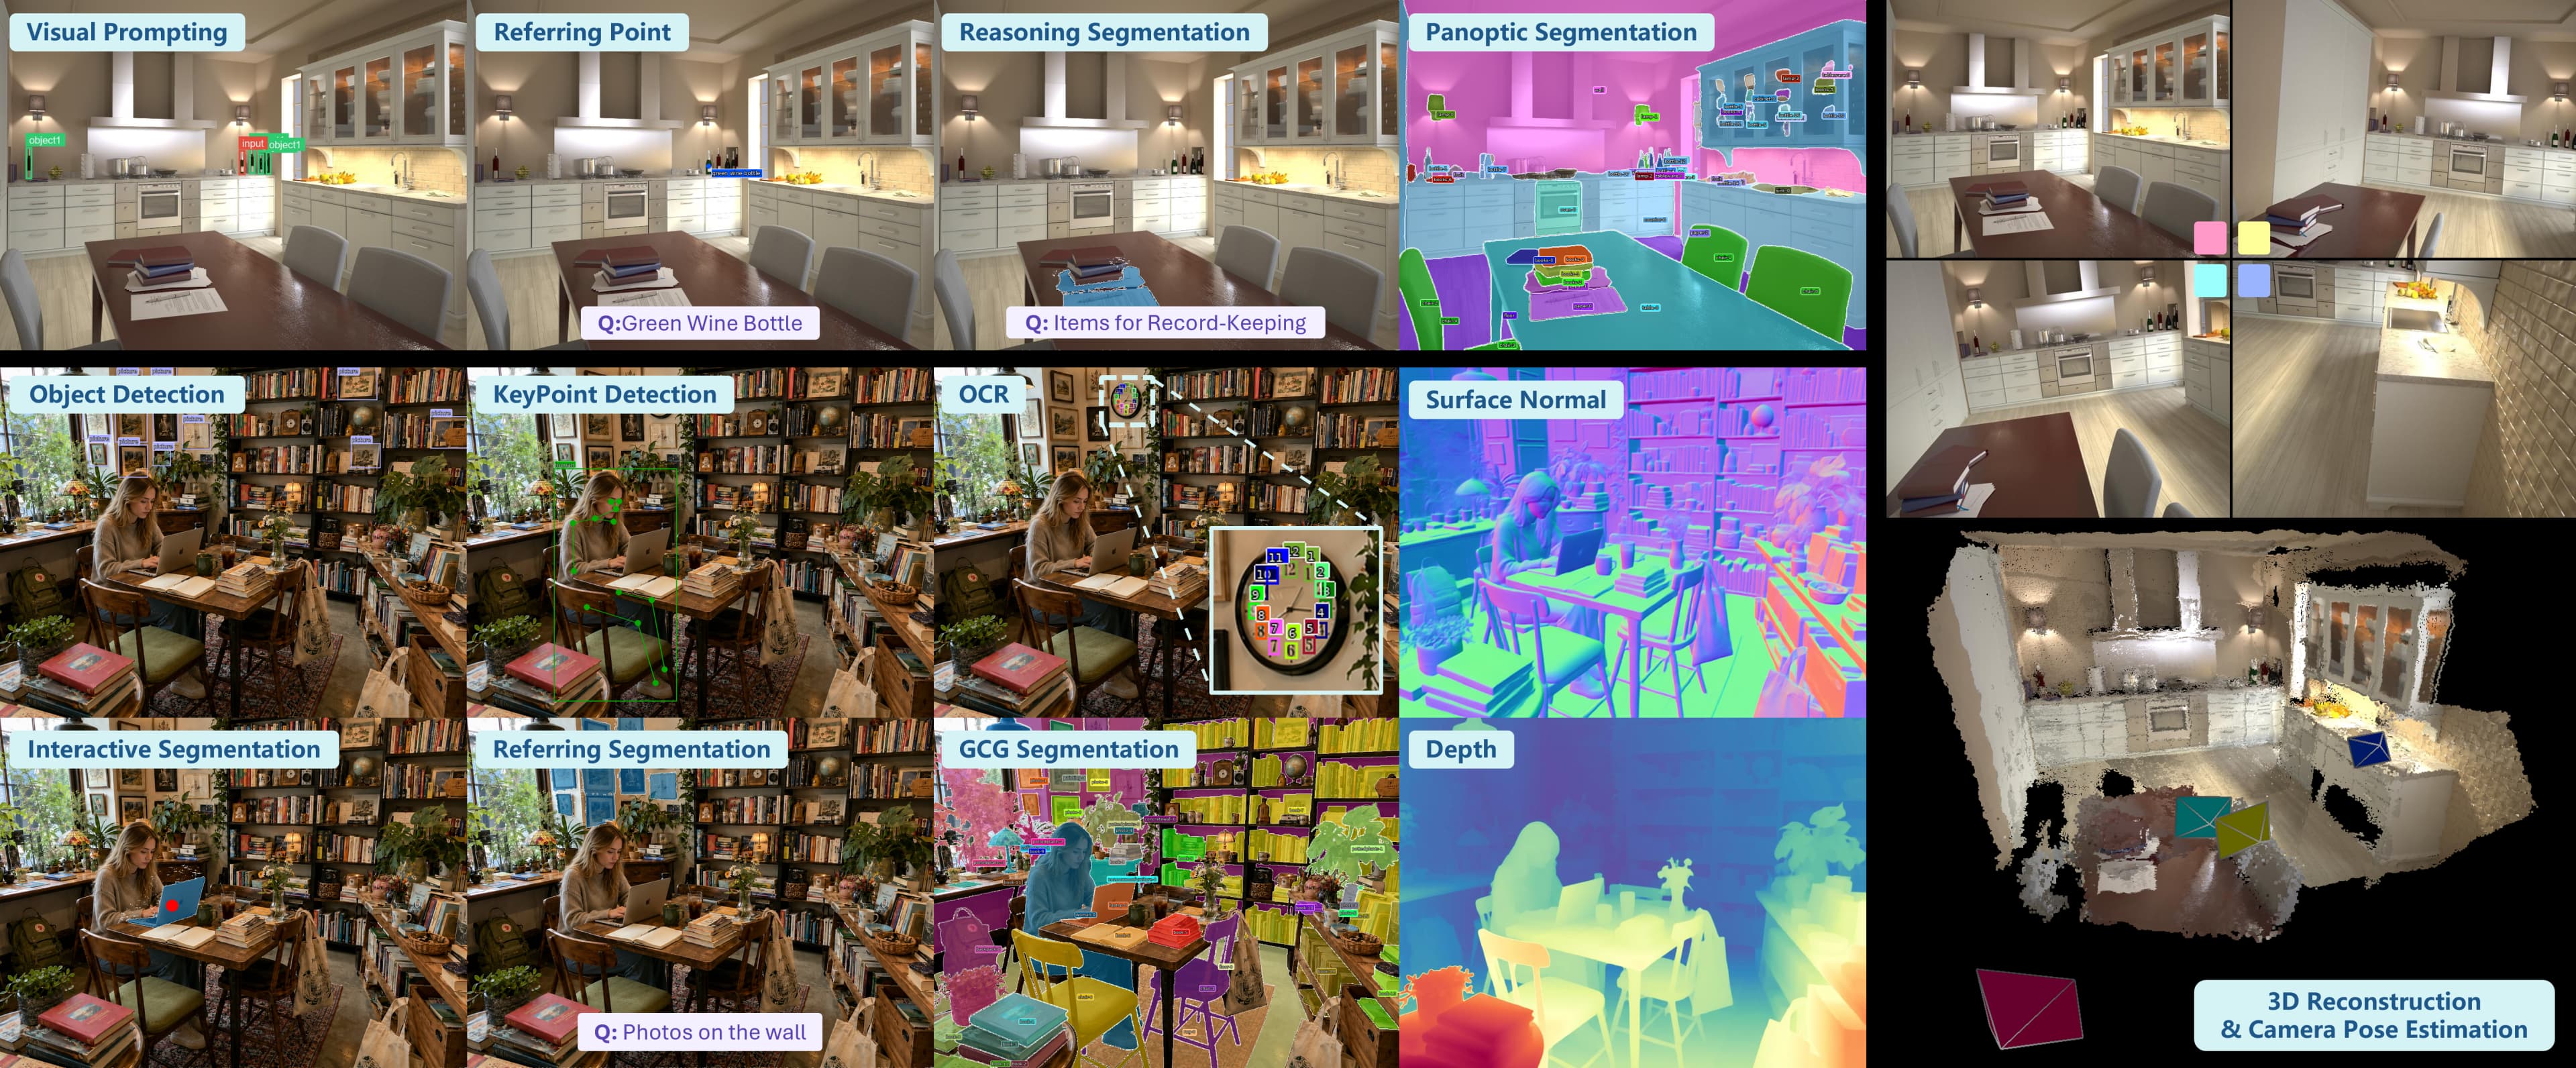
SenseTime has published SenseNova-Vision-7B-MoT on Hugging Face, a 7-billion-parameter multimodal model designed to handle a broad sweep of image and text tasks within a single architecture. Rather than shipping separate models for understanding and generation, the release positions itself as an "any-to-any" system.
What it covers
According to the release, the model targets several capabilities that are usually split across distinct systems:
- Vision-language understanding, in the style of a conventional VLM
- Image generation from text prompts
- Image editing
- Visual perception tasks
At 7B parameters and a dense (non-MoE) design, the model sits in a size class that many teams can run without exotic hardware, which matters for the kind of experimentation open weights are meant to enable.
Why it matters
The interesting bet here is unification. Most open multimodal stacks pair an understanding model with a separate diffusion or editing pipeline; combining perception, comprehension, generation and editing in one set of weights simplifies deployment and hints at tighter feedback between what a model sees and what it produces. Whether that translates to competitive quality on each individual task is the open question, and SenseTime has not attached headline benchmarks to this listing.
The model is distributed under an "other" license, so teams evaluating it for commercial use should read the terms on the model page carefully before building on it.
Sources
- Visit
sensenova/SenseNova-Vision-7B-MoT
Hugging Face
More from SenseTime
All SenseTime releases →SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
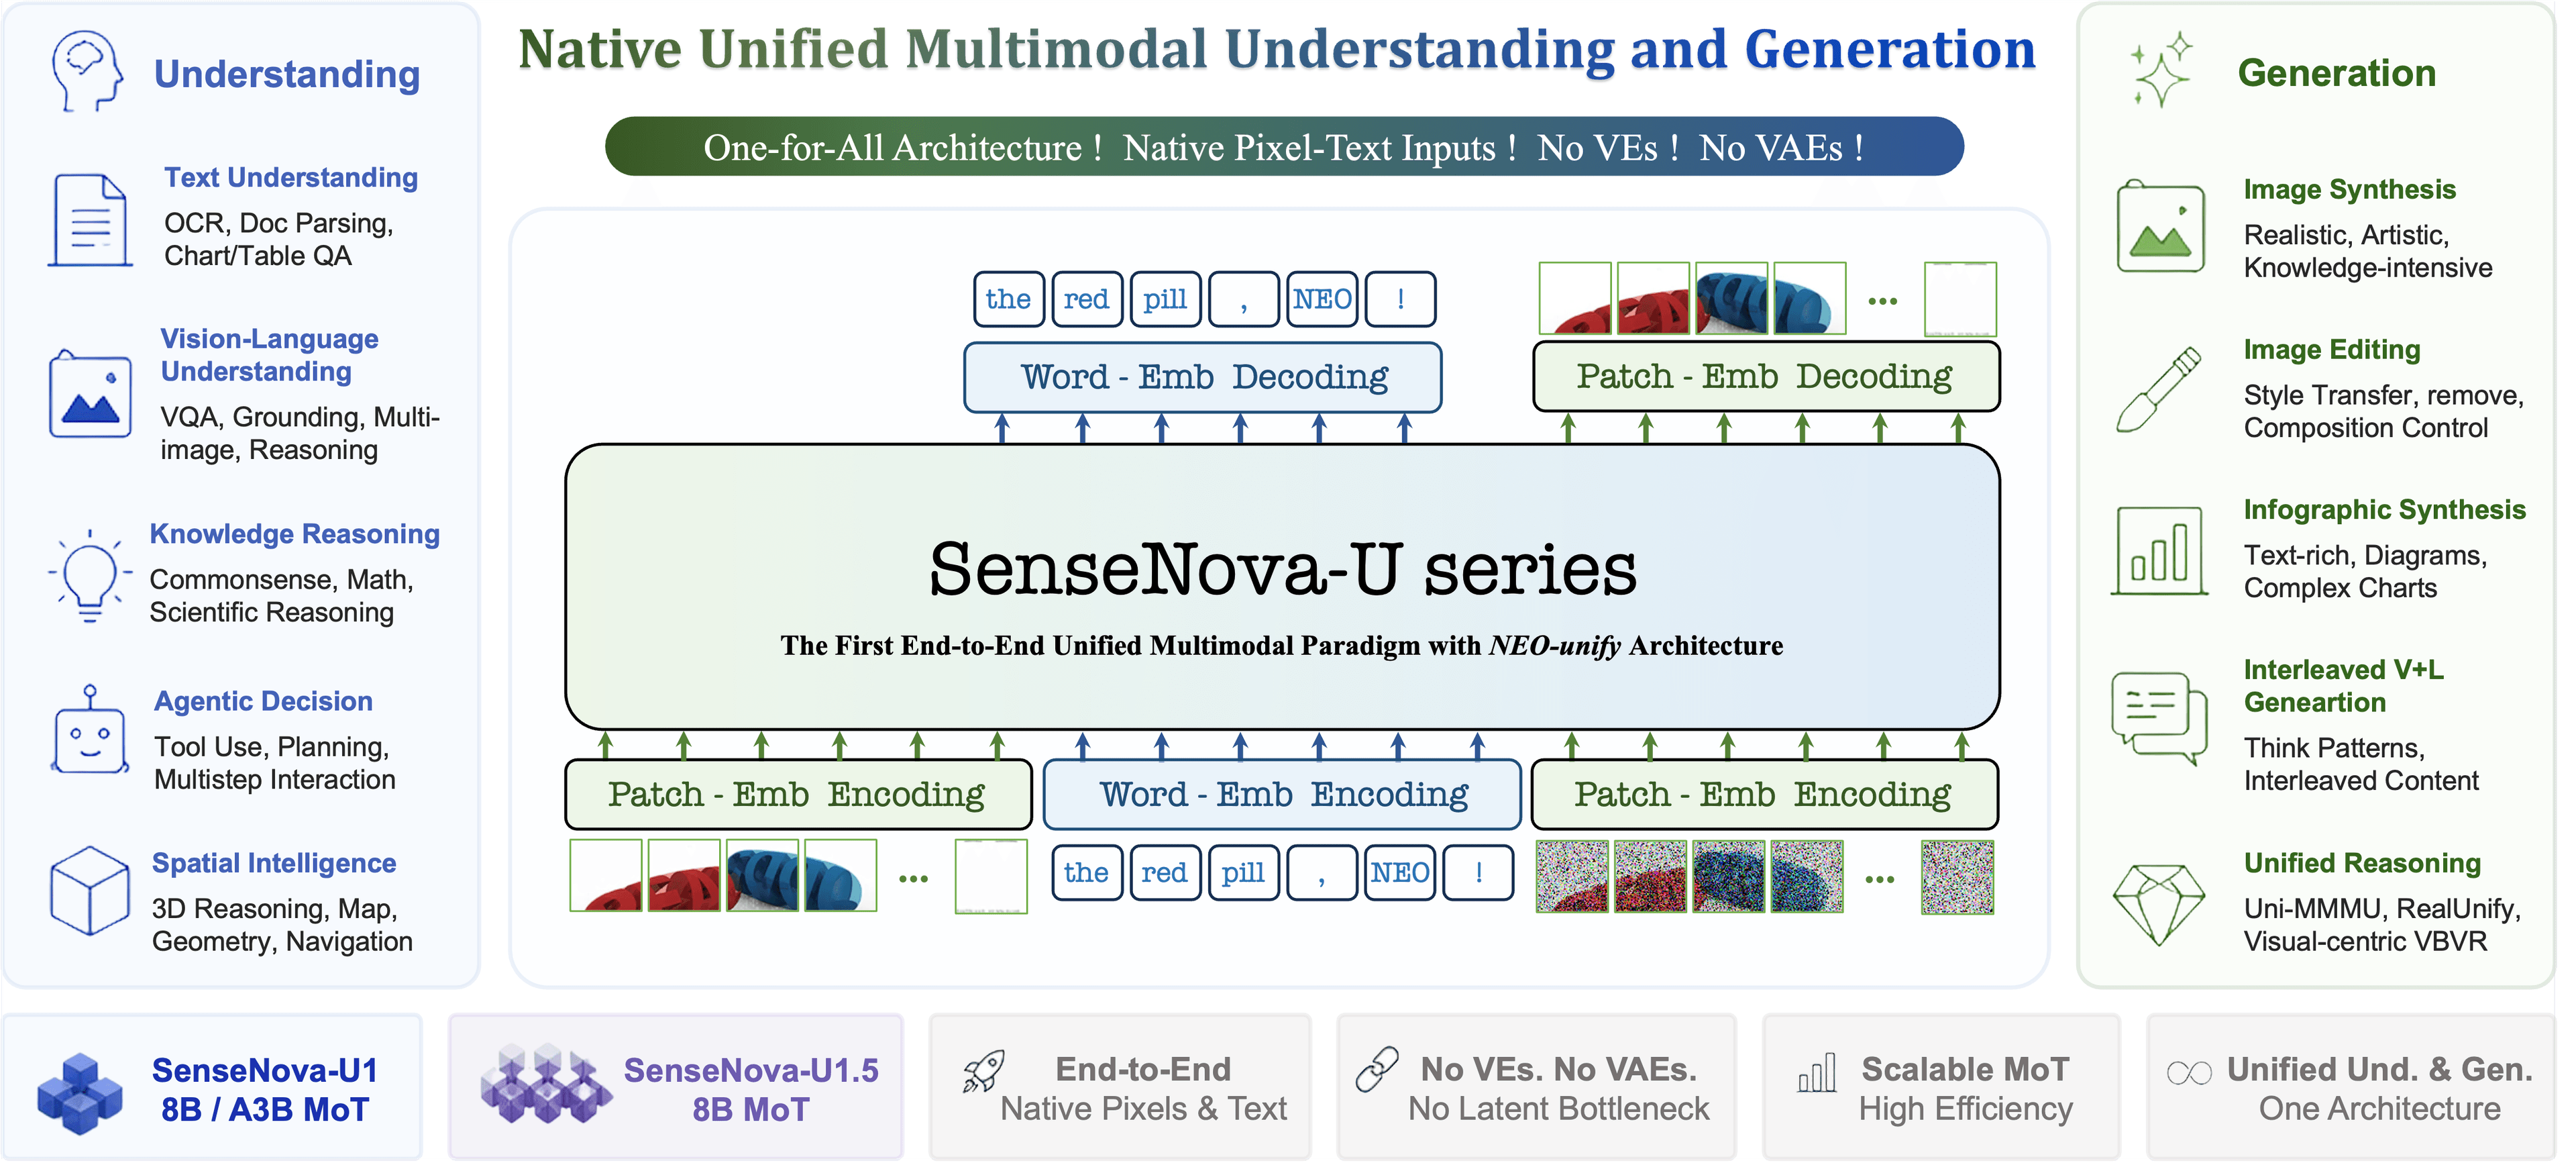
SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
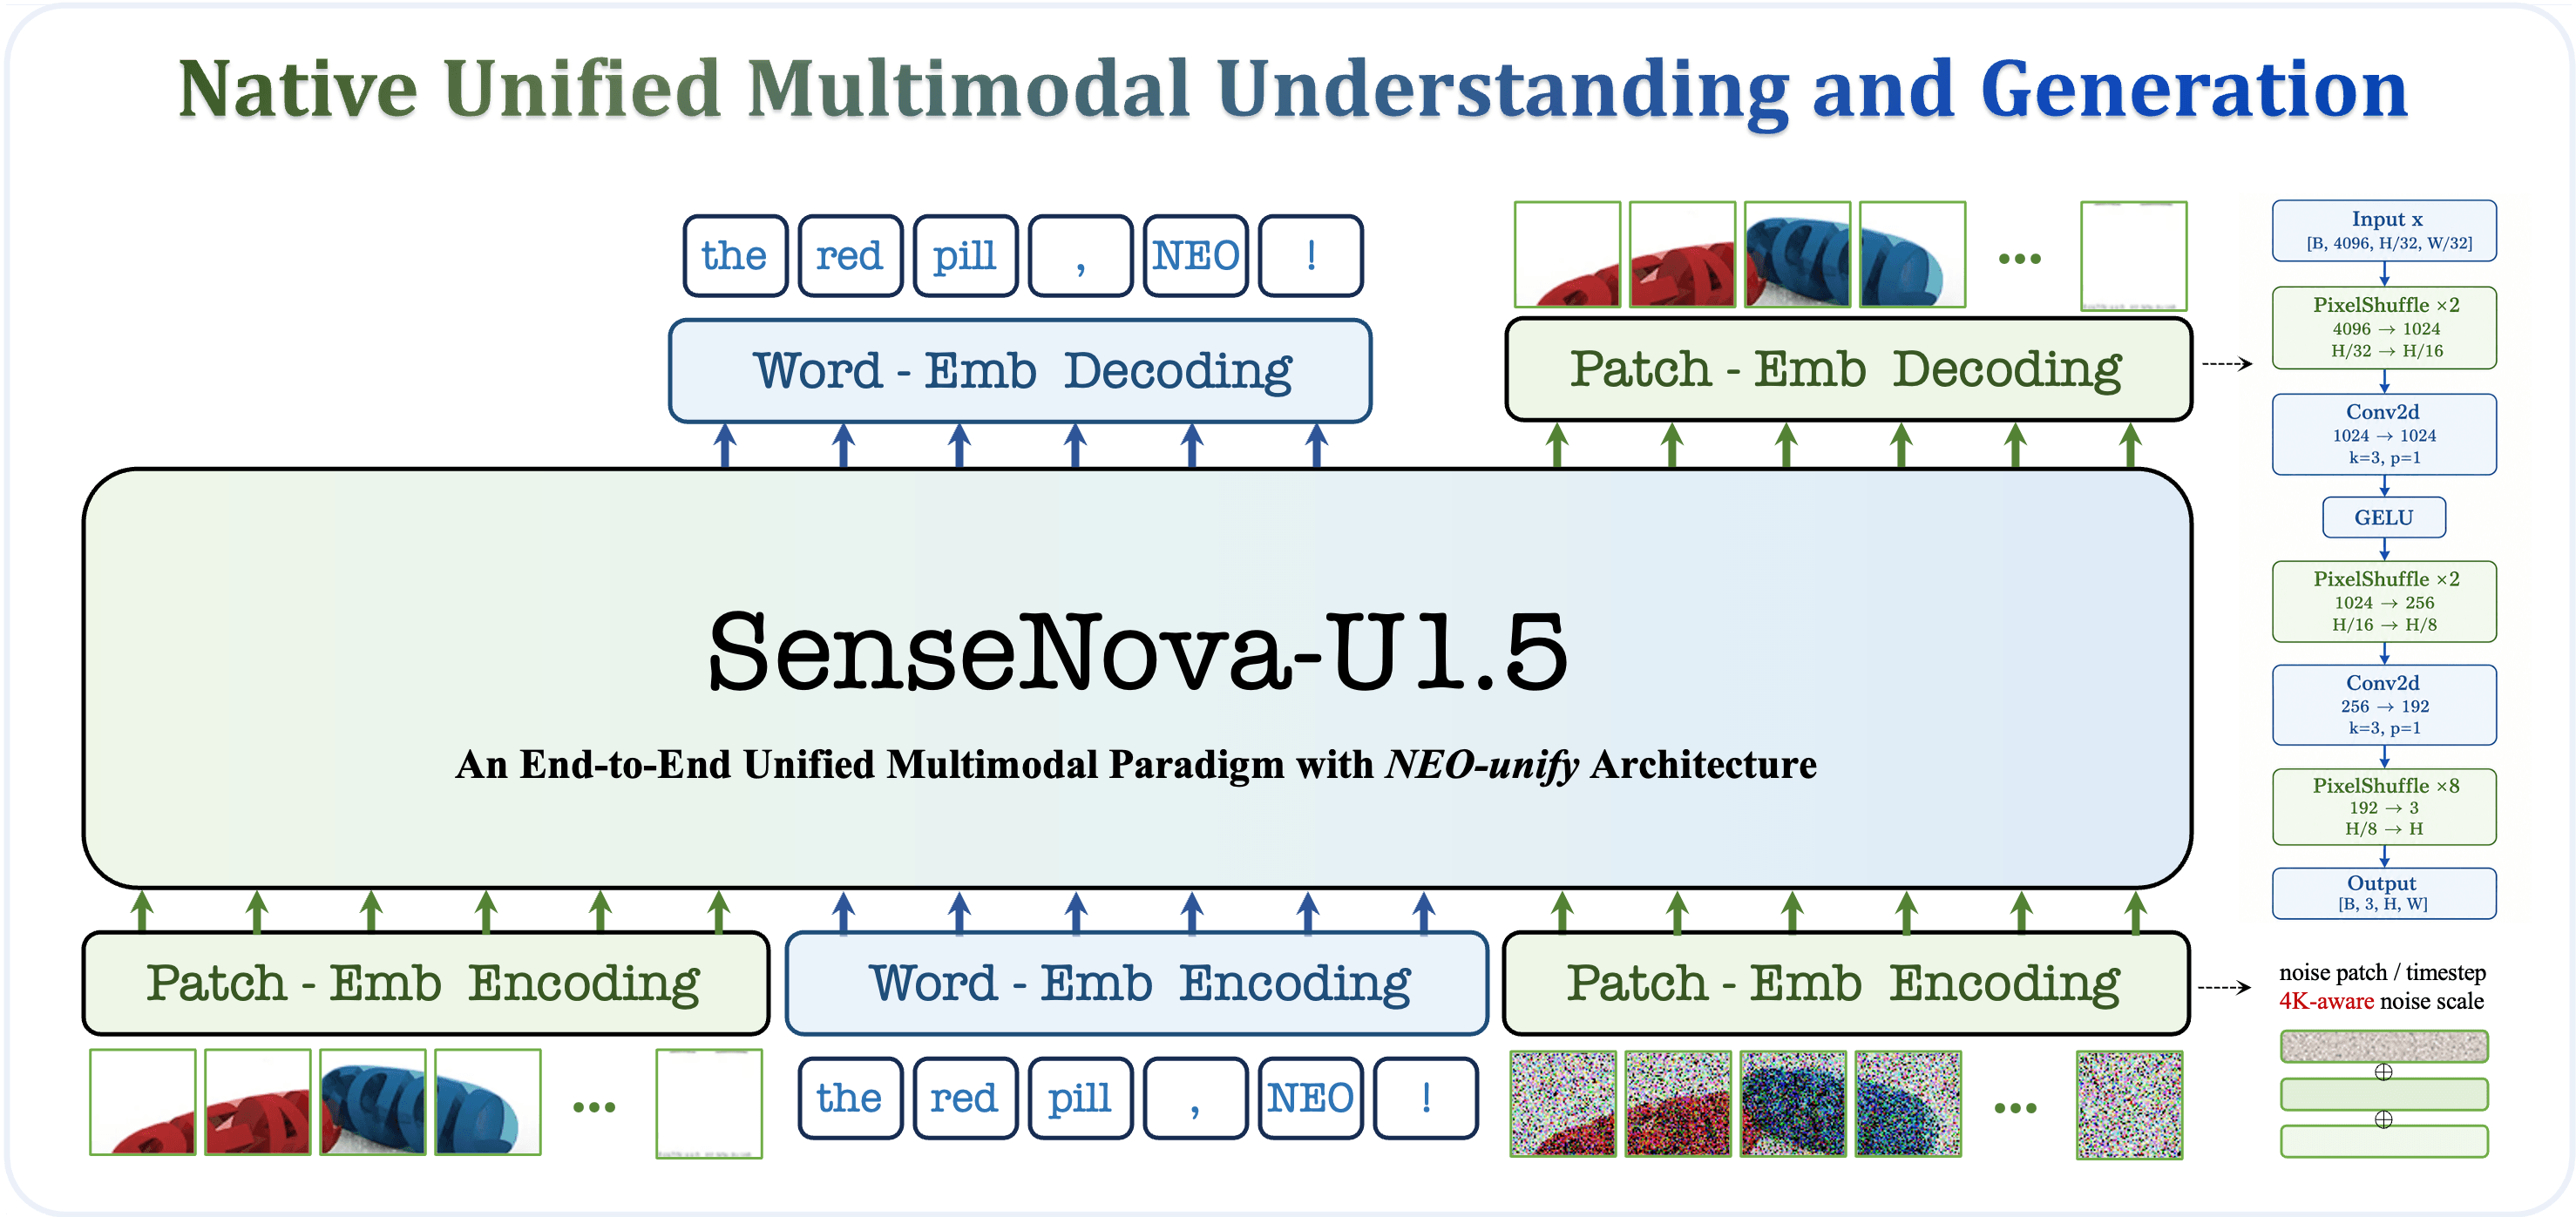
SenseTime Debuts SenseNova U1.5 8B Multimodal Preview
An 8B any-to-any model that reads, generates, and edits images at up to 4K resolution, released as an early preview.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.