Liquid AI's LFM2.5-DSpark targets faster inference
The new efficient language model claims up to 3.2x faster inference, extending Liquid AI's push toward lean, deployable models.
Liquid AI has released LFM2.5-DSpark, a compact language model built around one central promise: speed. According to the company's release post on Hugging Face, the model delivers up to 3.2x faster inference than comparable baselines, positioning it for latency-sensitive and resource-constrained deployments.
The model sits in the small-to-mid size range, making it a candidate for on-device workloads, edge hardware, and applications where serving costs scale with every token. Rather than chasing frontier benchmark scores, DSpark leans into the efficiency story that has defined much of Liquid AI's recent work.
Why it matters
Inference speed has quietly become one of the most important axes of competition in open models. A faster model means lower serving bills, better responsiveness in interactive apps, and the ability to run useful AI on smaller hardware.
- Up to 3.2x faster inference versus comparable models
- Compact footprint suited to edge and cost-sensitive deployments
- Distributed through Hugging Face under Liquid AI's release
As with any efficiency-focused release, the real test will come from independent evaluation of how DSpark's speed gains hold up against quality trade-offs across varied tasks. For teams weighing throughput against accuracy, the model is worth a look via the official announcement.
Sources
More from NVIDIA
All NVIDIA releases →NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
More in Text / LLM
All Text / LLM →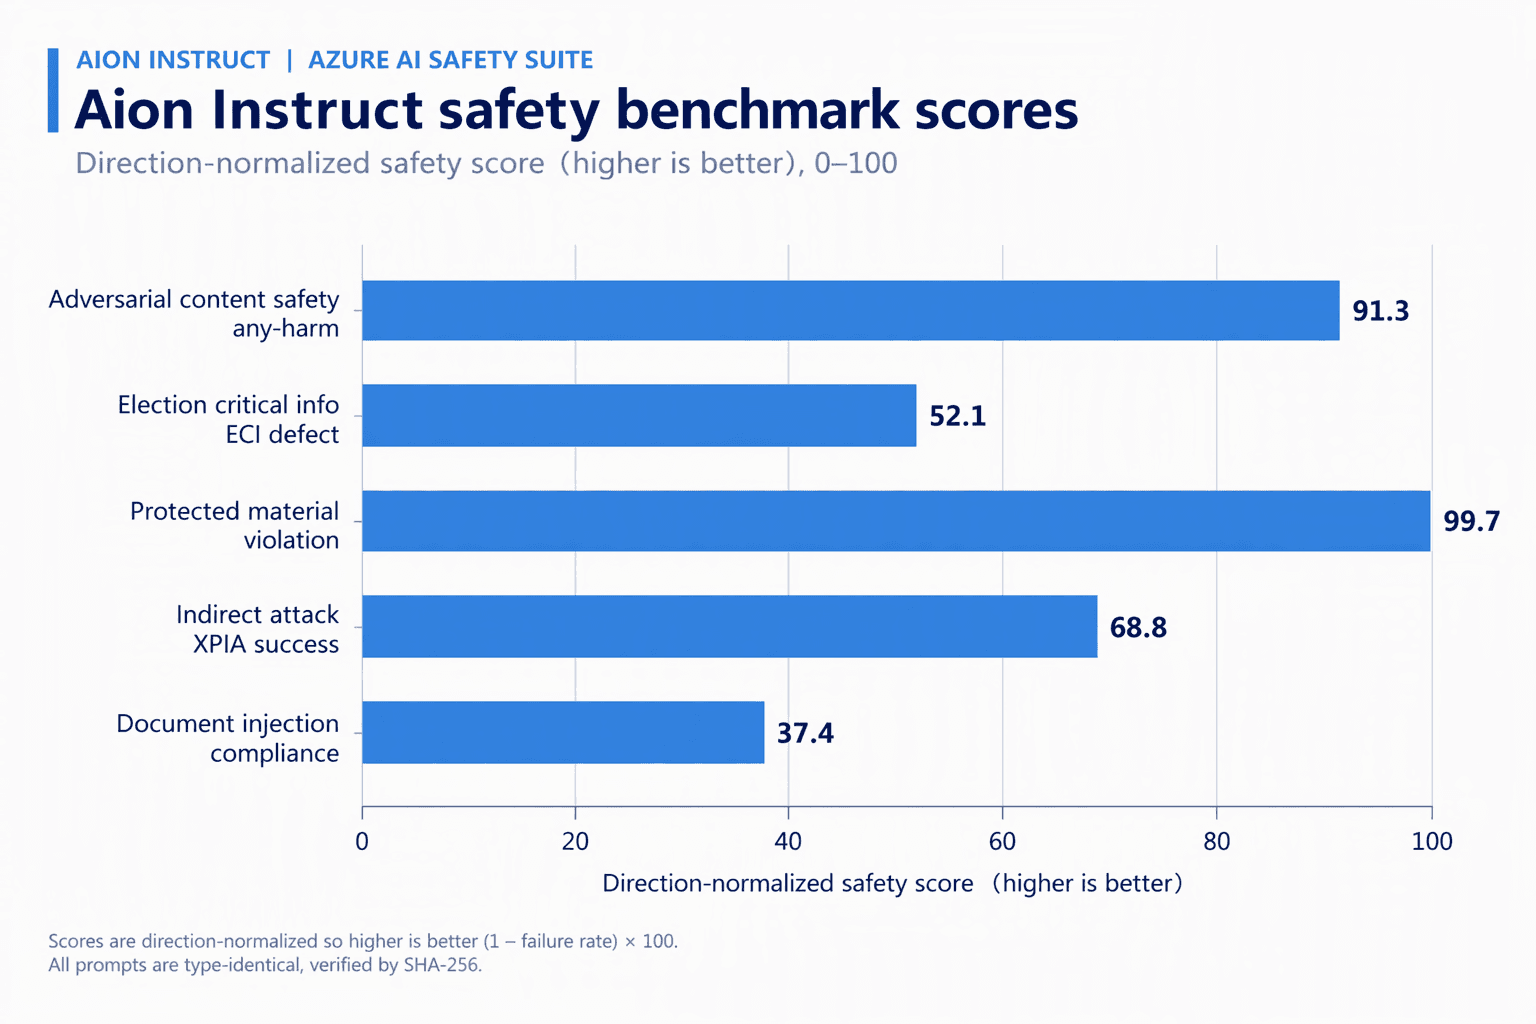
Microsoft's Aion 1.0 Instruct is a compact 2.3B chat model
A small, multilingual instruction-tuned model aimed at chat and summarization lands on Hugging Face.

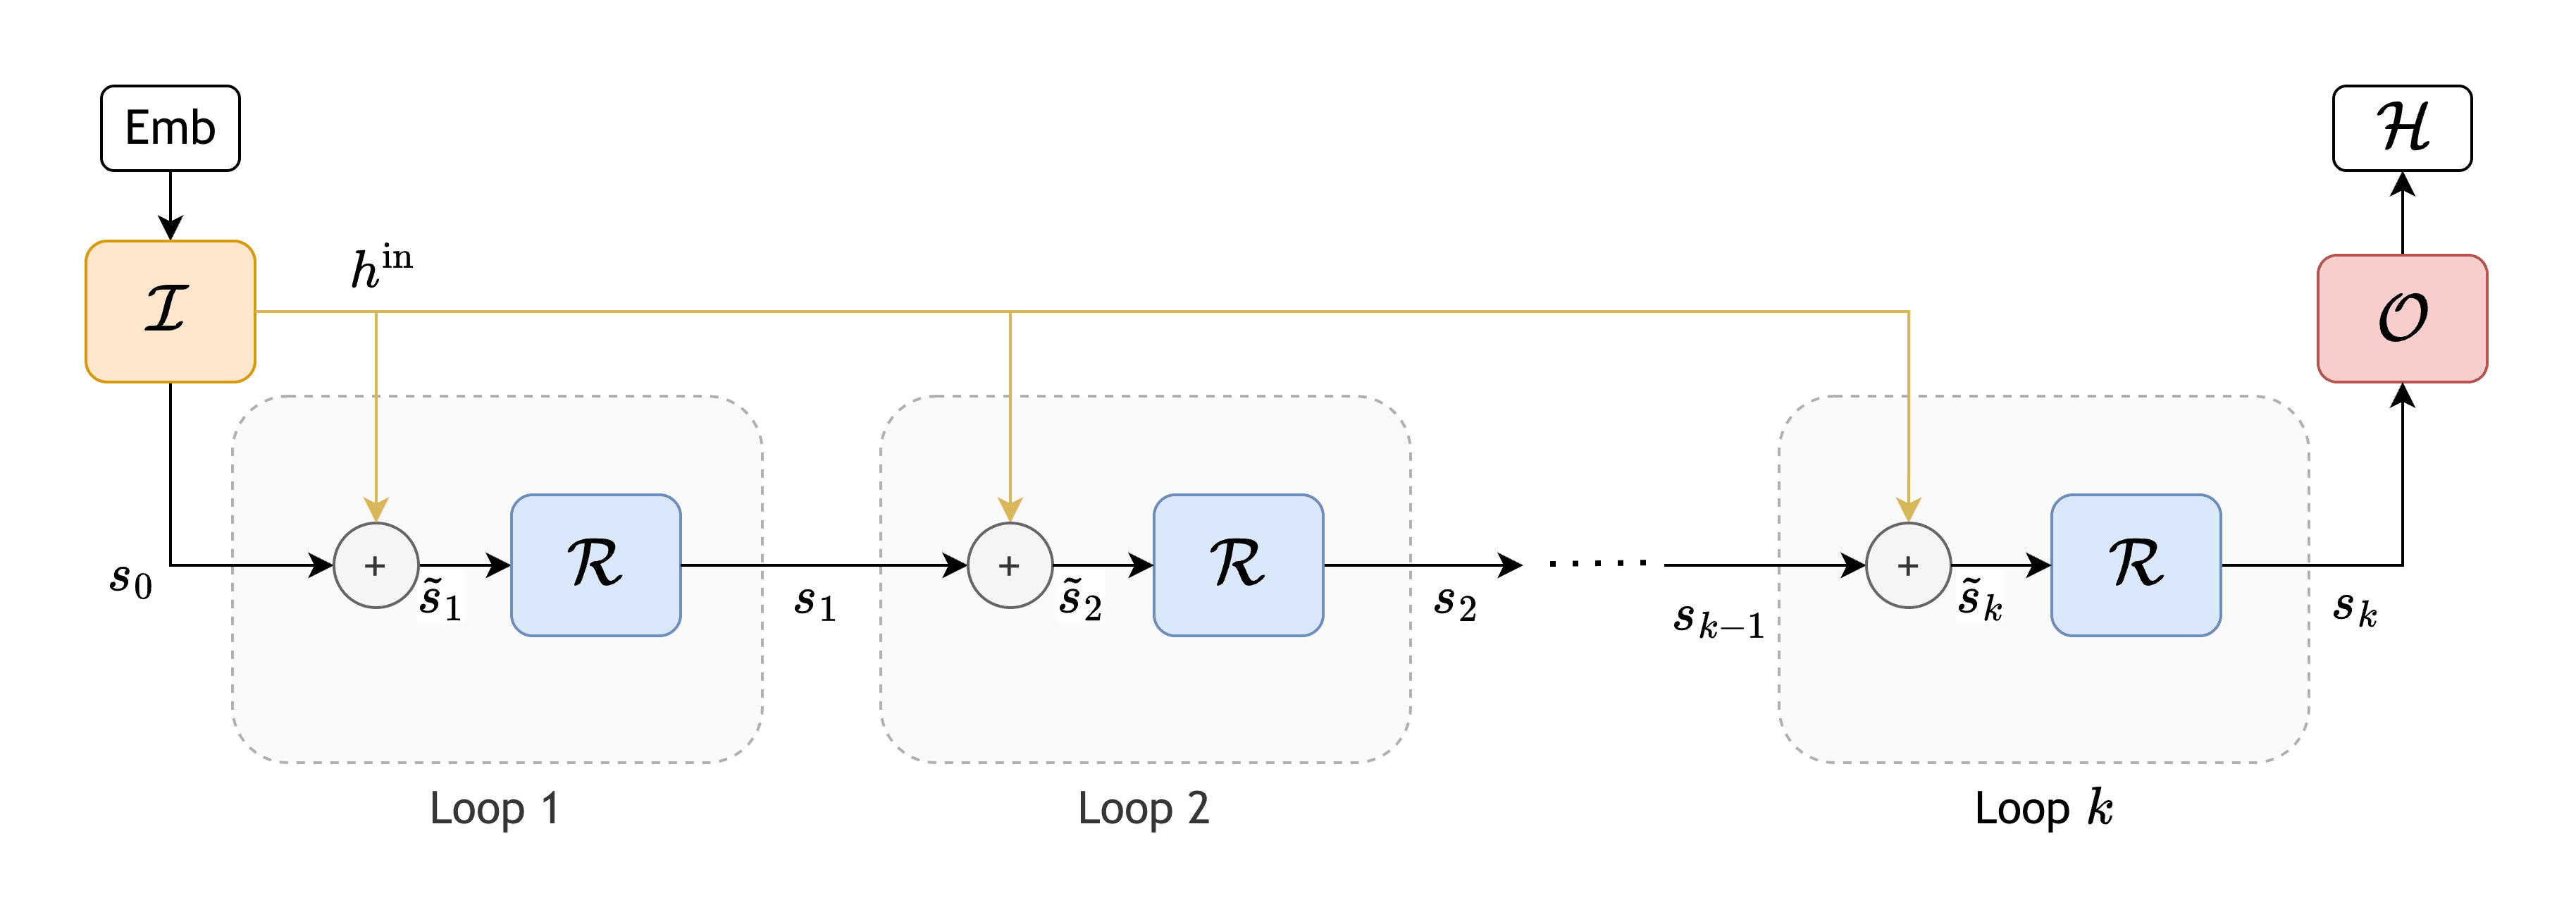
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
0 comments
No comments yet. Be the first to weigh in.