Tencent releases Hunyuan Hy4, an MoE vision-language model
The instruction-tuned, mixture-of-experts model handles both images and text under an open weights listing on Hugging Face.
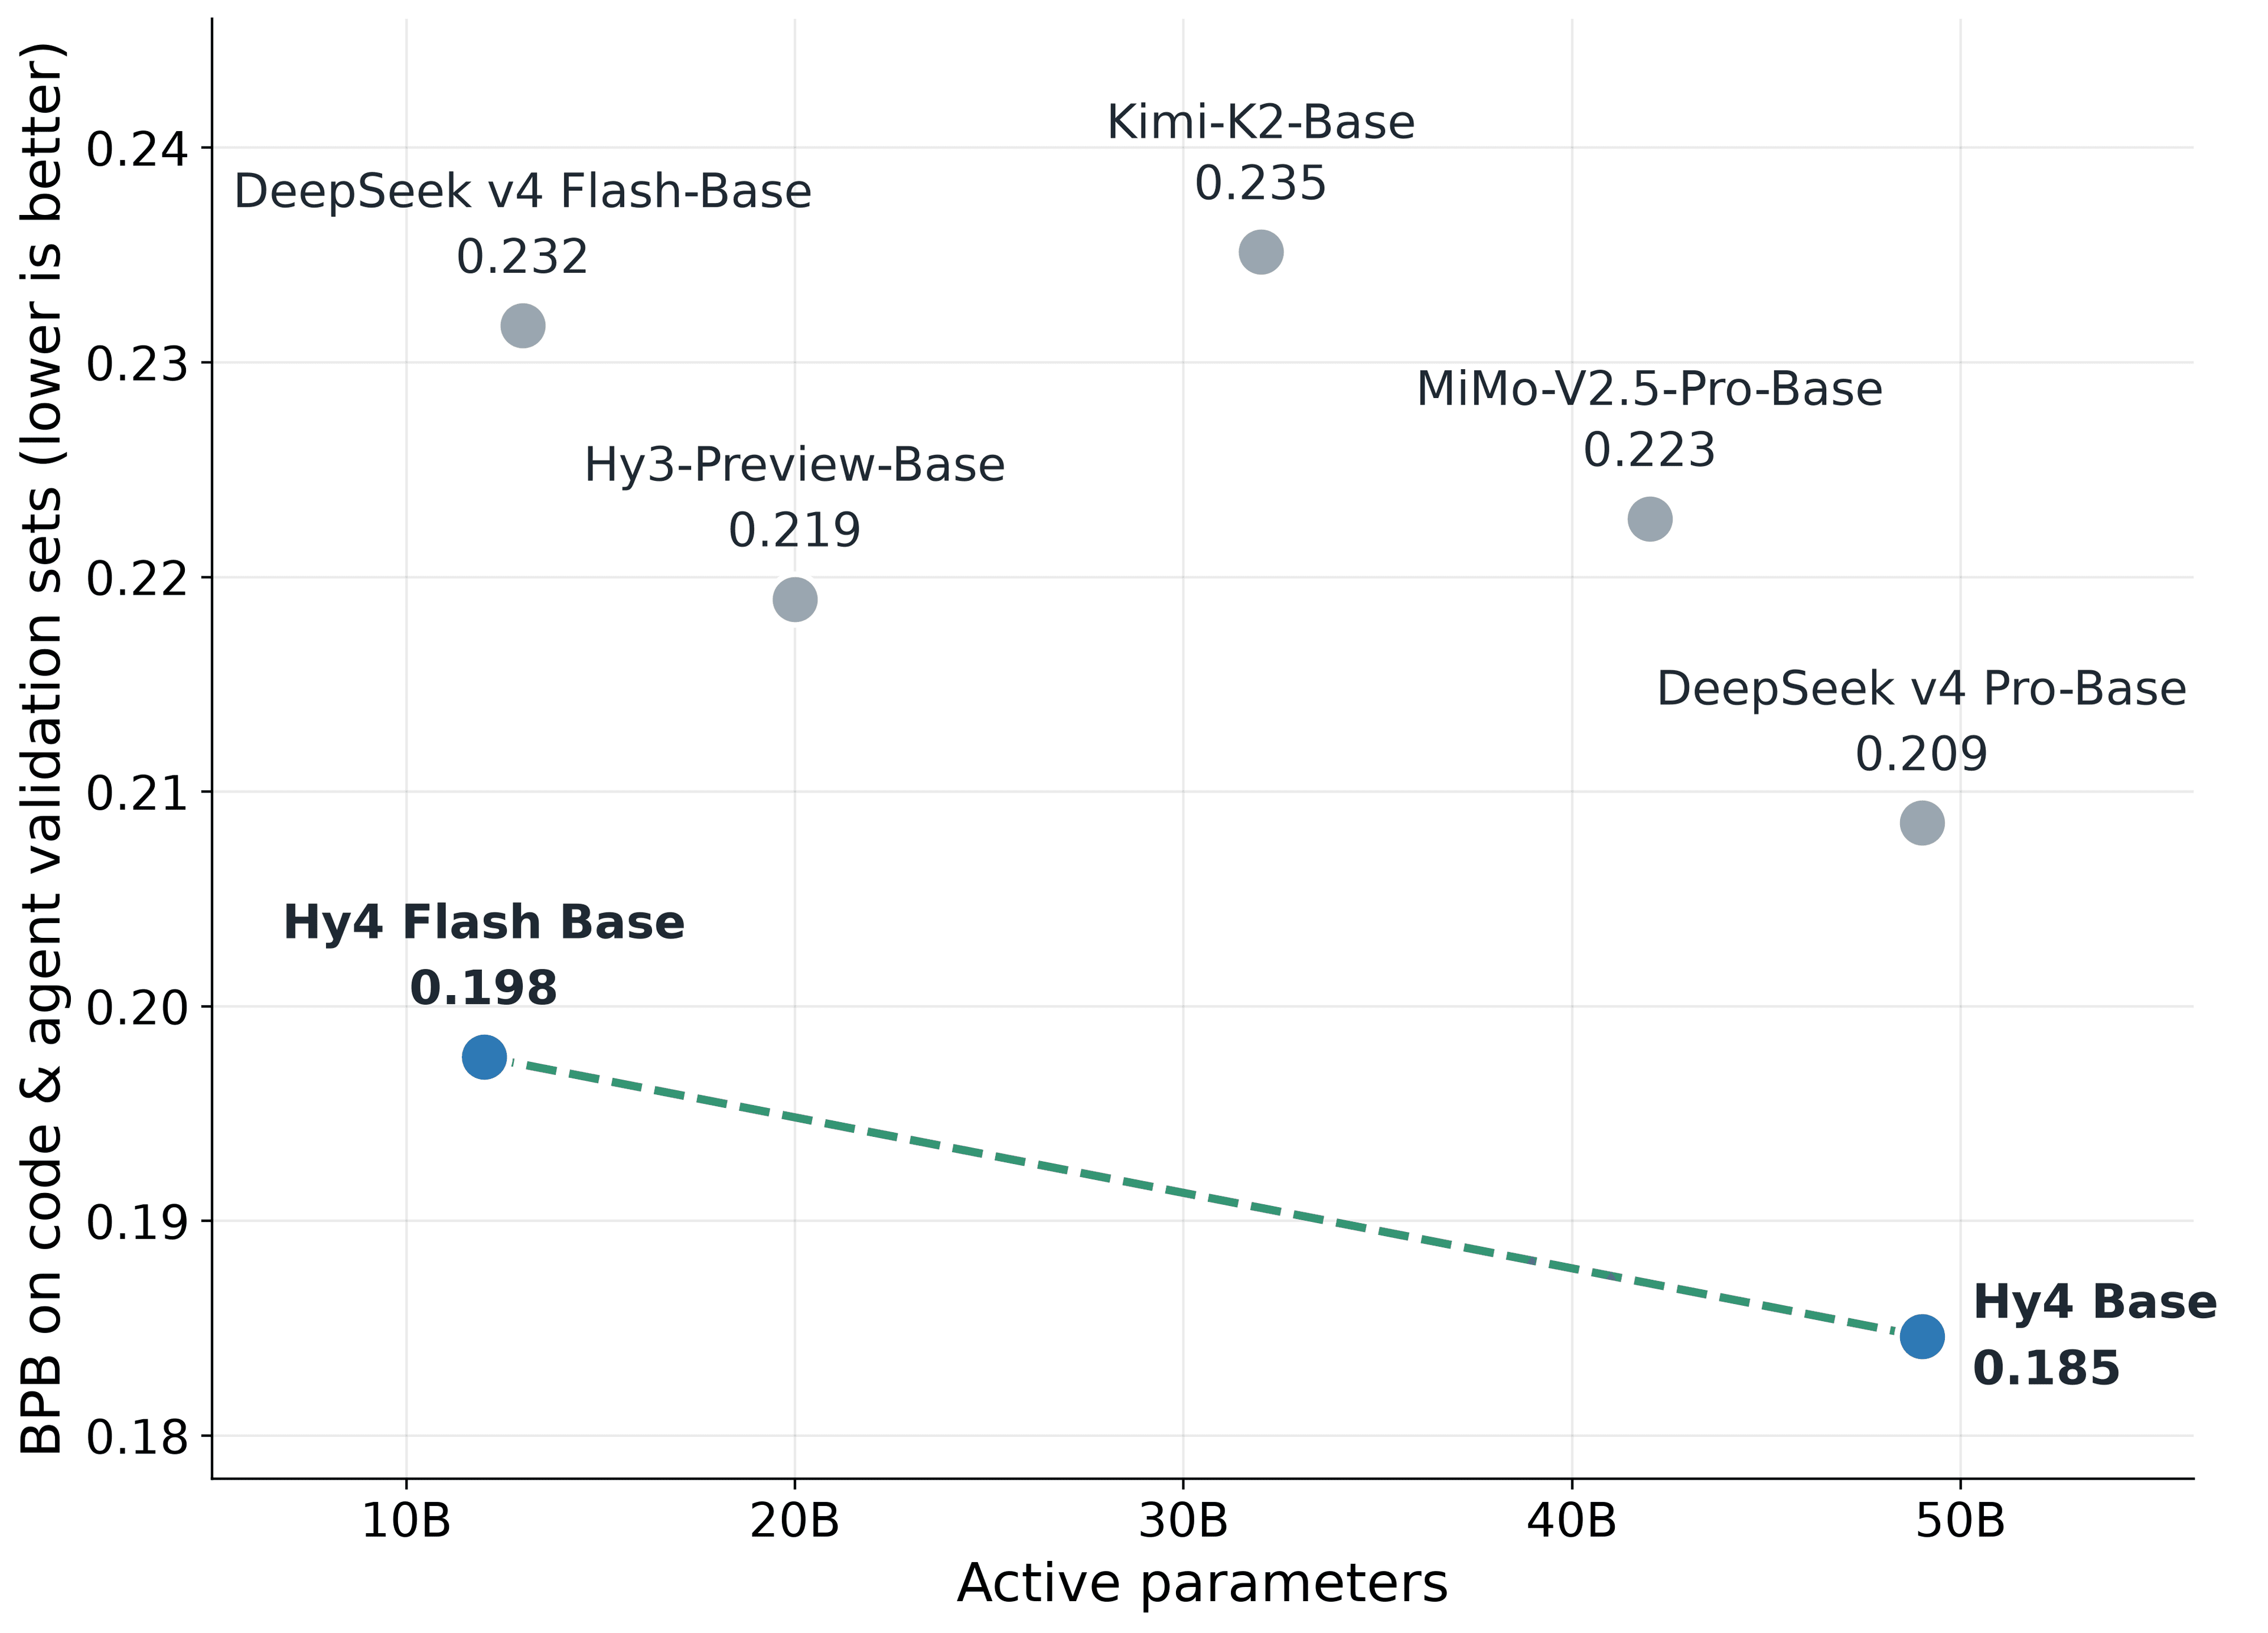
Tencent has published Hunyuan Hy4, a multimodal vision-language model, to Hugging Face. The release extends the company's Hunyuan line into territory that pairs image understanding with text generation in a single system.
Hy4 is described as an instruction-tuned model built on a mixture-of-experts (MoE) architecture. MoE designs activate only a subset of their parameters for any given input, a technique that lets developers scale total capacity while keeping the compute cost of each inference in check. That approach has become a common thread across recent frontier-scale open releases.
Why it matters
Vision-language models are the connective tissue for a growing set of applications — document parsing, UI automation, visual question answering, and multimodal assistants among them. A capable open-weights VLM from a company of Tencent's scale gives developers another foundation to build on without committing to a closed API.
A few practical notes from the listing:
- It is positioned as a vision-language model with text generation capability.
- It uses a mixture-of-experts architecture and is instruction-tuned.
- It ships under a custom license, so teams should review the terms before commercial use.
Tencent has not yet detailed parameter counts, context length, or benchmark results in the record available at launch. Prospective users will want to watch the model card for documentation, evaluation numbers, and licensing specifics as they are published.
Sources
- Visit
tencent/Hy4
Hugging Face
More from Tencent
All Tencent releases →
Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
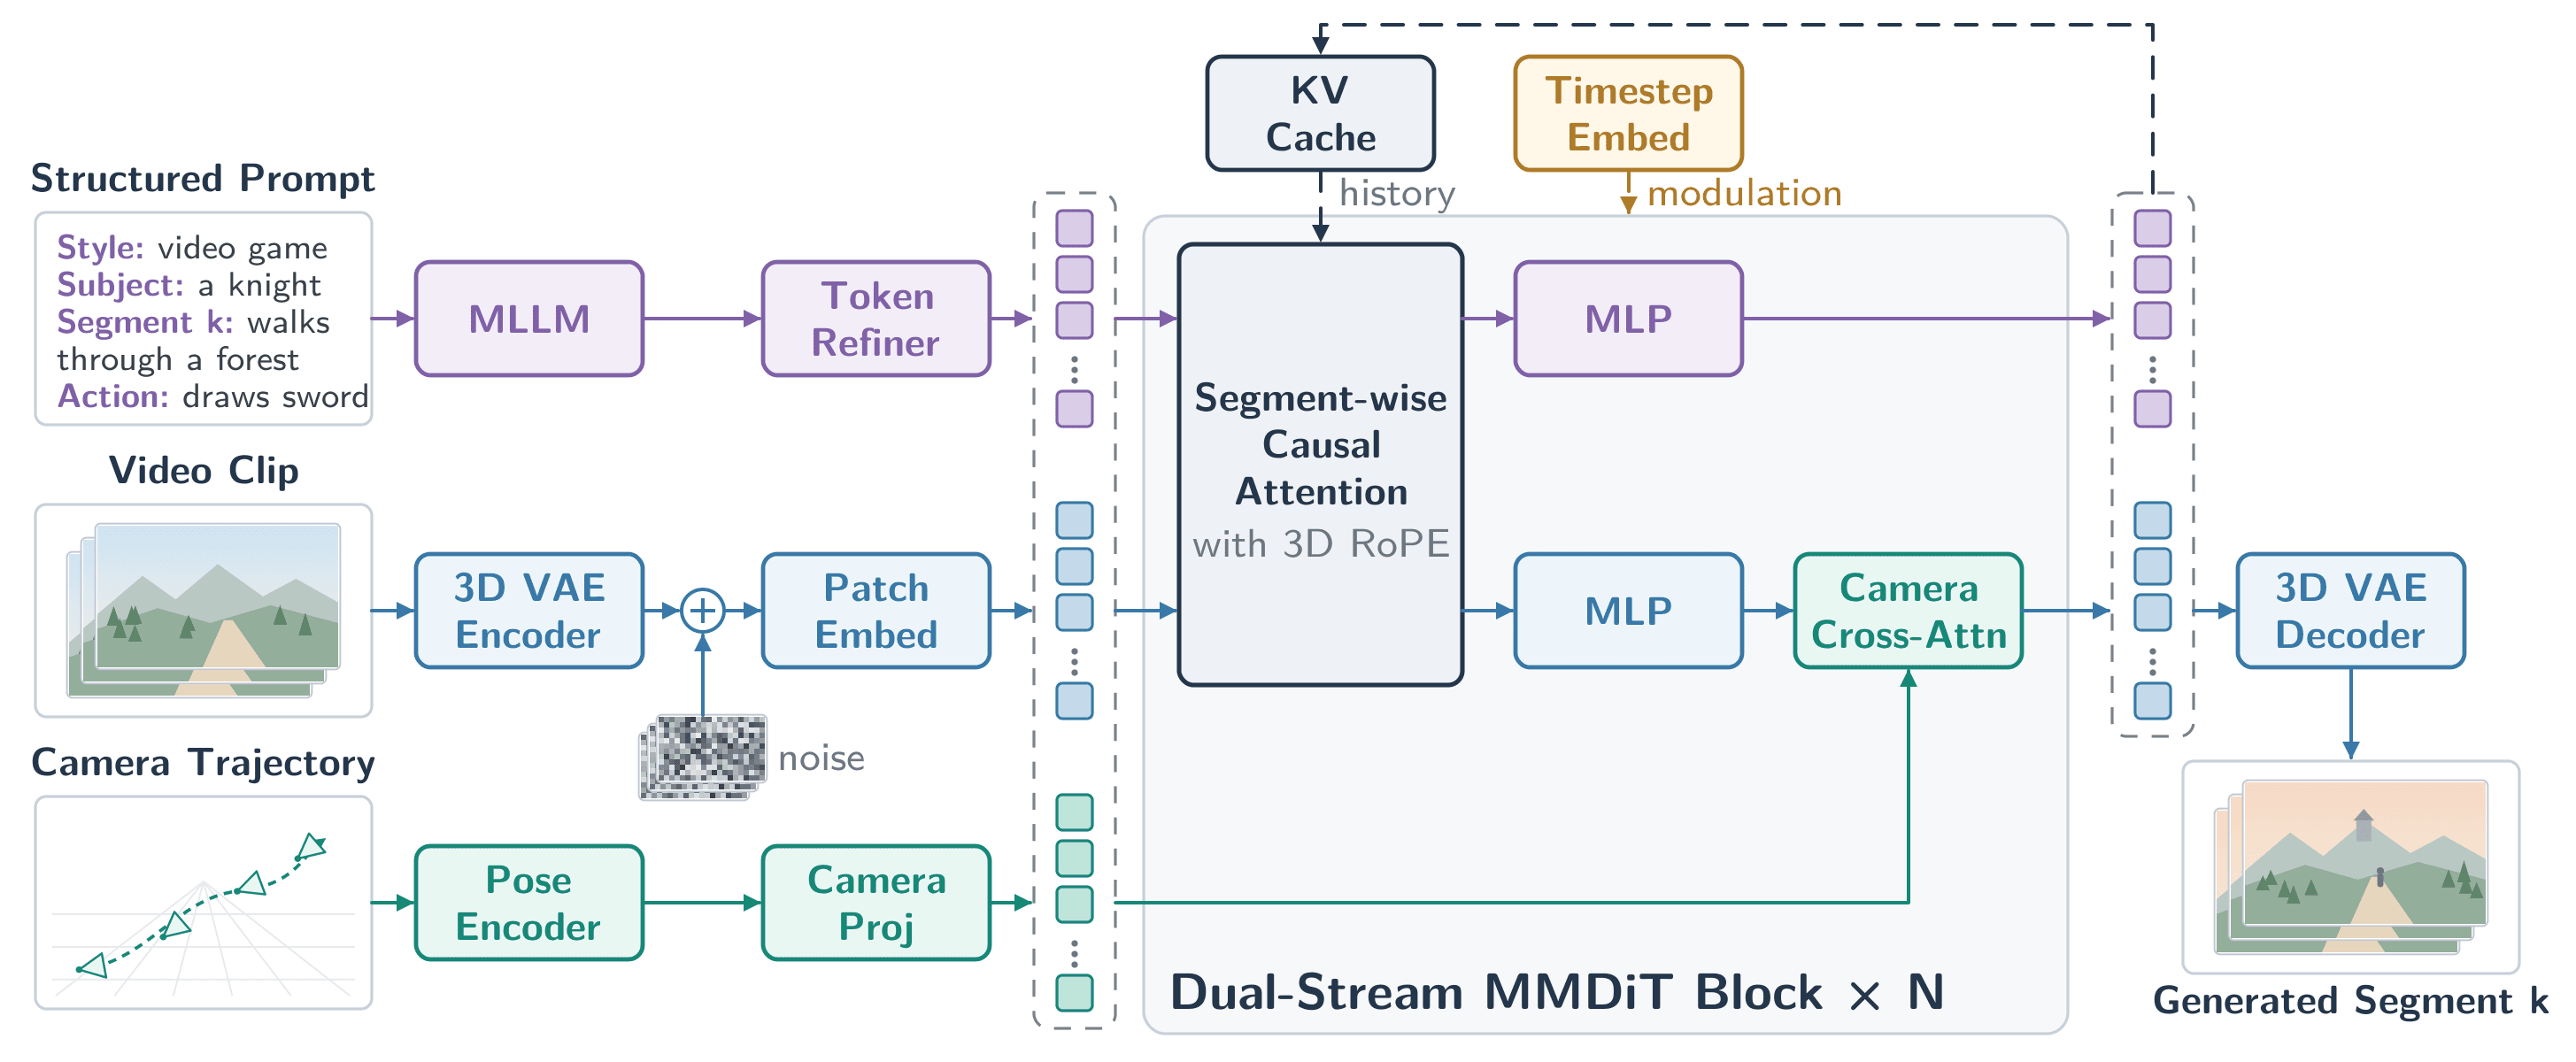
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
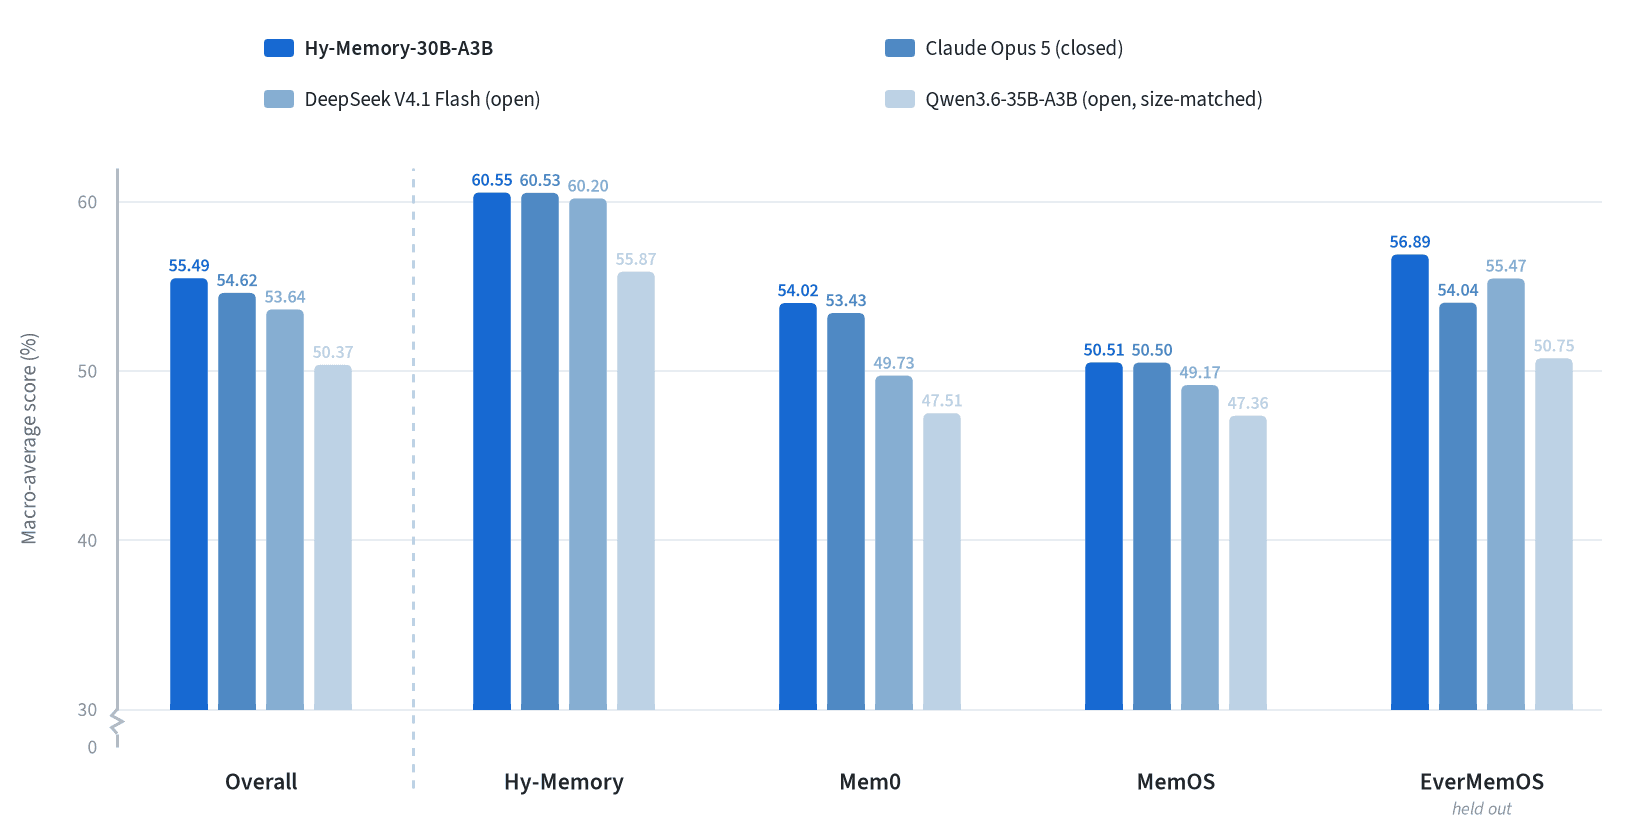
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
More in Text / LLM
All Text / LLM →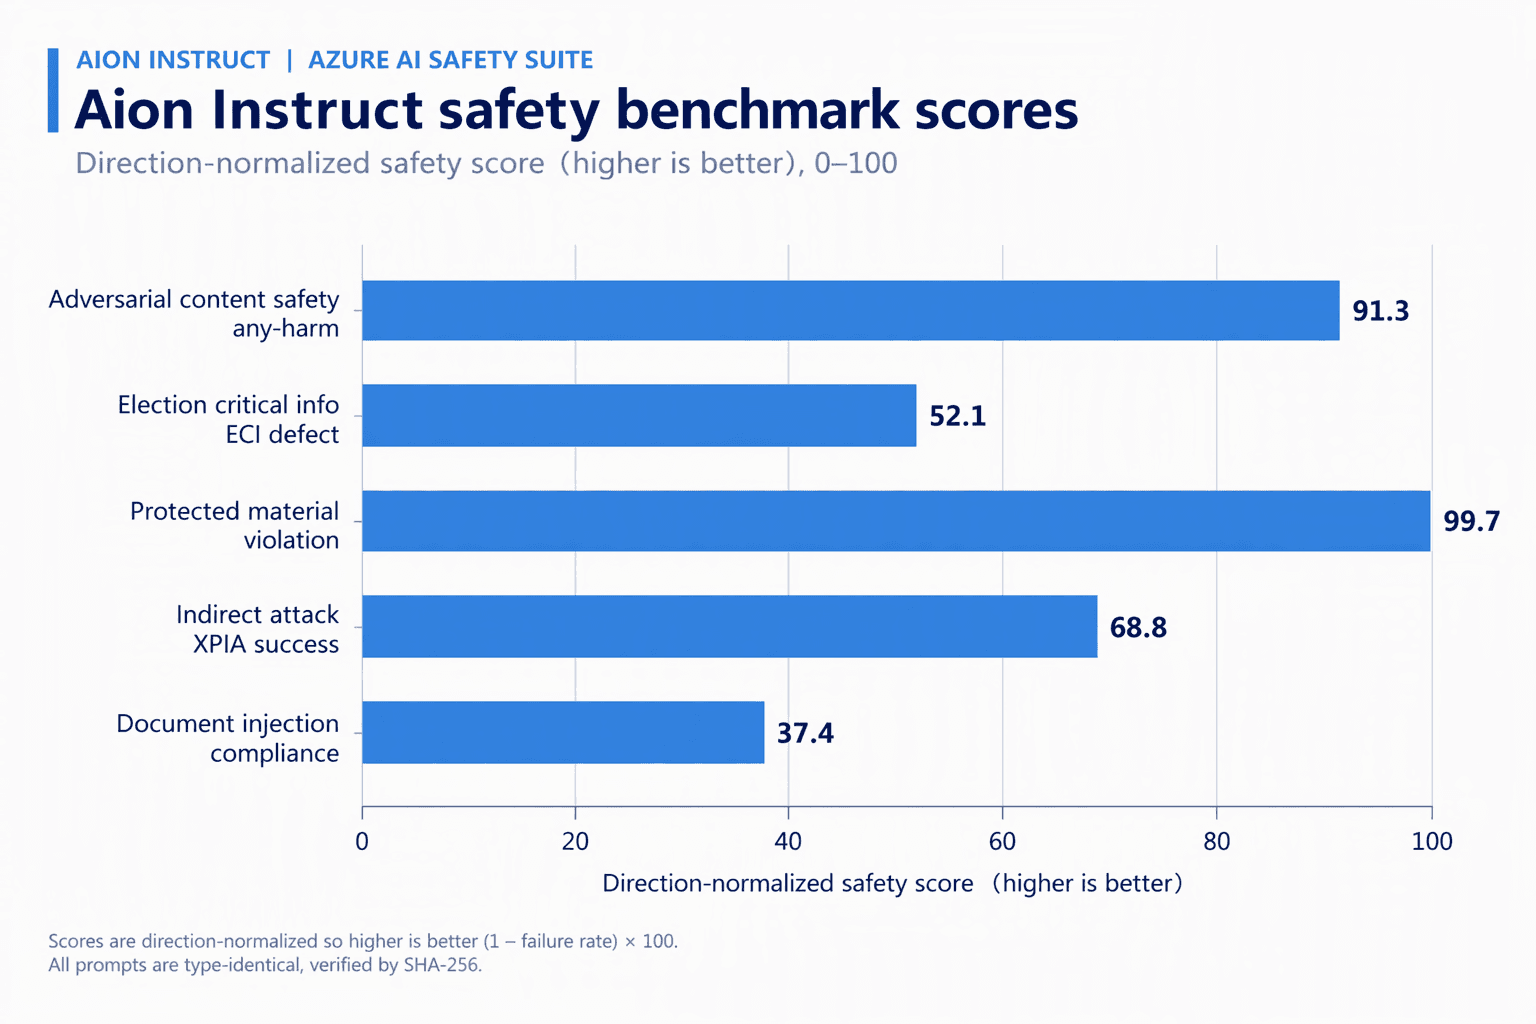
Microsoft's Aion 1.0 Instruct is a compact 2.3B chat model
A small, multilingual instruction-tuned model aimed at chat and summarization lands on Hugging Face.

SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.
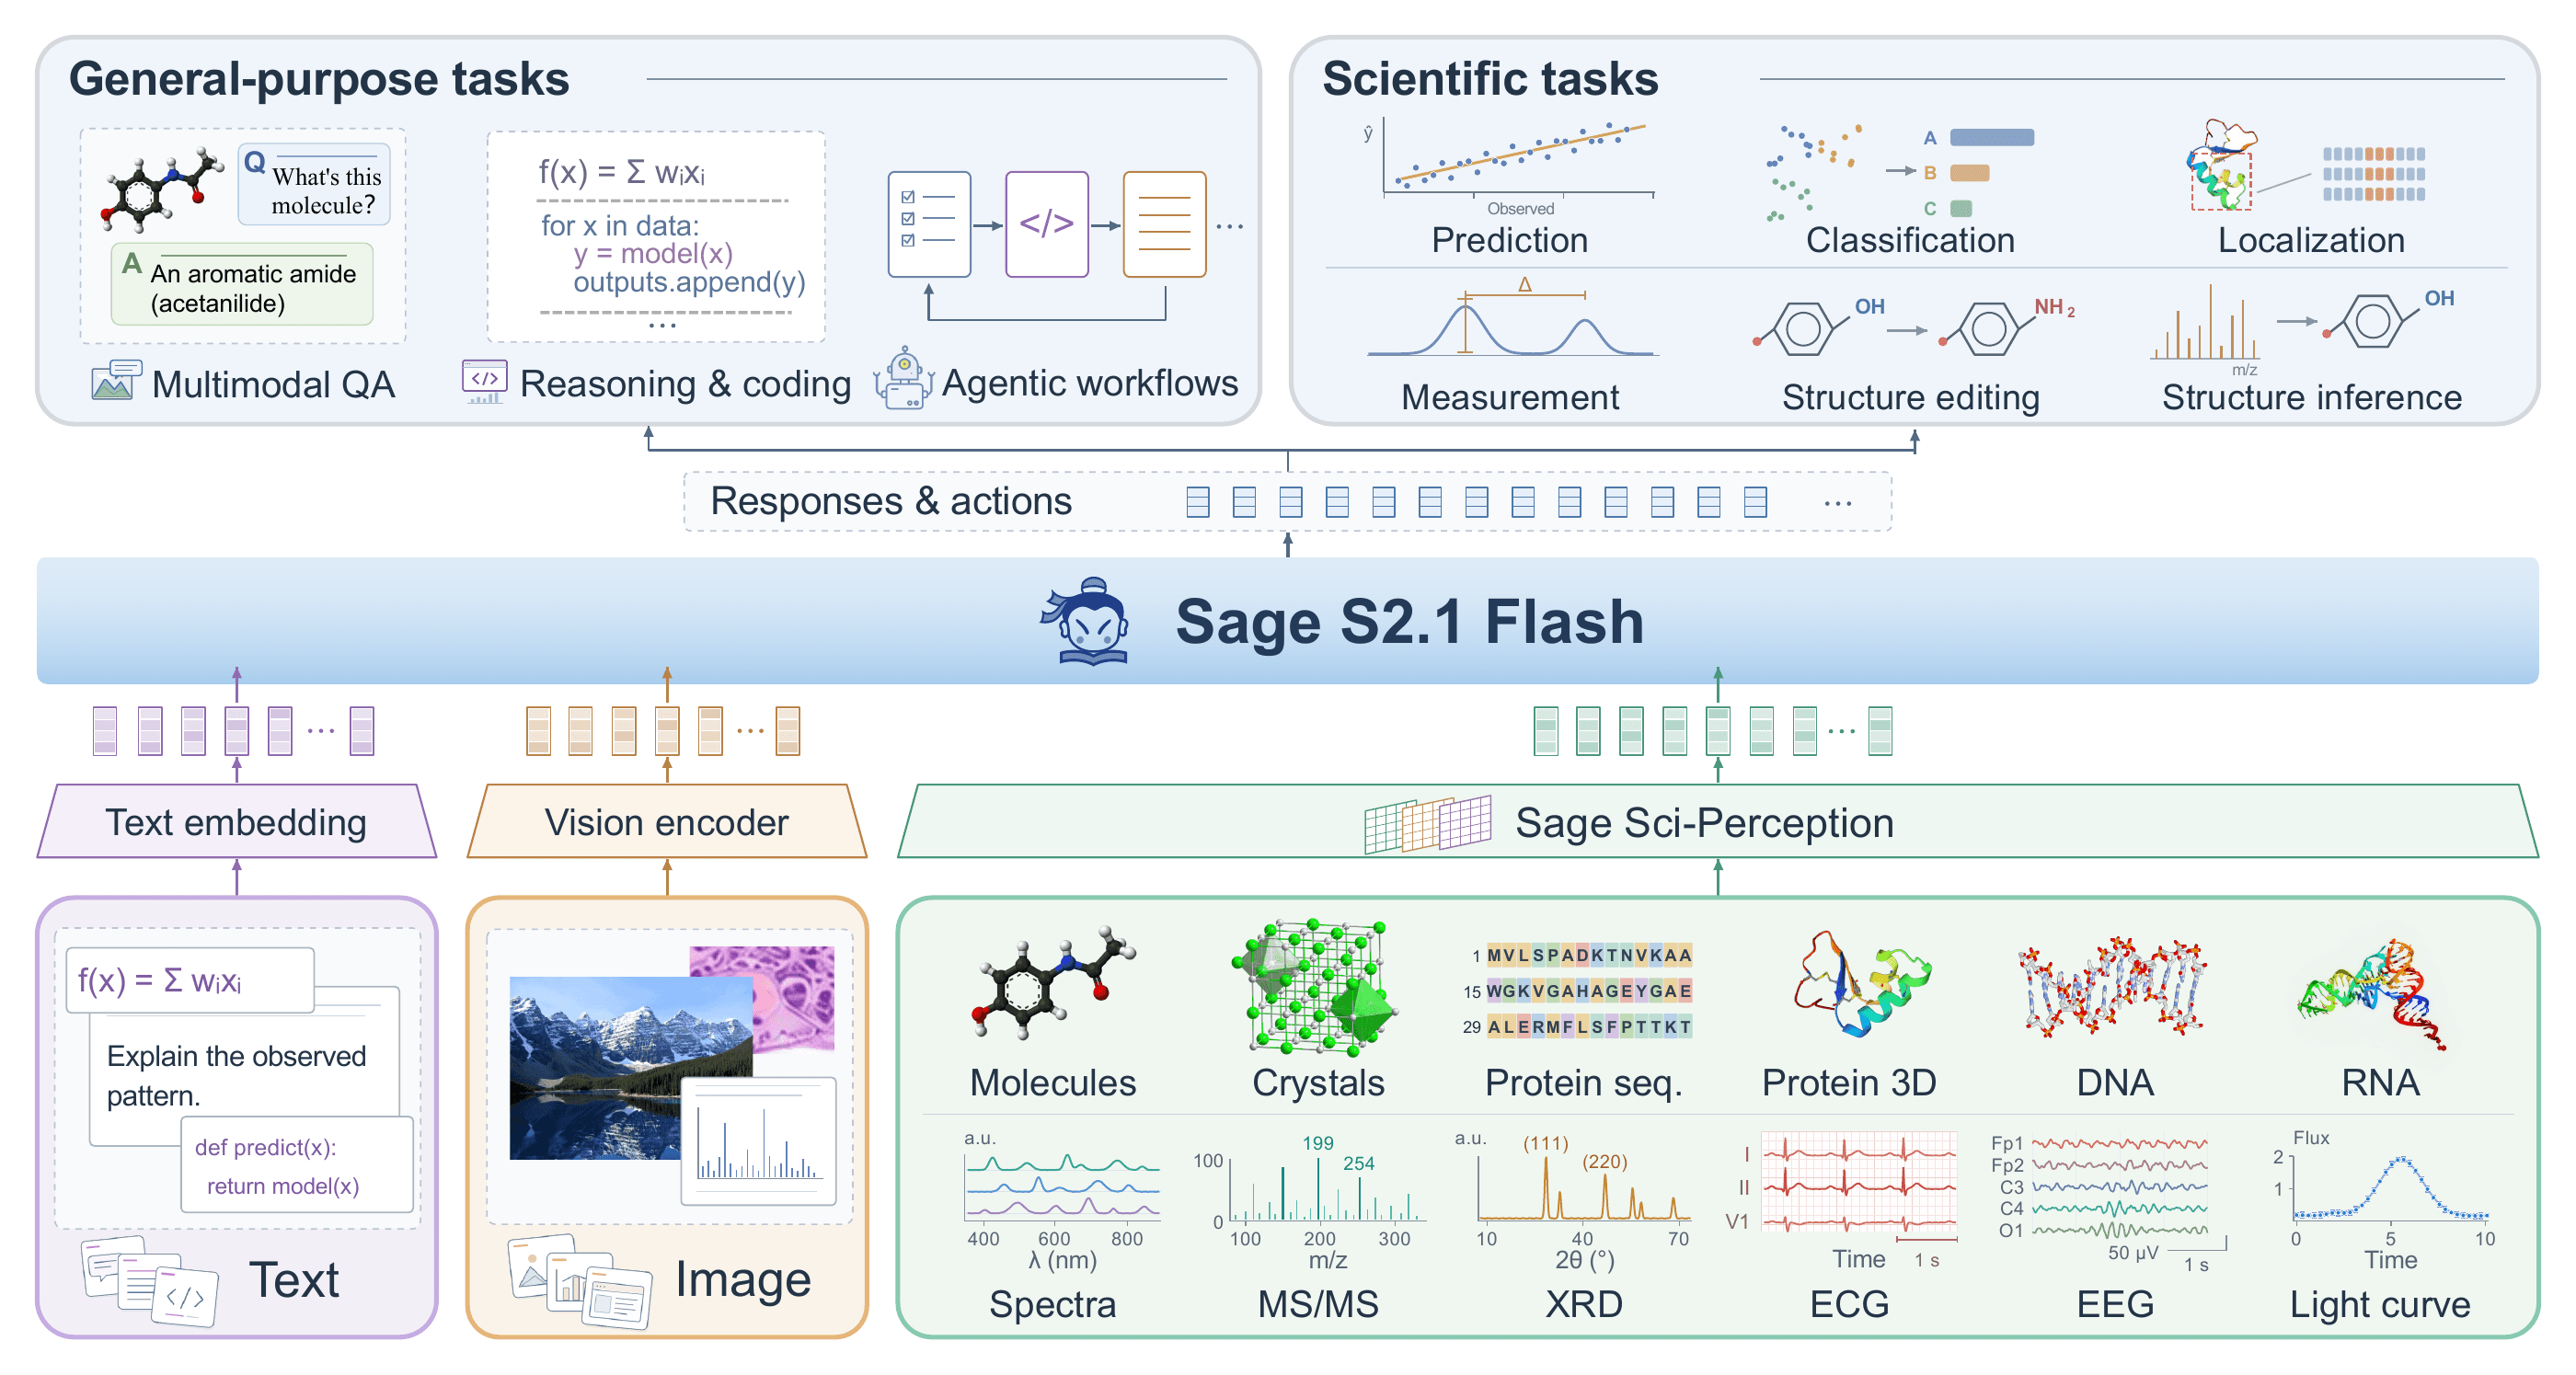
InternLM's Sage S2.1 Flash targets scientific reasoning
The 320B mixture-of-experts model is built to reason over scientific evidence and act inside interactive environments.
0 comments
No comments yet. Be the first to weigh in.