NVIDIA's Nemotron-3.5 Bolt targets 24GB GPUs
A multimodal mixture-of-experts model with 74B total parameters but just 9B active, tuned to fit consumer-class hardware.
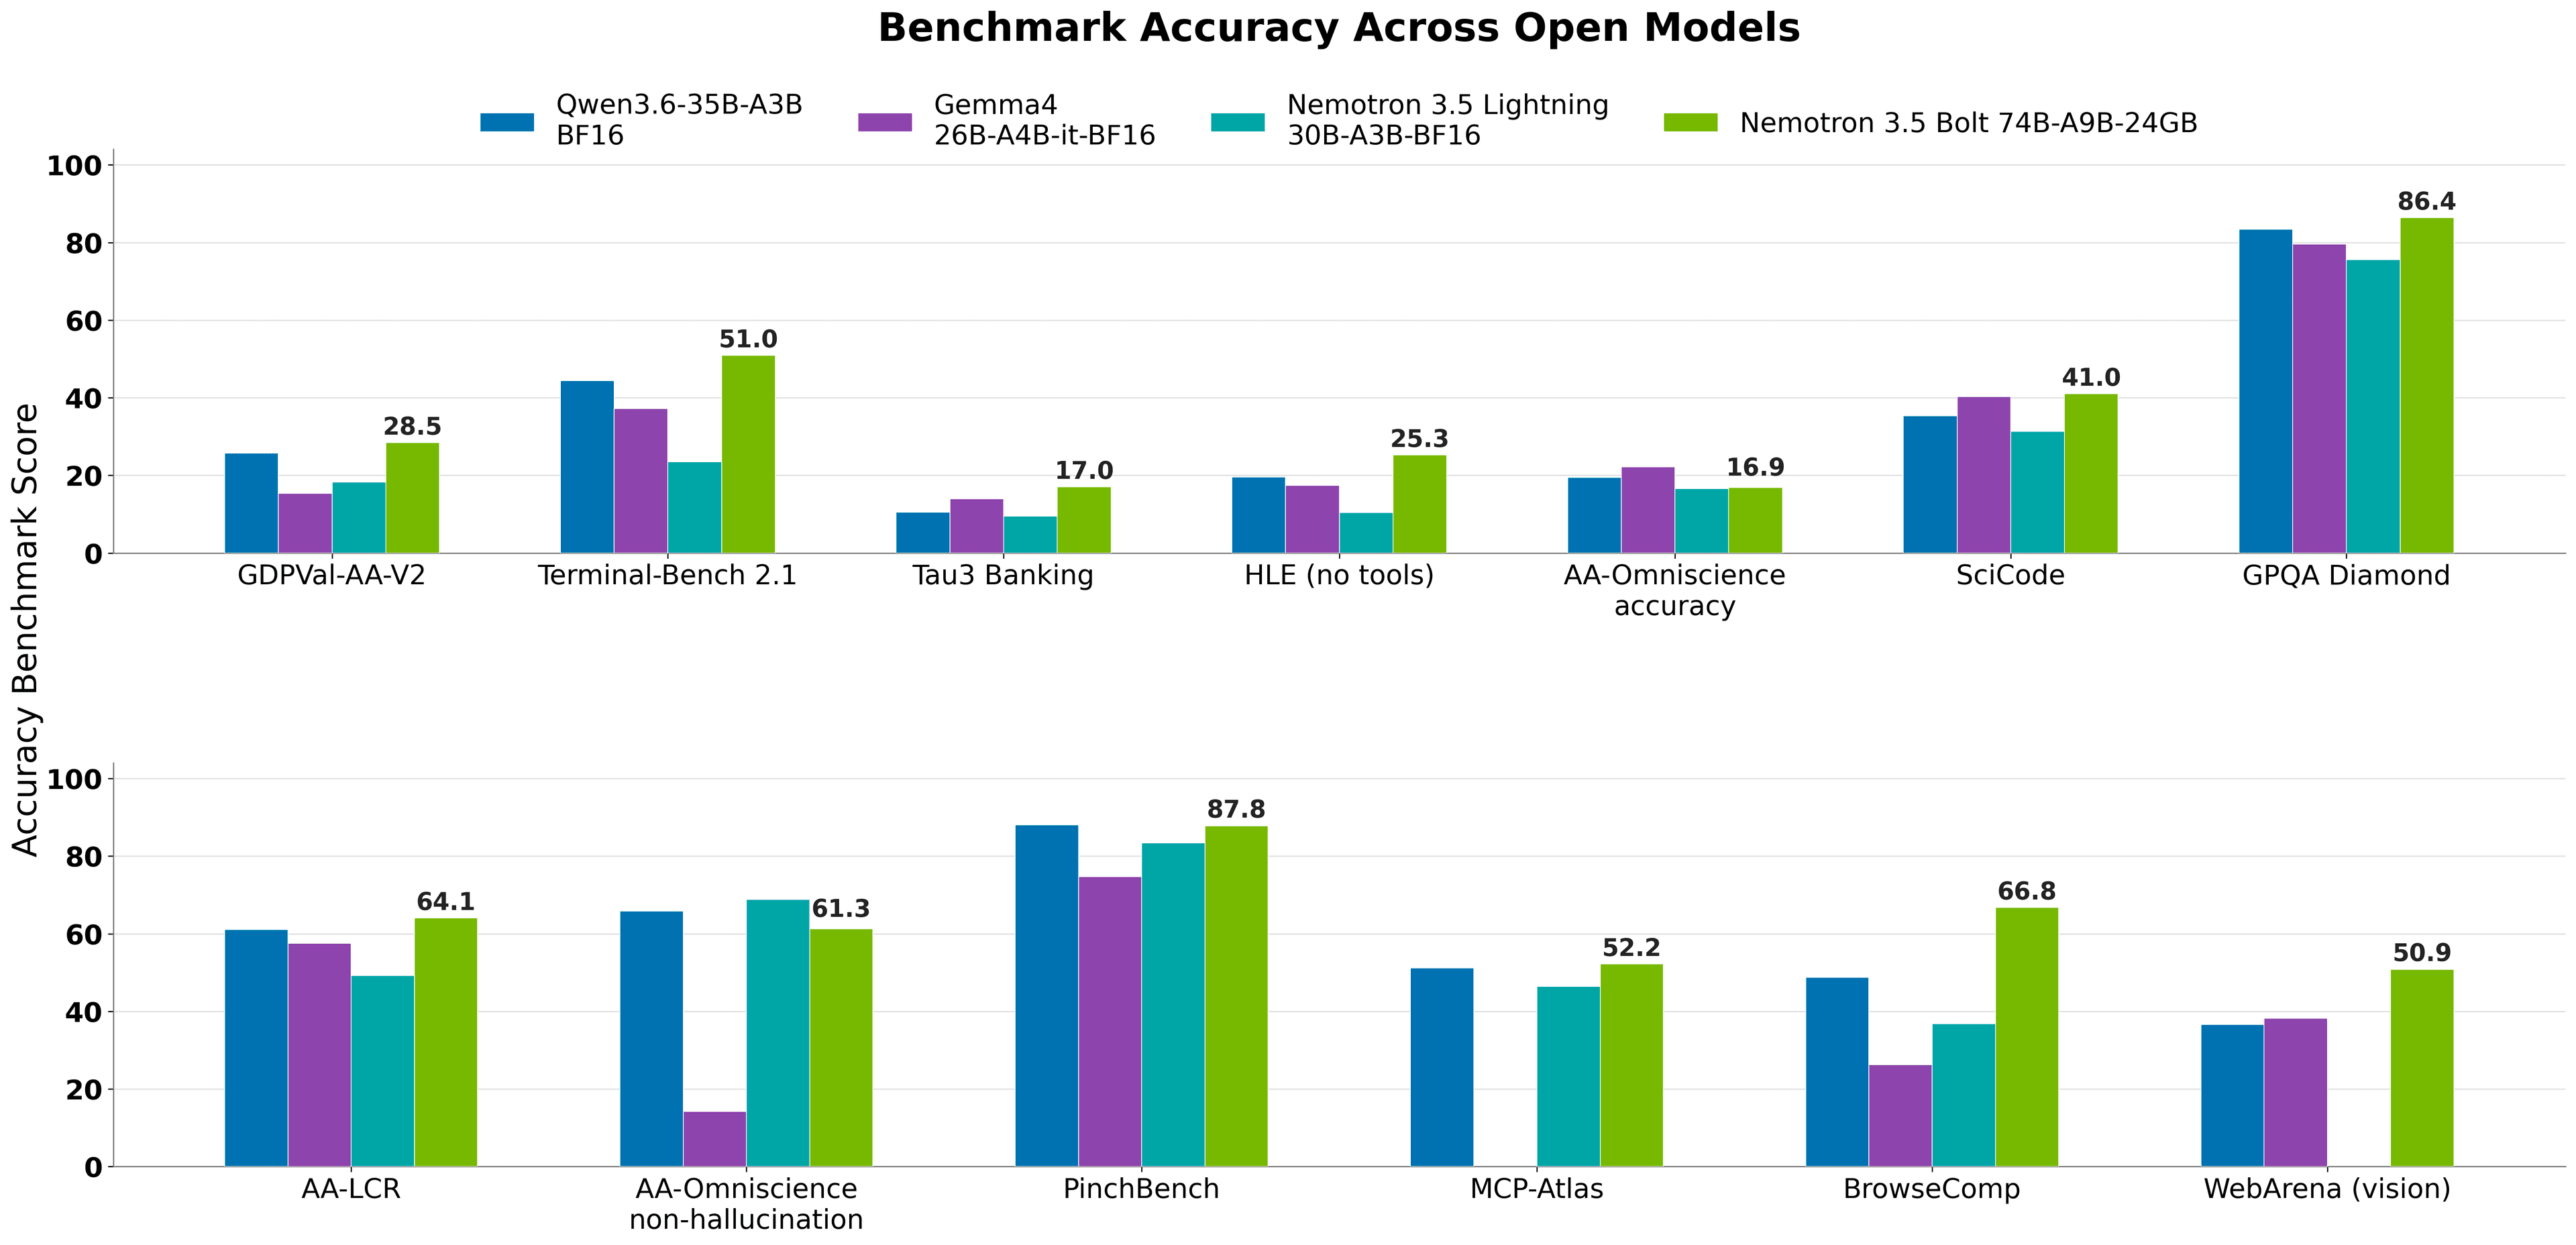
NVIDIA has published Nemotron-3.5 Bolt, a multimodal mixture-of-experts model that pairs a large 74-billion-parameter capacity with a lean nine-billion active footprint. The release is available now on Hugging Face.
The naming is unusually explicit about its intended home: the "24GB" suffix signals that NVIDIA has sized this model to run on a single 24GB GPU, the class of memory found in cards like the RTX 4090 and professional workstation parts. That framing matters because large vision-language models have typically demanded multi-GPU setups or datacenter accelerators.
Why the MoE math matters
Mixture-of-experts designs route each token through only a fraction of the network, so the compute and memory cost at inference tracks the active parameters rather than the full total. Here that means:
- 74B total parameters for overall capacity
- 9B active parameters per forward pass
- A target of 24GB of GPU memory
That combination is the central pitch — expert-level breadth without the full hardware bill. The model is listed as a vision-language model, extending Nemotron beyond text into multimodal understanding.
NVIDIA has not published a context length in this record, and the model carries a custom "other" license, so teams will want to review the terms before building on it. Still, a multimodal MoE engineered for consumer-class memory lowers the barrier for developers who want capable vision-language inference on hardware they already own.
Sources
- Visit
nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB
Hugging Face
More from NVIDIA
All NVIDIA releases →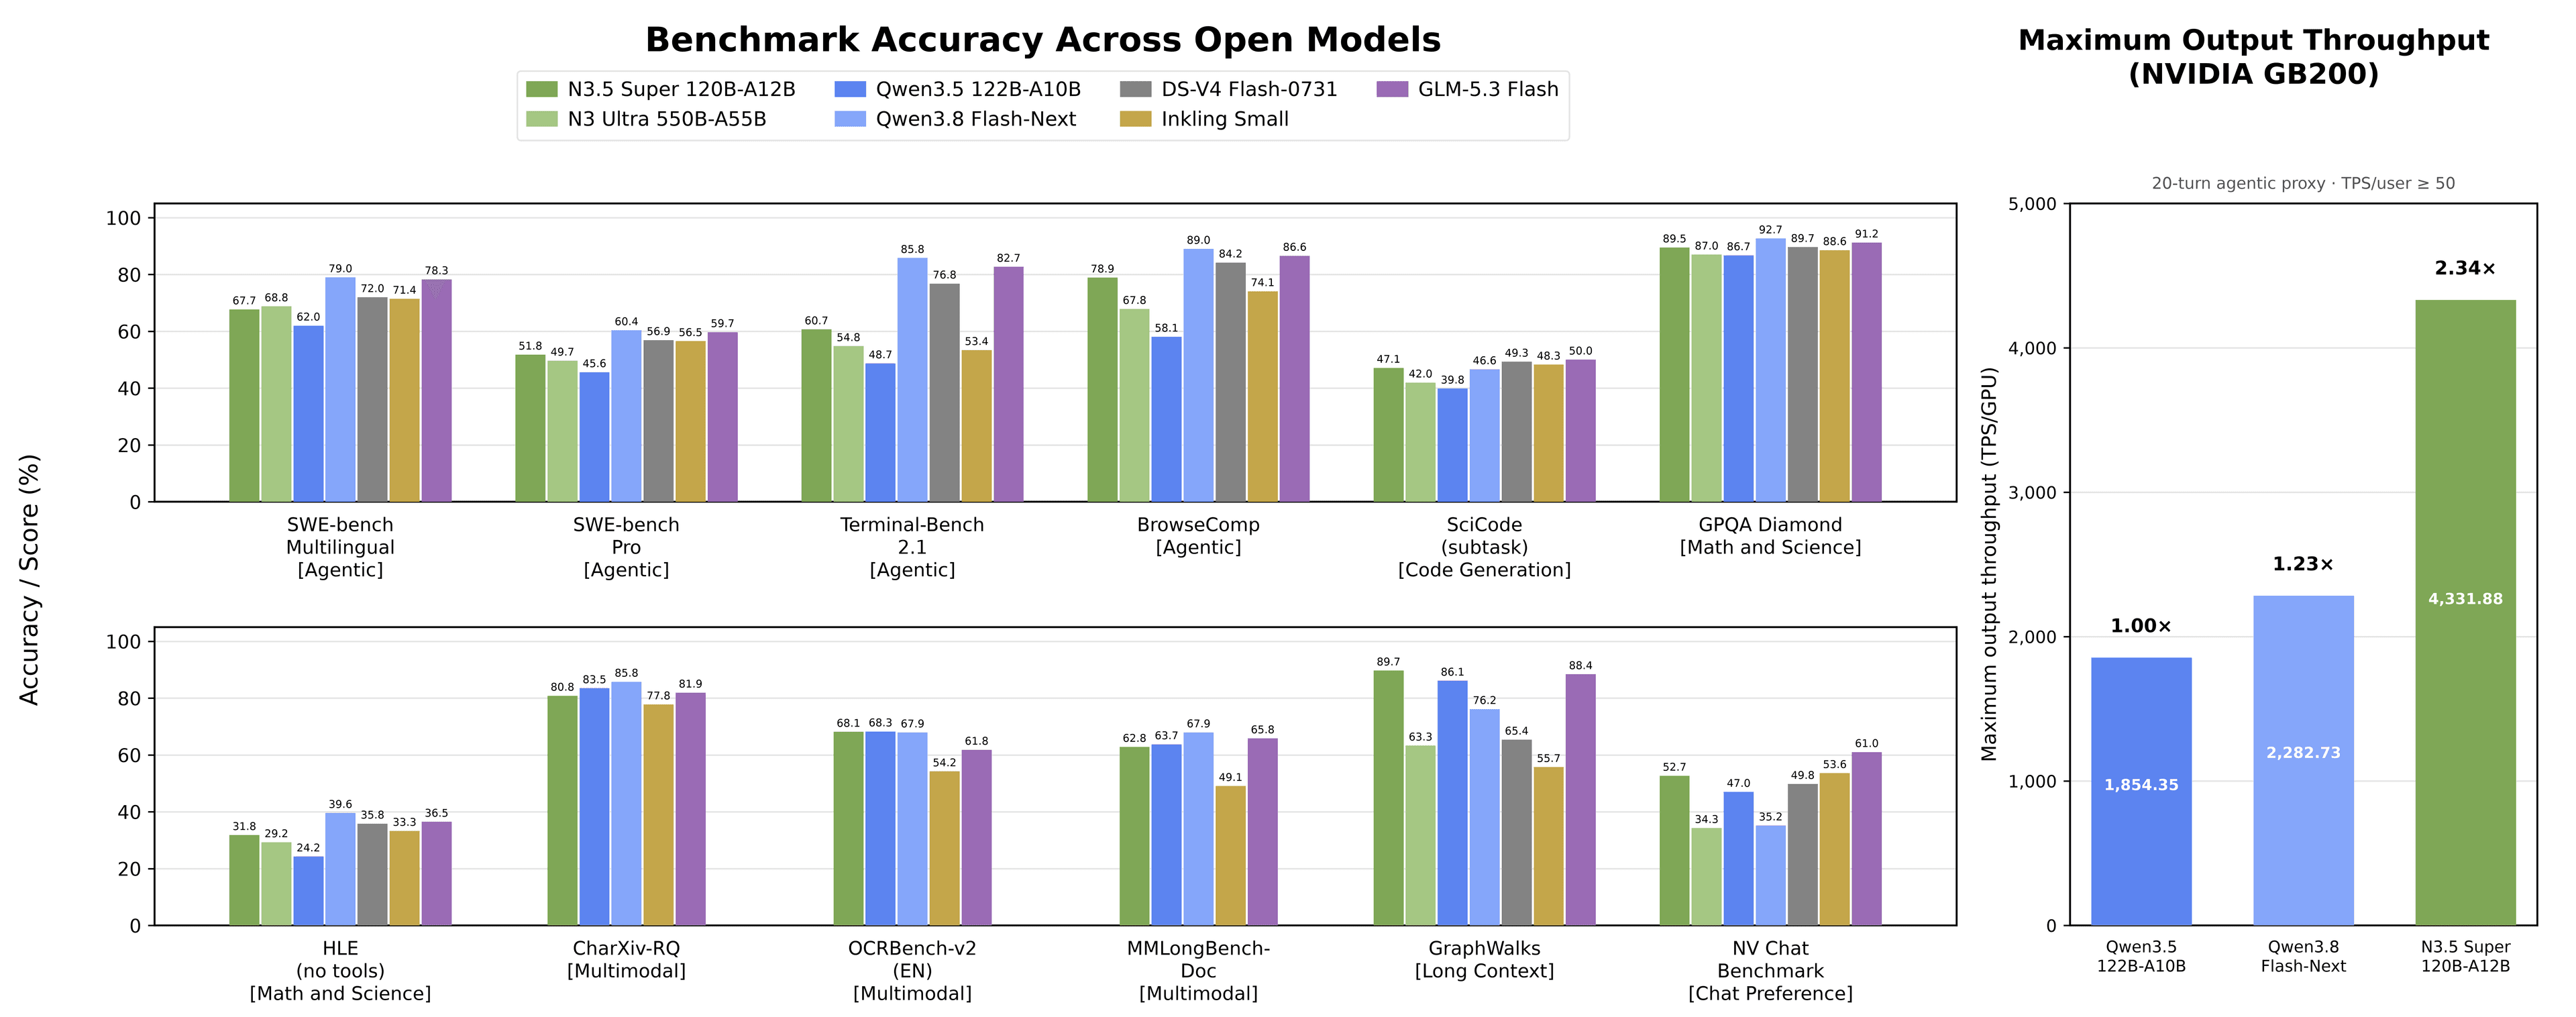
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
TII Brings Falcon to Speech With New ASR Model
The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.
Falcon-Emirati tunes an LLM for local dialect
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
More in Vision-Language
All Vision-Language →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
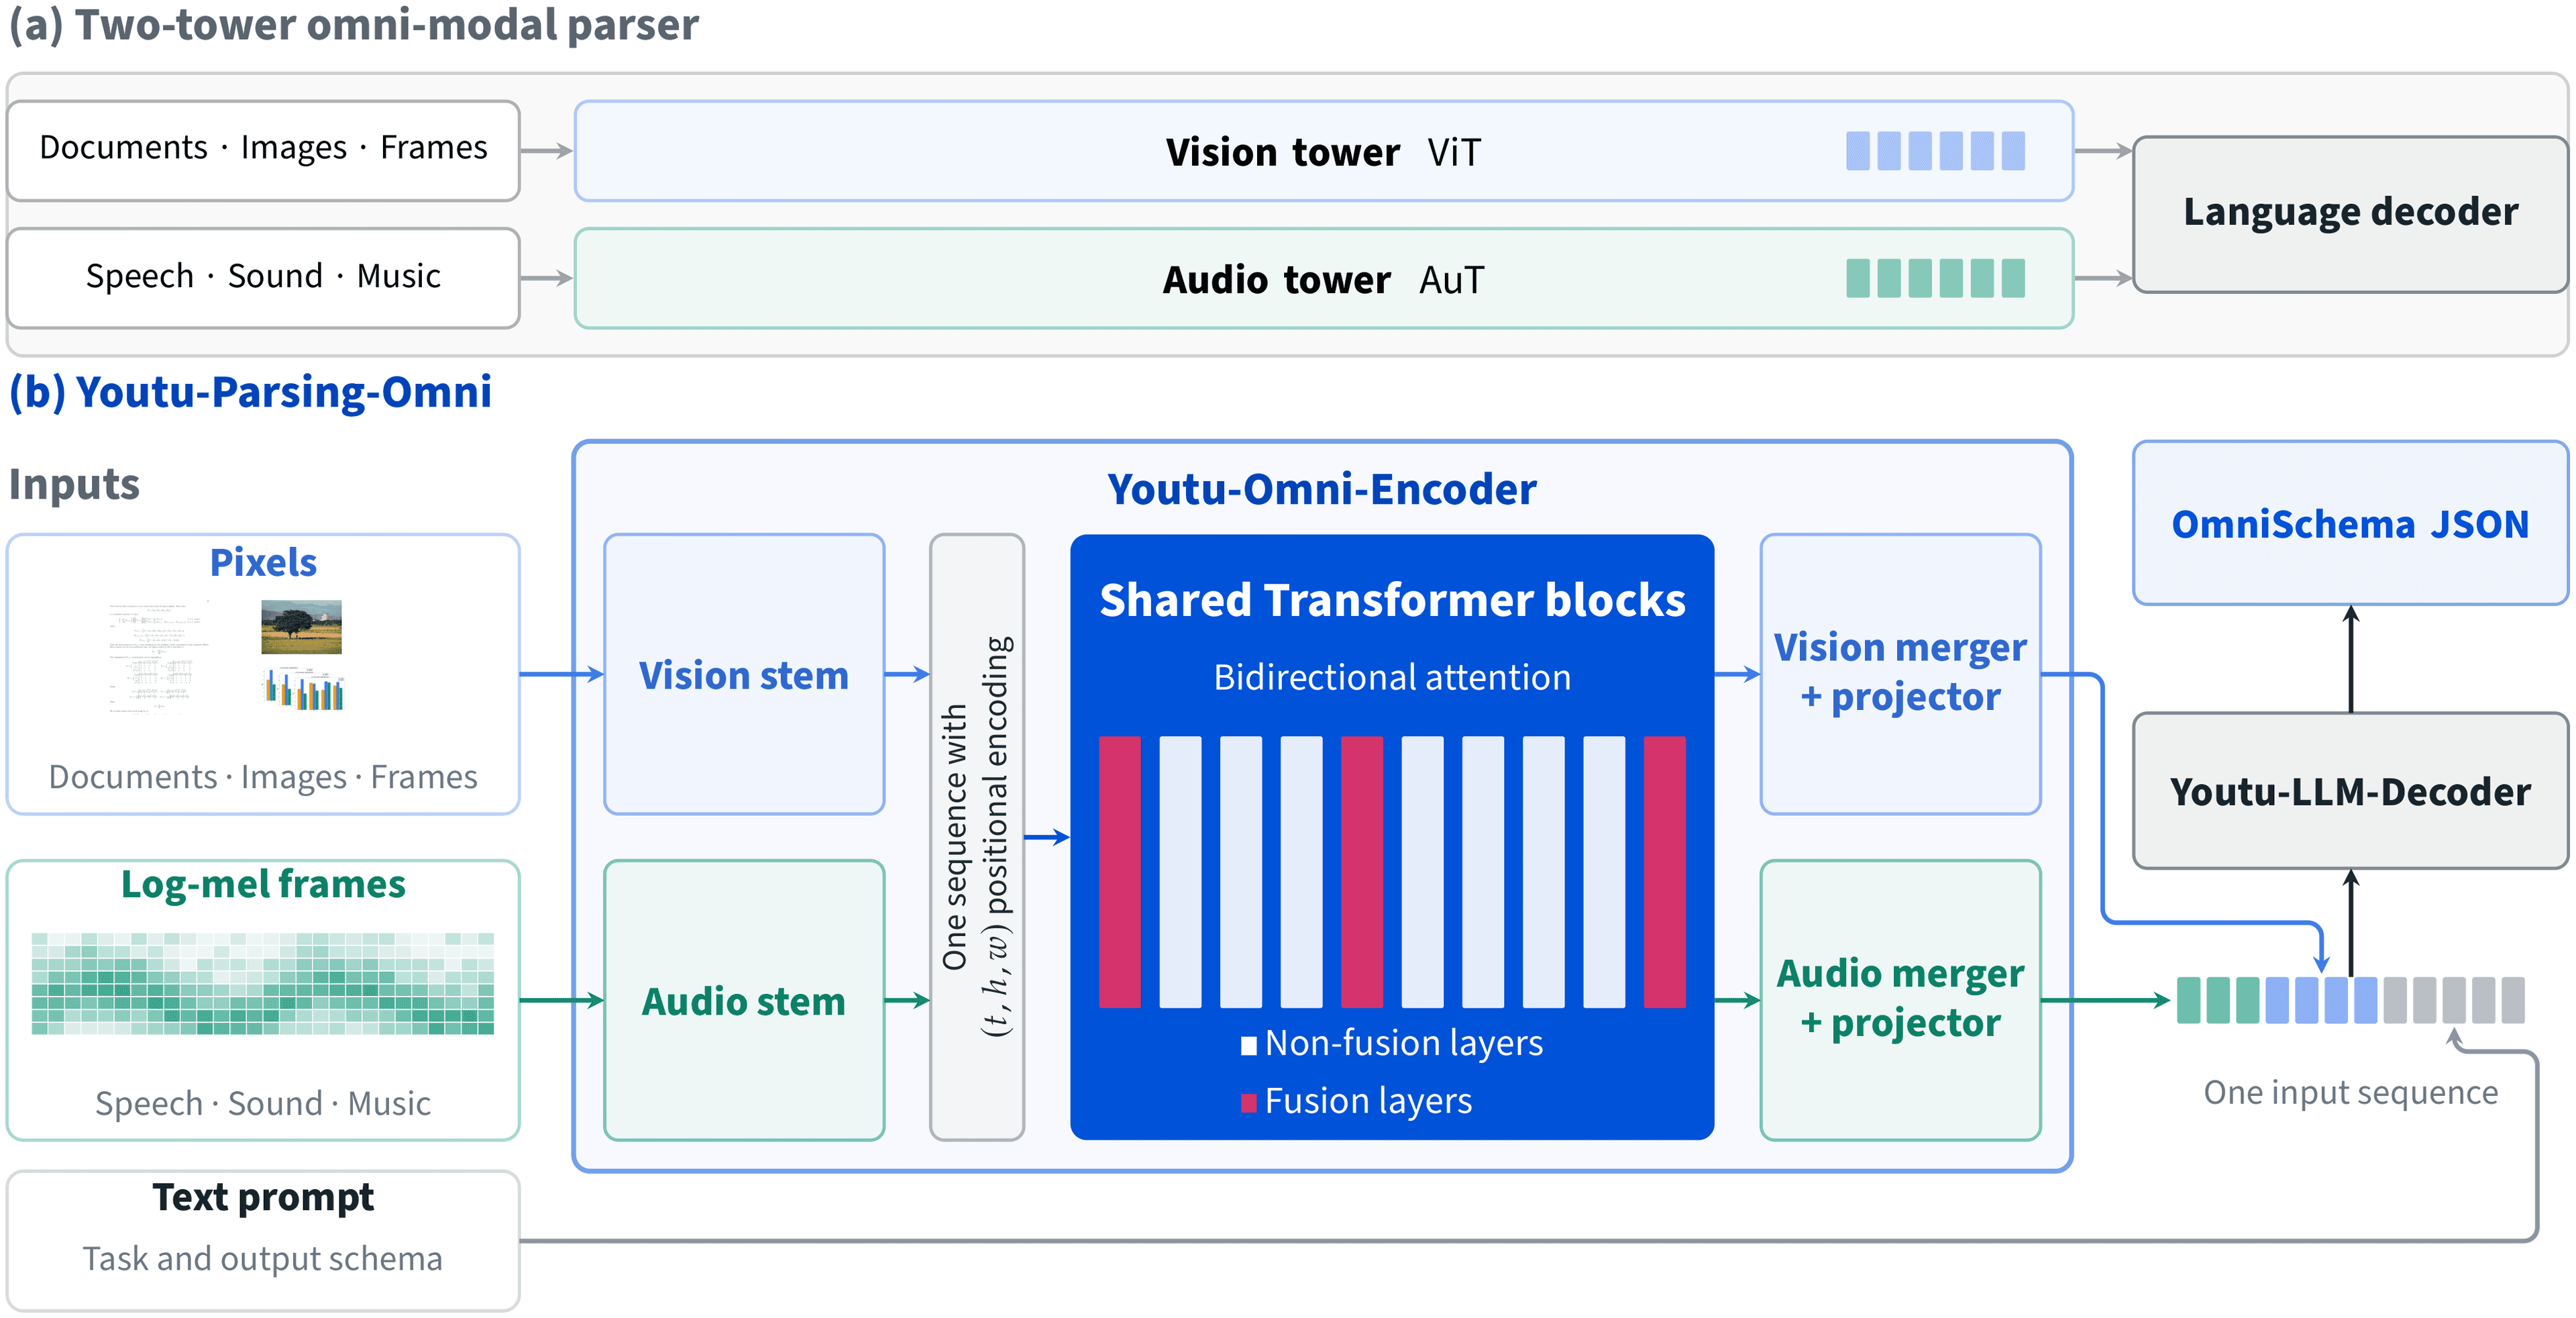
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.
0 comments
No comments yet. Be the first to weigh in.