OpenMOSS releases YuE2-3B for music generation
The 3-billion-parameter model pairs symbolic planning with agentic editing to generate and refine full songs in English and Chinese.

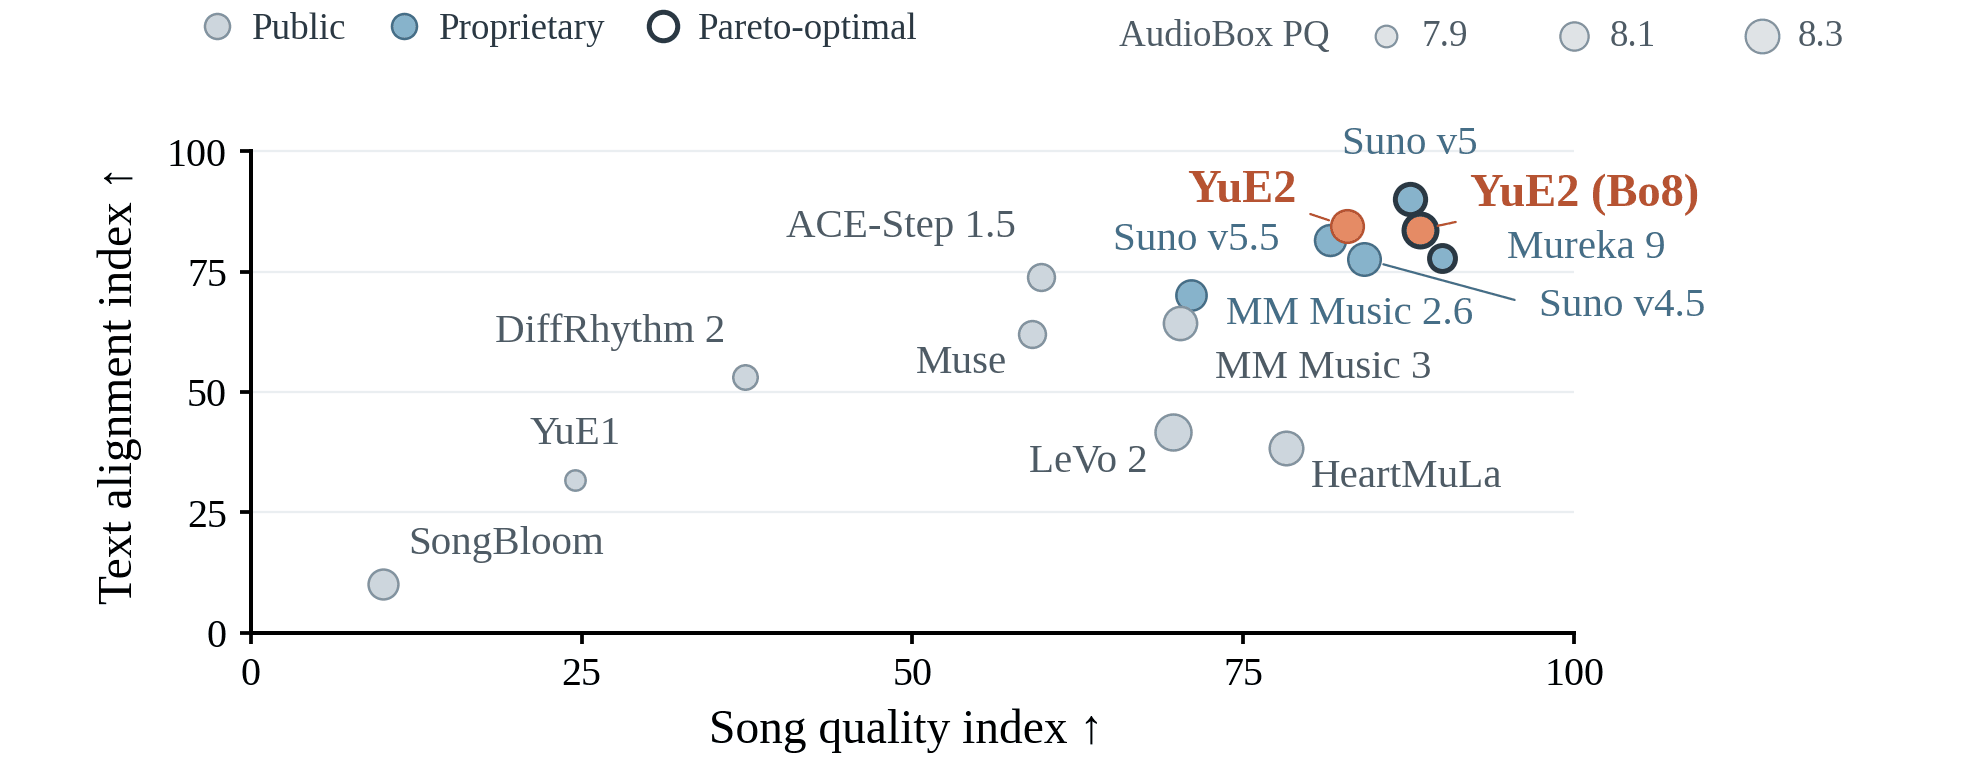
OpenMOSS has published YuE2-3B, a 3-billion-parameter music generation model, on Hugging Face. The model targets full-song generation and supports both English and Chinese lyrics, and it arrives under a non-commercial CC-BY-NC-4.0 license.
What distinguishes YuE2 from a straightforward text-to-audio system is its stated approach: the model combines symbolic planning with agentic editing. In practice that means the system can reason about musical structure before committing to audio, then revise its output rather than producing a single one-shot render.
Why it matters
Open music models have lagged behind their text and image counterparts, in part because coherent long-form composition is hard and high-quality training data is scarce. A mid-sized, openly available model that leans on structured planning is a useful data point for anyone building or studying generative audio tools.
- Roughly 3B parameters, a dense (non-MoE) architecture
- Bilingual support for English and Chinese
- Symbolic planning plus agentic editing for iterative refinement
- Released under CC-BY-NC-4.0, limiting commercial use
The non-commercial license means YuE2-3B is best understood as a research and experimentation release rather than a drop-in tool for commercial production. Full details and weights are available on the model's Hugging Face page.
Sources
- Visit
m-a-p/YuE2-3B
Hugging Face
More in Music
All Music →StepFun's StepAudio 3 Music Plans Before It Plays
The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.
StepFun's StepAudio 3 Gen Unifies TTS and Music
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
OpenMOSS Unveils YuE2-3B Music Generation Model
The 3-billion-parameter model adds symbolic planning and agentic editing to open-source music generation.
0 comments
No comments yet. Be the first to weigh in.