AREX-2 arrives as an open deep-research agent model
The reasoning-focused release pairs tool use with long context and self-improvement, and ships as a vision-language model on Hugging Face.
A new model called AREX-2 has appeared on Hugging Face, positioned as a "deep-research" agent built around reasoning, tool use, long context and what its authors describe as self-improvement. The release is hosted under the BAAI organization at huggingface.co/BAAI/AREX-2 and is tagged for both reasoning and vision-language workloads.
The framing matters because "deep research" has become shorthand for a specific class of system: one that can plan a multi-step investigation, call external tools, and read long documents before producing an answer. Rather than a single-shot chat model, AREX-2 is pitched at that agentic workflow, where the model decides when to retrieve, compute, or verify.
What the record tells us
- A reasoning-first model with vision-language (VLM) capabilities
- Designed for tool use and long-context tasks
- Described as supporting self-improvement in its research loop
- Published under an "other" license, so terms should be checked before use
Several specifics remain unstated at launch. The listing does not disclose a parameter count, context-window length, or benchmark results, and it is marked as a dense (non-MoE) model. Those details will determine how AREX-2 compares with the growing field of open agentic systems.
For now, the release is most useful as a signal of where open models are heading: away from standalone answer engines and toward configurable agents that combine reasoning, perception and tools. Teams interested in evaluating it should review the model card directly, particularly the license and any usage requirements, before building on top of it.
Sources
- Visit
BAAI/AREX-2
Hugging Face
More in Reasoning
Aleph Alpha releases Kolibri, a sovereign reasoning model
The German AI company's open-weight mixture-of-experts model targets European needs with strong German and English reasoning.
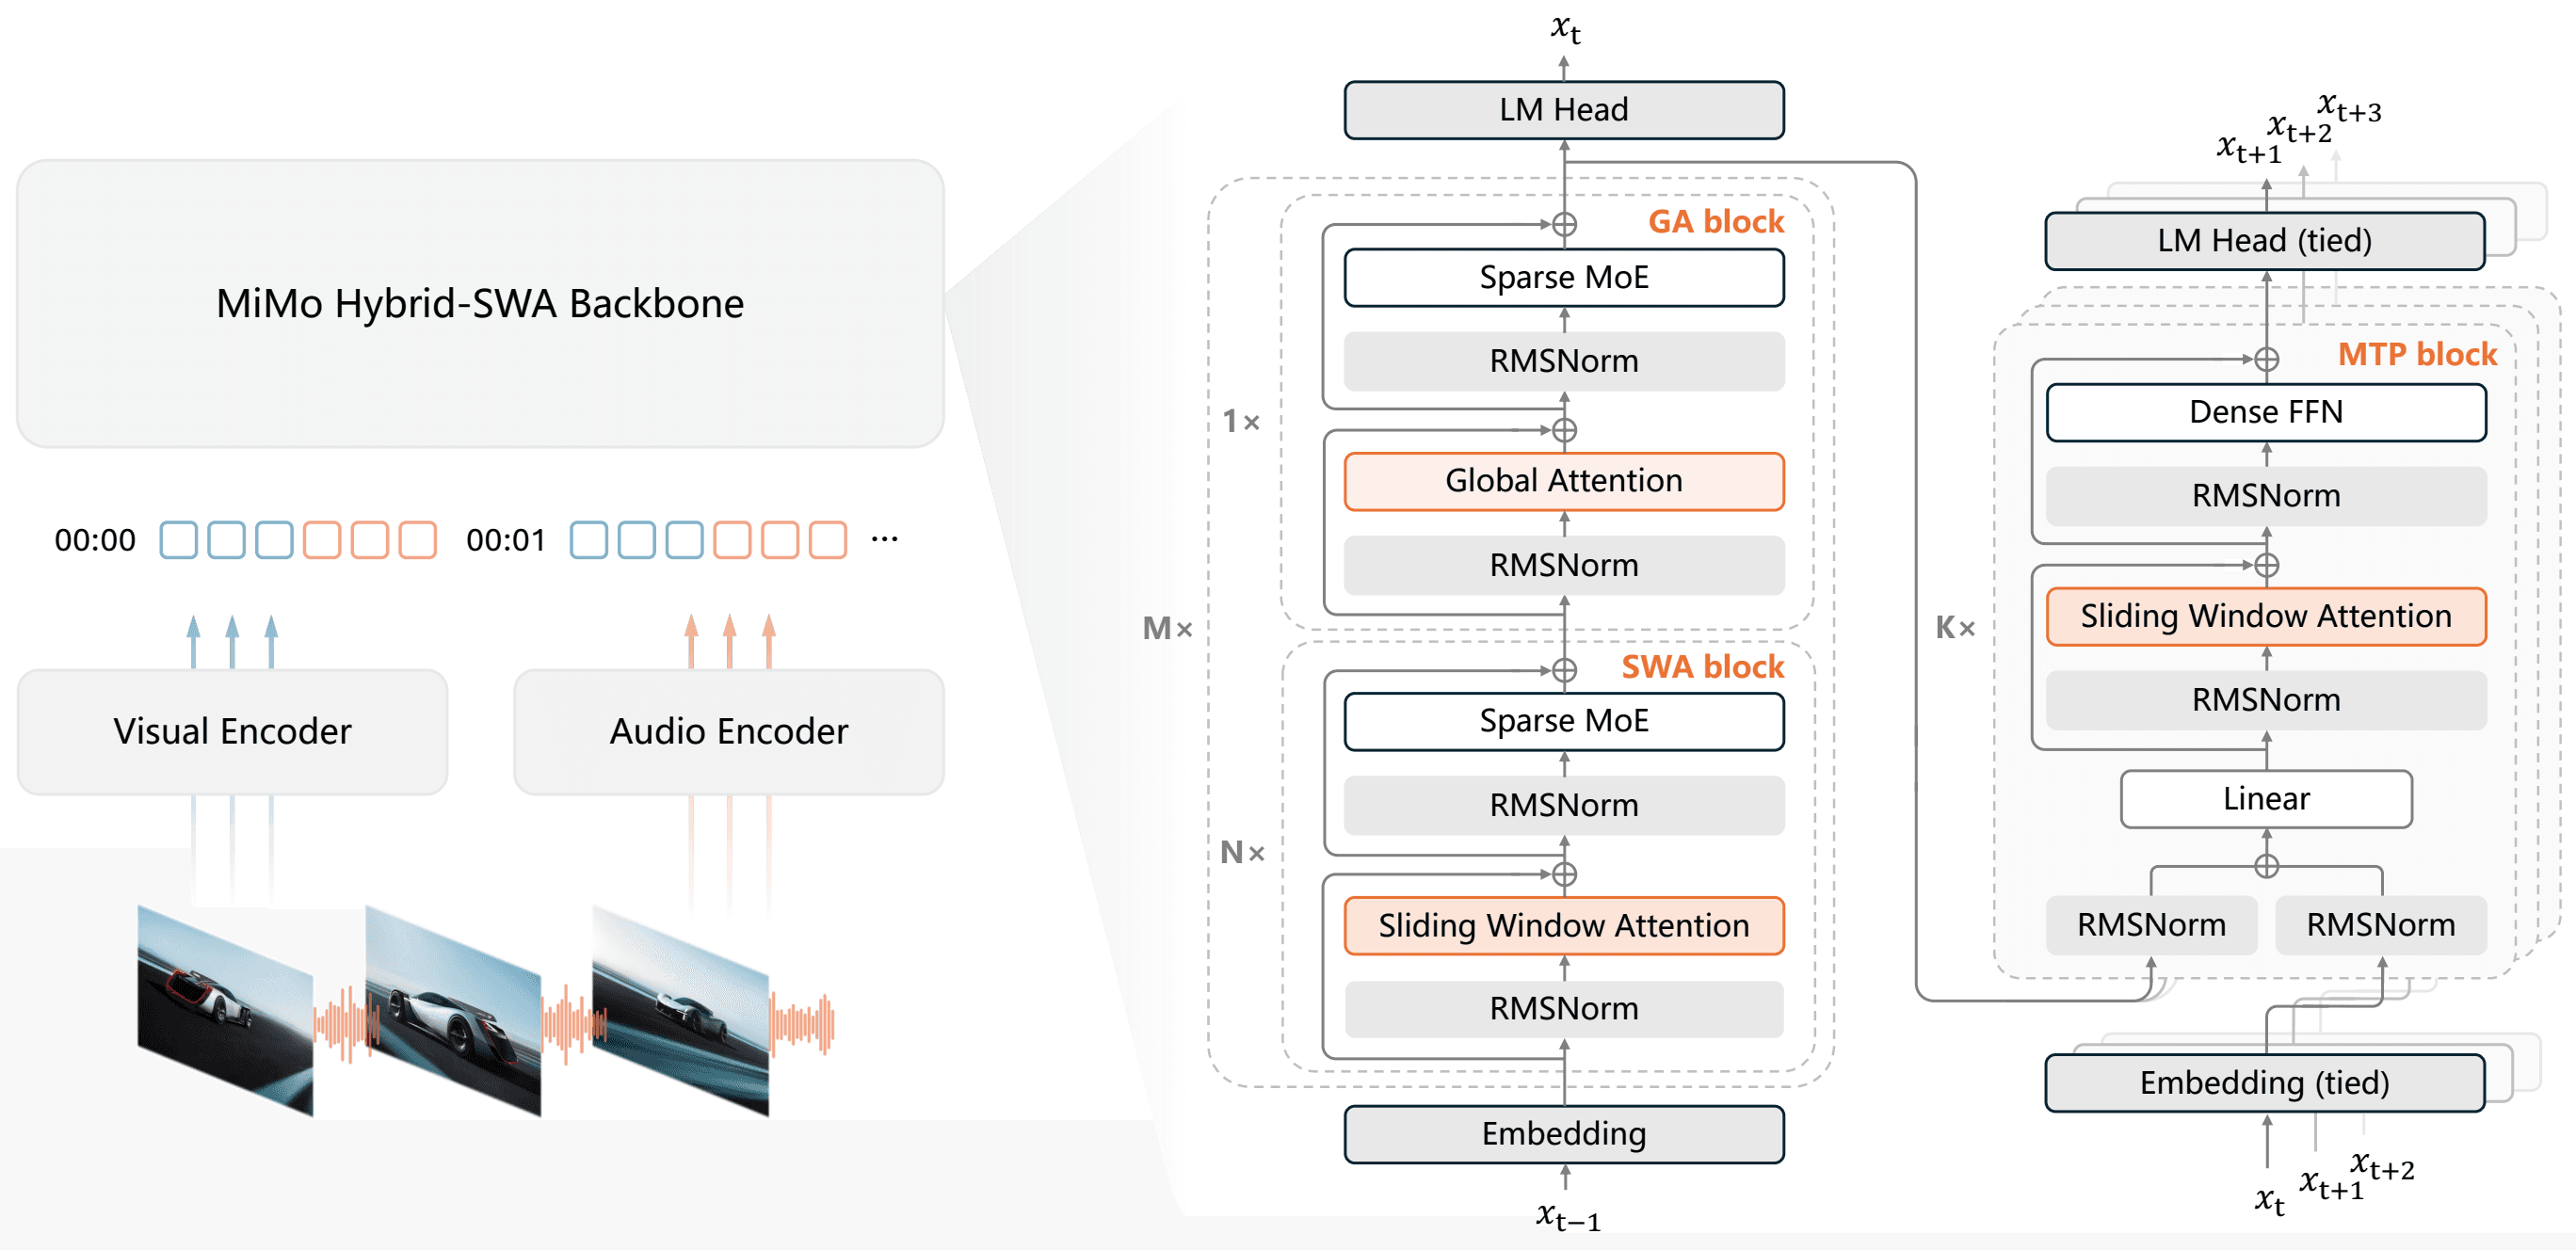
Xiaomi expands MiMo line with V2.6 multimodal models
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
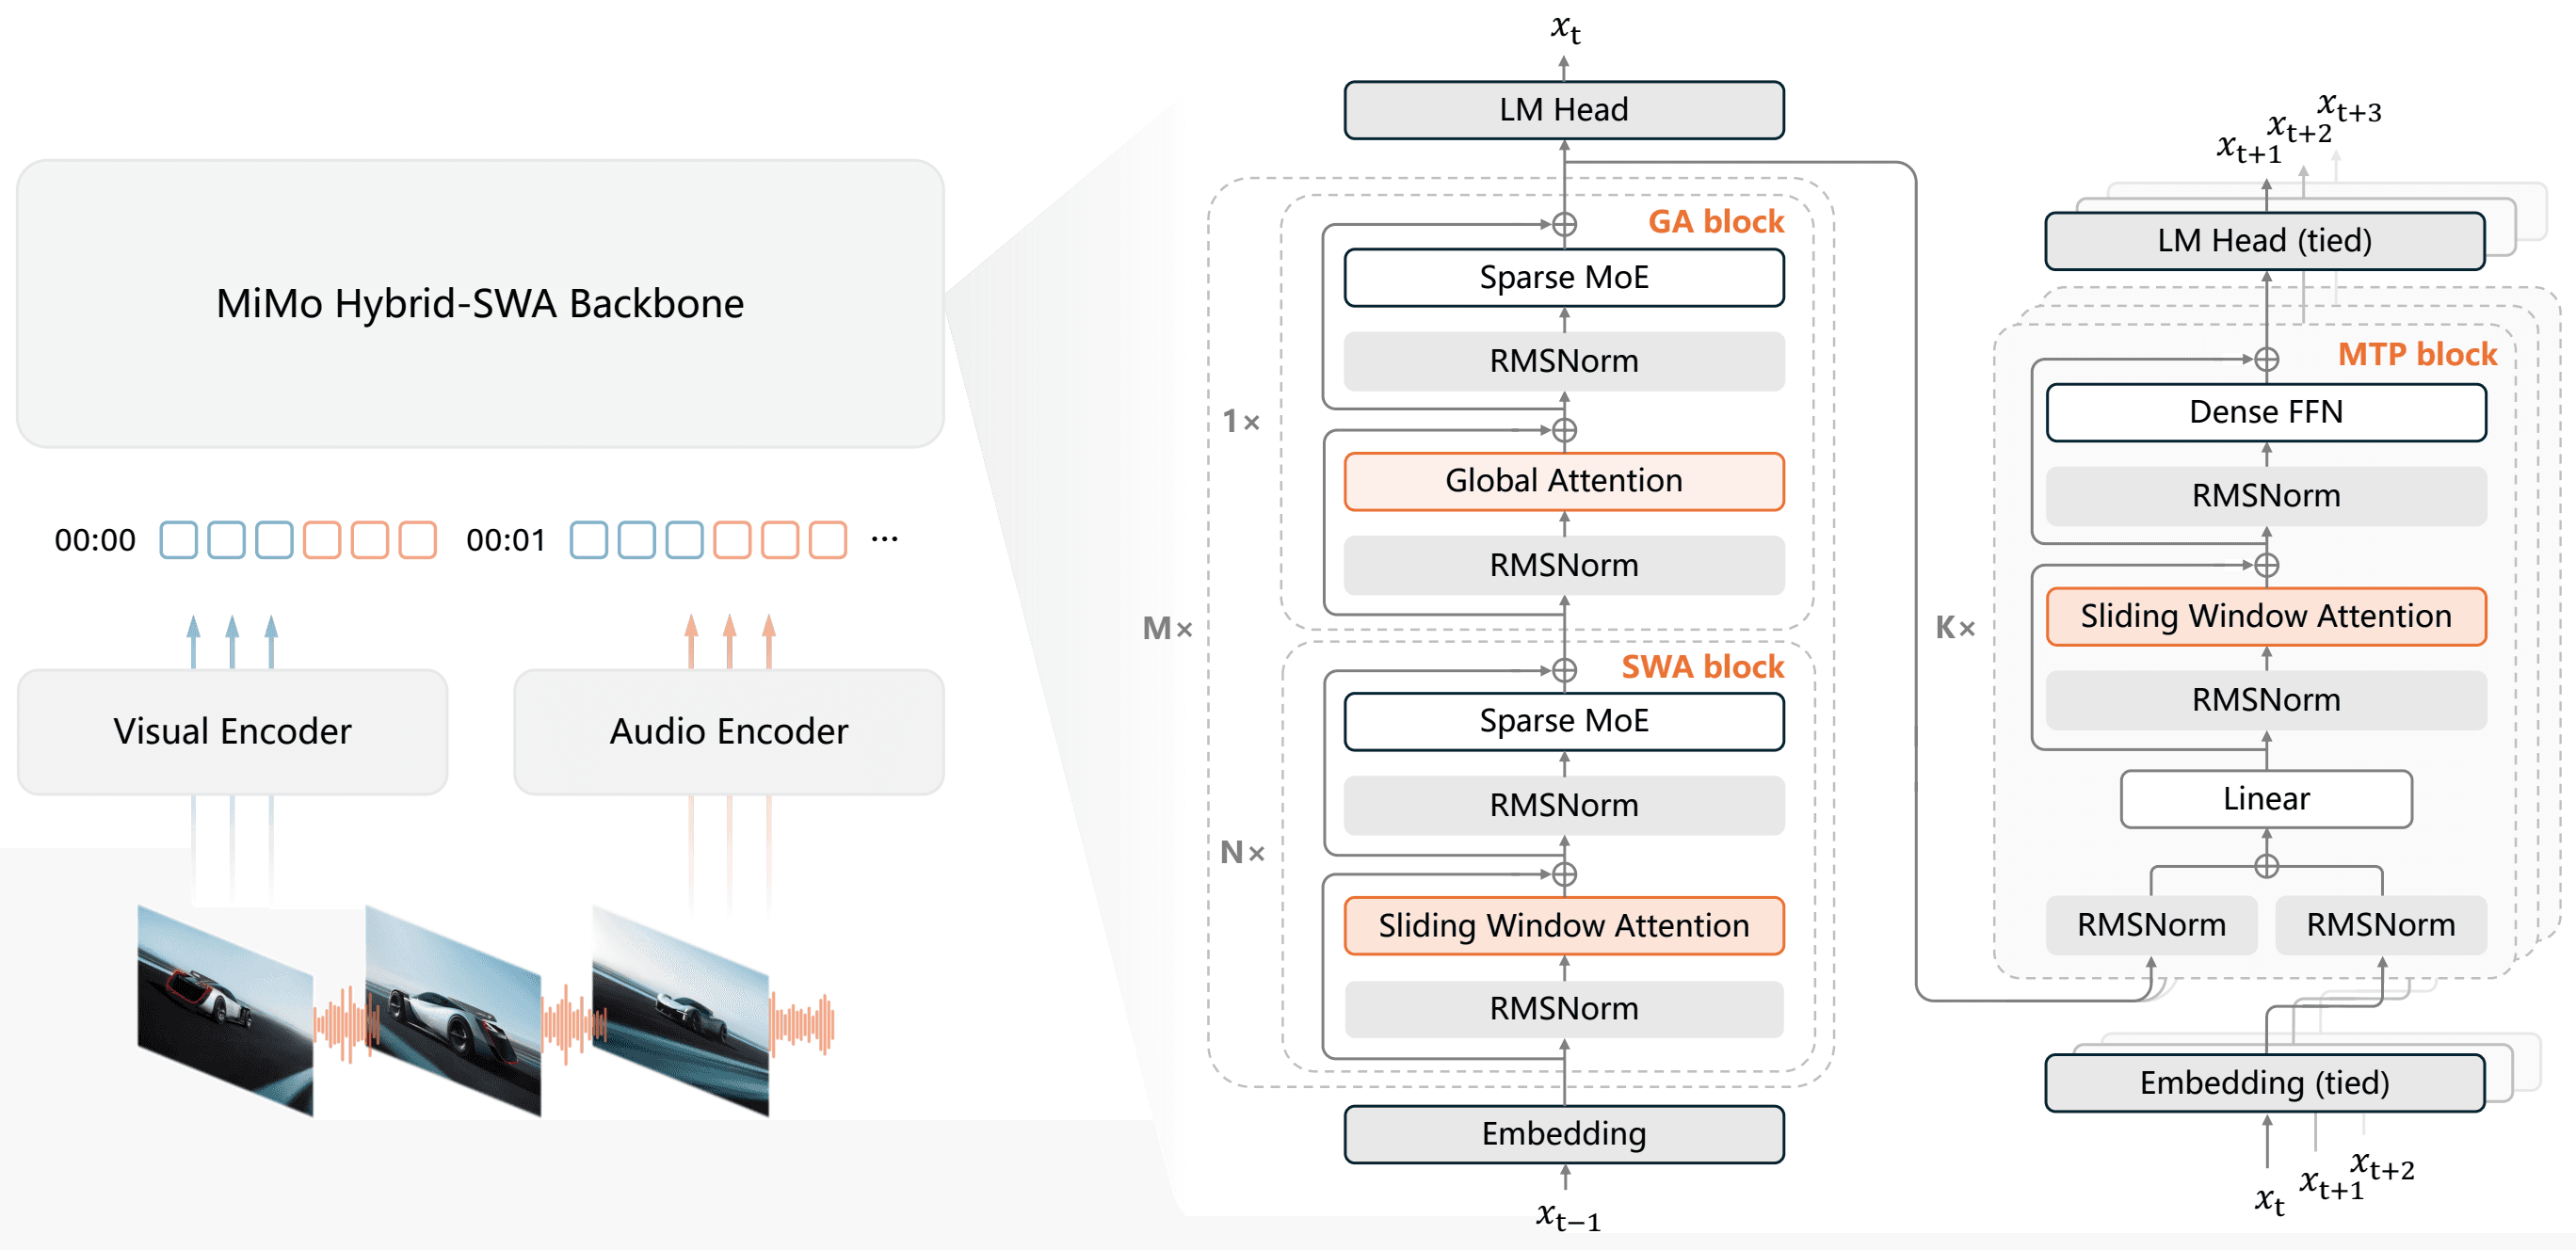
Xiaomi's MiMo V2.6-Pro-RL Targets Agentic Multimodal Work
An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.
0 comments
No comments yet. Be the first to weigh in.